On MLCR-AA and HealthBench Professional, Anthropic models give the most…
- Source
- x.com
- Date

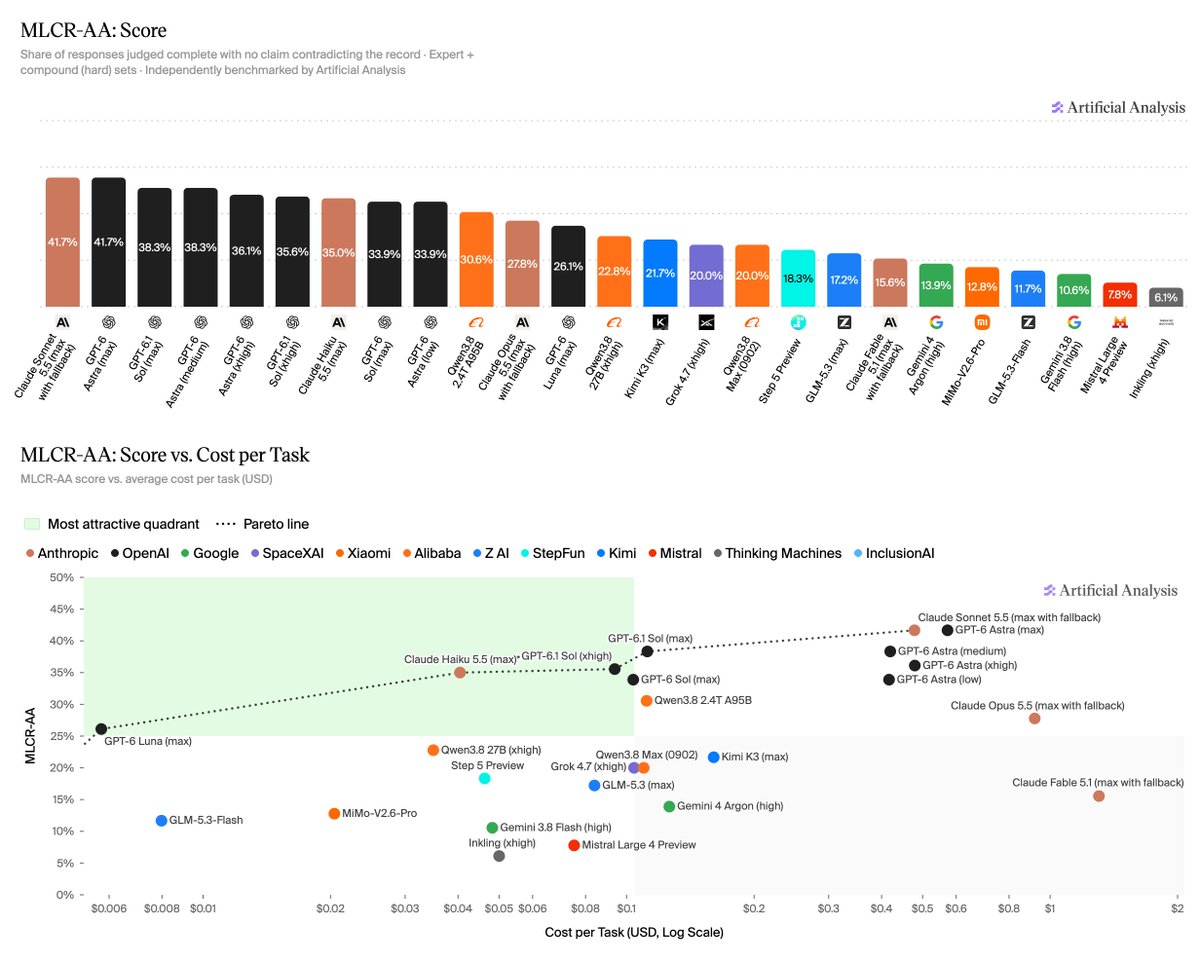
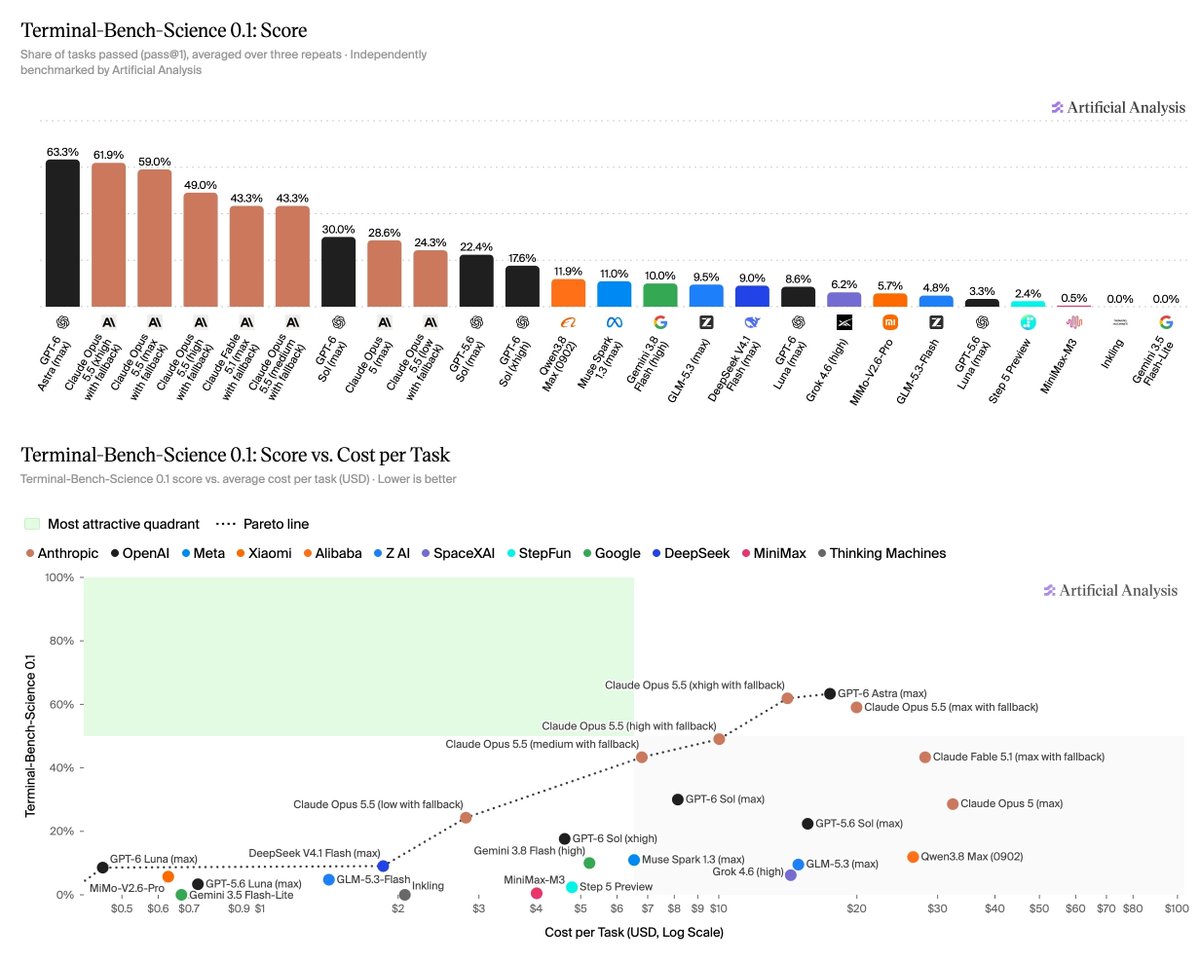
On MLCR-AA and HealthBench Professional, Anthropic models give the most complete answers but OpenAI models are more accurate and concise We compared 14 models with results on both MLCR-AA, our leaderboard for @wisedocsai's Medical Long Context Reasoning benchmark, and @OpenAI's HealthBench Professional. MLCR-AA grades answers about long medical records on completeness (covering every key point of the expert's answer) and accuracy (no claim contradicting the record), and its score requires both. HealthBench Professional grades replies to clinicians against physician-written rubrics: the raw score is the share of rubric points earned, while the length-adjusted score penalizes longer answers. Key takeaways: ➤ Anthropic models lead on completeness and raw score: Claude Sonnet 5.5, Opus 5.5 and Fable 5.1 (all max with fallback) from @AnthropicAI hold the top three MLCR-AA completeness scores, ~19-23 points ahead of the best OpenAI model, and Opus and Sonnet post the highest HealthBench Professional raw scores (71.4% and 70.8%), narrowly ahead of GPT-6 Astra (69.7%) ➤ OpenAI models lead on accuracy and conciseness: OpenAI models hold the top MLCR-AA accuracy scores. Longer answers…

Longer answers contain more chances to contradict the source: Anthropic models write 4-6x more and score 19-61% on accuracy versus 89-97% for OpenAI models. Pick a model by whether your task rewards coverage or precision.
- The comparison covers 14 models on two medical benchmarks: MLCR-AA, which requires answers about long medical records to be both complete and free of claims contradicting the record, and HealthBench Professional, graded on physician-written rubrics.
- Claude Sonnet 5.5, Opus 5.5 and Fable 5.1 hold the top three MLCR-AA completeness scores, about 19-23 points ahead of the best OpenAI model, while OpenAI models hold the top accuracy scores, 89-97% against 19-61% for Anthropic models.
- The analysis links the accuracy gap to length: Anthropic models write about 4-6x more per answer, and each extra claim is another chance to contradict the record.
- On scores that reward both qualities the gap closes: GPT-6 Astra ties Claude Sonnet 5.5 for first on MLCR-AA, and Claude Opus 5.5 drops from first on HealthBench Professional's raw score to sixth once length is penalized.
Checking sign-in…
Loading comments…