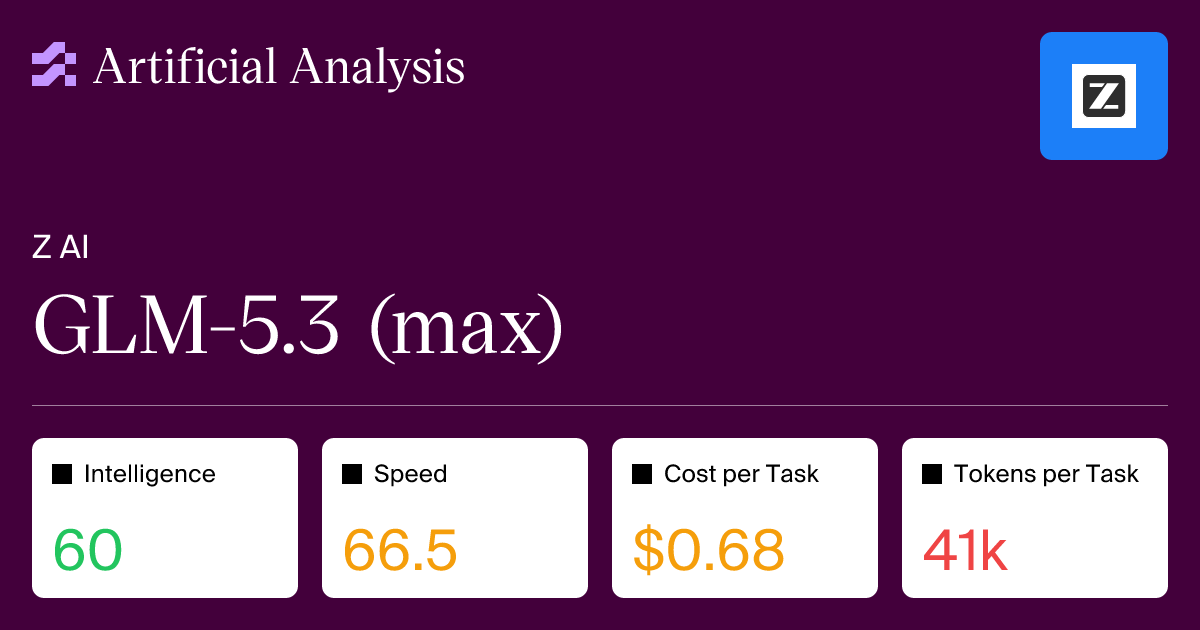
Artificial Analysis's GLM-5.3 page separates model capability from the speed of delivering an answer. In the page checked on October 12, 2026, the Max configuration scored 45 on Intelligence Index version 4.3.2, which combines ten evaluations. It also reported generation speed of 65.6 text tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → per second through Z.ai's API.
That speed measures output after generation starts. It excludes the initial wait, so it cannot by itself tell a user how long a complete answer takes. The page separately defines time to the first answer token and end-to-end response time. Model comparisons need the same configuration, index version and timing definition.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.