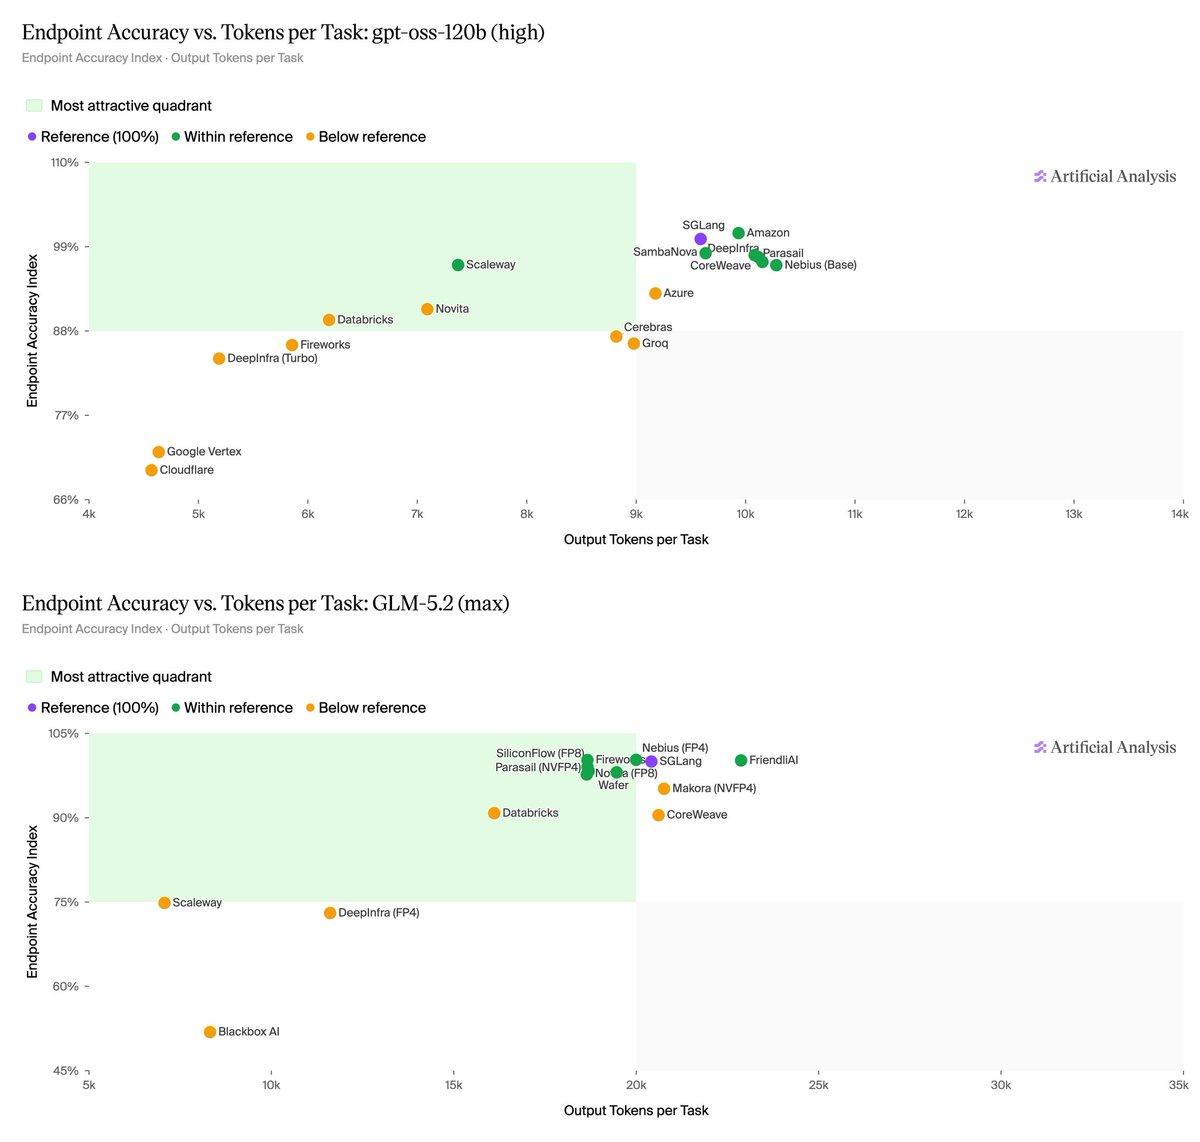
Lower-Scoring LLM Endpoints Produce Fewer Output Tokens
Source
ArtificialAnlys
Author
ArtificialAnlys
Date
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Why it matters
The same model name served by different providers can quietly reason less; output-tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → counts per task are a cheap tell for which endpoints are being throttled before you commit traffic to them.




 articleEvaluate Llm Provider PerformanceOpenRouter
 articleAre the Financial Reasoning from LLMs Credible? A Real World Test over Long-Horizon StatementsXinke Tong, Xuanming Zhang, Tianyi Tang, An Yang, Jiatu Hu, Guojie Lin, Zhenzhen Shi, Lingfeng Zeng, Boyu Yang, Bing Zhao, Hu Wei, Lin Qu, Dayiheng Liu