In long-horizon stress testing, Muse Code iteratively optimized GPU kernels…
- Source
- x.com
- Date

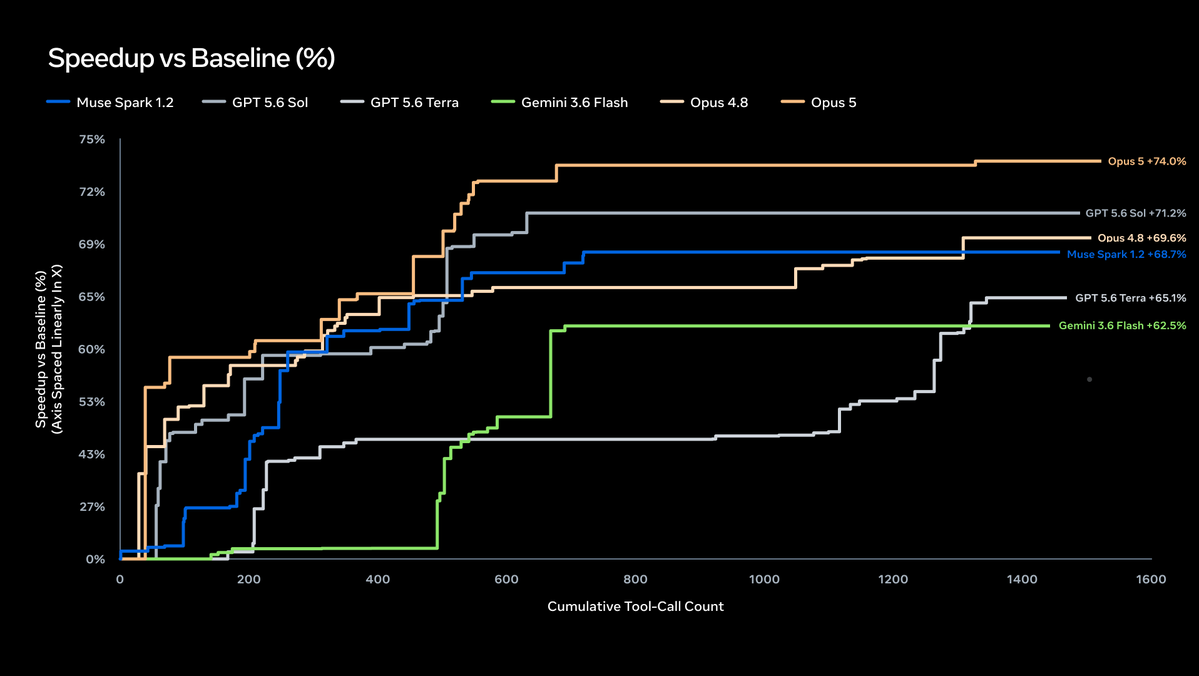
In long-horizon stress testing, Muse Code iteratively optimized GPU kernels over 1,000+ tool calls (up to 24 hours) on @nvidia Hopper GPUs, delivering very competitive performance gains for KDA and MLA relative to baseline Triton implementations.

Context
Meta tested whether Muse Code could keep improving GPU kernels, the programs that execute particular calculations on a graphics processor. Its stress-test post describes runs exceeding 1,000 tool calls and lasting up to 24 hours on NVIDIA Hopper hardware.
The release article explains the loop: write code, compile it, measure performance and revise it. The two workloads used different baselines: an existing Triton implementation for KDA and a PyTorch reference for MLA. The reported gains therefore concern those particular comparisons, rather than a general speed increase for GPU software.
Checking sign-in…
Loading comments…