Extending the Context Length to 1M Tokens!
- Source
- qwenlm.github.io
- Author
- Qwen Team
- Date
Context
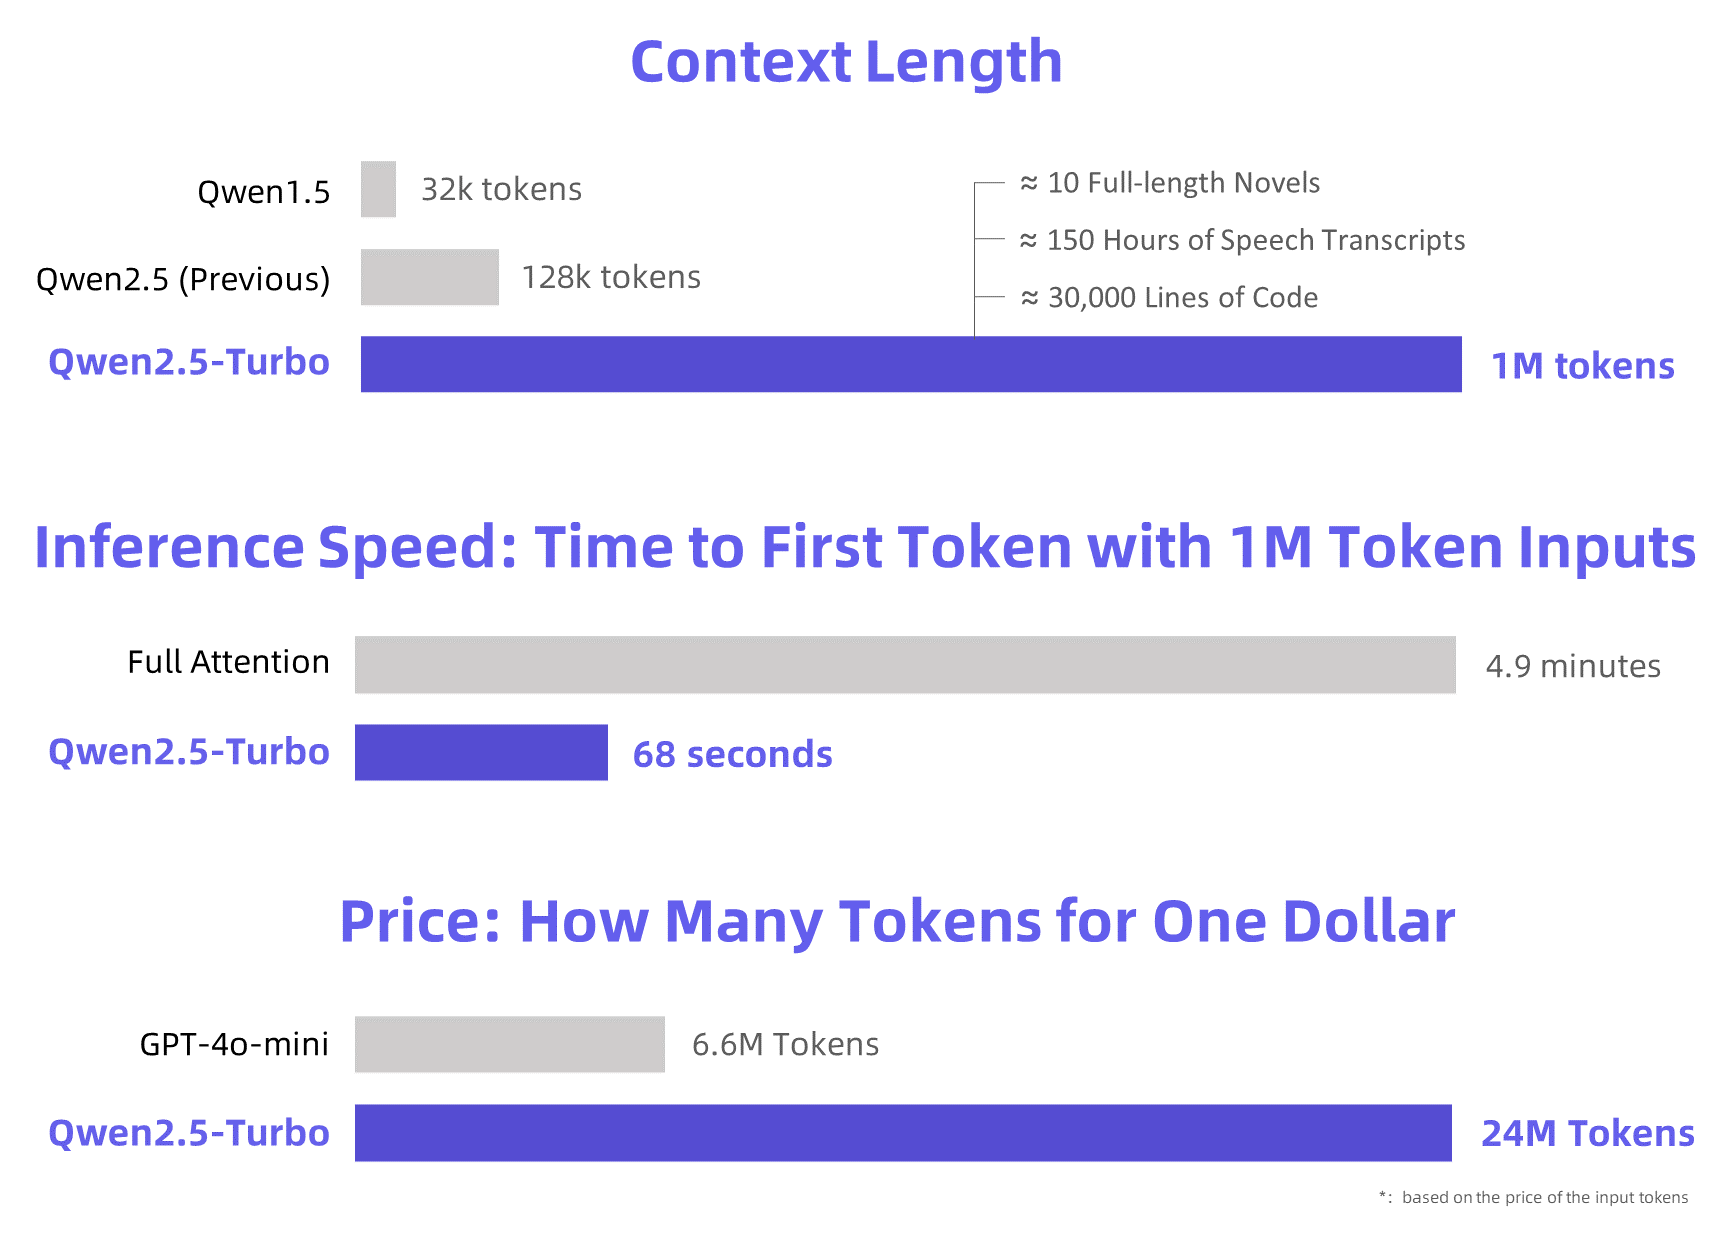
The million- Qwen2.5-Turbo update addressed the wait before a model starts answering a very long input. Qwen reported reducing that wait from 4.9 minutes to 68 seconds using sparse , which reduces attention computation. This was time to the first generated text unit, so the result describes input-processing latency rather than the speed of the entire answer. The November 2024 announcement also expanded the supported from 128,000 to one million tokens.
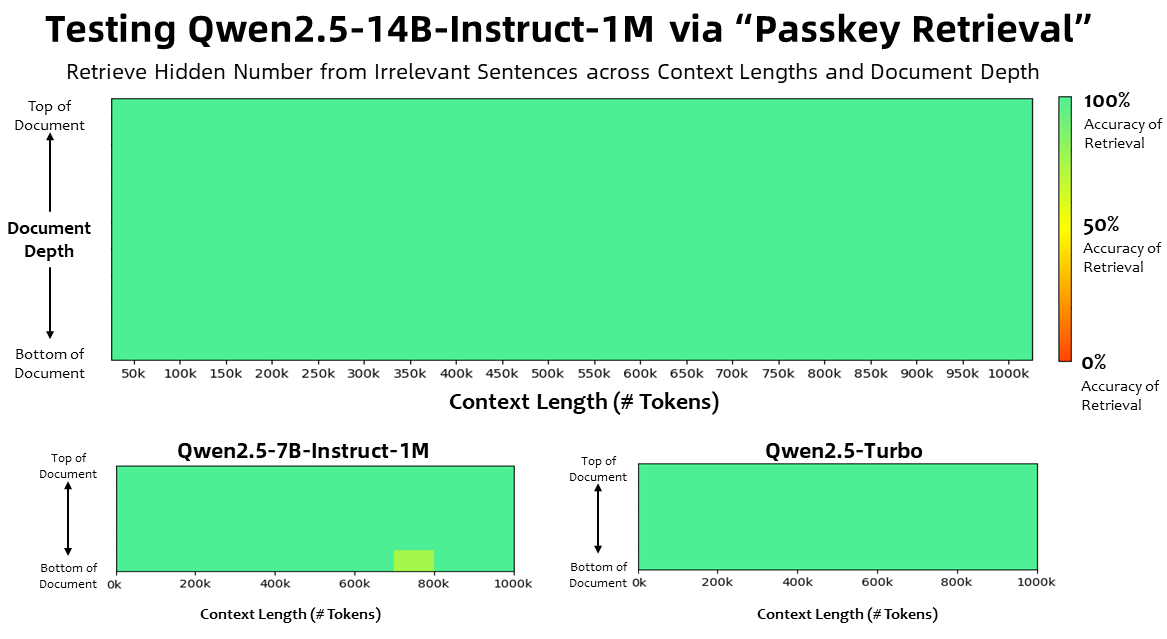
The strongest million-token test reported was retrieval of hidden numbers. More complex evaluations used shorter inputs, up to 256,000 tokens. The release therefore established expanded capacity and faster initial processing, while leaving broad reliability across million-token reasoning tasks unresolved.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
Checking sign-in…
Loading comments…