WANDR opens up a benchmark that verifies claims against live sources
- Source
- x.com
- Date

We’re open sourcing WANDR. WANDR is an internal benchmark we built and used for building deep and wide research capabilities inside Perplexity Computer. https://t.co/gp2BWjFK4d
Wide-and-deep research requires two capabilities. 1) Agents must search broadly enough to find all qualifying entities 2) Agents must investigate deep enough to support every claim with evidence.

WANDR represents these requirements as hierarchical, independently verifiable records. It consists of 500 research tasks that require 170,495 source-backed records across three tiers of difficulty.

WANDR tests how well agents discover large sets of entities and verify specific facts about each one. It provides a dense, interpretable eval signal that reveals whether an agent fails, and where. The pipeline also doubles as a semi-automated factory for training data.

Context
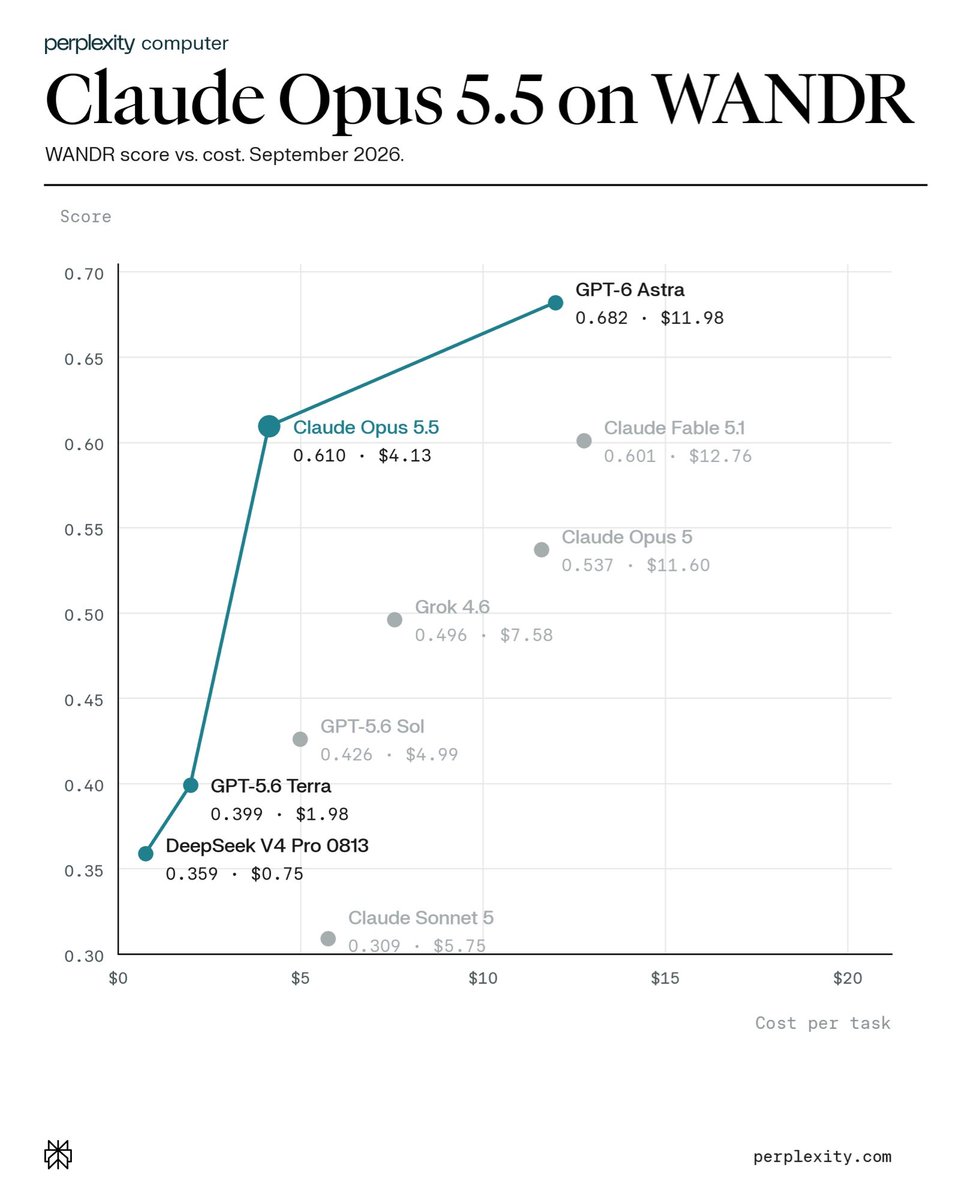
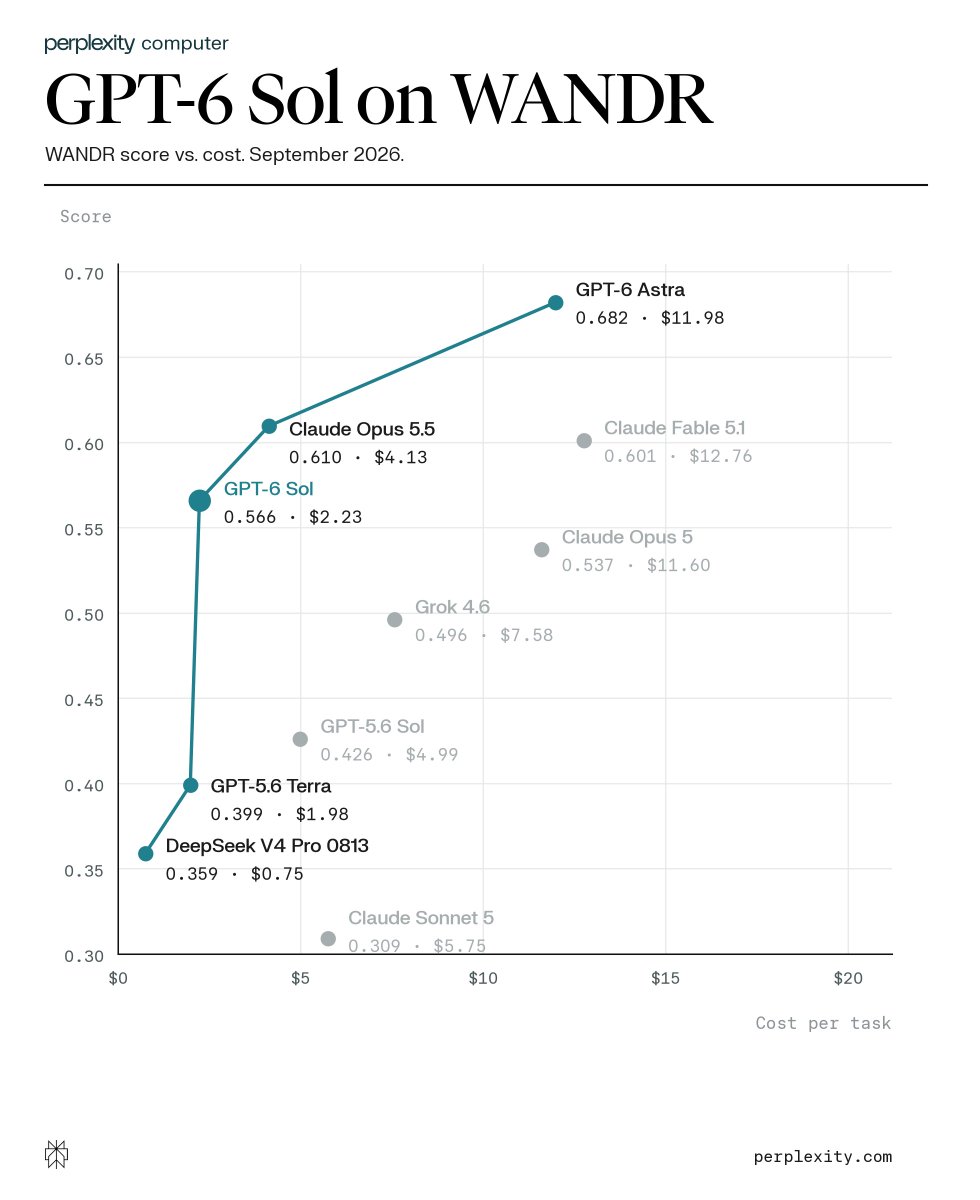
Perplexity built WANDR to test whether a research can assemble a complete collection and substantiate its entries. Its 500 tasks break research into individually checkable records. The grader retrieves cited pages again and checks the submitted claims against them, accommodating facts that change. Partial completion earns credit under the soft score; the hard score counts an entry only when every required part is correct. That separates finding convincing examples from completing the requested research. The benchmark description explains both measures.
 articleBenchmarking Hybrid Deep Research Across Database Querying and Web SearchRuofan Wu, Peiran Xu, Xiaolong Li, Fan Shu, Soyoung Yoon, Yite Wang, Xiaodong Yu, Boyi Liu, Feng Yan, Debiao Li, Yuxiong He, Zhewei Yao
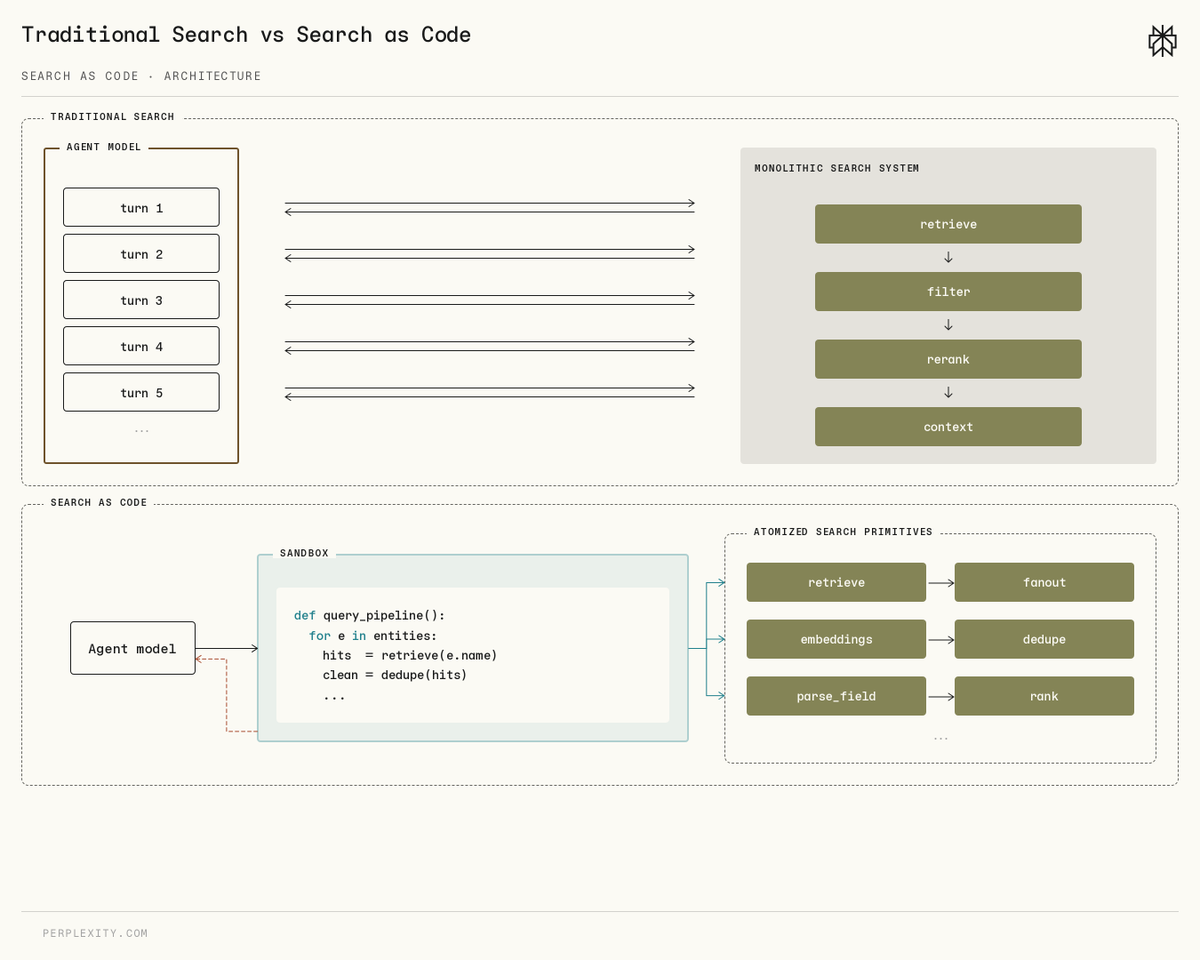 postSearch as Code: let the model write retrieval instead of calling toolsPerplexity
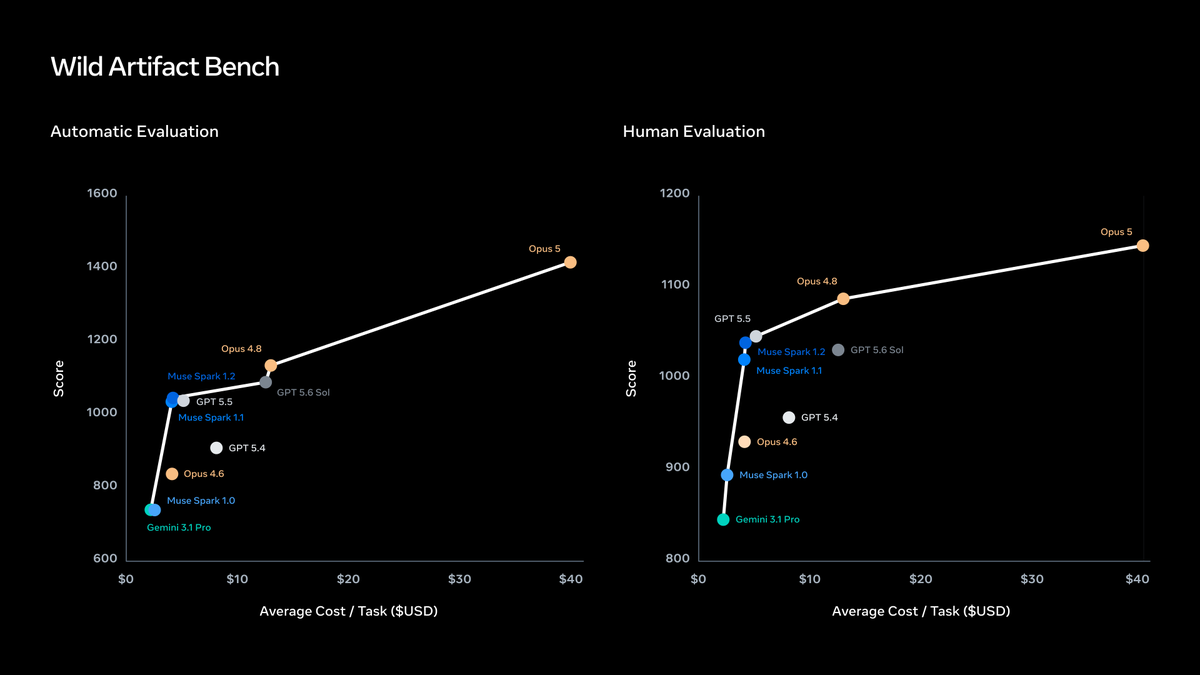 postMeta previews WildArtifactBench and releases ten of its tasksAI at Meta
Checking sign-in…
Loading comments…