GPT-6 Sol and Luna halve OpenAI's cost per intelligence
- Source
- x.com
- Date

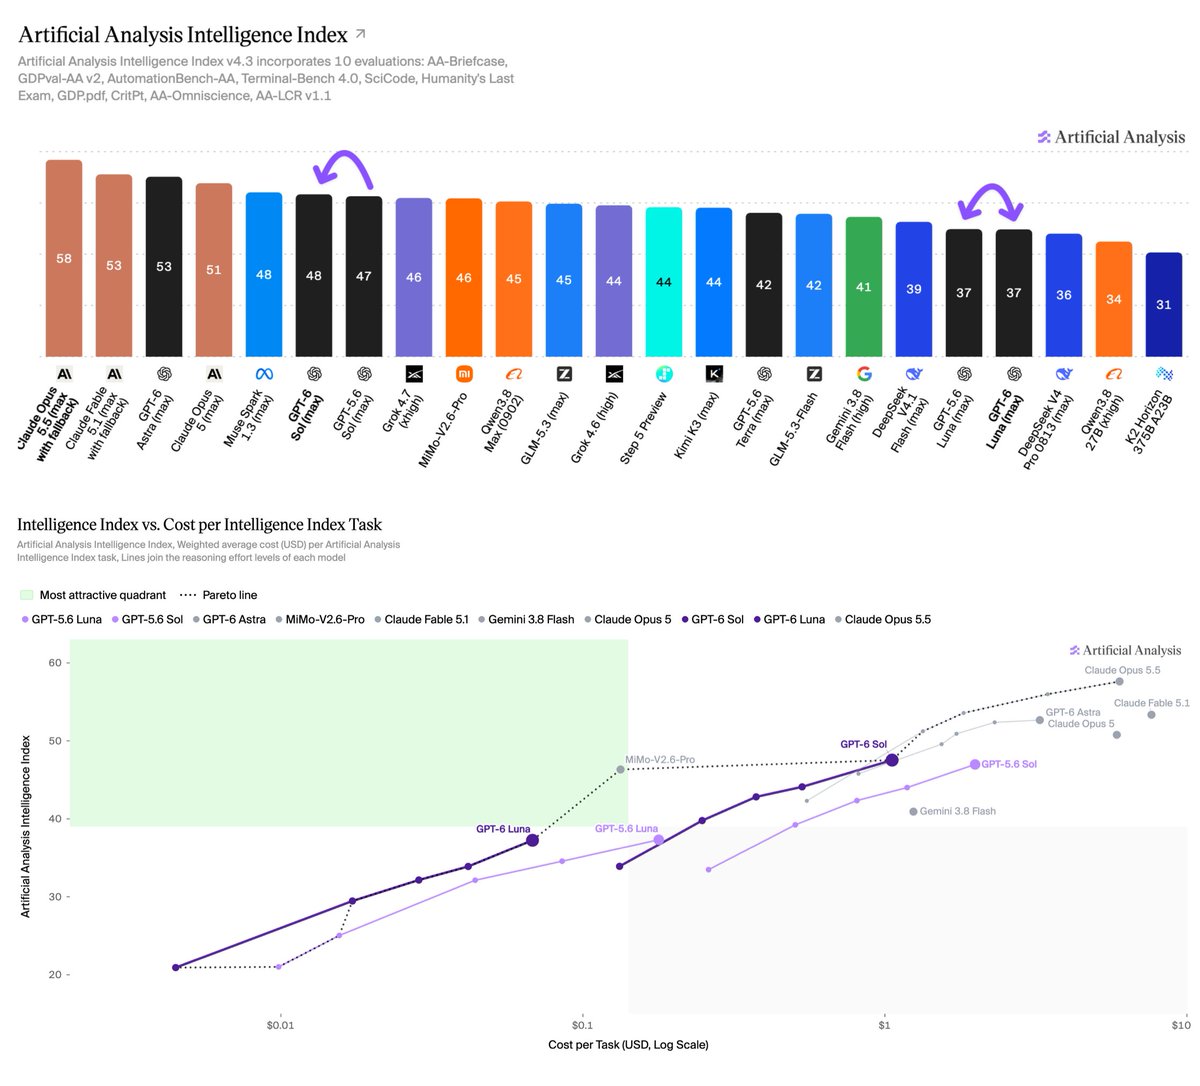
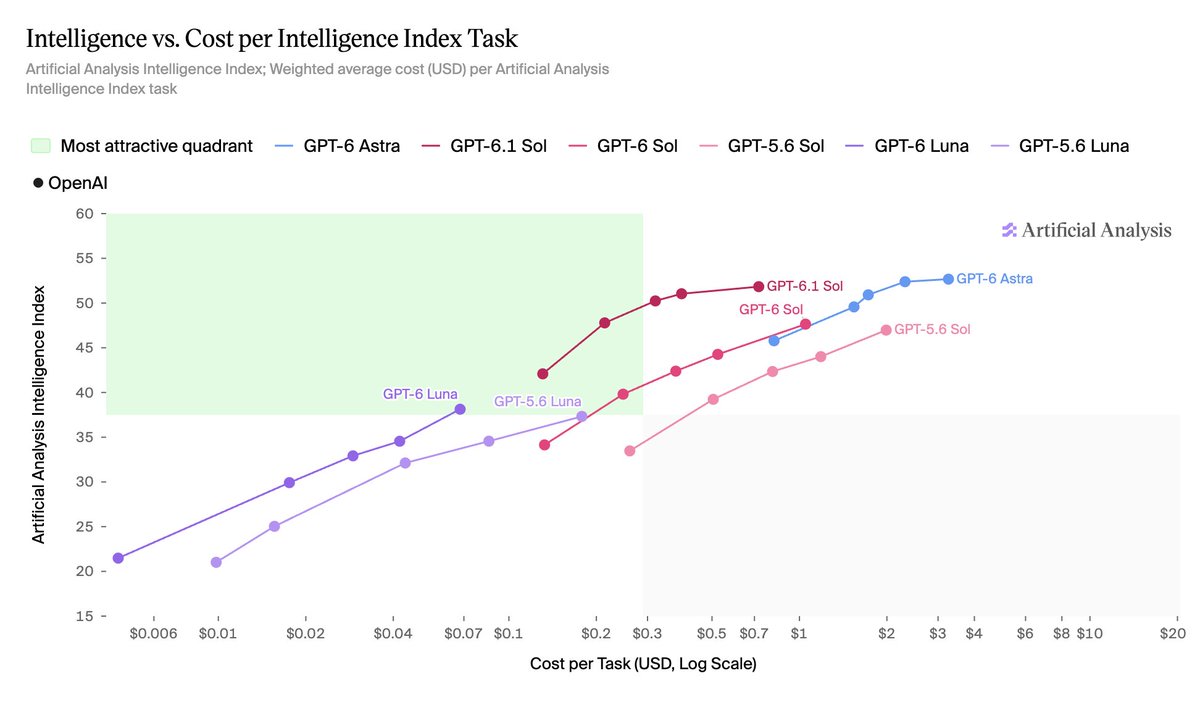
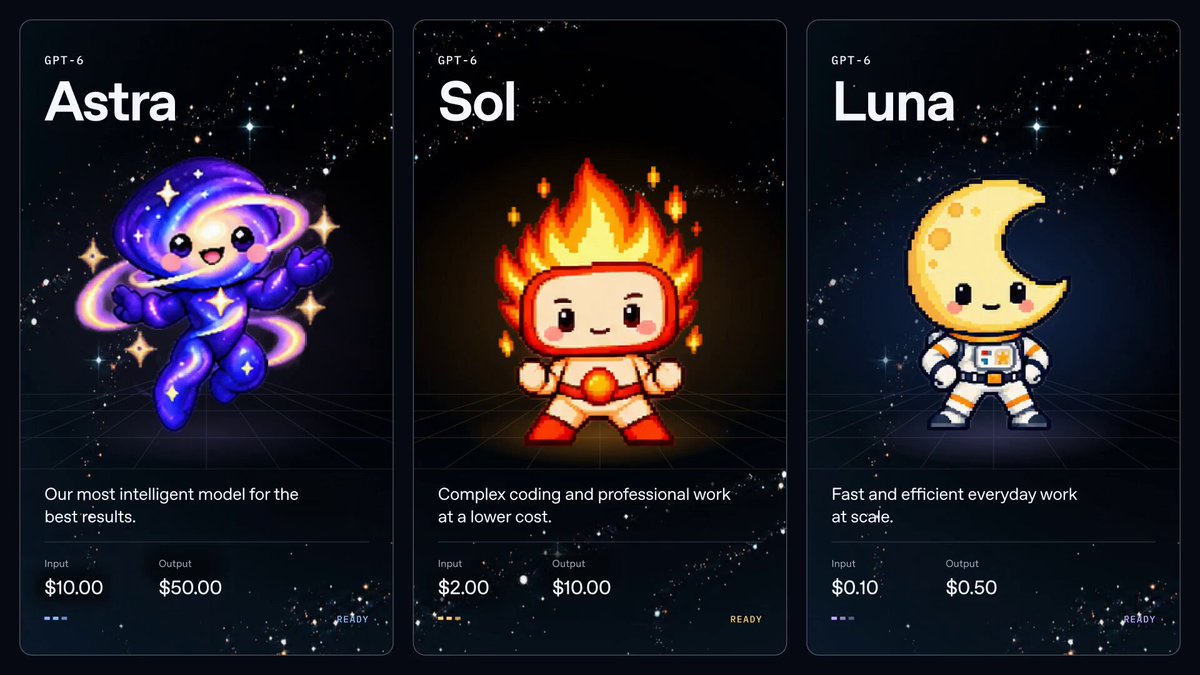
GPT-6 Sol and Luna continue to push the cost efficiency frontier for OpenAI. The two new models halve the cost of their predecessors with similar scores in the Intelligence Index Charting the Artificial Analysis Intelligence Index shows the trade-off between Intelligence and Cost per Intelligence Index Task. Cost improvements in GPT-6 Sol and Luna are driven by a ~50% reduction in token pricing

Context
OpenAI's GPT-6 Sol and GPT-6 Luna score about the same as their predecessors on the Artificial Analysis Intelligence Index while costing half as much to run it, and the saving comes from lower prices. That is the reading from Artificial Analysis, a firm that benchmarks AI models, which says the cost improvement is driven by a roughly 50% reduction in token pricing.
The firm charts each model's Intelligence Index score against its cost per Intelligence Index task, meaning what it costs to have the model complete one task in the firm's suite. A model pushes the cost efficiency frontier when it reaches a given score for less money than earlier models did. Sol and Luna move that line by holding their predecessors' scores at about half the cost, not by scoring higher. OpenAI announced the price cut in its own launch post for the two models.
For someone paying for API access, the post points to a cheaper route to the same performance, not a more capable model. The post does not name the predecessor models or give their scores, and its charts were not available for this explanation, so the specific figures behind 'similar scores' are not shown here.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…