Cua's RL-Trained Decision Model Hits 92.9% on GUI-360, Open-Sourced
- Source
- Cua
- Date

1/ Today we're introducing Cua-S1-4B-0.2, the first multimodal decision model trained with RLOO on live computer-use tasks, using task-completion rewards. Text and multimodal adapters are available under Apache-2.0: https://t.co/0R5fWjfpGg

2/ At each step, the CUA-S1 model receives the screen state, the task goal, and a fixed set of candidate actions. It returns one action. The environment changes, and the next step starts from the new state.
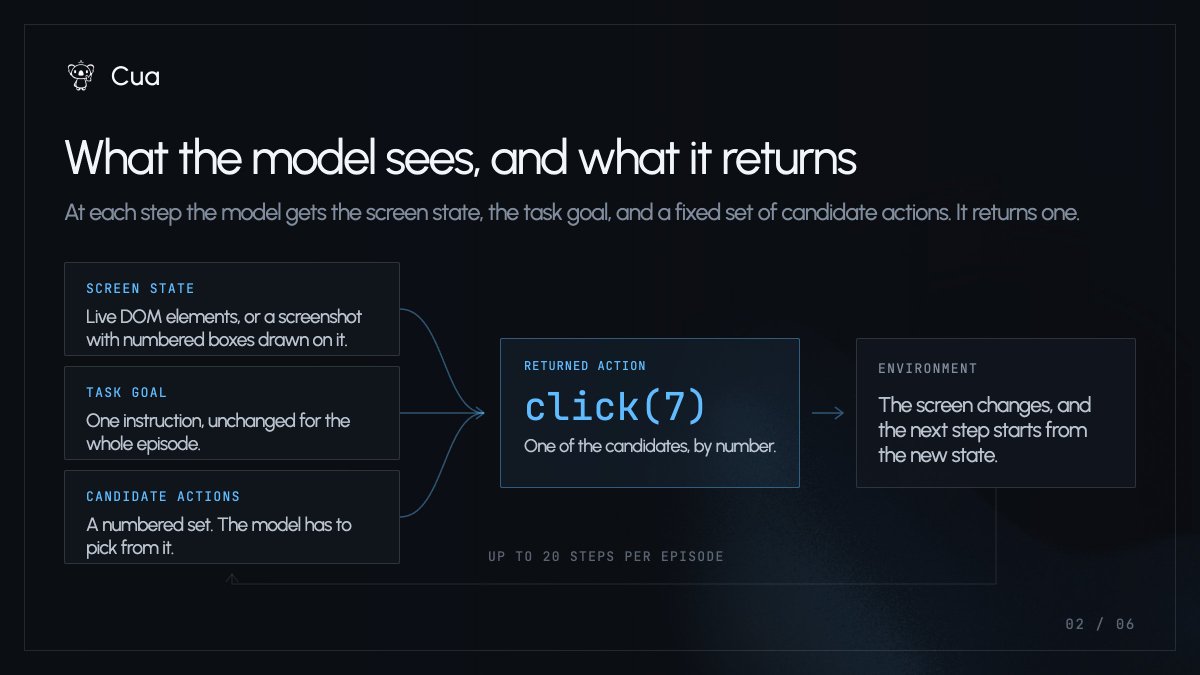
3/ The training recipe has two stages. Supervised training teaches the decision format. Agentic RL then runs the model in live cua-bench-basic environments, where only a completed task earns the environment's reward.

4/ On the same held-out tasks, Cua-S1-4B-0.2 completes 17/18 text episodes and 13/18 multimodal. Zero-shot djev completes 16/18 and 12/18.

- Training has two stages: supervised training teaches the decision format, then agentic RL with RLOO runs the model in live cua-bench-basic environments where only a completed task earns the environment's reward.
- At each step the model gets the screen state, the task goal and a fixed set of candidate actions, and returns one action; the environment then changes and the next step starts from the new state.
- On held-out tasks, Cua-S1-4B-0.2 completed 17 of 18 text episodes and 13 of 18 , versus 16 and 12 for zero-shot djev, a much smaller gap than the 92.9% versus 60.1% result on the frozen 168-task GUI-360 split.
- Both GUI-360 runs used the same inputs and scoring with no accessibility tree. The training code and results are merged into the Cua repo, and a Hugging Face Space lets users see how the model scores candidate actions.
- multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
A concrete, reproducible RL recipe and for training small models to make GUI decisions from raw screen state, without needing an accessibility tree.
Checking sign-in…
Loading comments…