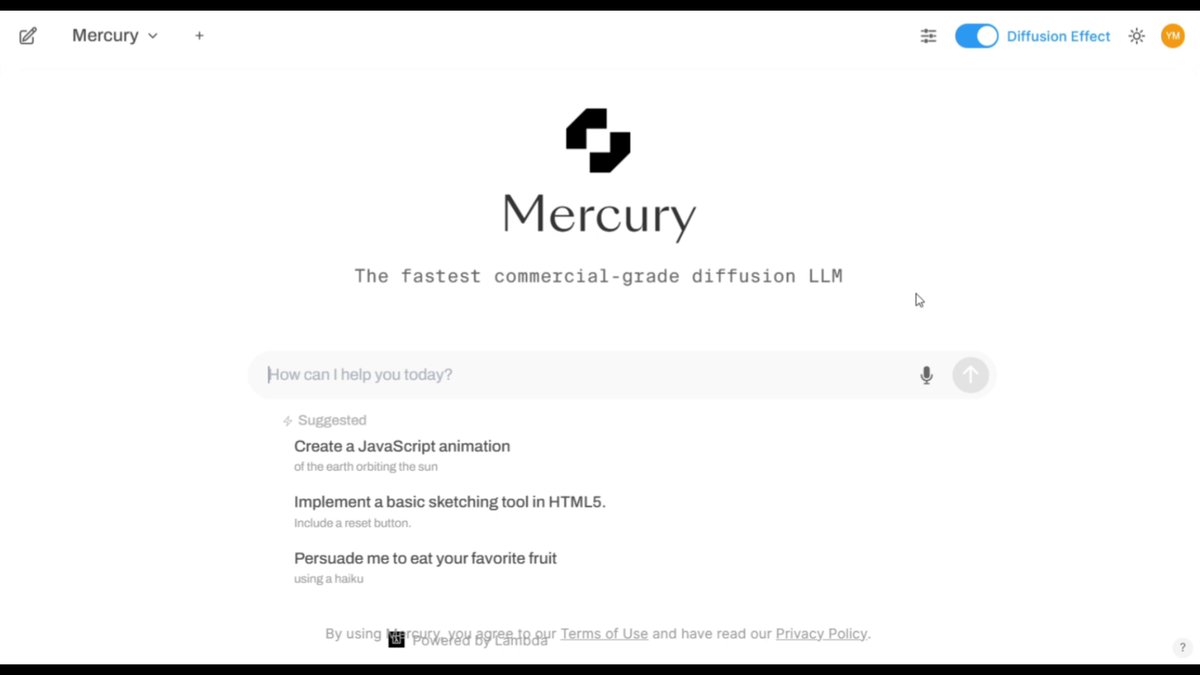
Inception extended its diffusion-based language technology from coding to general chat with Mercury. The chat-model announcement reports output throughput of 708 tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → per second and describes uses in conversational websites and voice applications.
The mechanism comes from the company's earlier Mercury introduction: the model progressively improves an answer by changing multiple text positions together, as explained in its technical overview. This offers a different way to reduce generation time. The launch table shows varied results across knowledge, mathematics, and coding tests, so the speed figure is more informative than treating Mercury as uniformly equal to every model it compares against.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
 postInception ships Mercury Decide update with ZDR and 66k context
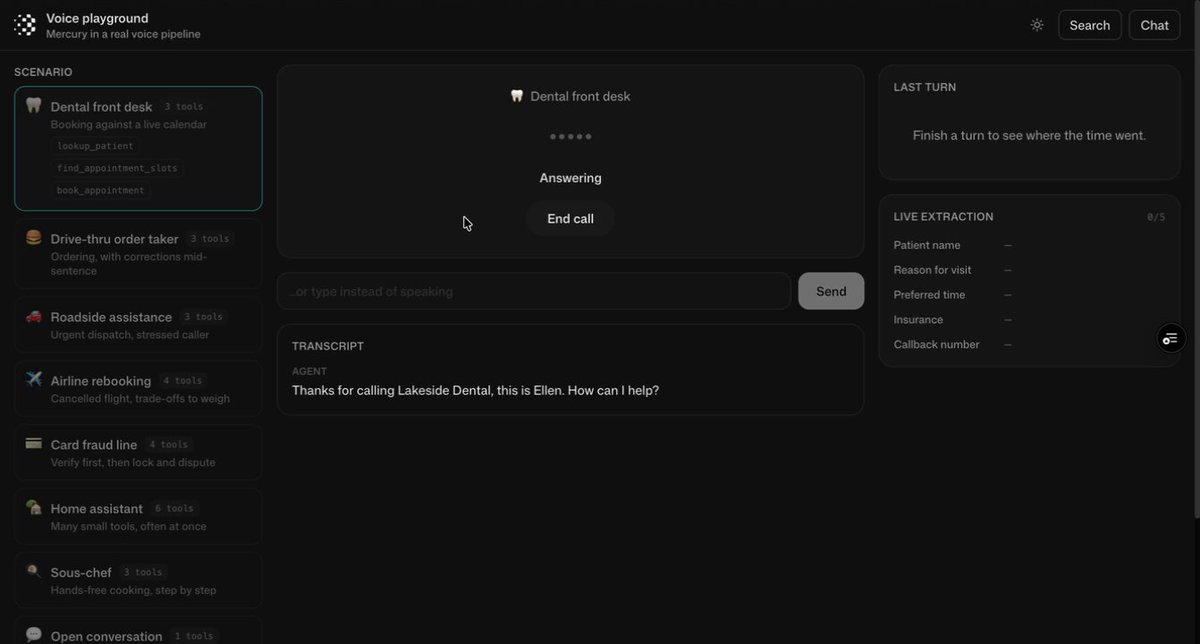 postInception launches Mercury Voice, a diffusion LLM for low-latency voice agents
 postToday, we’re introducing Mercury 2.5, the most capable diffusion LLM on the…
 postInception ships Mercury 2.5 Preview at roughly 1,100 tokens per second