GPT-6.2 Astra tops AA-3D human-preference benchmark
- Source
- x.com
- Date

GPT-6.2 Astra ranks #1 on AA-3D, our benchmark measuring how well models can build interactive 3D experiences. Humans preferred these scenes in 139 of 152 head-to-head votes against other models

Context
GPT-6.2 Astra, which OpenAI released on November 17, now ranks first on AA-3D, Artificial Analysis's of how well AI models build interactive 3D scenes, but its lead is narrow. On the live leaderboard, as of November 18, Astra scores 1318 against 1271 for Claude Fable 5.2, with 95% confidence intervals of 1286 to 1349 and 1246 to 1297. Those ranges overlap. A week earlier, Artificial Analysis announced Fable 5.2's first place by noting that its interval did not overlap any other model's, which put that lead outside the margin of error. Astra's lead does not pass that test.
The ratings come from people judging finished scenes. In AA-3D, which launched in October, each model works as an in an offline , with tools such as Blender and a headless browser for testing its own work, and turns a written brief into a 3D web page that runs in a browser. A recruited panel compares two scenes built from the same brief without knowing which model made which. According to the methodology, the votes feed a Bradley-Terry model, a standard way to estimate each competitor's strength from who beat whom, rescaled to look like chess-style Elo ratings.
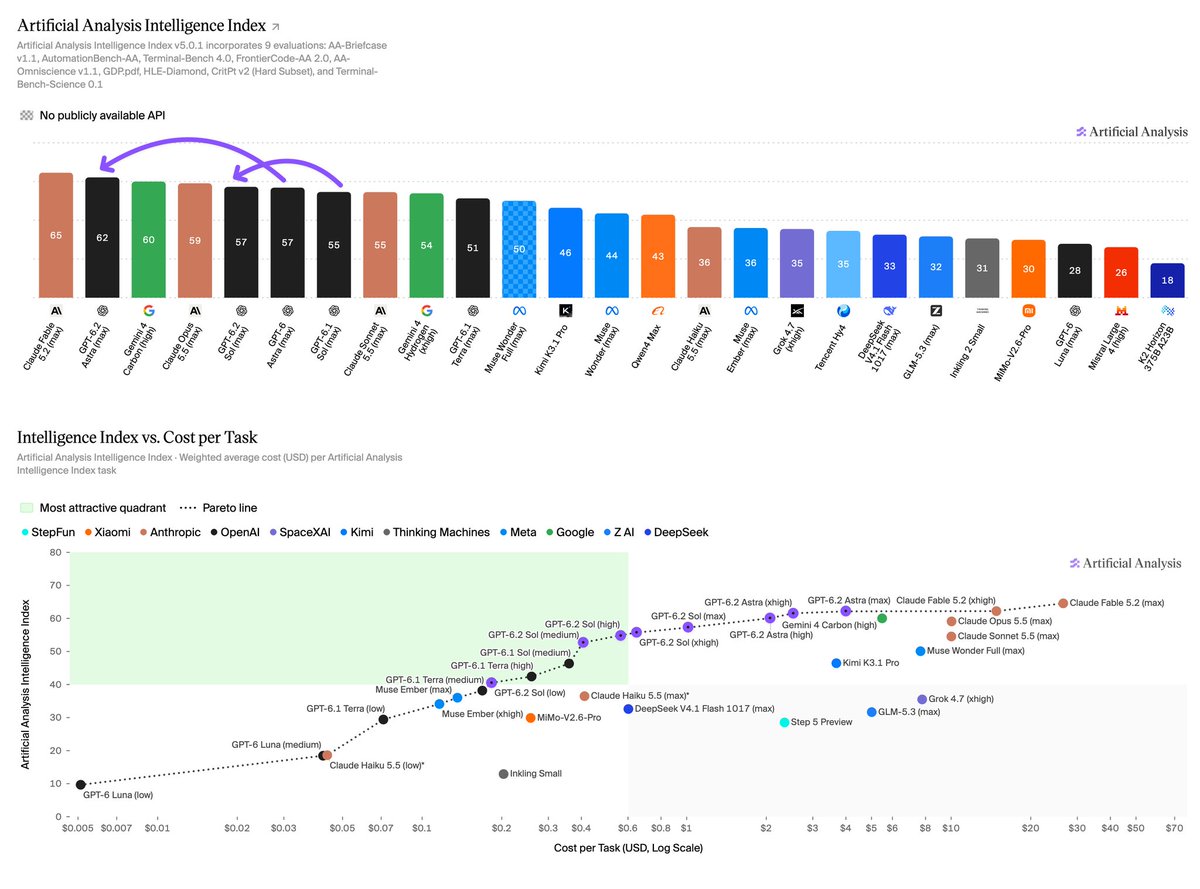
The figure in Artificial Analysis's post, that panelists preferred Astra's scenes in 139 of 152 head-to-head votes, is a raw share of about 91%. The post does not say which models those votes were against, and the rating adjusts for the strength of each opponent, which is why the ranking rests on the rating rather than the share. The attached video could not be reviewed. The result also says nothing about coding in general: in its review of the release, Artificial Analysis found Astra no better than its predecessor on its Coding Agent Index.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- sandbox — An isolated environment where AI-generated code or agent actions run without being able to touch anything real.

Checking sign-in…
Loading comments…