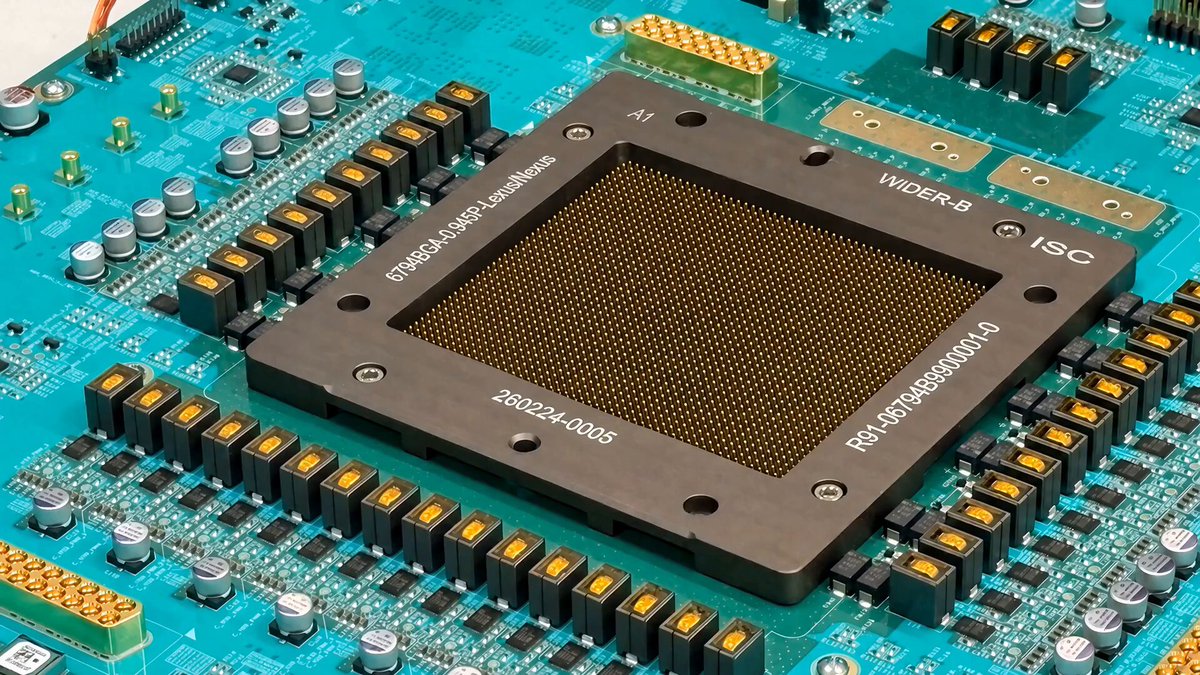
OpenAI's Jalapeño chip is designed for inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition →, the computation that generates model responses. OpenAI and Broadcom announced it on June 24, 2026, and OpenAI's announcement describes a chip built for the language-model workloads behind ChatGPT, Codex and the API.
The announcement reported engineering samples running model workloads in the lab at target production frequency and power. Large-scale deployment remained a plan, and further performance reporting was still to come. The supported milestone is a working custom chip and a route toward deployment; the announcement does not establish that Jalapeño was already serving customers at scale.
Terms in this piece · Glossary
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.