It tests agents on connected multi-week projects rather than isolated prompts, and separates correctness from presentation quality. Use it for realistic comparisons, including cost against open-weights options like GLM-5.2.
Key takeaways · AI-distilled
AA-Briefcase runs models through four multi-week projects with 91 private tasks and nearly 2,000 source files, including more than 3,500 emails and 25,000 Slack messages that are fragmented and sometimes contradictory.
Scoring combines binary rubric checks for correctness with pairwise grading of analytical and presentation quality, so outputs that look polished but are wrong or shallow are exposed rather than rewarded.
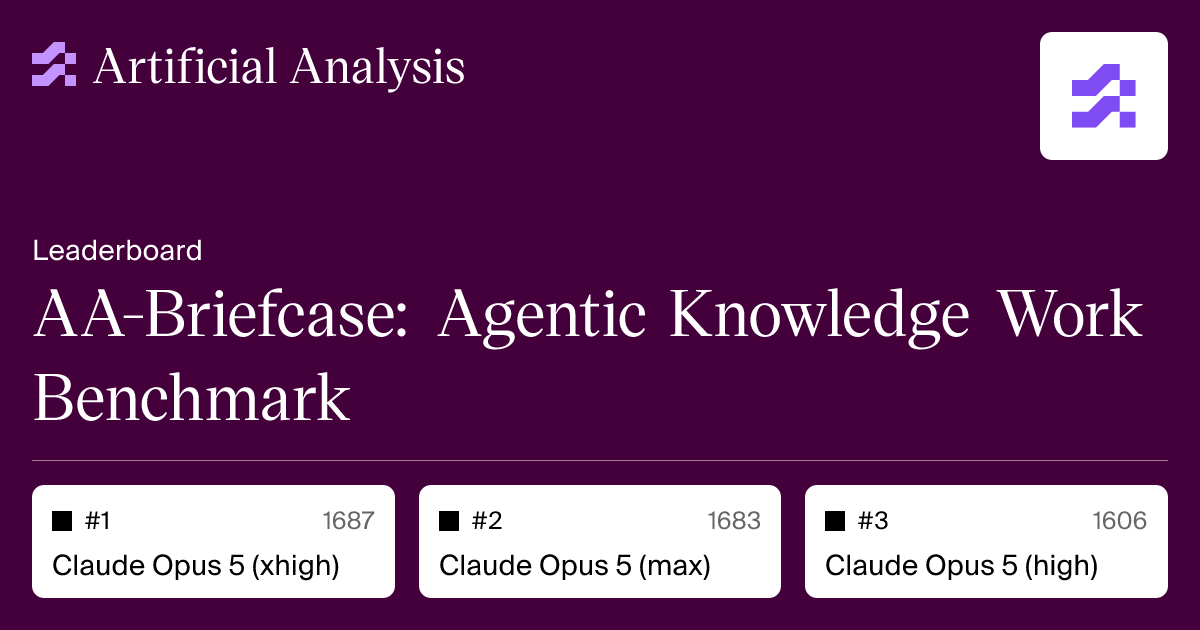
At launch Claude Fable 5 led the combined Elo, followed by Claude Opus 4.8 (max) and GLM-5.2 (max), with GPT-5.5 (xhigh) fourth; GLM-5.2 was the clear open weightsA model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.Full definition → leader on capability versus cost.
Scenarios were built over months by experts in data science, product management and corporate strategy from firms including Google, McKinsey and BCG; a fifth public scenario on Hugging Face is demonstrative and does not count.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.