A published methodology for grading agents on realistic multi-week deliverables — rubric checks plus pairwise quality judgments — that you can borrow when designing evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → for long-horizon knowledge work.
Terms in this piece · Glossary
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
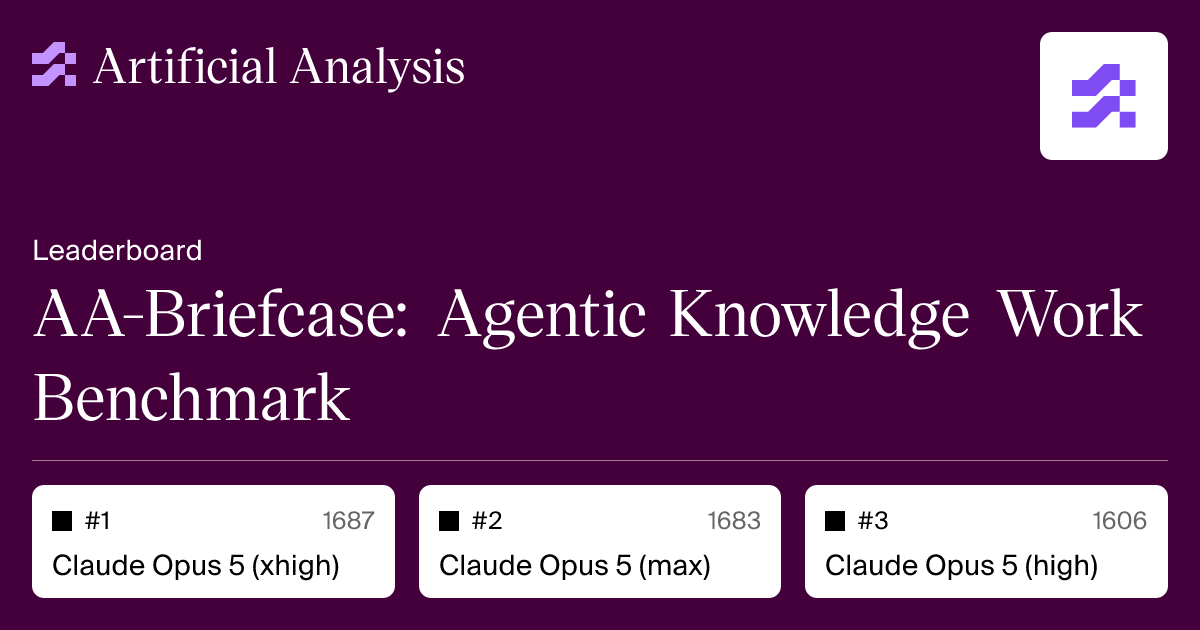
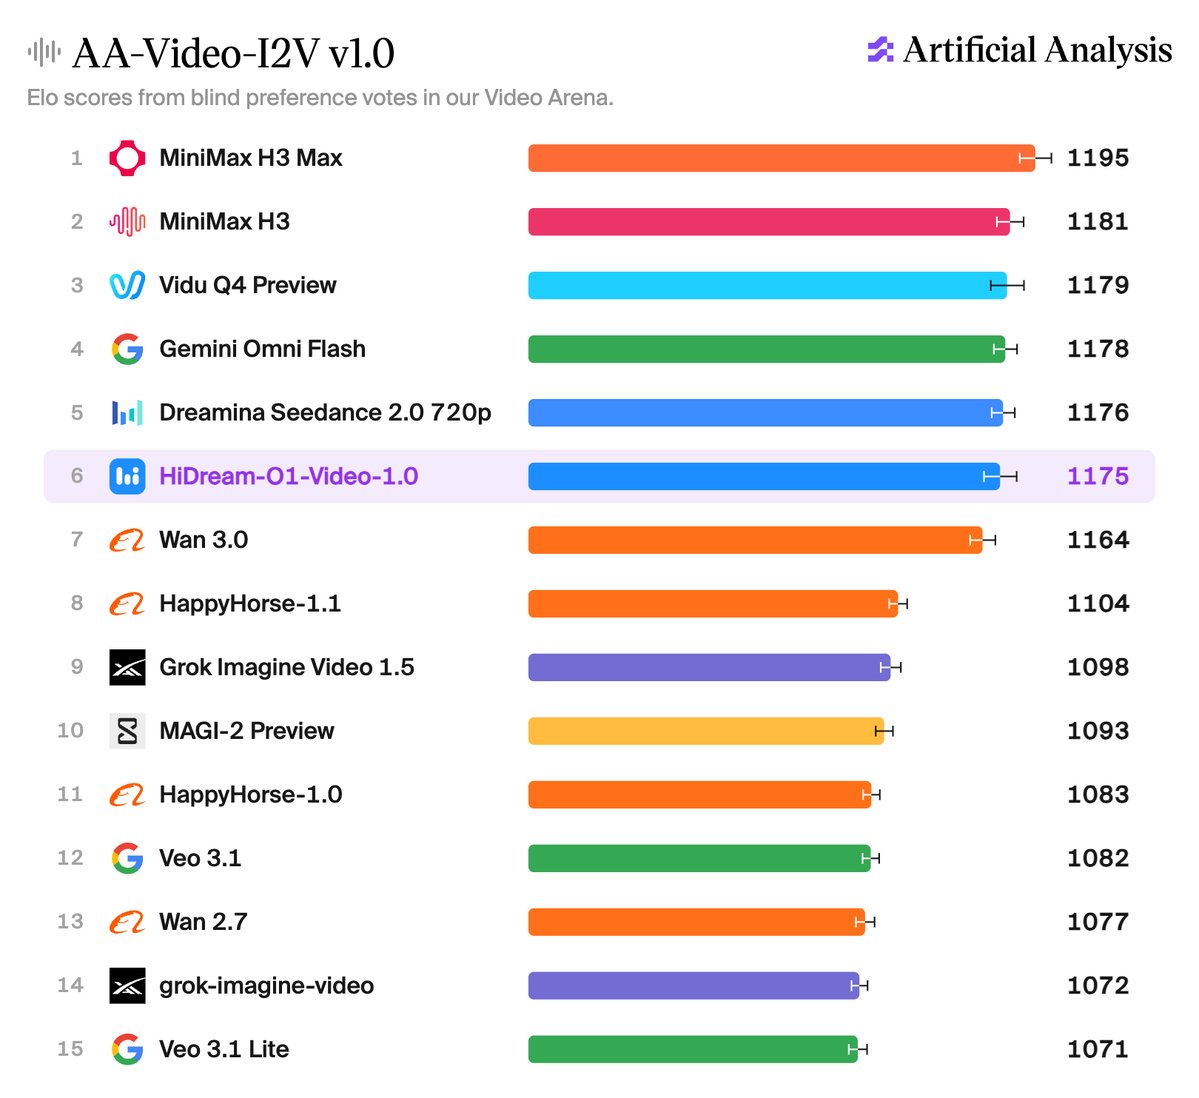
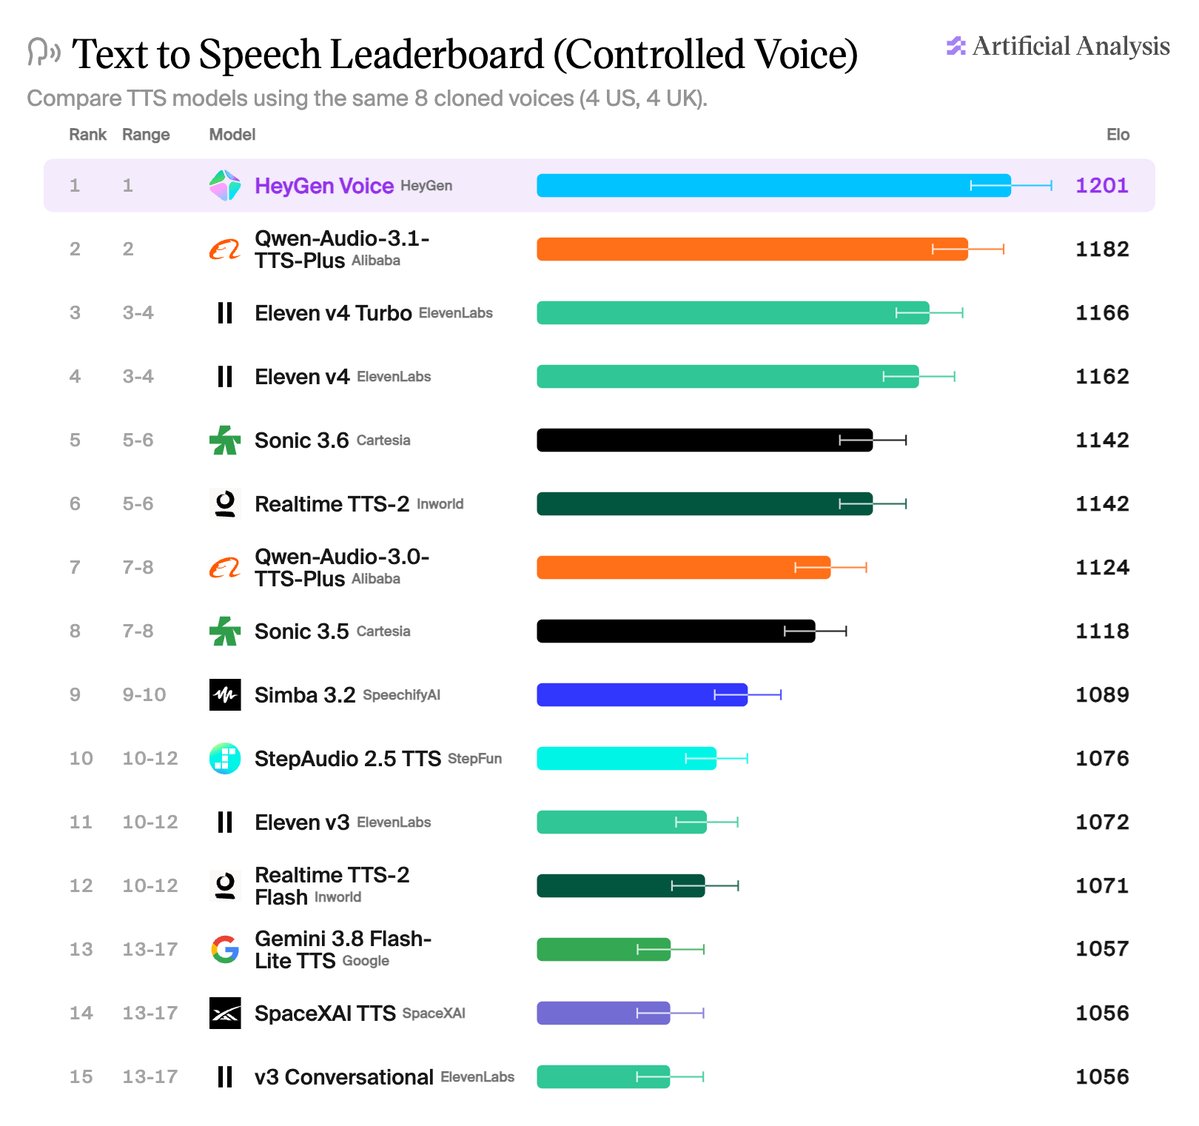
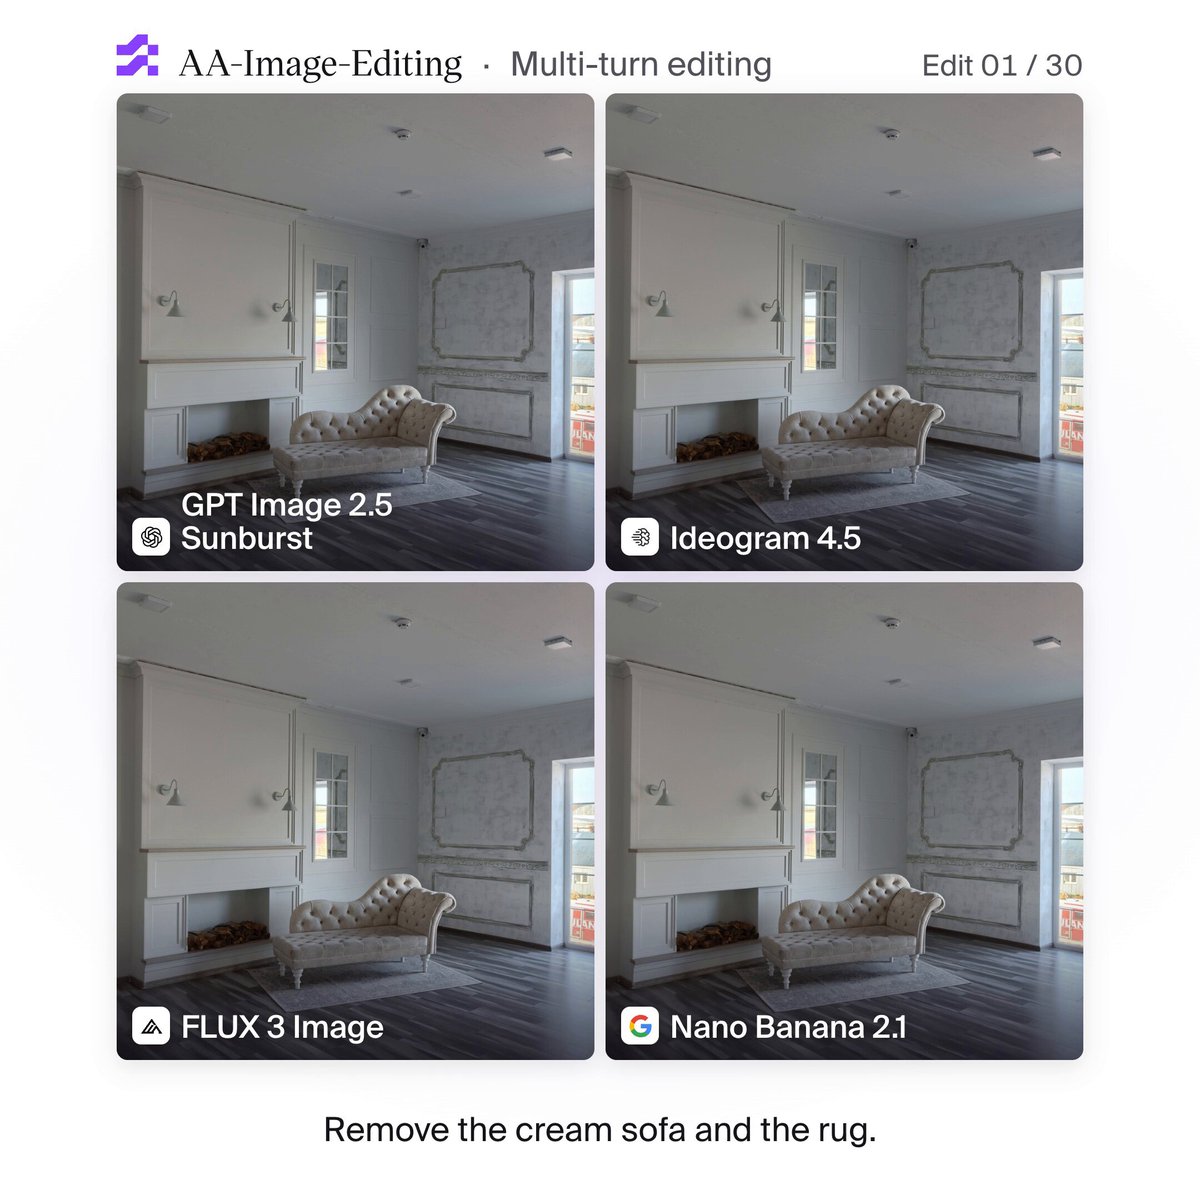
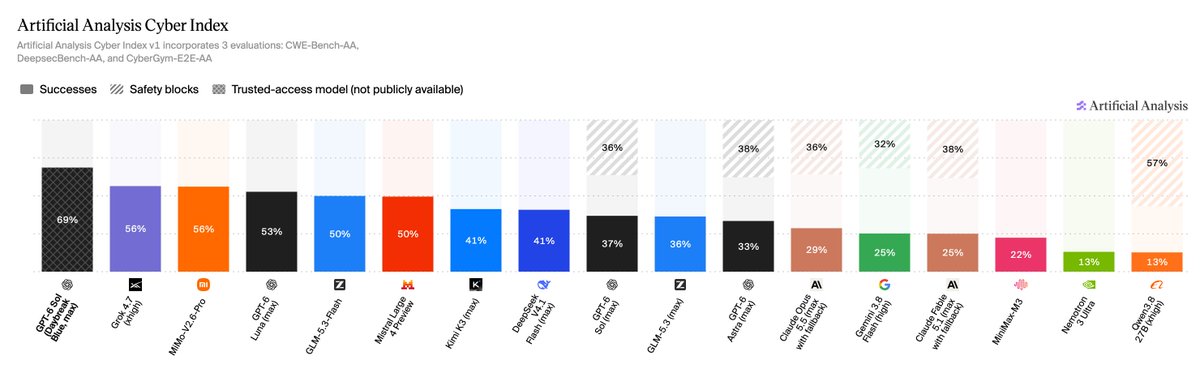
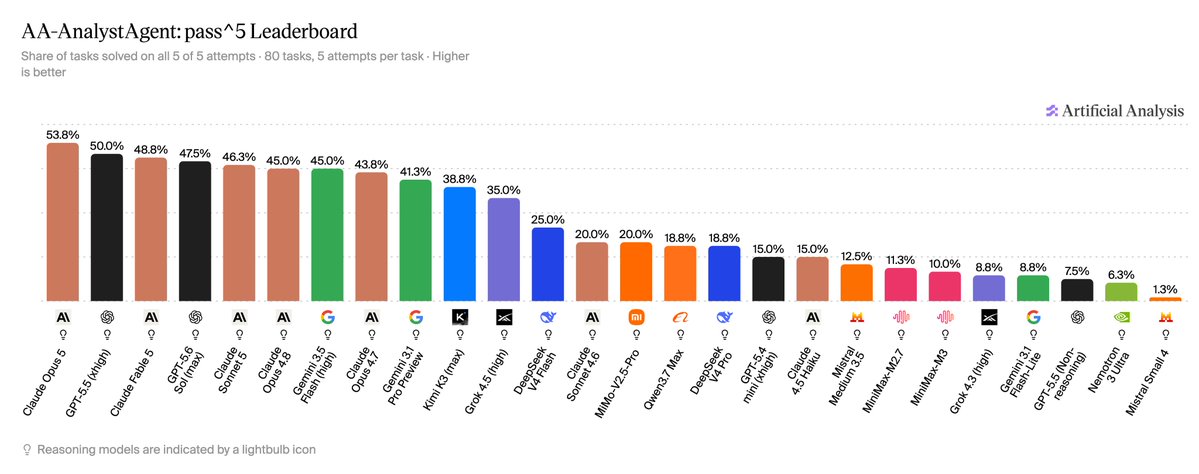 postAnnouncing AA-AnalystAgent, our new agentic benchmark for quantitative analysis…Artificial Analysis
 videoStanford CS329A Self-Improving AI Agents | Part 8 | Agentic Evaluations and Long Horizon TasksStanford Online
 articleEvaluating Enterprise Analytics Agents: An End-to-End, Trace-Backed MethodologyTeja Venkat Kolli, Sang Su Lee, Xueying Yan, Jessie Chen, Chi Cheng, Kartik Ravisankar, Shishir Dash, Vijay Anand Raghavan