GPT-6 Astra tops Perplexity's WANDR benchmark at $11.98 per task
- Source
- x.com
- Date

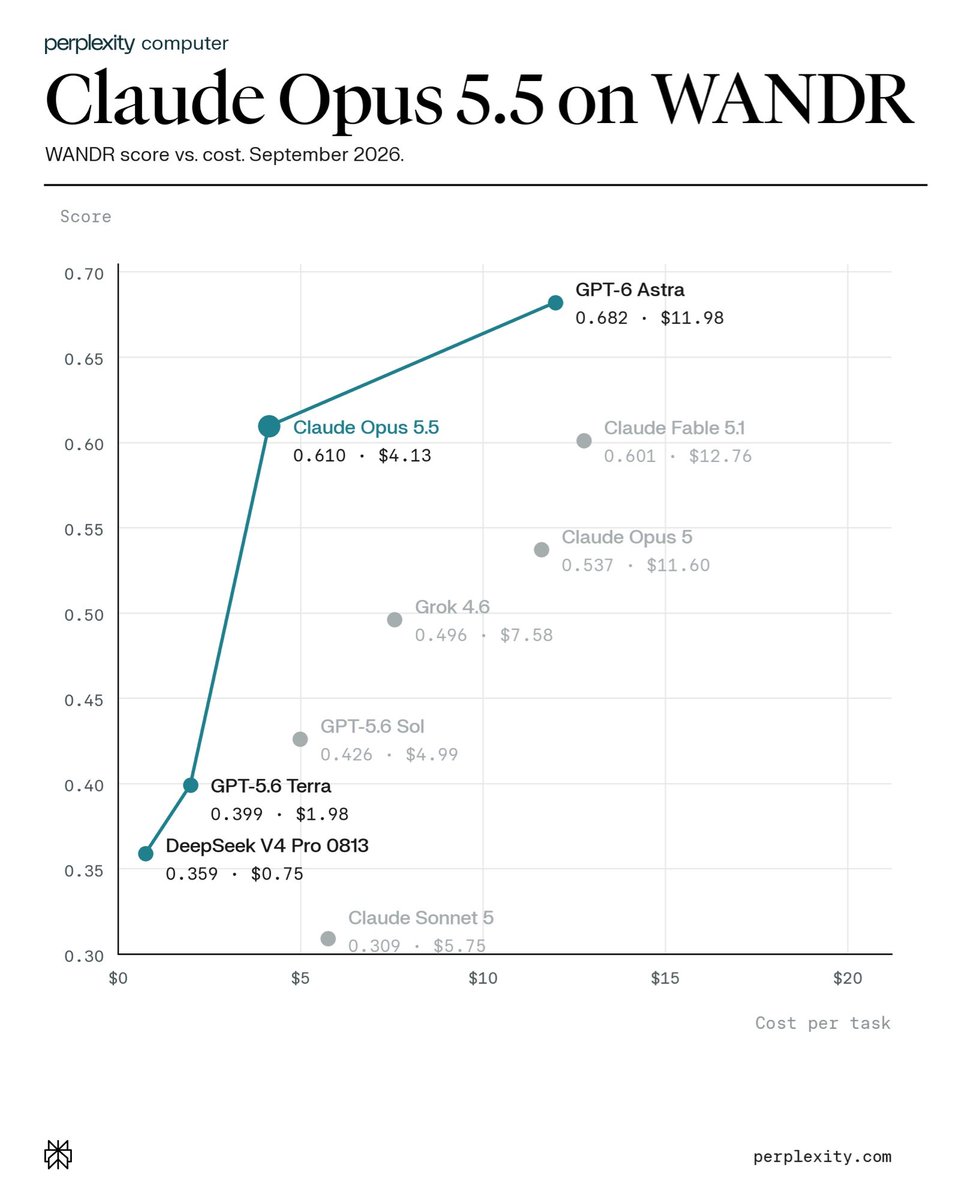
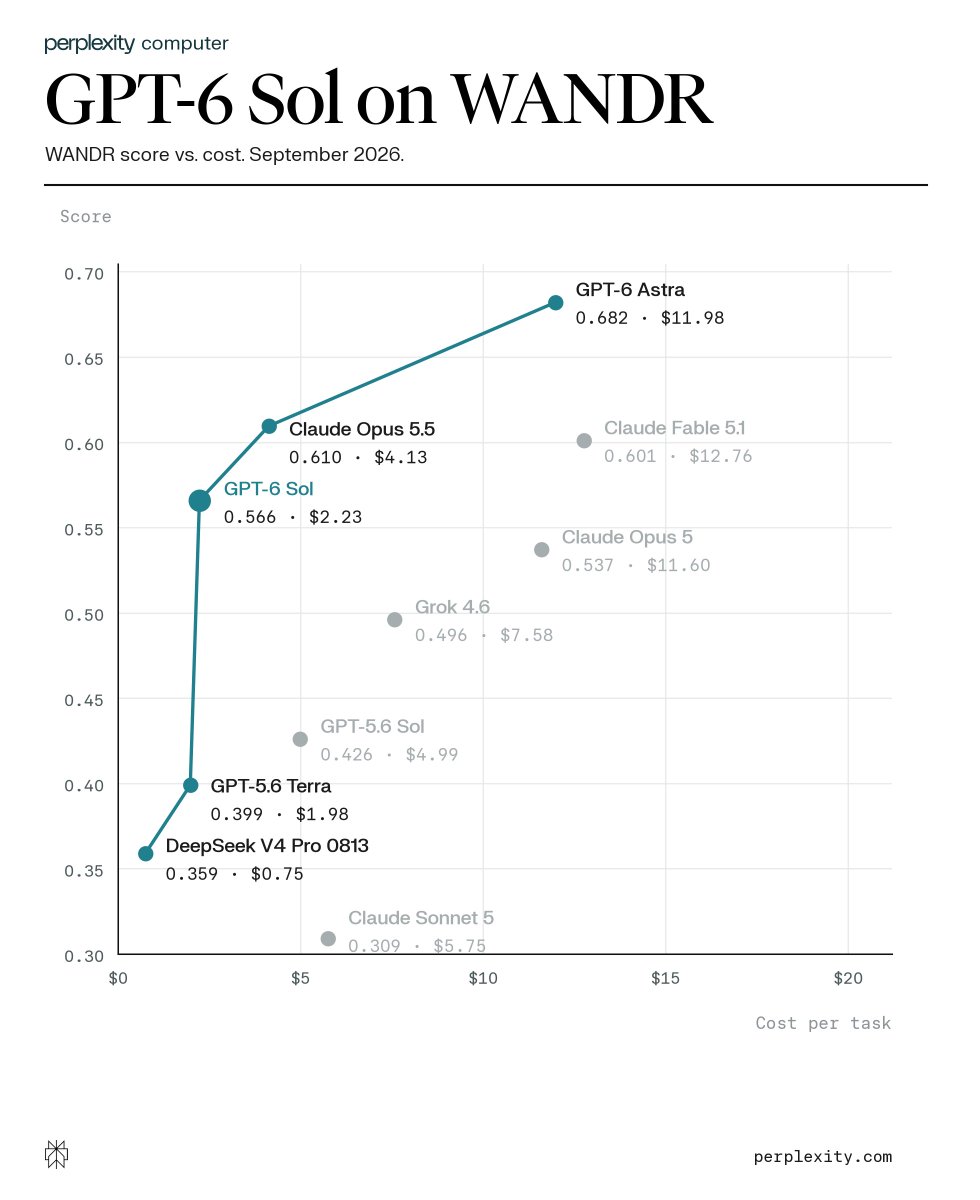
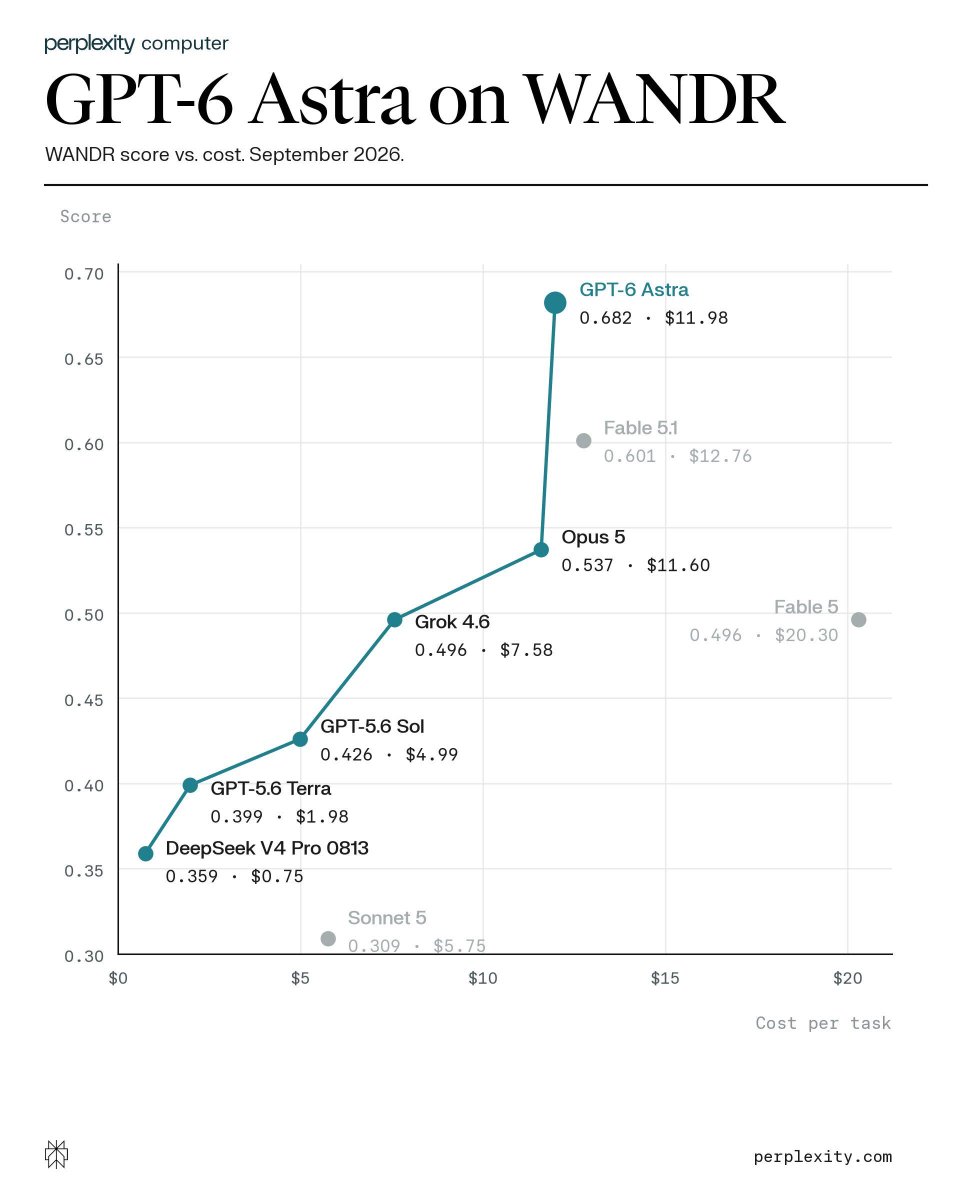
We evaluated GPT-6 Astra on WANDR. It scored 0.682 at $11.98 per task, the highest score of any model we tested. GPT-6-Astra scored 13.5% higher than Fable 5.1 at 6.1% lower cost, and 27.0% higher than Opus 5 at 3.3% higher cost.

Context
Perplexity reports that GPT-6 Astra, OpenAI's new computer-use and coding model, scored 0.682 on WANDR, Perplexity's own , at $11.98 per task, the highest score of any model it has tested there. That is 13.5% higher than Claude Fable 5.1 at 6.1% lower cost, and 27.0% higher than Claude Opus 5 at 3.3% higher cost, by Perplexity's own numbers.
Perplexity runs and publishes WANDR itself, so the ranking reflects its own methodology and task set rather than an independently audited comparison.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- model routing — Sending each request to a model chosen by the difficulty of the task, rather than using one model for everything.
Checking sign-in…
Loading comments…