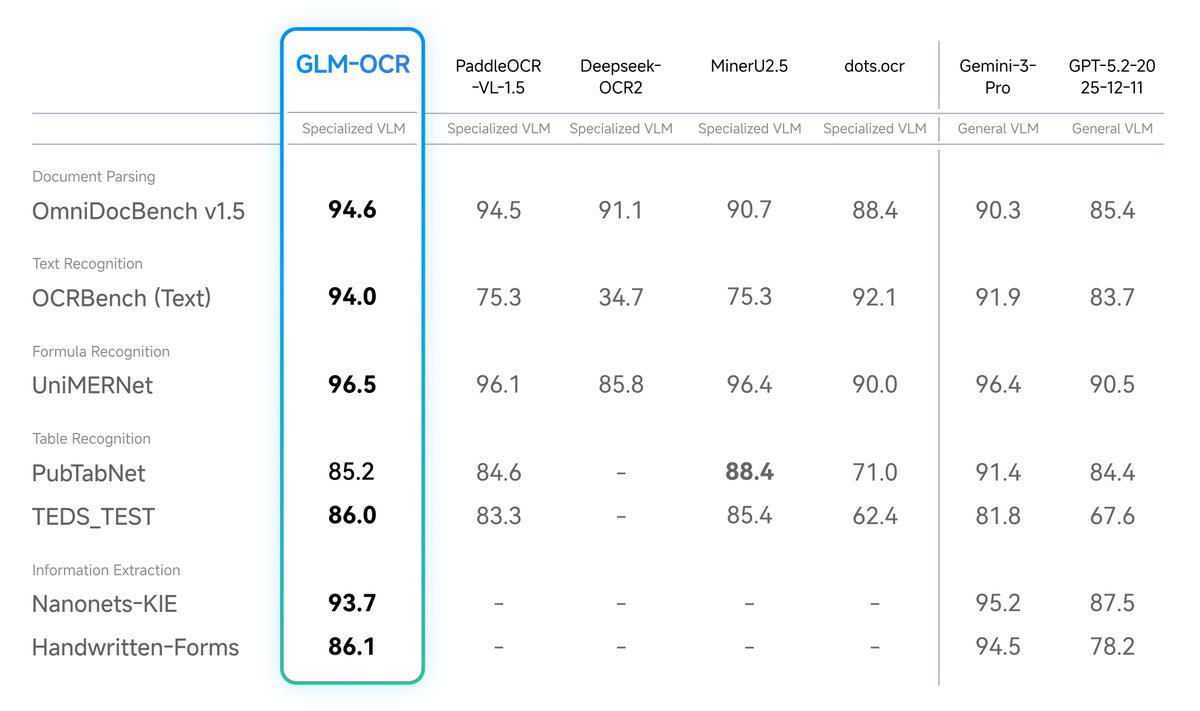
GLM-OCR technical report: multi-token prediction for document parsing
Source
arxiv.org
Author
Z.ai
Date
Context
Z.ai's GLM-OCR turns document images into structured text by first splitting each page into regions. A layout detector separates regions such as paragraphs, tables and formulas so they can be recognized in parallel. The system then merges their outputs and restores reading order. The technical report describes Markdown and JSON as output formats.
Within recognition, multi-tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → prediction lets the model produce several text units per decoding step. The authors report an average of 5.2 tokens per step and approximately 50% higher throughput. The report also identifies a dependency: incorrect region detection can propagate into recognition errors or misplaced reading order.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
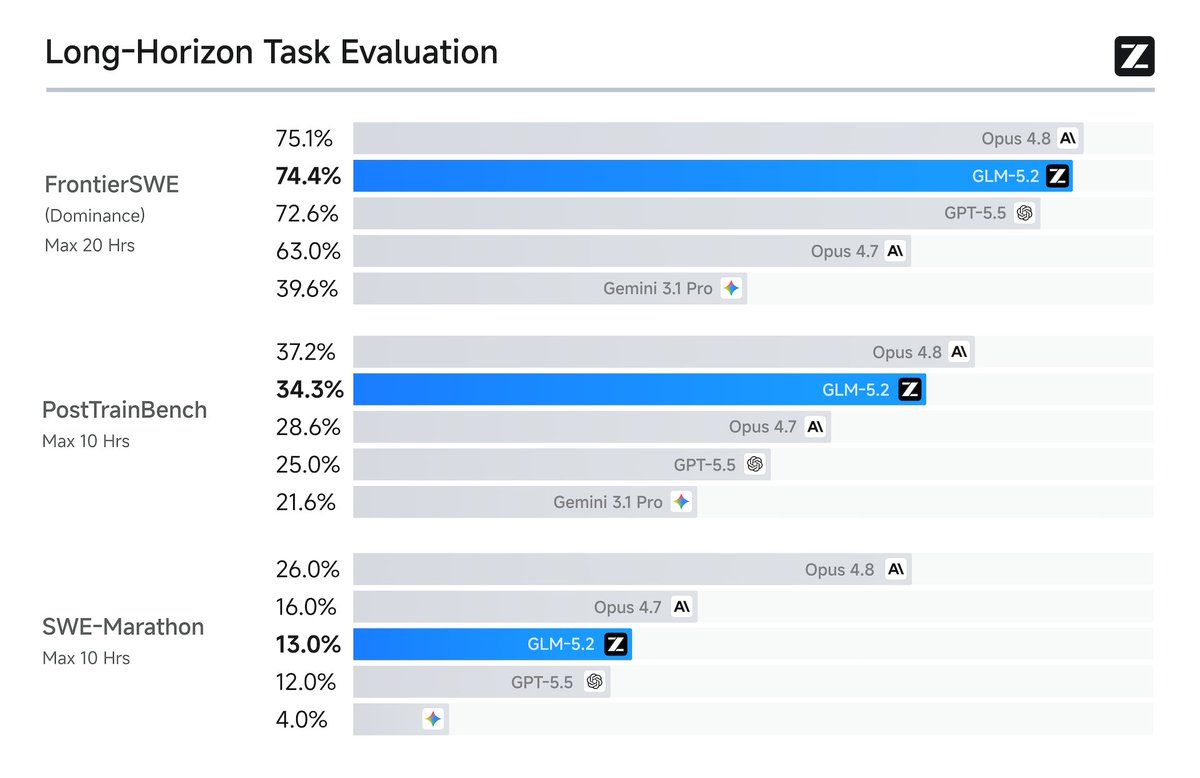
 postWe’re sharing how GLM-5.3 helped build and optimize the inference infrastructure serving GLM-5.3-Flash.
 articleZ.ai details GLM-5.3's leap in exploit analysis and staged release
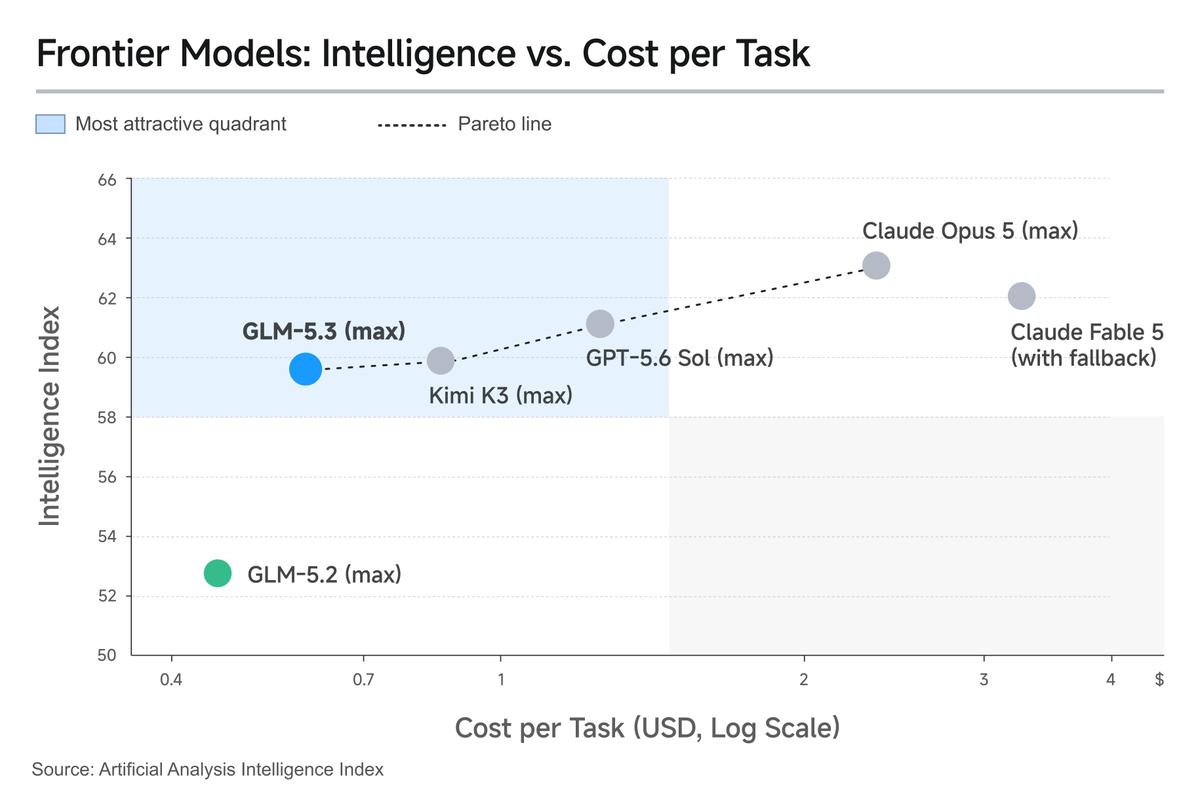 postGLM-5.3 API launches for coding and cybersecurity agentic tasks