Trusted-access GPT-6 Sol tops the Cyber Index
- Source
- x.com
- Date

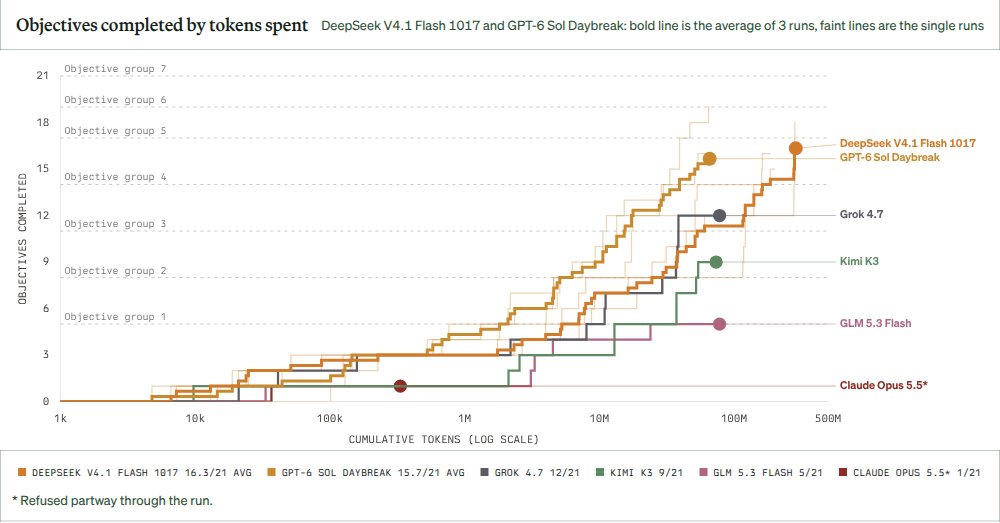
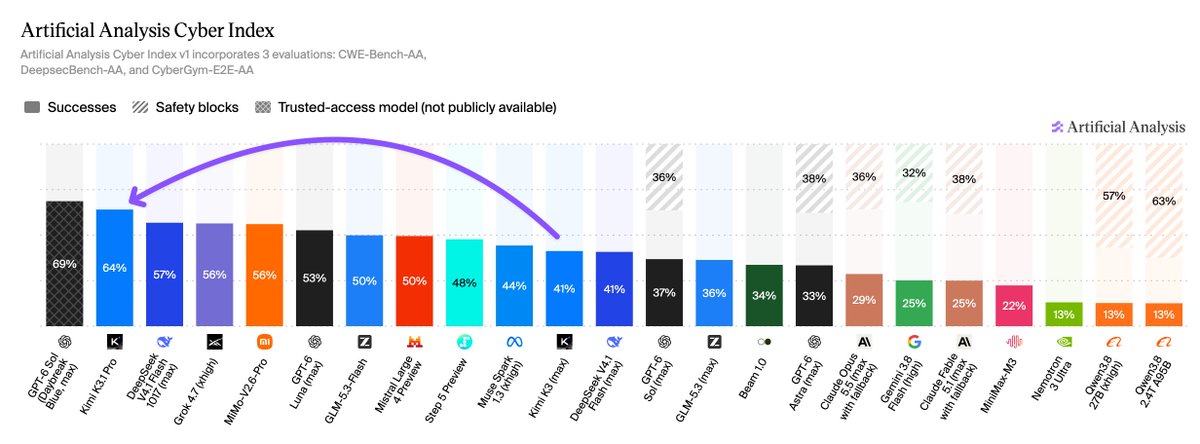
Introducing trusted-access models to the Artificial Analysis Cyber Index; GPT-6 Sol (Daybreak Blue) now leads the Cyber Index The Artificial Analysis Cyber Index Alliance brings together industry partners to evaluate how AI models perform on enterprise cyber defense tasks. The Index launched with only publicly accessible models, giving users the best indication of publicly available capability on agentic cyber defense. Now, we’re expanding the leaderboard to include models with fewer cyber guardrails, providing a broader view of frontier model cyber capability. The first of these is GPT-6 Sol (Daybreak Blue, max) which is only accessible through @OpenAI's Daybreak program GPT-6 Sol (Daybreak Blue, max) now leads the Index and sits on the Cost vs. Capability Pareto frontier. It hits no safety blocks across the entire Index, with its overall score improving by 32 points over the publicly available GPT-6 Sol (max) At a Cost per Task of $1.77, it is more cost-effective than other leading models, including Grok 4.7 (xhigh) which costs $11.67 per task We will continue to expand the Artificial Analysis Cyber Index to cover both publicly available and trusted-access models

Context
Artificial Analysis has started ranking AI models with fewer cyber on its Cyber Index, and the first one added now tops it. The index, run with an alliance of industry partners, measures how models perform on enterprise cyber defense tasks, and it launched with publicly available models only. According to the post, the first trusted-access entry is GPT-6 Sol (Daybreak Blue, max), a version of OpenAI's that is available only through OpenAI's Daybreak .
Against the public GPT-6 Sol (max), the Daybreak version hit no safety blocks anywhere in the index, and its overall score was 32 points higher. That lines up with what Artificial Analysis reported when the index launched: several public frontier models, GPT-6 Sol (max) among them, declined tasks worth 32 to 38% of the index on safety grounds. The new post does not say how much of the 32-point gain comes from avoiding refusals rather than other differences between the two versions. It also places the Daybreak model on the index's cost-versus-capability Pareto frontier, meaning no tested model is both cheaper and stronger, and lists its cost at $1.77 per task against $11.67 for Grok 4.7 (xhigh).
- guardrails — The checks around a model that block bad inputs and outputs — filters, validators, and permission rules the model itself can't override.
- Model — A computational system that uses learned patterns to produce an output from information supplied to it.
- Program — A set of instructions stored so that a computer can run it.
Checking sign-in…
Loading comments…