Perplexity Computer Adopts Claude Opus 5.5 as Standard Tier
- Source
- x.com
- Date

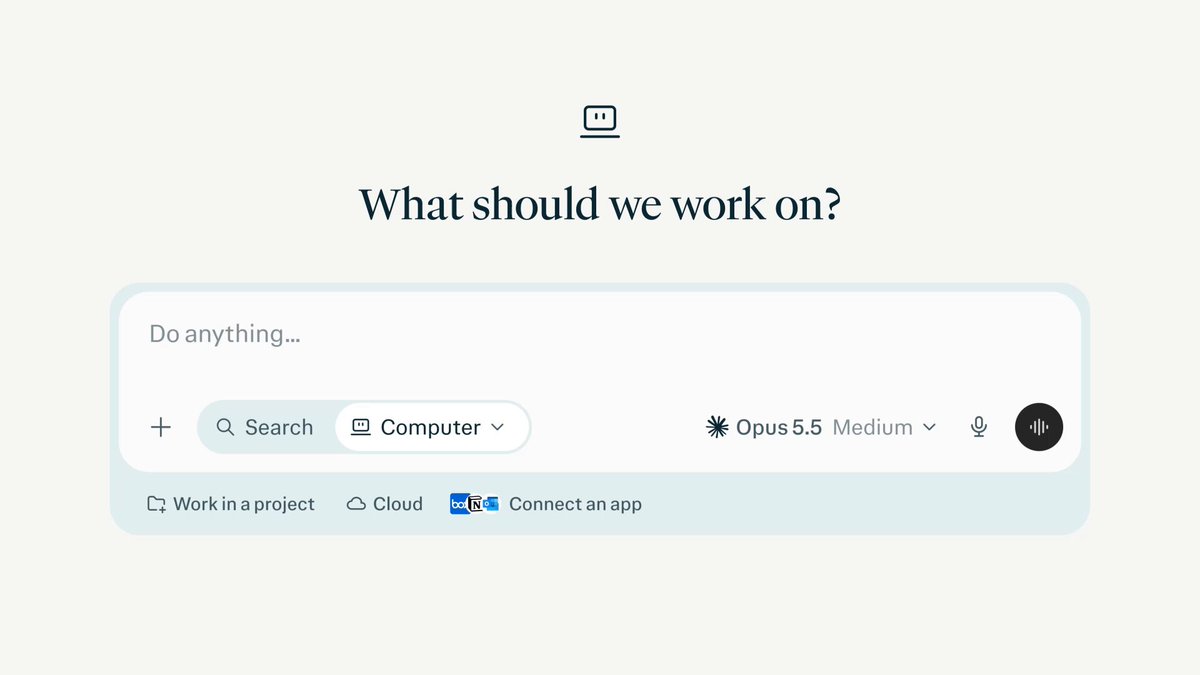
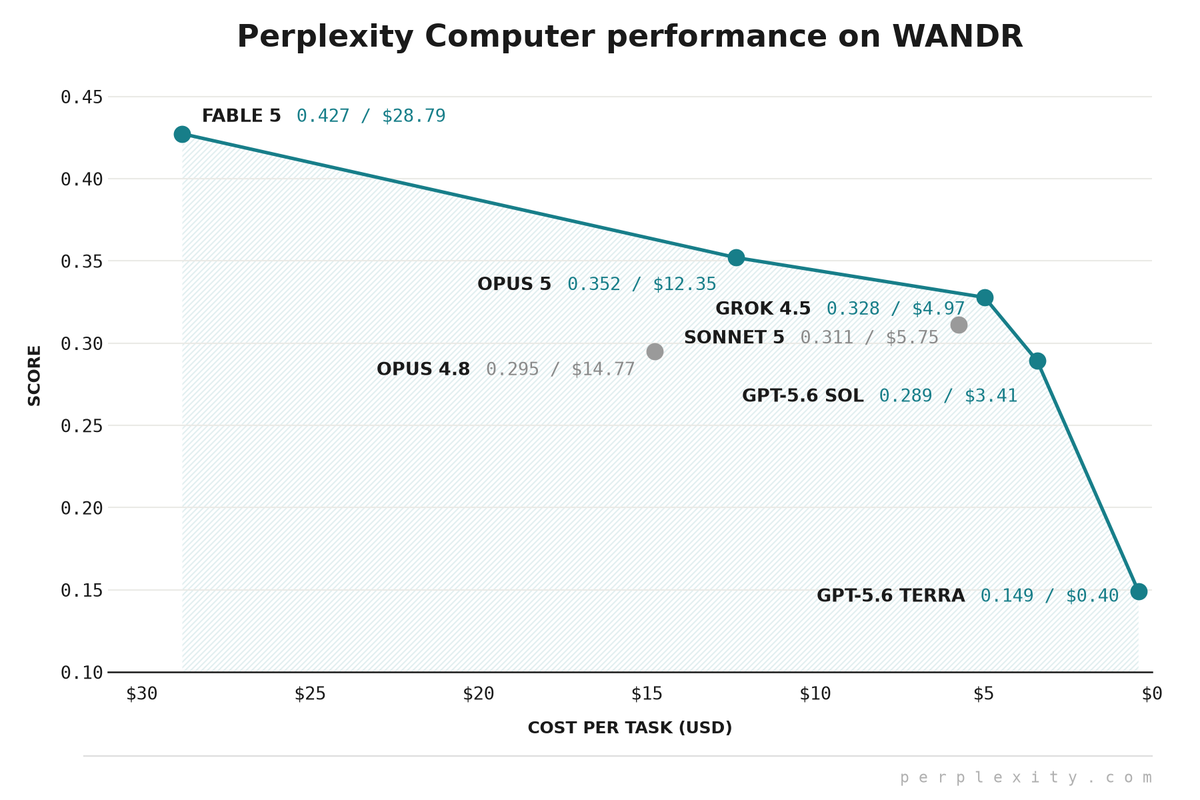
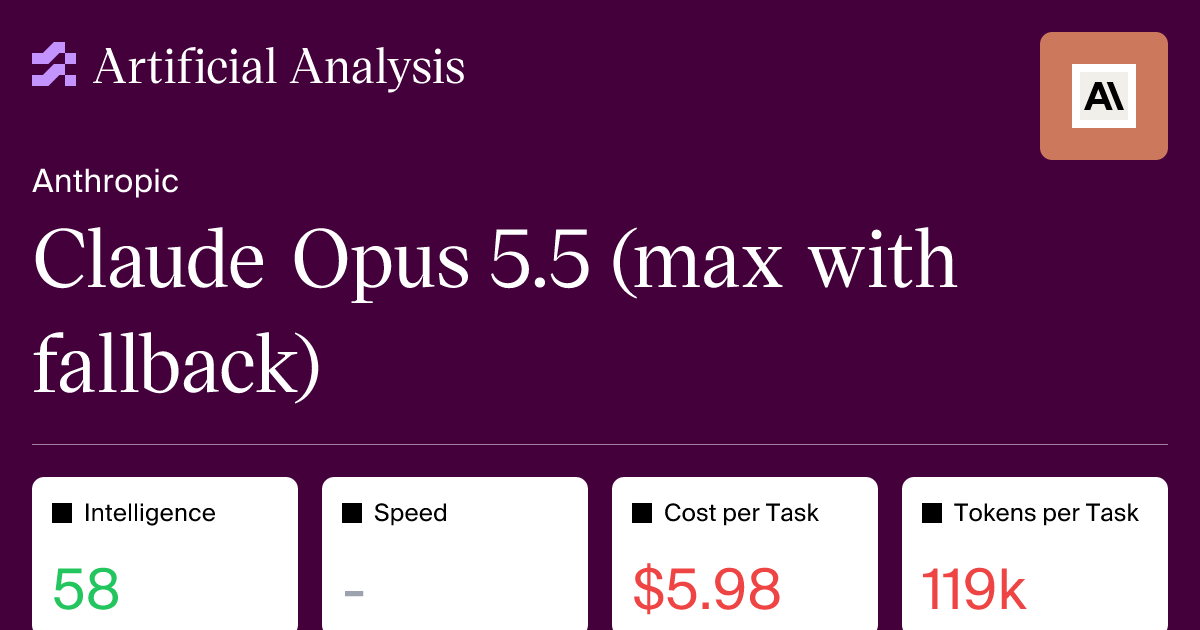
Claude Opus 5.5 is now available as the Standard effort level in Perplexity Computer. On our WANDR benchmark, it scored 0.610 at $4.13 per task, slightly outperforming Claude Fable 5.1 while costing 67.6% less per task.

Context
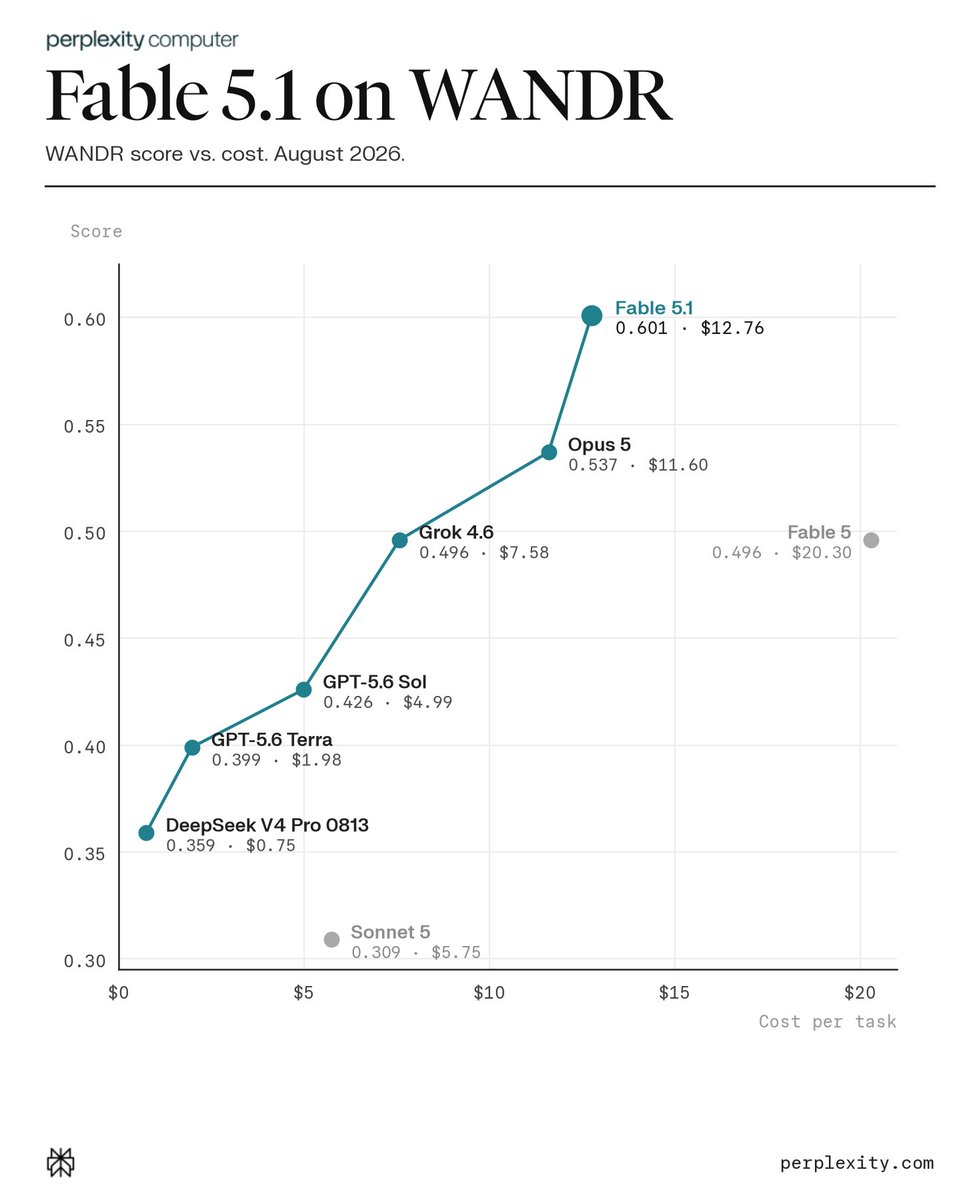
Perplexity has put Anthropic's Claude Opus 5.5 in the Standard effort level of Perplexity Computer, and its own testing shows the model slightly beating Claude Fable 5.1 for about a third of the price. Perplexity says Opus 5.5 scored 0.610 at $4.13 per task on its WANDR , slightly ahead of Claude Fable 5.1 while costing 67.6% less per task. WANDR is Perplexity's open benchmark of 500 data-collection tasks, in which a research must build a large collection and back every item with specific evidence.
Perplexity's earlier posts fill in the comparison. It had reported Fable 5.1 ranking first in its August WANDR evaluation at 0.601 and $12.76 per task, figures consistent with the new 67.6% saving. In early September, Perplexity also said GPT-6 Astra scored 0.682 at $11.98 per task, the highest score of any model it had tested. Opus 5.5 is therefore not the strongest model Perplexity has tested; it is the one that gets close to the leaders for far less money, which fits its role as the Standard level among Computer's effort presets.
All of these numbers come from Perplexity running models inside its own product on its own benchmark, and the post does not describe how the run was set up. They show how the models compare for Perplexity's research-agent work, not how Opus 5.5 performs elsewhere.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
Checking sign-in…
Loading comments…