Perplexity puts Claude Fable 5.1 top of its WANDR agent evaluation
- Source
- x.com
- Date

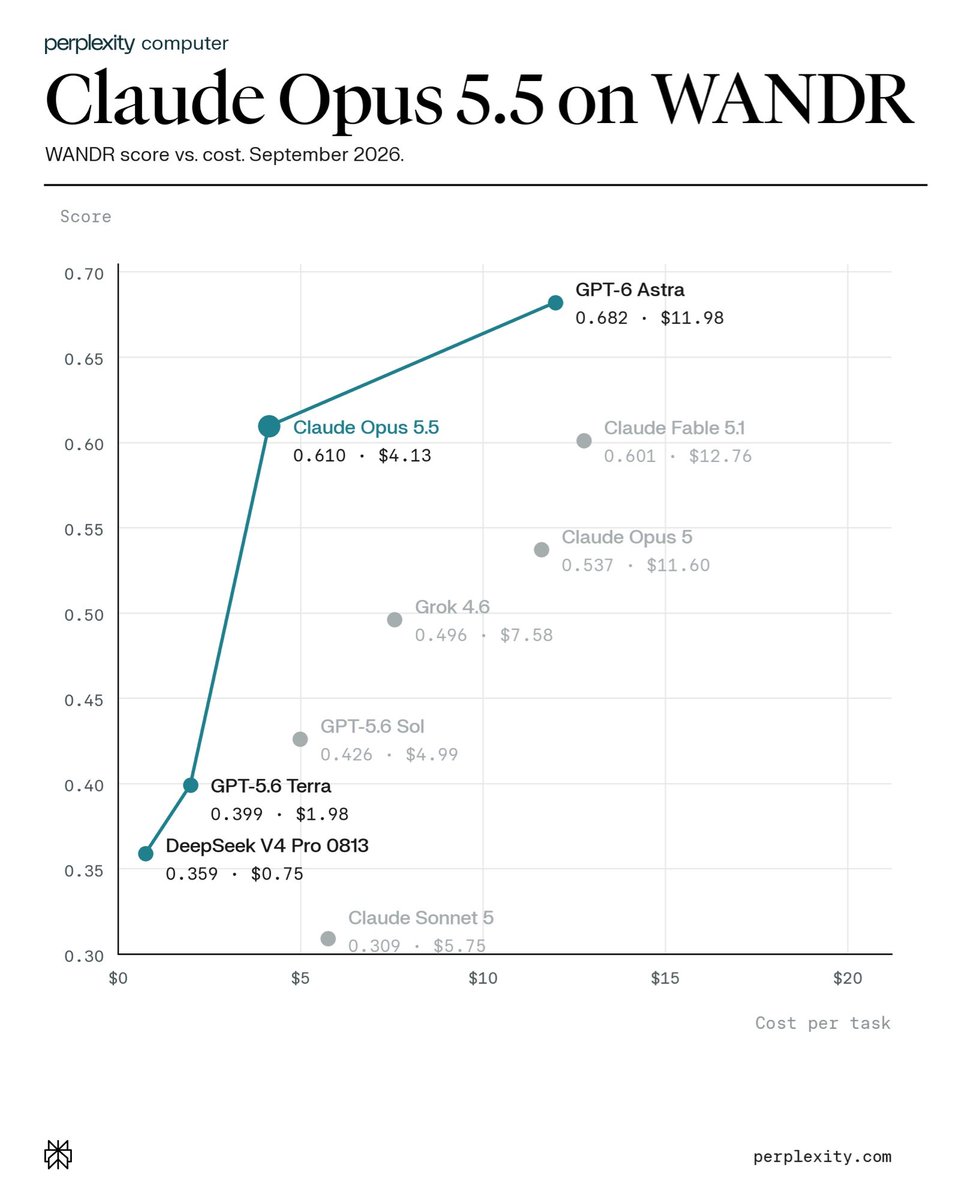
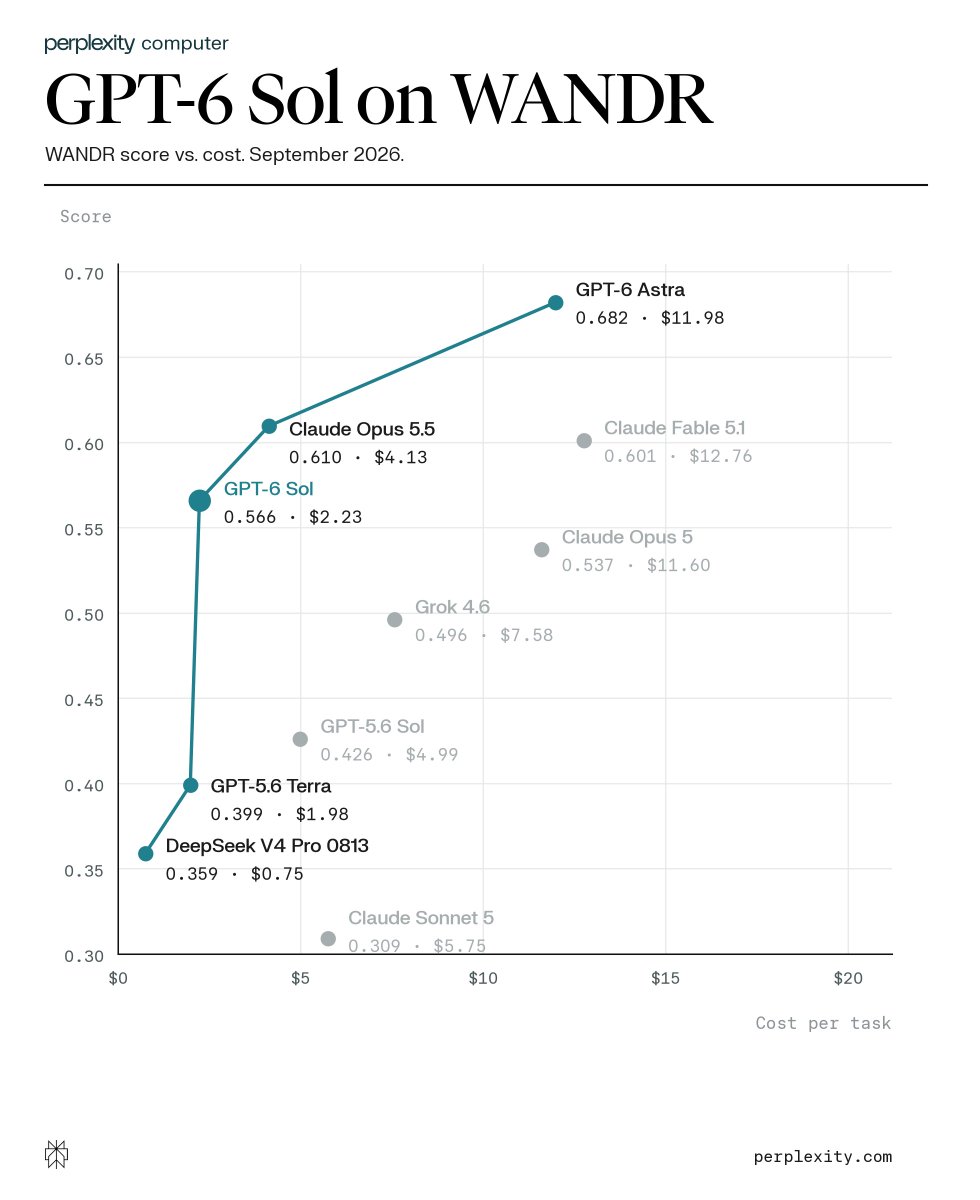
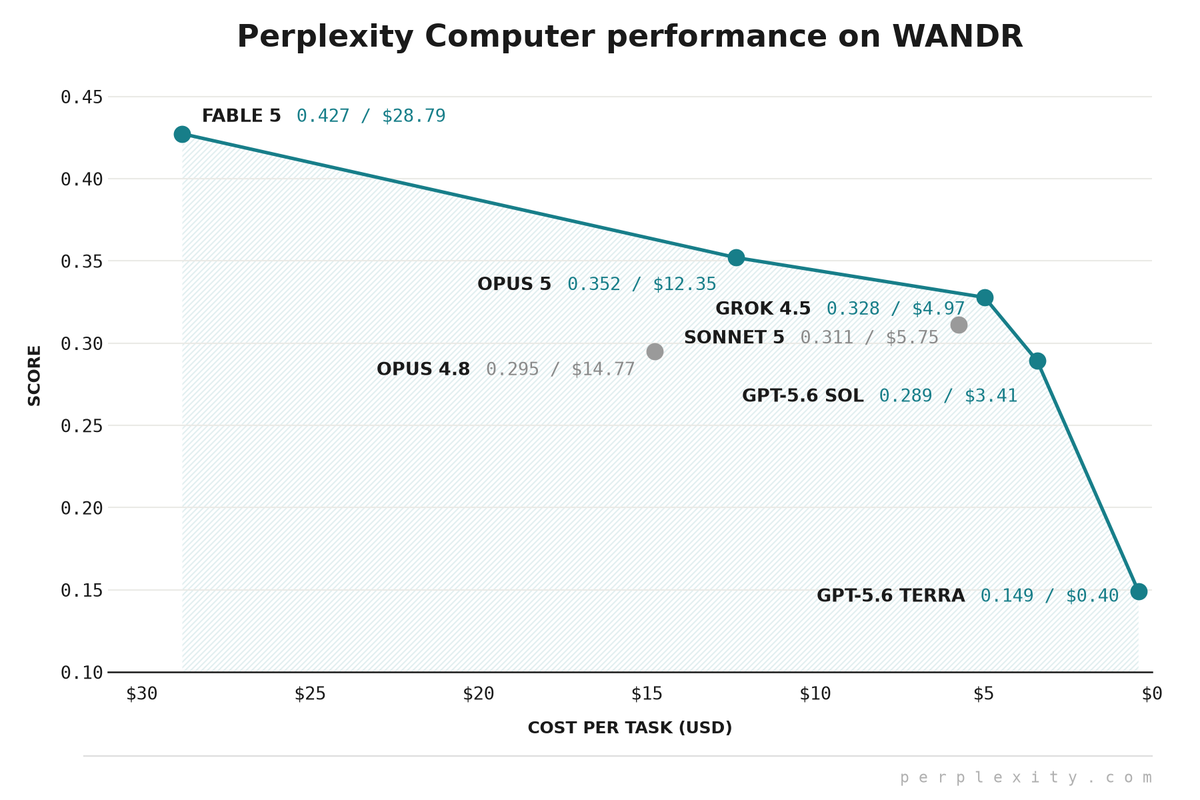
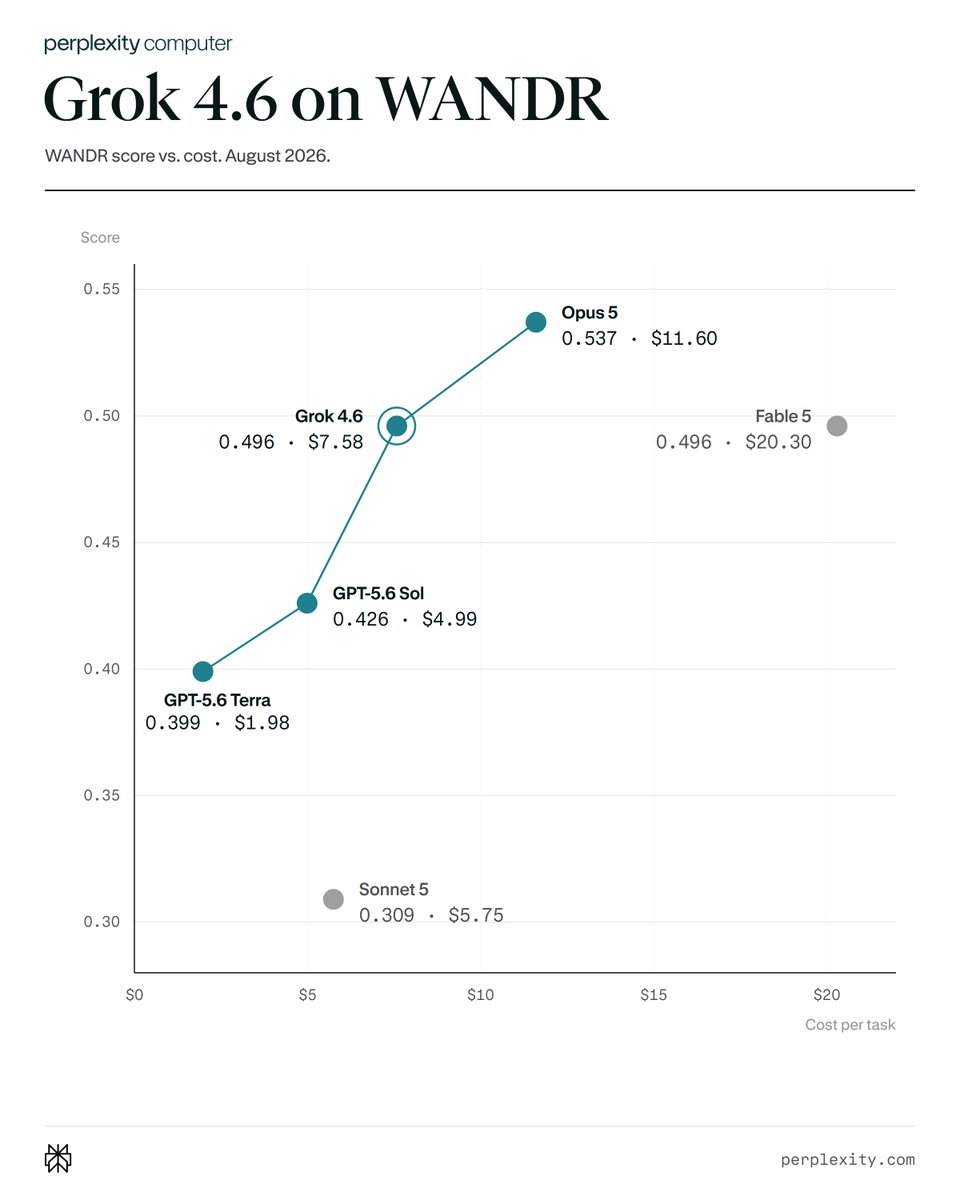
Claude Fable 5.1 is now available in Perplexity Computer for Pro and Max subscribers. It ranked first in our August WANDR evaluation at 0.601 and $12.76 per task, a 21% higher score and 37% lower cost than Fable 5.

Context
Perplexity reported that Anthropic's Claude Fable 5.1 improved both score and cost over Fable 5 in its August WANDR . Its chart shows a score of 0.601 at $12.76 per task, compared with 0.496 at $20.30 for the predecessor. Those figures describe Perplexity's own evaluation, rather than a subscription price or a universal cost per request. Results announcement.
WANDR tests research agents on building collections of qualifying records and supporting each with evidence from the web. That makes the comparison relevant to extensive research jobs, where finding enough examples and verifying each one both matter. Benchmark design and earlier coverage.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…