GLM-5 lands at 744B parameters with open weights and heavier quota costs
- Source
- x.com
- Date

Introducing GLM-5: From Vibe Coding to Agentic Engineering GLM-5 is built for complex systems engineering and long-horizon agentic tasks. Compared to GLM-4.5, it scales from 355B params (32B active) to 744B (40B active), with pre-training data growing from 23T to 28.5T tokens. Try it now: https://t.co/WCqWT0raFJ Weights: https://t.co/DteNDHjSEh Tech Blog: https://t.co/Wxn5ARTJxH OpenRouter (Previously Pony Alpha): https://t.co/7Khf64Lxg6 Rolling out from Coding Plan Max users:
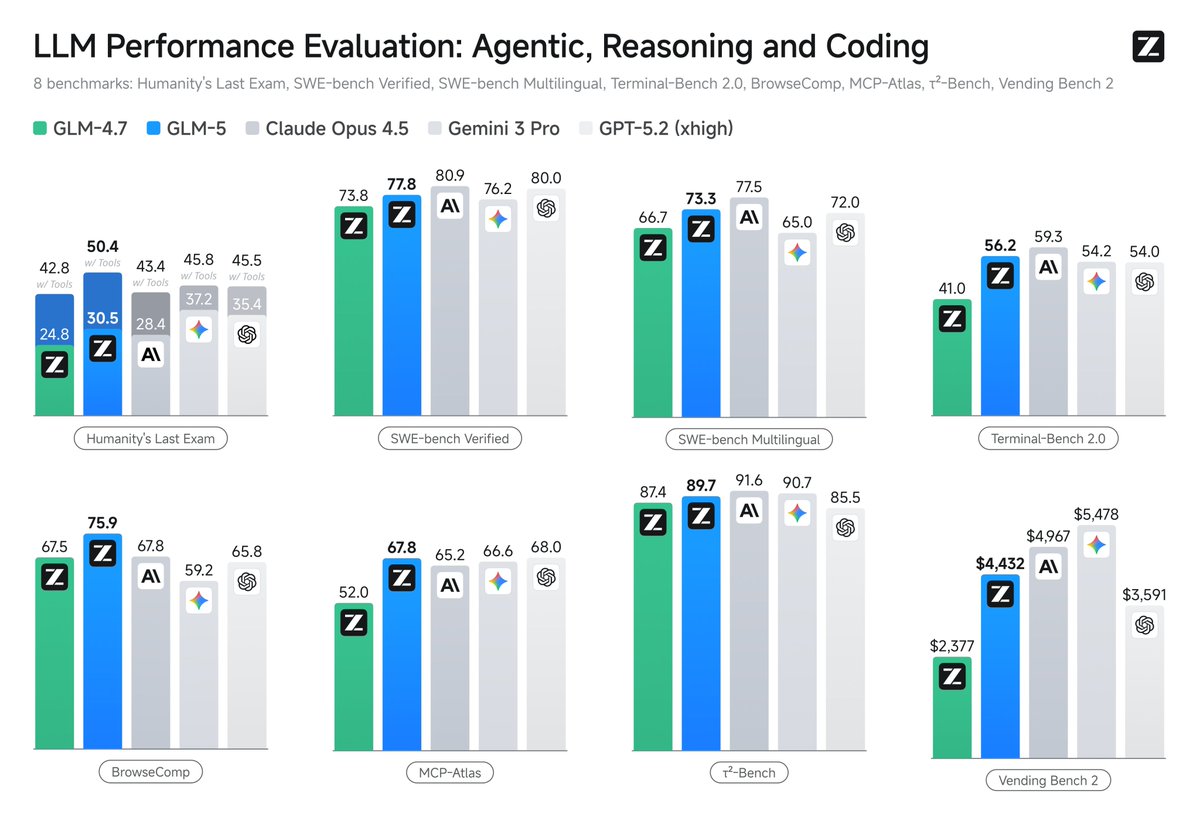
On our internal evaluation suite CC-Bench-V2, GLM-5 significantly outperforms GLM-4.7 across frontend, backend, and long-horizon tasks, narrowing the gap with Claude Opus 4.5.

On Vending Bench 2, GLM-5 ranks #1 among open-source models, finishing with a final account balance of $4,432. It approaches Claude Opus 4.5, demonstrating strong long-term planning and resource management.

For GLM Coding Plan subscribers: Due to limited compute capacity, we’re rolling out GLM-5 to Coding Plan users gradually. - Max plan users: You can enable GLM-5 now by updating the model name to "GLM-5" (e.g. in ~/.claude/settings.json for Claude Code). - Other plan tiers: Support will be added progressively as the rollout expands. - Quota note: Requests to GLM-5 consume more plan quota than GLM-4.7.
Context
Z.ai released GLM-5 in February 2026, scaling up from GLM-4.5's 355 billion total parameters (32 billion active) to 744 billion total (40 billion active), with data growing from 23 trillion to 28.5 trillion , according to the company's launch thread. On its internal CC-Bench-V2 suite, Z.ai reported GLM-5 significantly outperforming GLM-4.7 on frontend, backend and long-horizon coding tasks, narrowing the gap to Claude Opus 4.5. On Vending Bench 2, a test of an running a simulated vending business over many turns, Z.ai said GLM-5 ranked first among open-source models with a final account balance of $4,432, again approaching Claude Opus 4.5's result.
GLM-5's weights were released openly, and Z.ai rolled the model out first to GLM Coding Plan Max subscribers, warning that GLM-5 requests would consume more plan quota than GLM-4.7. Z.ai has released further versions since, including GLM-5.1, GLM-5.2, and GLM-5.3, so the standing described here reflects February 2026, not the lab's current lineup.
- pretraining — The first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
 postWe’re sharing how GLM-5.3 helped build and optimize the inference infrastructure serving GLM-5.3-Flash.
- postGLM-5 lands in Zhipu's Coding Plan Pro as pricing shifts
 articleZ.ai details GLM-5.3's leap in exploit analysis and staged release
 postGLM-5.3 API launches for coding and cybersecurity agentic tasks
Checking sign-in…
Loading comments…