Four new models reshape the Intelligence Index cost frontier
- Source
- x.com
- Date

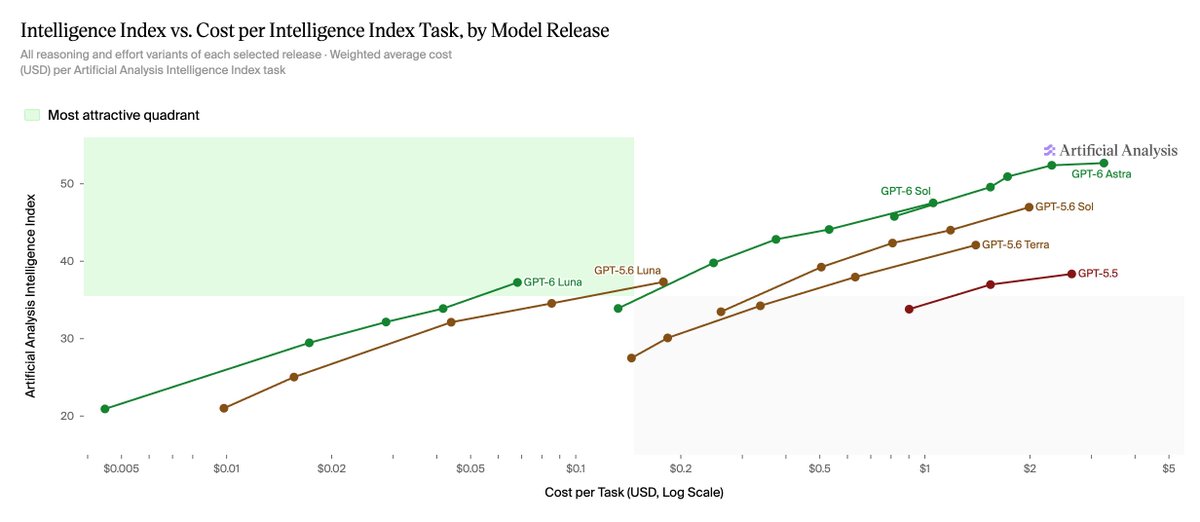
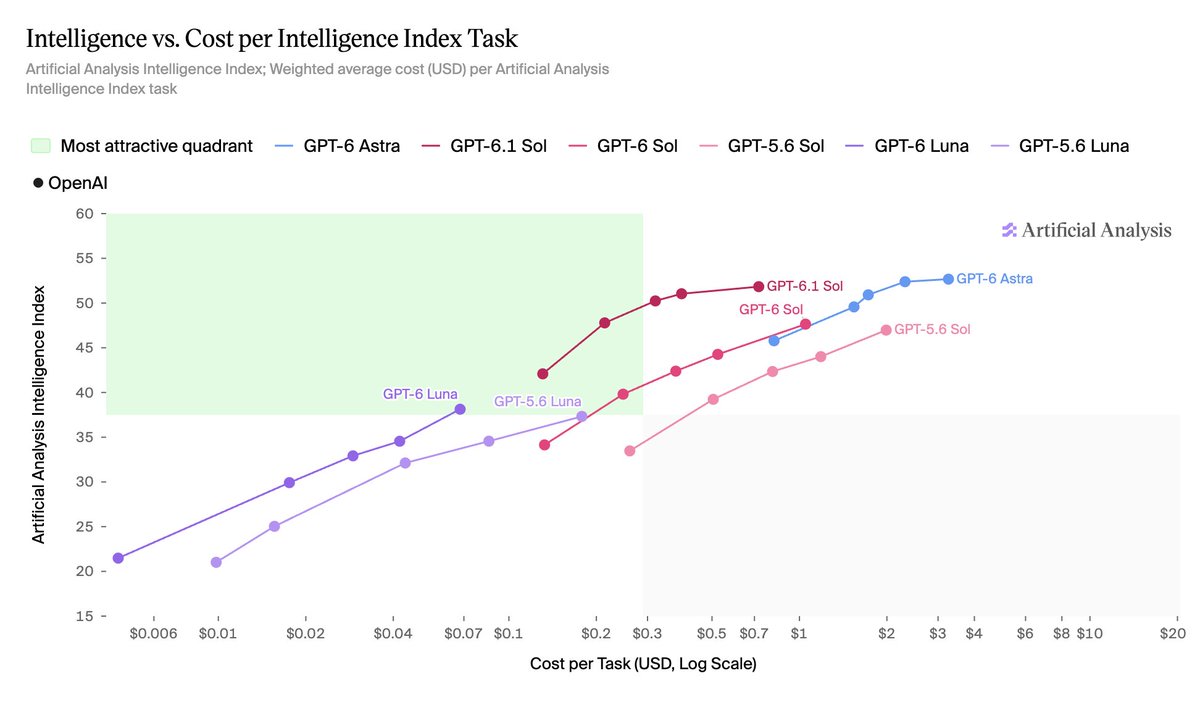
The Intelligence Index vs Cost per Task Pareto frontier shifted this week with the releases of MiMo-V2.6-Pro, Claude Opus 5.5, GPT-6 Luna, and GPT-6 Sol Together they have established eleven new points on the Pareto frontier (driven by different reasoning efforts): five from GPT-6 Luna, one each from MiMo-V2.6-Pro and GPT-6 Sol, and four from Claude Opus 5.5. GPT-6 Luna (max) scores 37 at $0.068 per task, MiMo-V2.6-Pro scores 46 at $0.13, GPT-6 Sol (max) scores 48 at $1.06, and Claude Opus 5.5 (max with fallback) is the new highest-scoring model at 58 at $5.98.

Context
Artificial Analysis plots each model's Intelligence Index score against what it costs to run one index task, and the Pareto frontier is the edge of that chart: the set of options where nothing else scores higher for the same or lower cost. A model on the frontier is the best choice available at its price. In one week, four releases added eleven new points to that frontier: five from GPT-6 Luna, one each from MiMo-V2.6-Pro and GPT-6 Sol, and four from Claude Opus 5.5. A single model can add several points because each reasoning effort setting, which trades extra thinking for extra cost, is plotted separately.
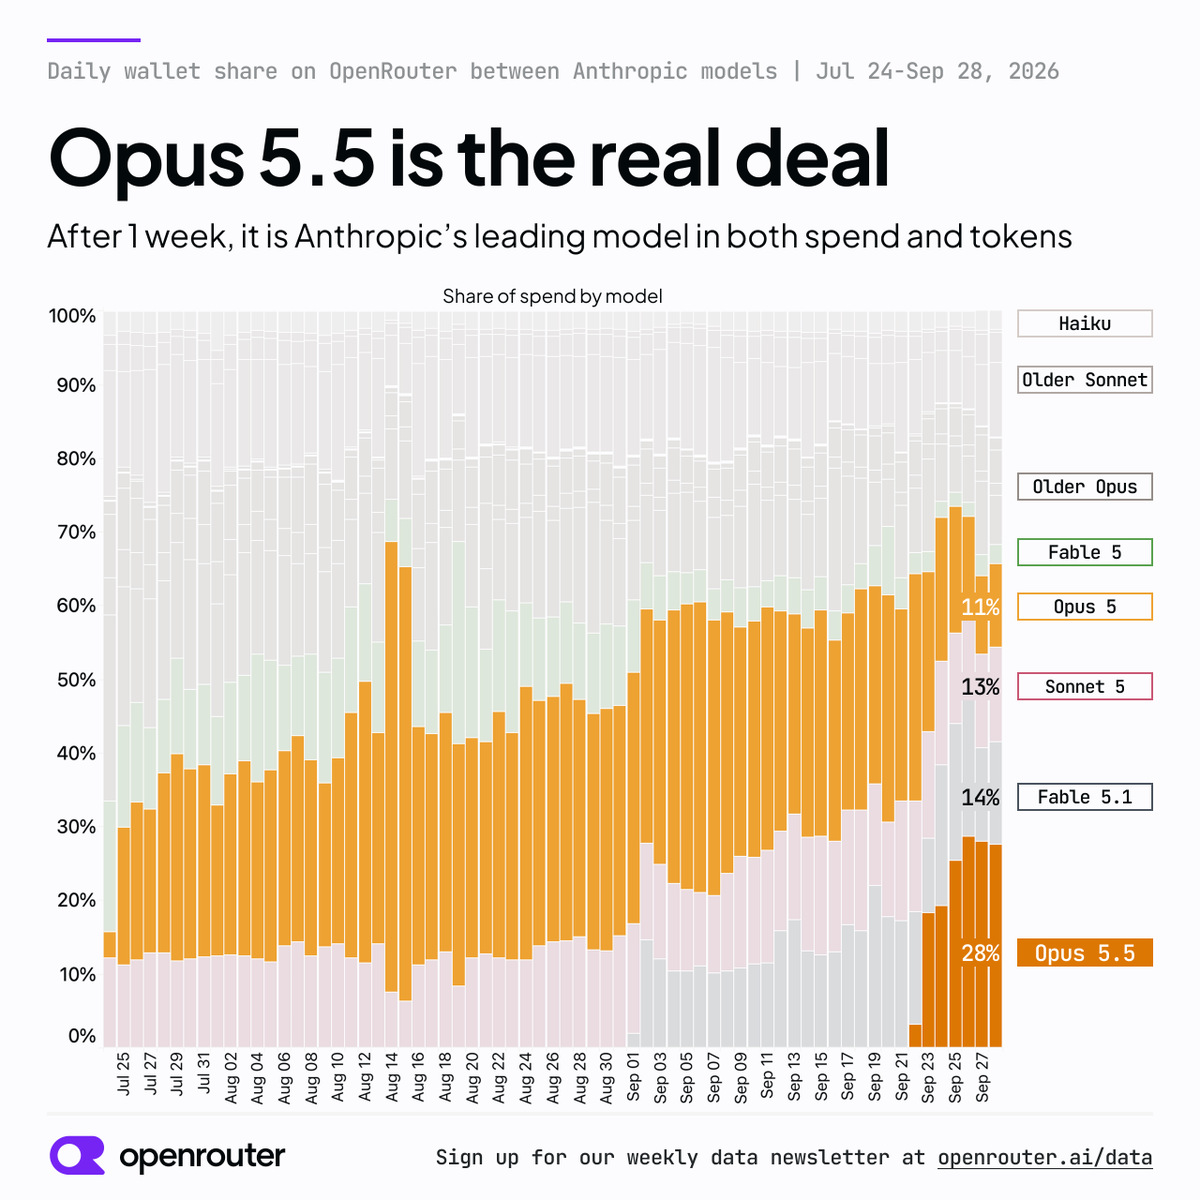
The new points stretch from very cheap to expensive. OpenAI's GPT-6 Luna on its max setting scores 37 at $0.068 per task. MiMo-V2.6-Pro, which Xiaomi released as an open-weights model, scores 46 at $0.13. GPT-6 Sol on max scores 48 at $1.06, and Anthropic's Claude Opus 5.5, in a configuration labelled max with fallback, is the new highest-scoring model at 58 for $5.98 per task. The practical result is that the best available score now depends heavily on budget: MiMo-V2.6-Pro comes within two points of GPT-6 Sol at a small fraction of its cost, while the top score costs several dollars a task.
Checking sign-in…
Loading comments…