Intel
Page 68
HxAgent: Iterative Agent Planning for End-to-End Web Application Testing
An iterative LLM planning agent for web testing that re-reads page state after every action and draws on both recent actions and past correct and incorrect sequences, reported ahead of WALT on three benchmarks.
Why it mattersThe proactive re-assessment loop and the split between short-term and long-term memory are directly transferable to anyone building a browser-driving agent.
The Unwritten Benchmark: A New Challenge for Multimodal Machine Learning in Abstract Perceptual Reasoning
A benchmark asking models to infer written words from pen-scratch audio and hand-movement video with no visible ink, where humans clear 80 percent accuracy and leading multimodal models stay under 10.
Why it mattersIt marks a class of inference from dynamic multimodal evidence where current frontier models fail almost completely, which is useful when scoping what a multimodal agent can be trusted to do.
Evaluating Agentic Code Repair Capabilities in Distributed Systems
A code-repair benchmark of 60 real distributed-system bugs that runs each case with and without bounded debugging context, isolating how much logs, traces and runtime state change agent success.
Why it mattersCoding agents cluster in the high 70s on single-process SWE-bench, and this shows what happens when root causes span processes and what feeding in logs and traces is worth.
The Recall Trap: A Recall-Maximizing Retriever Configuration Reduces Issue Resolution in Fixed-Budget Code Context
A controlled study on SWE-bench Verified showing that the higher-recall retriever setting lowers single-shot issue resolution under a fixed context budget.
Why it mattersRetrieval for code agents is routinely tuned against recall@k, and this is direct evidence that optimizing that metric can cost you resolved issues when the context window is fixed.
Kozuchi Agent: A Language-Agnostic Open-Weight Agent for Software Repair
An open-weight software repair agent with explicit phases, persistent state and deterministic tools that resolves 374 of 500 SWE-bench Verified instances on the official evaluator using a locally hosted 27B model.
Why it mattersIt is evidence that a locally hosted open-weight model plus disciplined agent scaffolding reaches frontier-adjacent repair rates, which changes the build-versus-buy calculation for teams that cannot send code to a hosted API.

Anthropic reports Claude Code CLI now uses half the CPU at p99 after moving Bun's garbage collection off a fixed timer to run only when the process is idle.
Why it mattersAnyone running Claude Code in CI or on constrained machines gets the win by updating, and the timer-versus-idle GC diagnosis generalizes to other Bun-hosted agent runtimes.
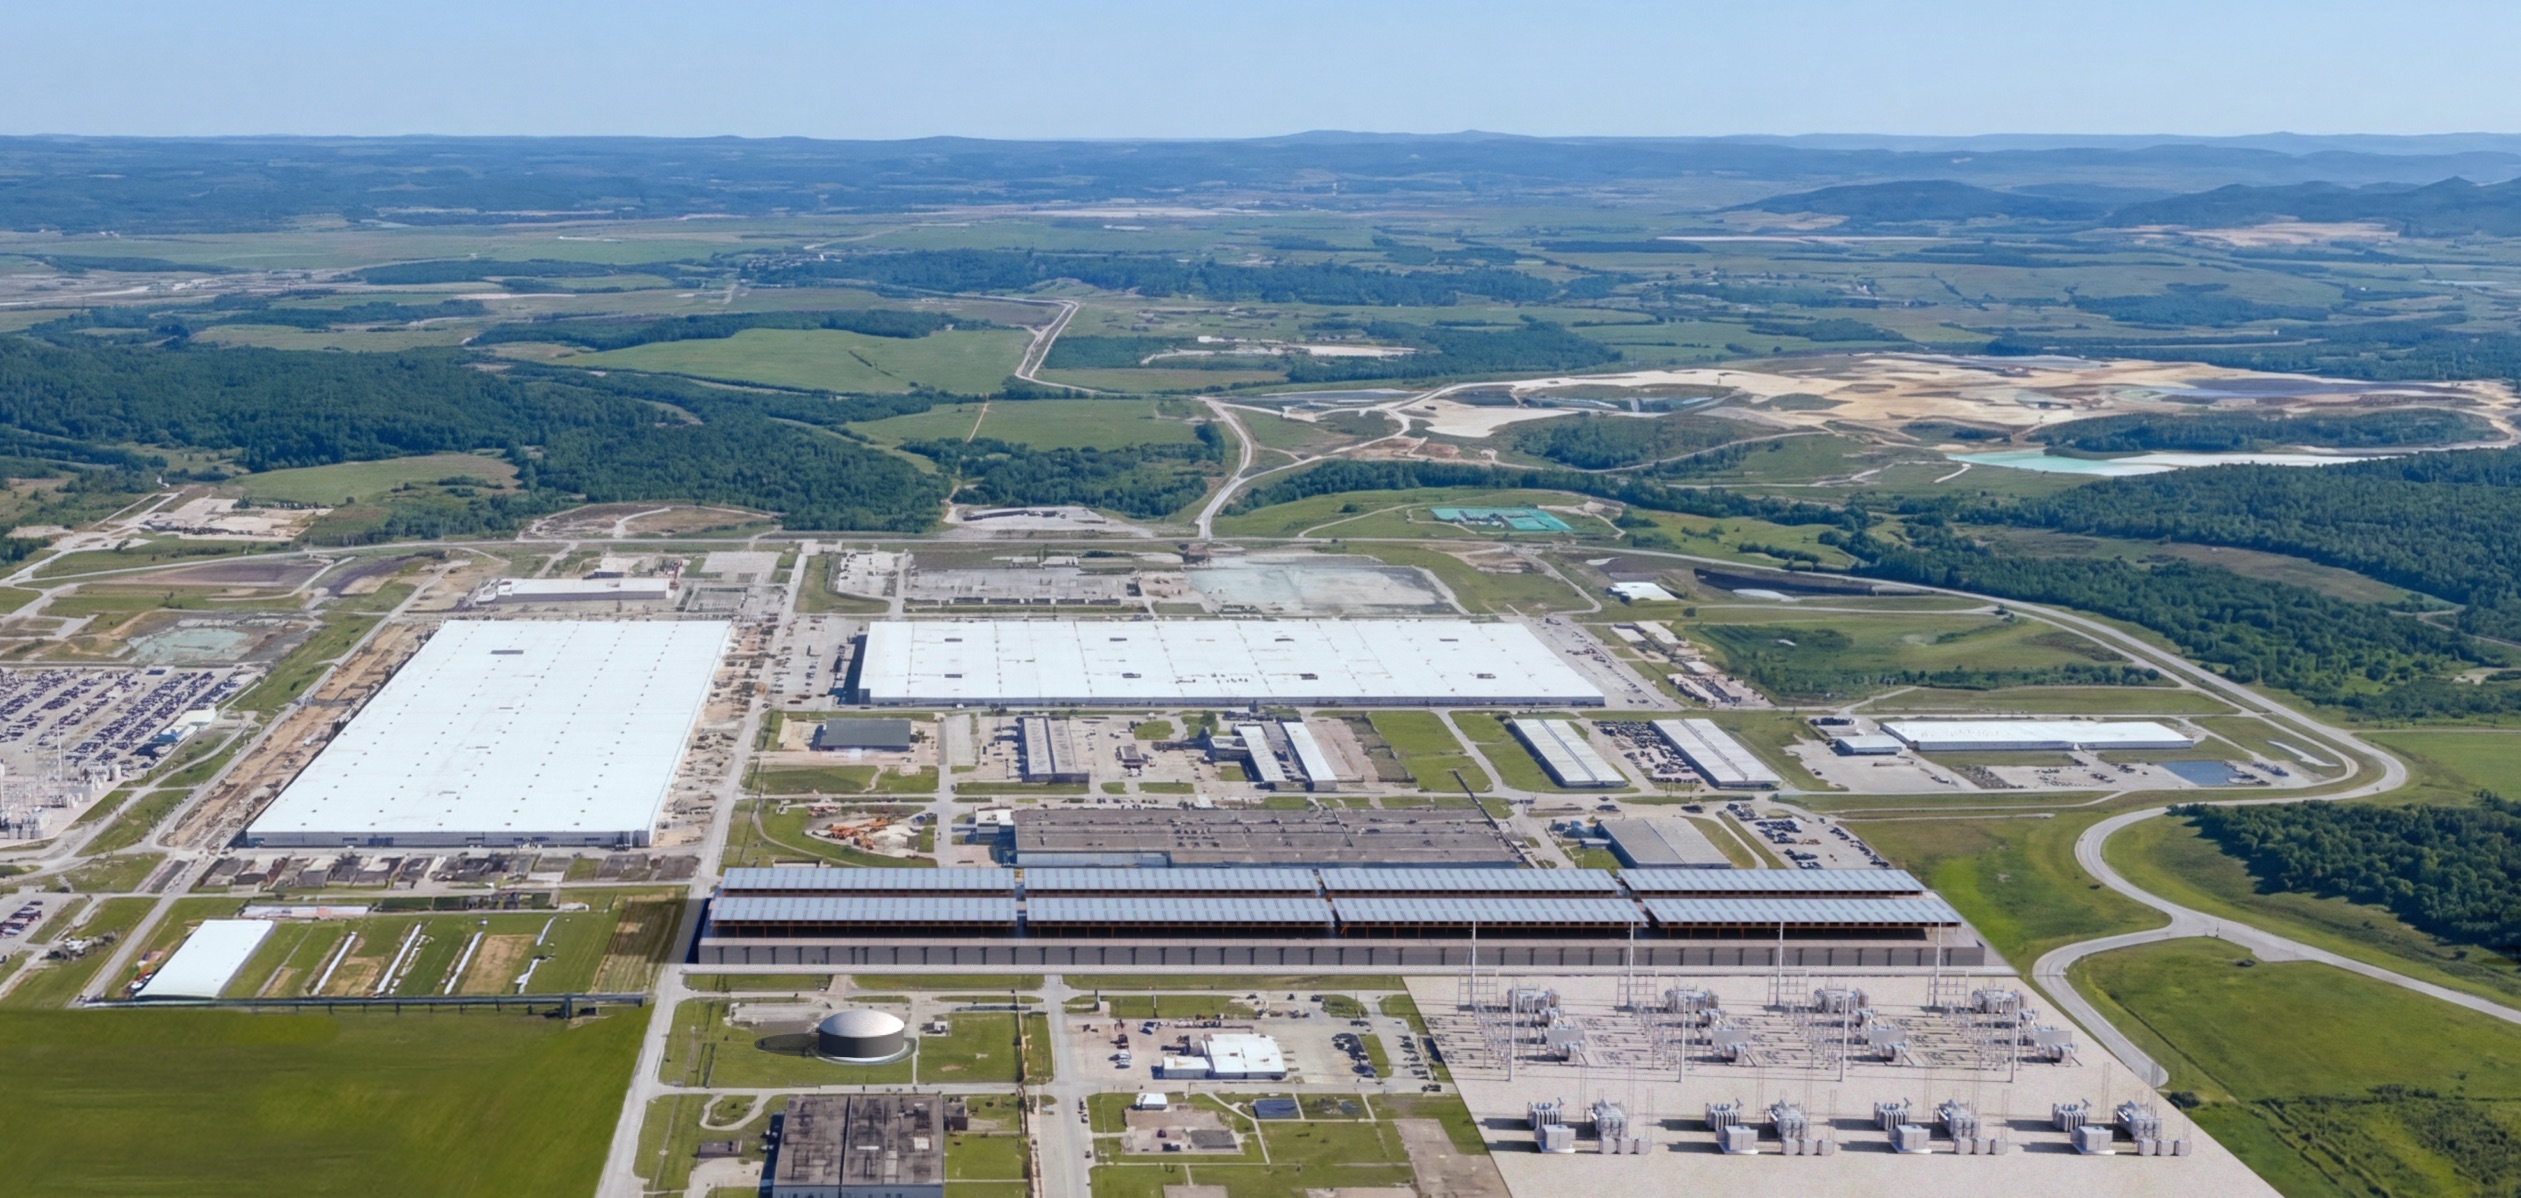
8/17: Nvidia + OpenAI + SB Energy = PORTS-Pike
Search Api
Artificial Analysis launches the Search Index comparing search API providers inside the Stirrup harness with GPT-5.6 Luna, scored on DeepSearchQA, BrowseComp and AA-Omniscience against a no-search baseline.
Why it mattersHolding the agent and model constant, it measures how much each search API lifts answer quality, cost and speed, helping you pick a search provider for research agents.
GLM 5.3 now available on AI Gateway
GLM 5.3 lands on Vercel's AI Gateway with better multi-step agent and software engineering results than GLM 5.2 at fewer output tokens, a 1M token context window, 128K max output.
Why it mattersA new open-weights-class model reachable through an existing gateway, with published effort levels and a documented path into Claude Code, Codex and other agents, is directly actionable.
Cline is now available in the AI SDK harness layer
Vercel adds an official Cline adapter to the AI SDK harness layer, built with the Cline team.
Why it mattersSwapping coding-agent runtimes behind one interface is the point of the harness layer, and each added adapter widens what a team can switch to without rewriting application code.
Why Ai Agents Need A Cloud Browser
The browser, not the model, is usually where agent automation breaks.
Why it mattersNames the specific points where an agent's browser layer outgrows a laptop Chrome, and what changes at the CDP boundary when it moves — the reasoning holds whether you buy or self-host.
Multi-Vector (Late Interaction) Embedding Models with Sentence Transformers
Sentence Transformers v6.0 adds MultiVectorEncoder for ColBERT-style late interaction.
Why it mattersLate interaction preserves token-level matching that a single dense vector averages away.
DeepSeek V4 Pro 0813 vs GPT-5.6 Sol on DeepSWE: Cost, Coding, and Routing
A DeepSWE head-to-head putting DeepSeek V4 Pro 0813 against GPT-5.6 Sol on accuracy, cost per rollout and failure modes.
Why it mattersIt quantifies when a 35x cheaper model is good enough and gives a concrete escalation policy teams can copy into their own routing layer.
Qwen 3.8 27B scores 52 on the Artificial Analysis Intelligence Index
Qwen 3.8 27B lands at 52 on the Artificial Analysis Intelligence Index — the same score as GPT-5.6 Luna (max), one point behind GLM-5.2 and DeepSeek V4 Pro, both vastly larger.
Why it mattersAn open-weight 27B model scoring level with a frontier closed model on a public index changes the arithmetic on running inference locally instead of paying per token.
[AINews] Stripe buys OpenRouter for $7B
Stripe's ~$7B acquisition of OpenRouter closes 90 days after a $1.3B Series B, on roughly $140M annualized revenue and ~70% gross margins, with 250T tokens routed monthly.
Why it mattersThe router 8 million developers call is now Stripe-owned, and the disclosed numbers — 250T tokens a month at roughly 70% gross margin — show where margin in the AI stack is actually landing.

I'm done with terminals
Theo argues the terminal is the wrong surface for coding with agents, and that after a career spent living in it the workflow now needs something else.
Why it mattersEvery coding agent shipping today defaults to a terminal, so a serious argument that it is the wrong surface is worth hearing before teams standardize around it.

SemiAnalysis traces Google's TPU interconnect from 2D torus on TPUv2 to 3D on v4/v5p and Boardfly on v8i, then walks the rumored 6D torus for TPUv9t: 12 ICI links per chip, worst-case hops on 4,096 chips cut from 24 to 12, paid for in far more optics.
Why it mattersCluster topology sets how far a training job scales efficiently. A 6D torus halves worst-case hops and multiplies bisection bandwidth, paid for in optics and OCS capacity — a cost that shapes future TPU availability and pricing.
Claude Code ships /design as a research preview in both CLI and Desktop, bringing Claude Design's artboard workflow to the terminal on top of artifacts — generate UI options, edit the one you want, then have Claude build it. Live on Pro, Max, Team and Enterprise after updating.
Why it mattersDesign exploration now happens inside the coding agent: generate editable artboards for a UI, pick one, and have Claude implement it rather than describing the interface in prose.
Claude Code ships a /design skill in research preview that generates editable artboards in the CLI and Desktop and hands the chosen one back to the agent to implement.
Why it mattersIt puts a design step inside the coding agent loop, so a builder can go from artboard to implementation without leaving the CLI.

Tarun Chitra reads the largest open weight model marketplace as an unbundling of the frontier lab product: open harnesses let a user pick the model and the compute provider separately, and that split changes the incentives around caching and pricing.
Why it mattersIf you route inference through a marketplace, the provider you land on and how honestly it caches determine both your bill and your latency.

How to Kill the Code Review — Ankit Jain, Aviator
Ankit Jain argues code review has already ended, with over 30% of changes merging unreviewed, and proposes replacing the diff with intent and evidence.
Why it mattersTeams are already merging AI-written code with no human reader, and this is a worked proposal for what replaces the diff as the review surface rather than a complaint about it.

Sakana AI's Namazu is routable on OpenRouter. Built on Kimi K2.6, it pairs reasoning with integrated web search and code execution and is specialized for Japanese cultural and business context.
Why it mattersIf you serve Japanese-language workloads, there is now a reasoning model tuned for that context with web search and code execution, reachable through the same OpenRouter API as everything else in your stack.
Same Cluster, 33 Points More Utilization: What Changed Was the Order
A constraint-aware GPU allocator benchmarked against FIFO across seven scenarios on identical hardware.
Why it mattersCluster utilization under contention is decided by allocation order, not hardware: mixing contiguous-block training jobs with elastic inference demand under FIFO leaves large amounts of capacity and priority-weighted output on the table.
Download Hermes Desktop to get started:
Nous ships Hermes Agent as a native desktop app for macOS, Windows and Linux alongside the terminal build.
Why it mattersAn open-source agent you can run locally across desktop and terminal, with per-session sandbox backends spanning Docker, SSH, Singularity and Modal, persistent memory across chat surfaces.

Nous Research adds Bot Mode to Hermes Desktop. Agent profiles become named bots, each carrying its own role, model, memory, skills and avatar, and bots can call any model or hand work to each other.
Why it mattersReusable specialist agents with their own model and memory is the shape multi-agent runtimes are converging on, and this is a shipped reference implementation of it.
.@mondaydotcom built their AI copilot, Sidekick, to do more than answer question
A production account of why a single agent with a growing toolbelt got worse as it got more capable, and what replaced it.
Why it mattersAdding tools to one general-purpose agent degraded tool selection, cost, and debuggability in production; the fix was bounded subagents plus an isolated execution sandbox for agent-generated code.
Security Firewall for Agents — Ryan Dahl, Deno
Ryan Dahl explains why Deno treats its incident response agents as untrusted software and puts an MIT licensed proxy in front of them.
Why it mattersAnyone giving an agent production credentials needs a guard that survives prompt injection, and this is a working design with an open license rather than a policy document.
Developing Nemotron 3.5 Lightning NVFP4 with QAD Using NVIDIA Model Optimizer
NVIDIA walks through quantization-aware distillation for Nemotron 3.5 Lightning.
Why it mattersRecovering agentic and coding benchmark accuracy at four-bit weights changes what a team can realistically self-host on one node instead of renting.
GPT-5.6 Sol is discounted 50 percent on OpenRouter through September 18, applied automatically on the openai/gpt-5.6-sol slug and extending to batch, flex, and priority tiers. Flex reaches $1.25 in and $7.50 out. OpenAI provider only, non-BYOK requests.
Why it mattersHalving the price of a frontier coding model through September 18 changes what is affordable to run in evals and batch jobs, with flex landing at $1.25 in and $7.50 out.
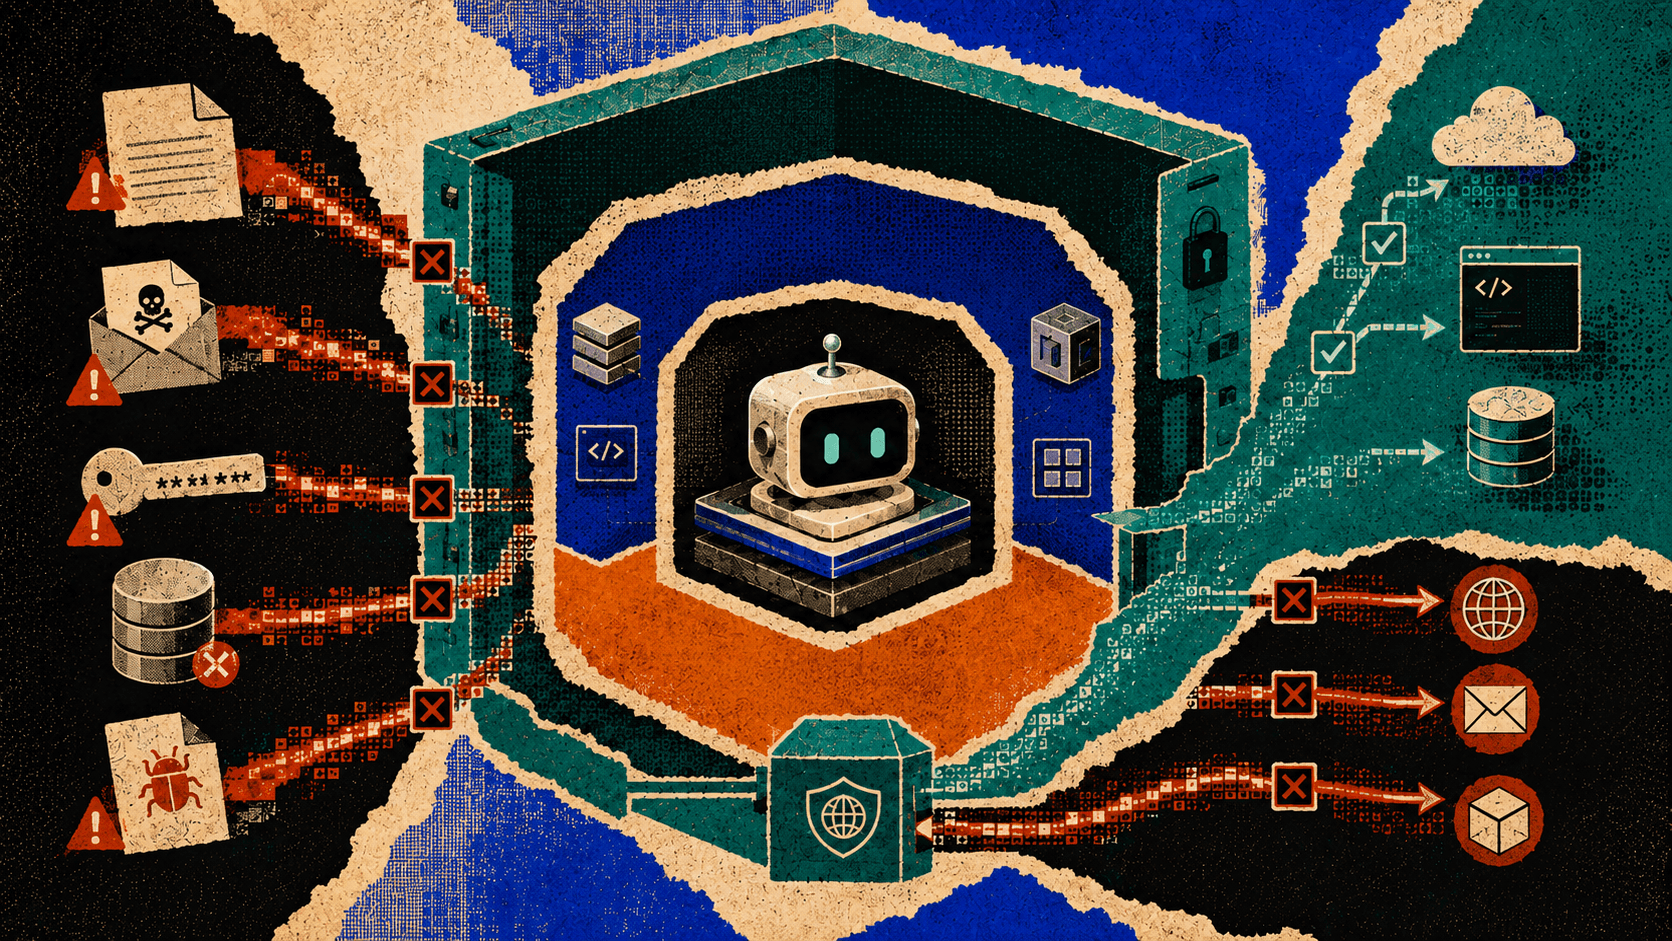
Do not ask whether the agent follows the rule. Ask what stops it when it does no
Semantic guardrails get bypassed, so the question is what physically stops an agent.
Why it mattersSystem prompt rules do not stop an agent that decides deleting the database is correct. Enforcement has to sit in the sandbox, the container lifecycle, and an outbound network proxy that can block and escalate.

A breakdown of agent security as three enforcement layers: sandboxed infrastructure holding credentials outside the agent, a reduced runtime surface with isolated ephemeral containers, and outbound network inspection that routes risky calls to an LLM judge and a human approver.
Why it mattersIt reframes agent safety as a systems problem with enforceable layers rather than prompt discipline, and names a concrete implementation at each layer.
See the top models on the Artificial Analysis Speech leaderboard: Vote for model
Cartesia's Sonic 3.6 takes the top of Artificial Analysis's controlled-voice arena at 1,117 Elo, ahead of Sonic 3.5, ElevenLabs v3 and Alibaba's Qwen-Audio-3.0-TTS-Plus.
Why it mattersCartesia's Sonic 3.6 now leads the controlled-voice arena at 1,117 Elo, ahead of ElevenLabs v3, at $49 per million characters — with the full table showing quality and price diverging sharply across providers.

Artificial Analysis puts Cartesia's Sonic 3.6 at number one on both the Provider Voice and Controlled Voice speech arenas, reporting Elo scores and appearance counts alongside per-character pricing and generation speed against ElevenLabs, Speechify and Alibaba entries.
Why it mattersAnyone shipping a voice agent gets current quality, speed and price for the leading text-to-speech models in one comparison instead of trusting vendor claims.

Aiden Bai released improve-threejs, an installable agent skill built on React Doctor that takes rough Three.js prototypes and rewrites them into faster scenes with the visual bugs cleaned up.
Why it mattersTargeted skills that repair a known class of agent-generated code are a practical answer to prototype-grade output, and this one covers a domain coding agents are visibly weak in.
Run this to install: npx skills add --skill improve-threejs Powered by React Doc
React Doctor scans a codebase deterministically for the patterns agents get wrong.
Why it mattersAgents produce React that passes review by looking plausible; a deterministic scanner installed as a skill catches state and effect misuse, performance traps and duplicated JSX before the code lands.

Cursor has launched Origin, its own code hosting platform, now rolling out in beta and wired directly into the editor. Teams get started by syncing existing repositories over from GitHub.
Why it mattersCursor moving upstream of the repository puts an agent-first vendor in control of review, CI and deploy hooks for teams already living in that editor.
We're rolling out the beta starting today.
Cursor now hosts code.
Why it mattersCursor now hosts repos and pull requests with two-way GitHub sync and agents operating in the same surface, so code hosting and agent execution stop being separate systems — with Vercel previews and Depot/Buildkite CI already wired in.
Your agents can now pay for the APIs they use. We worked with AWS on the AgentCo
LangChain and AWS shipped AgentCore Payments middleware.
Why it mattersMachine-to-machine payment on the 402 path is the first credible answer to agents hitting metered APIs, and pairing it with a spend trace is the governance half teams get asked about.

Context Engineering in 2026 — Louis-François Bouchard, Omar Solano & Samridhi Vaid, Towards AI
Across 11 context presets measured on an open source AI tutor, sending the full history beat every compaction technique on recall, cost and latency at once, because rewriting context invalidates the prompt cache that serves most of the tokens.
Why it mattersCompaction is a default in most agent frameworks, and this gives a cost model and a recall number for leaving the history alone instead.
How canvases make agentic workflows visible, steerable, and cost-efficient
GitHub argues that chat is the wrong container for agent execution and describes canvases.
Why it mattersWhen agents produce changes faster than anyone can review them, chat transcripts stop being a usable record. Canvases give agent work a durable, steerable surface you can approve incrementally instead of auditing after the fact.

Numbers from OpenAI's GPT-5.6 builder guide: Luna held 98% of GPT-5.5's extraction accuracy at a eighteenth of the cost, programmatic tool calling cut one team's input tokens 21%, and retained reasoning plus compaction moved Sol from 13.3% to 38.3% on ARC-AGI-3 with roughly 6x fewer output tokens.
Why it mattersModel tiering, programmatic tool calling, and retained reasoning with compaction are producing order-of-magnitude cost differences on the same workloads — with published numbers you can check your own agent stack against.
Teaching Everyone to Fish for Tokens
Nathan Lambert compares open weight models to installed software versions rather than to Linux.
Why it mattersAnyone betting a product on open weights is choosing a dependency with a shelf life, and this frames what actually makes that ecosystem self sustaining.
Gemini 3.7 Flash Is HERE – Testing Google’s BEST Model Yet!
Bijan Bowen runs Gemini 3.7 Flash through practical coding and design tasks.
Why it mattersIndependent task by task footage of a new Flash tier model is the fastest way to see where it holds up on real coding work before you route traffic to it.
OpenRouter added cost per session: the median real cost of a task in each major harness over 30 days, which folds in the token efficiency that per-token pricing hides. Rankings are published and the underlying data is queryable under CC BY 4.0.
Why it mattersA cheap verbose model can cost more per finished task than a terse expensive one. Cost per session measures that directly, and the Dataset API lets you rebuild the frontier for your own harness.

From Ambient Documentation to Clinical Intelligence — Chaitanya Asawa, Abridge
Abridge's Chaitanya Asawa on why clinical AI evaluation resists a single correct answer.
Why it mattersRubric-based judging with independent authors and adjudication is a directly reusable pattern for anyone evaluating open-ended agent output where no single answer is correct.

200 Million Patient Interactions Later — Vivek Muppalla, Hippocratic AI
Hippocratic AI runs 31 models on every clinical call, one holding the thread and 30 specialists in parallel, because a single model is a single point of failure.
Why it mattersIt is a rare, concrete account of designing a multi-agent system where latency and safety genuinely conflict, and the evaluation arithmetic transfers to any high-volume agent deployment.

A walkthrough of customizing the Codex CLI by having the agent read its own compiled bundle and inject new features, kept alive across updates with a mods folder the agent reapplies on request.
Why it mattersTreating a closed tool's compiled bundle as something an agent can patch turns unshipped features into an afternoon's work. The mods-folder reapply pattern is what makes those patches survive upstream updates.

Codex can be pushed to a 1M-token window on GPT-5.6 Sol, but OpenAI's Noam Brown argues against it: the shipped limit is tuned for performance and cost, and autocompaction is meant to carry long sessions instead.
Why it mattersCodex's context limit is a deliberate cost/performance setting, not a ceiling worth raising by default — autocompaction is the intended mechanism, and the 1M option is opt-in for a reason.
A Year in LLM Serving: Workload Evolution, Caching and Load-Balancing
A year-long production trace from a large inference provider, spanning popular and long-tail models, used to characterize how serving workloads evolve and what that implies for caching and load balancing.
Why it mattersAnyone sizing an inference tier or tuning prefix caching is currently guessing from short synthetic traces. A year of real production traffic, including long-tail models, gives that work an empirical baseline.
Rethinking Automated Program Repair: The Impact of Bug Complexity, Fault Localization, and LLM Cost-efficiency
An empirical pass over LLM-based program repair that pulls apart what actually drives outcomes.
Why it mattersRepair success is dominated by fault-localization precision and structural bug complexity, not model choice alone — and reasoning settings carry a cost that this study prices rather than assumes away.
An index of the vibe-coding frontier. Corrections welcome.