Fable 5.1 leads the index and still costs 20% more per task
- Source
- x.com
- Date

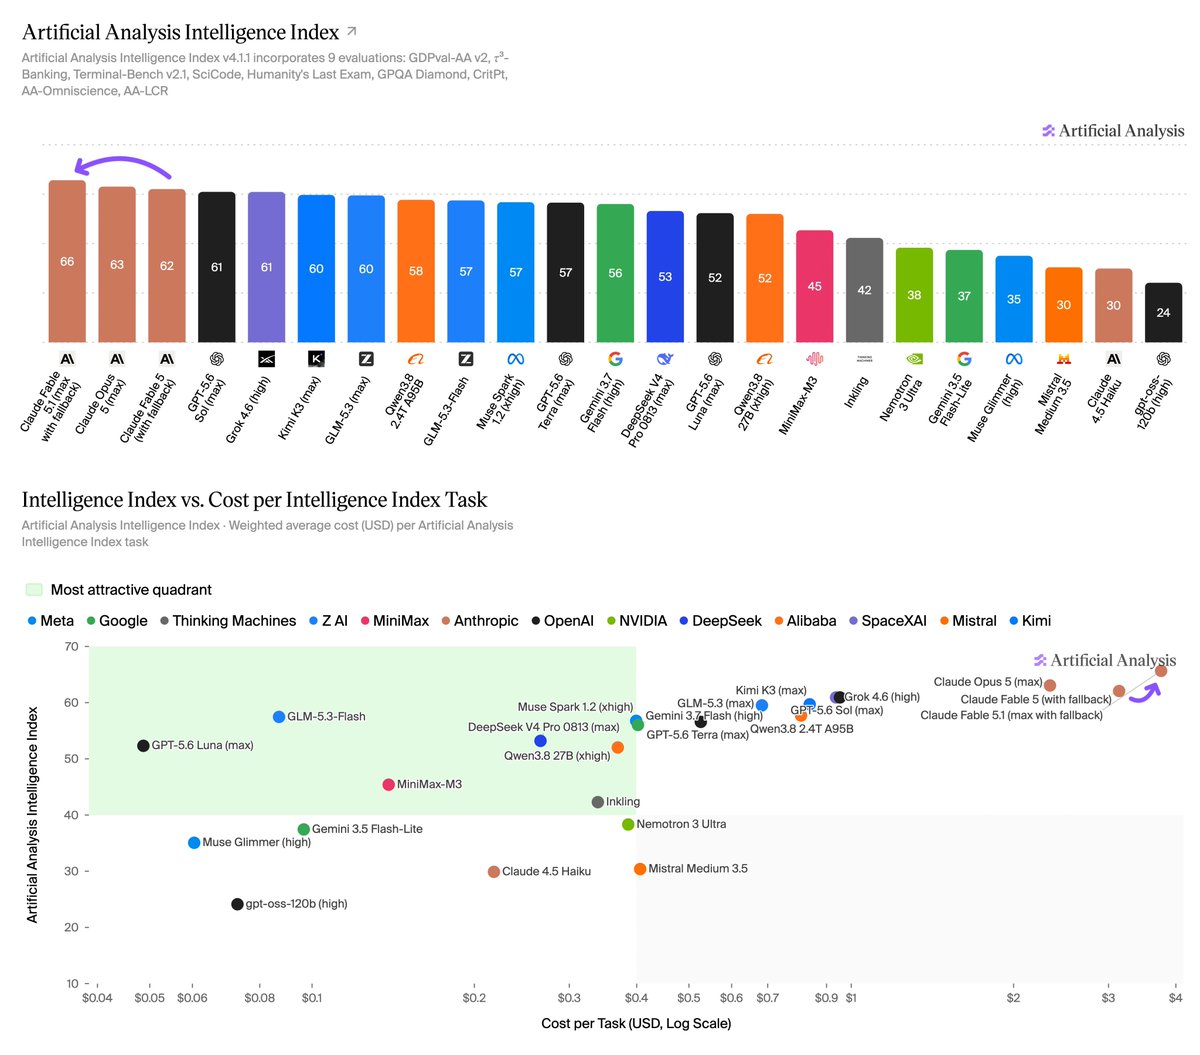
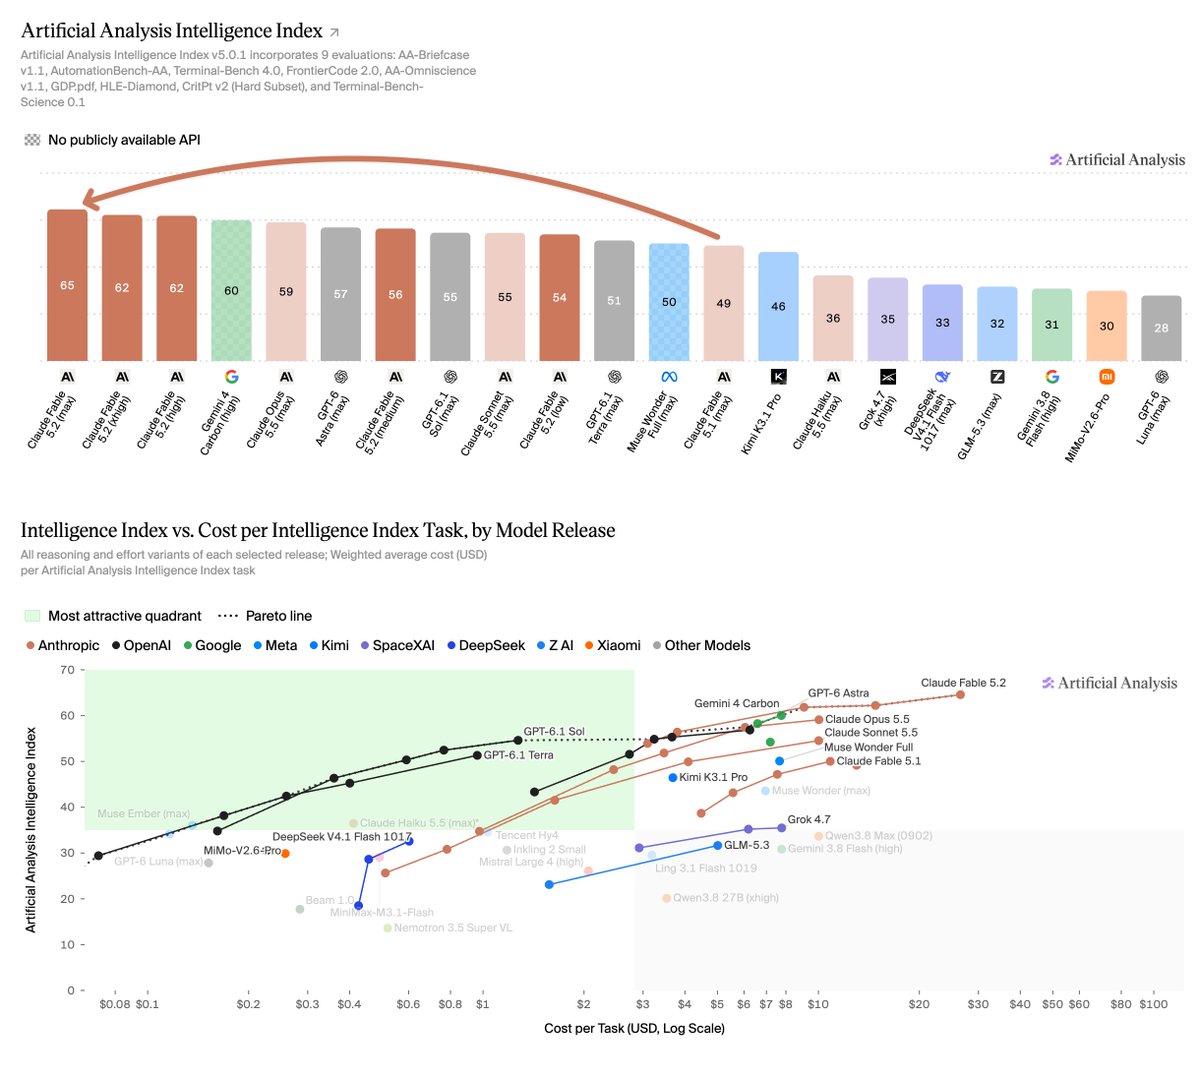
Claude Fable 5.1 tops the Artificial Analysis Intelligence Index but costs 20% more per task than Fable 5 despite a 75% cache read price cut We supported @AnthropicAI with pre-release evaluation of Claude Fable 5.1. At max effort it scores 66 on the Artificial Analysis Intelligence Index, the highest score we have measured, ahead of Claude Opus 5 (max, 63), Claude Fable 5 (max, 62), GPT-5.6 Sol (max, 61) and Grok 4.6 (high, 61). We evaluated the model with Anthropic's ‘default’ server-side fallback, which routes safety-flagged requests to Claude Opus 4.8 or Claude Opus 5; fallback served ~4% of output tokens across the Intelligence Index. Key takeaways ➤ Frontier Intelligence with improvements across benchmarks: Fable 5.1 gains +4 points on the Intelligence Index over Fable 5. On HLE, Fable 5.1 scores 59.1%, ahead of the previous best of 55.5% from Claude Fable 5. It posts the narrowly highest scores we’ve seen on Terminal-Bench v2.1 (91.4%) and SciCode (62.0%), and on τ³-Banking it gains 9 points over Fable 5 ➤ 75% cache read price cut, but Fable 5.1 still costs more per task: Anthropic has cut the cache read price from $1 to $0.25 per 1M cached input tokens, with standard…
Context
Anthropic's Fable 5.1 scored higher than any model Artificial Analysis had measured, and it also cost more to run per task than its predecessor, according to the firm's pre-release evaluation. At maximum effort it scored 66 on the Artificial Analysis Intelligence Index, the firm's combined score across a set of benchmarks, ahead of Claude Opus 5 at 63 and Fable 5 at 62. Each task in that index cost $3.76, 20% more than Fable 5 at the same setting.
The extra cost comes from how much the model writes. Anthropic cut the price of cache reads, input the model has already processed and stored, from $1 to $0.25 per million , and Artificial Analysis estimates that saved about $1.40 per task, mostly in the agentic tests where cached input makes up most of what the model reads. But output tokens cost $50 per million, five times the $10 price of ordinary input, and Fable 5.1 produced about 1.7 times as many of them as Fable 5. Artificial Analysis attributes the higher cost to that extra output. Anthropic's own estimate of about 25% savings measured something else: customer workloads at default effort, not this maximum-effort .
Lowering the effort setting cut the cost. At xhigh effort, Fable 5.1 scored 65 for $2.72 per task, $1.04 less than at maximum and one point lower, though still more expensive than Opus 5 at maximum effort ($2.34 for a score of 63). Artificial Analysis ran the model with Anthropic's default fallback, which sends safety-flagged requests to Claude Opus 4.8 or Opus 5; the firm says that fallback produced about 4% of output tokens.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Checking sign-in…
Loading comments…