AA benchmarks Devin Fusion, first multi-model coding agent on its index
- Source
- ArtificialAnlys
- Date
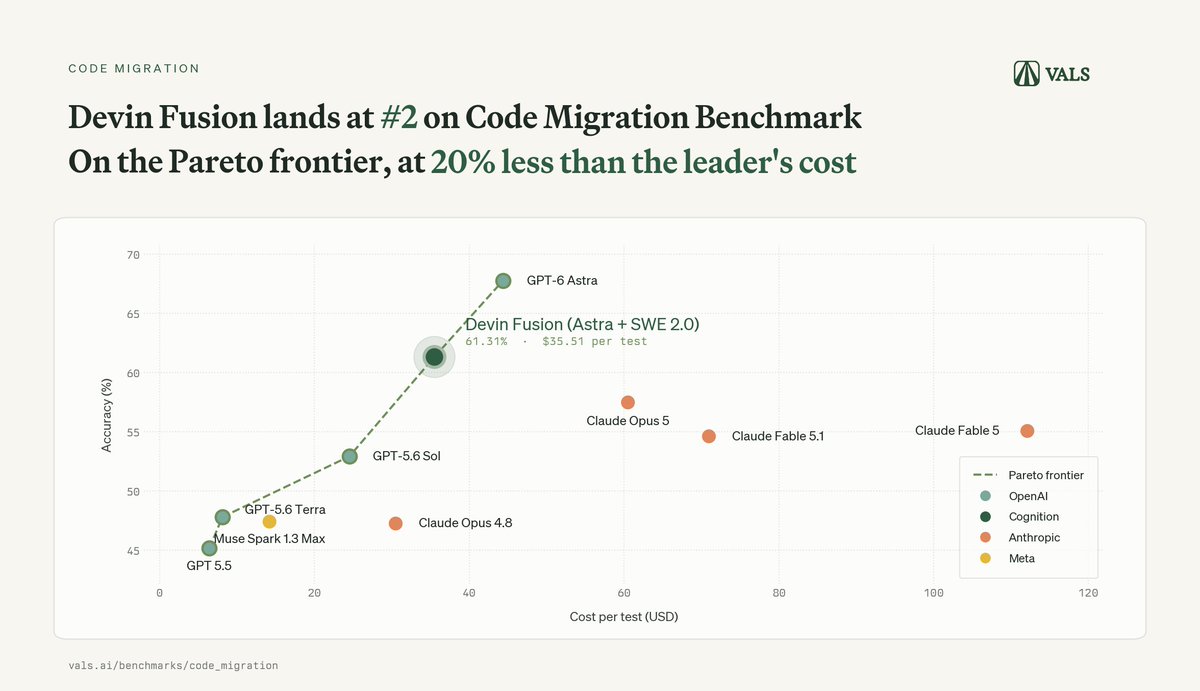
Artificial Analysis added Cognition's Devin Fusion to its coding agent index, and the result gives builders a concrete data point instead of a vendor claim. Devin Fusion is a dual model setup: a frontier model handles planning and hard reasoning steps, while the cheaper SWE-2 model executes routine edits and tool calls as a sidekick. Tested with GPT-6 Astra in the lead role, the pairing costs 43 percent less and completes tasks 31 percent faster than the same setup built on Claude Fable 5.1, while its accuracy score trails only slightly behind. That gap between cost and quality is the interesting part. Most coding agents still route every step through one expensive model, even when the step is a mechanical file edit that a smaller model handles just as well. Devin Fusion's benchmark suggests teams building their own agents can send the bulk of routine work to a cheap sidekick and reserve the frontier model for planning and judgment calls, without giving up much on task success. As agent frameworks mature, this lead plus sidekick pattern looks likely to become a default architecture rather than a niche optimization, and Artificial Analysis now has a first real benchmark to weigh that tradeoff against.
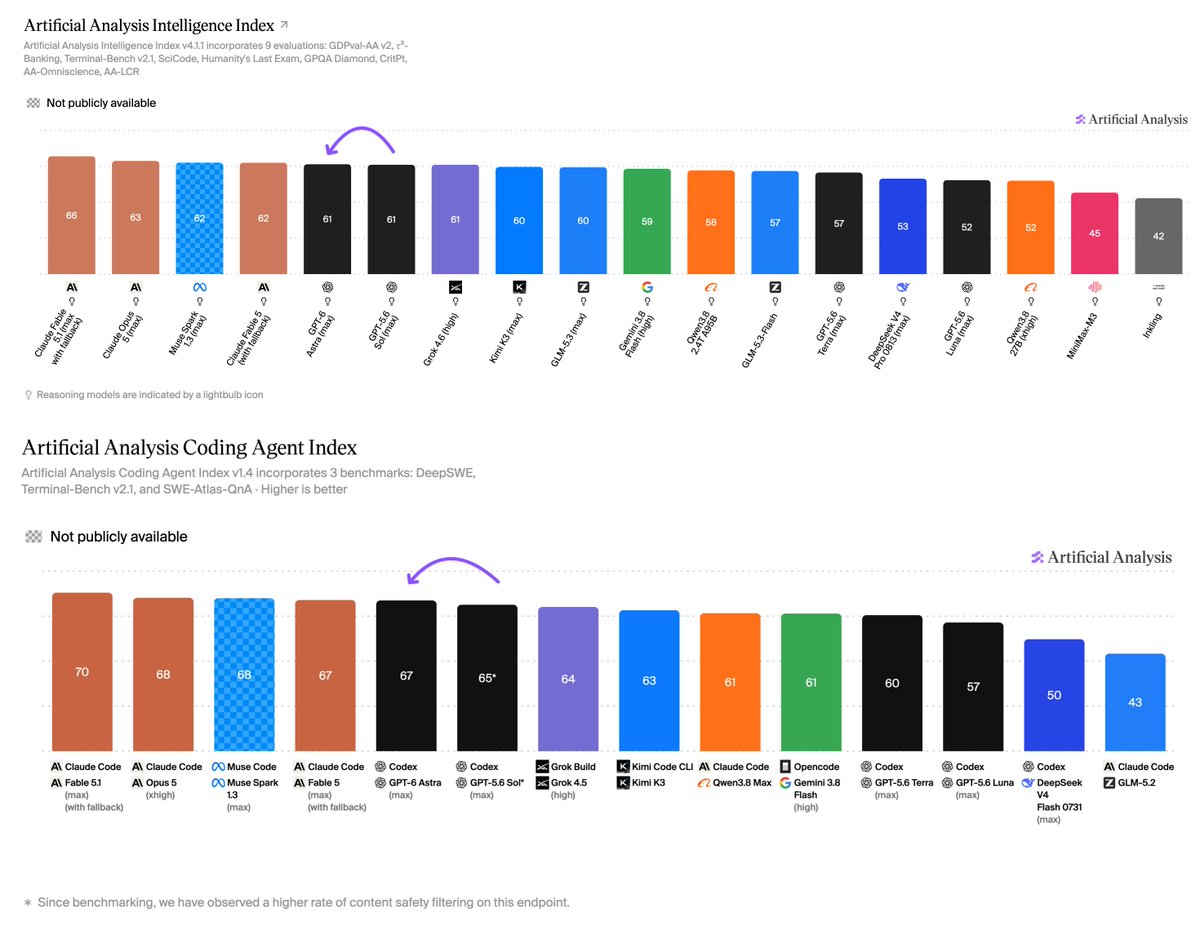
We independently benchmarked Devin Fusion for its release today - this is the first time a multi-model coding agent has been included on the Artificial Analysis Coding Agent Index, and it effectively retains Claude Fable 5.1 and GPT-6 Astra performance while reducing costs Devin Fusion runs a frontier lead model with a cost-efficient sidekick. We tested configurations from Cognition combining frontier models from Anthropic and OpenAI with their new SWE-2 (medium) as a sidekick model. Configured with Claude Fable 5.1 (xhigh) + SWE-2 (medium), Devin Fusion scores 62 on the Coding Agent Index v1.5, while with GPT-6 Astra (xhigh) + SWE-2 (medium) it scores 59. The Fable configuration has the higher score, while the Astra configuration is 43% less expensive and completes tasks 31% faster. Congratulations to @cognition on the release! See below for our results and analysis 🧵

Context
Artificial Analysis independently benchmarked Cognition's Devin Fusion, the first multi-model coding it has added to its Coding Agent Index. Fusion runs a frontier model as the lead, paired with Cognition's cheaper SWE-2 model as a sidekick for lower-stakes steps. Configured with Claude Fable 5.1 (xhigh) plus SWE-2, it scores 62 on the index; configured with GPT-6 Astra (xhigh) plus SWE-2, it scores 59, but that pairing costs 43% less and completes tasks 31% faster than the Fable configuration.
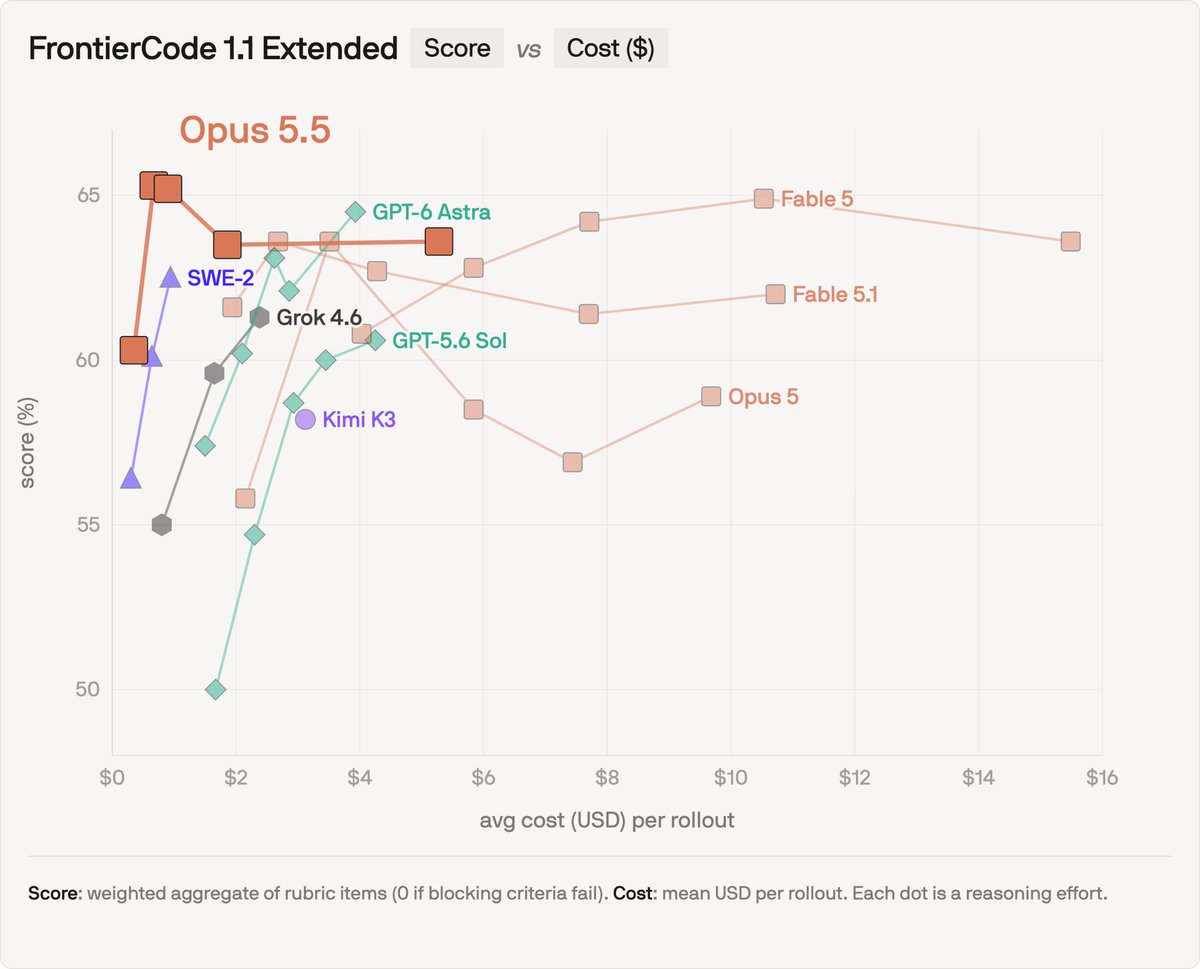
SWE-2 itself launched the same day as a lower-cost coding model Cognition post-trained from Kimi K3, with tunable reasoning effort so a task can trade accuracy for speed and cost. This is one of the first independent measurements of how that tradeoff plays out when SWE-2 is paired with a frontier lead model rather than run alone.




Checking sign-in…
Loading comments…