Xiaomi's MiMo-V2.6-Pro tops open-weights model benchmarks
- Source
- ArtificialAnlys
- Date
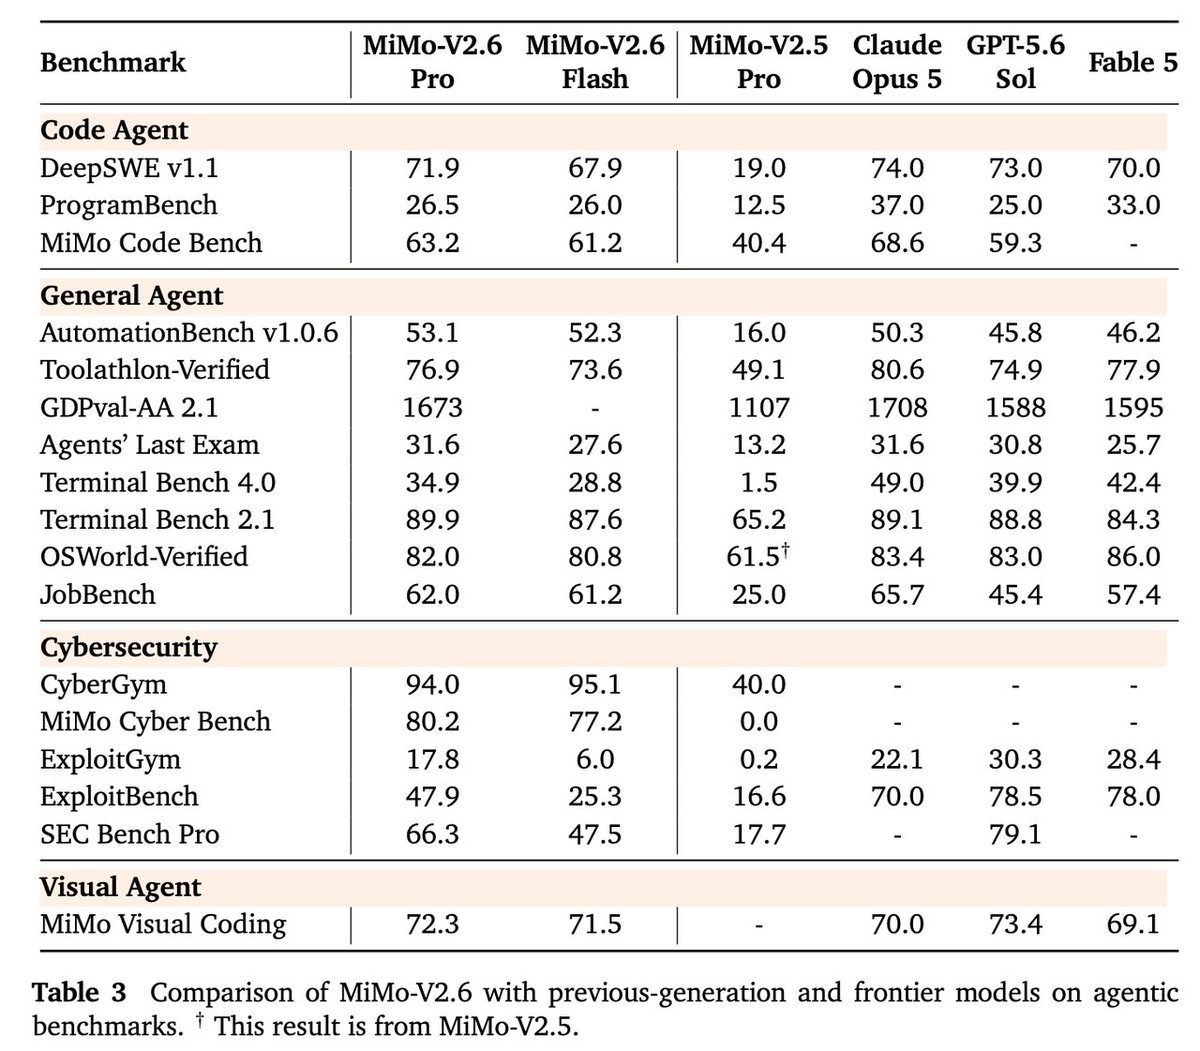
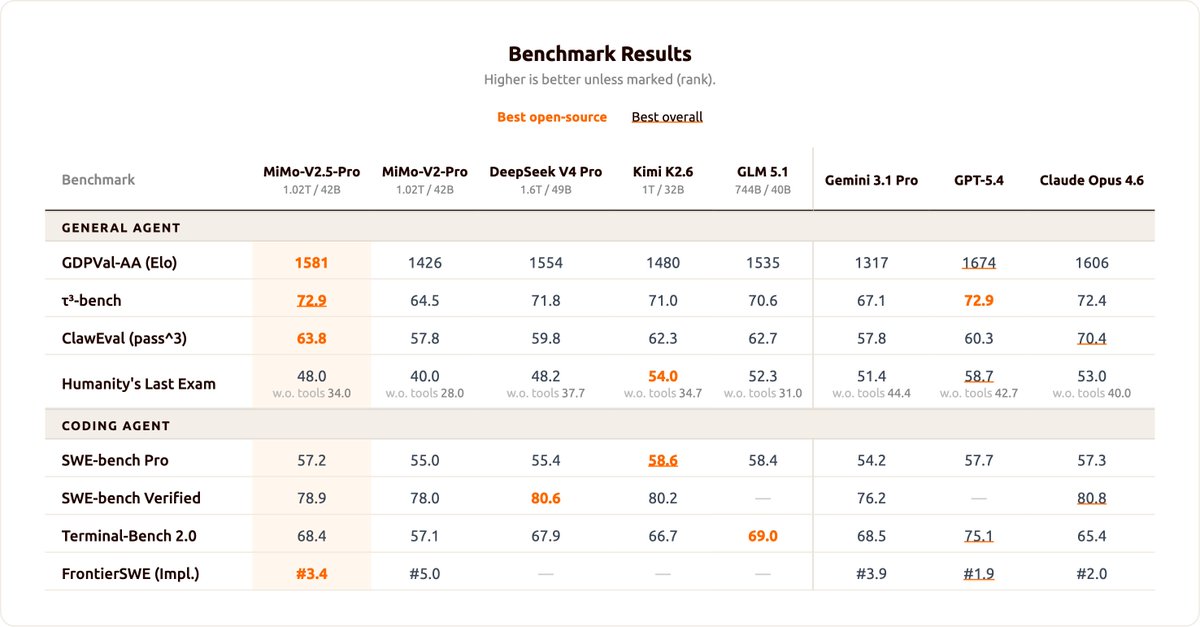
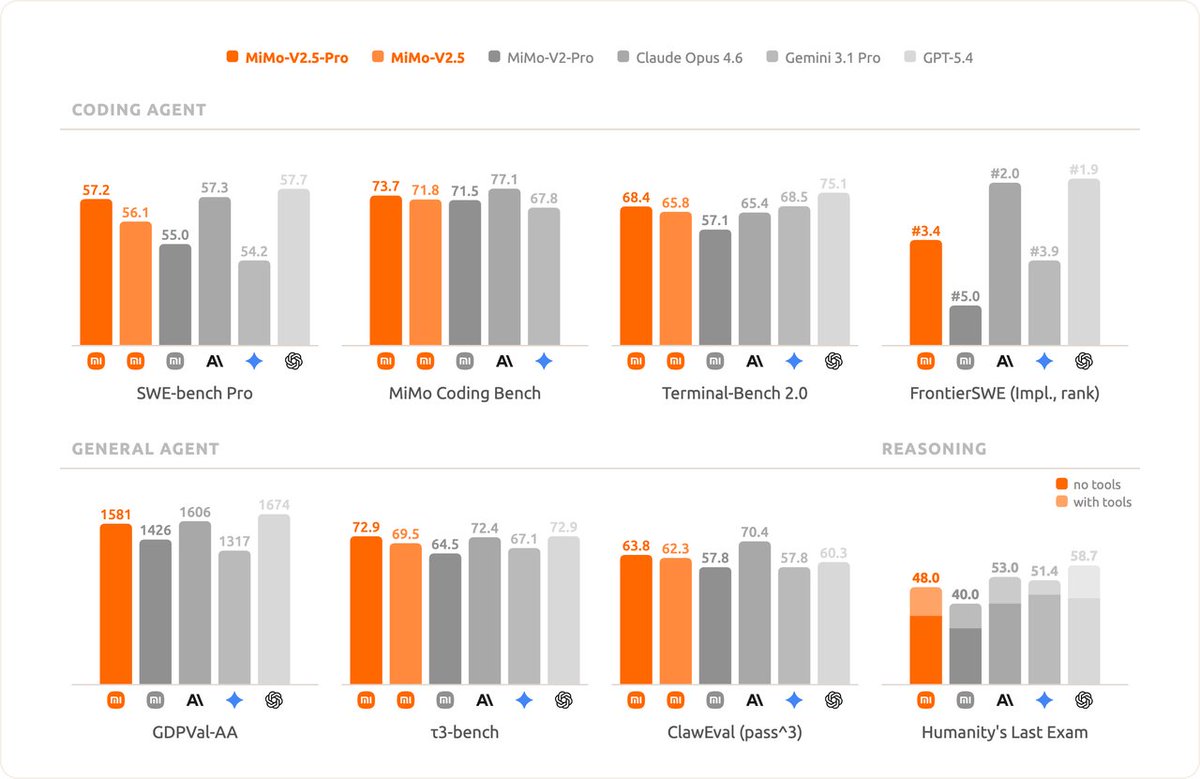
MiMo-V2.6-Pro debuts as the top open weights model on the Artificial Analysis Intelligence Index (46). At $0.13 per Intelligence Index task, it lands on the Intelligence vs. Cost per Task Pareto frontier @Xiaomi has just released MiMo-V2.6-Pro, an open weights model with major advances in intelligence over its predecessor, MiMo-V2.5-Pro (Intelligence Index: 26). Despite the improvement, it retains the same attractive pricing at $0.435 per 1M input tokens (with a 99% cache-hit discount) and $0.87 per 1M output tokens. This makes MiMo-V2.6-Pro one of the most cost-efficient models to deploy. MiMo-V2.6-Pro is an MoE model with 1.02T total parameters and 42B active parameters. Stay tuned for additional analysis of the model. Check out MiMo-V2.6-Pro full benchmarking breakdown here:

Context
Artificial Analysis's independent testing scores MiMo-V2.6-Pro, Xiaomi's newly released open-weights model, at 46 on its Intelligence Index, the top result among models and enough to place it on Artificial Analysis's intelligence-versus-cost Pareto frontier, the set of models offering the best intelligence available for their price. That is a large jump from its predecessor, MiMo-V2.5-Pro, which scored 26 on the same index.
The model is a design with 1.02 trillion total parameters but only 42 billion active per token, which keeps cost down despite the large total size. Pricing held steady at $0.435 per million input tokens, with a 99% discount on cached input, and $0.87 per million output tokens, working out to about $0.13 per Intelligence Index task by Artificial Analysis's measure. Artificial Analysis says a fuller breakdown is coming separately, so this post establishes the headline score and pricing but not category-by-category performance.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
- mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.




Checking sign-in…
Loading comments…