Artificial Analysis: Opus 5.5 Tops Intelligence Index With Price Cut
- Source
- ArtificialAnlys
- Date
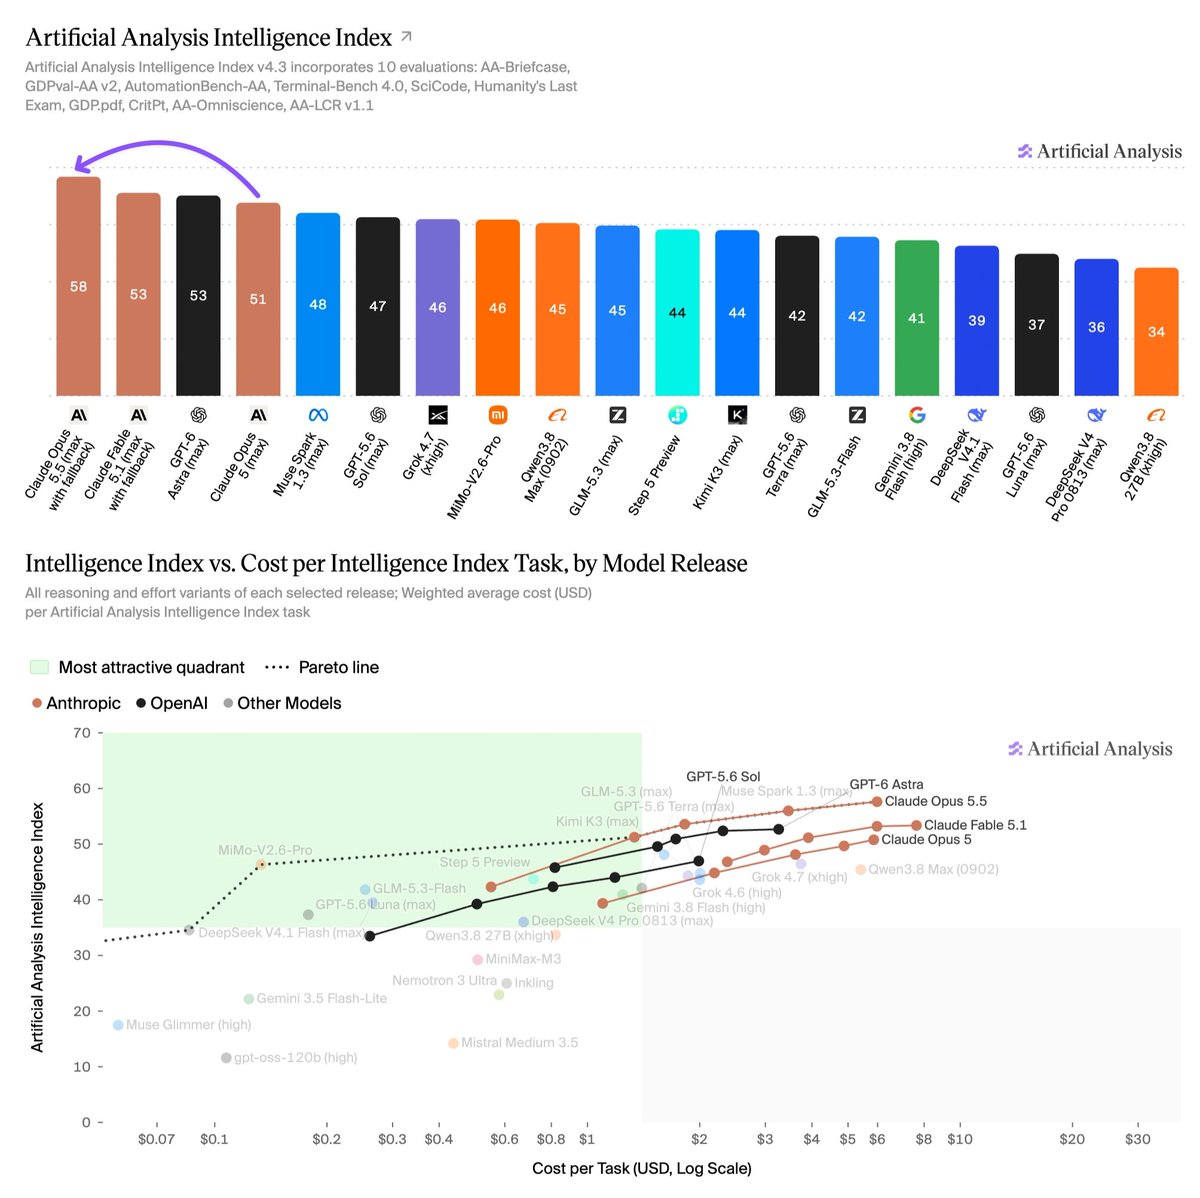
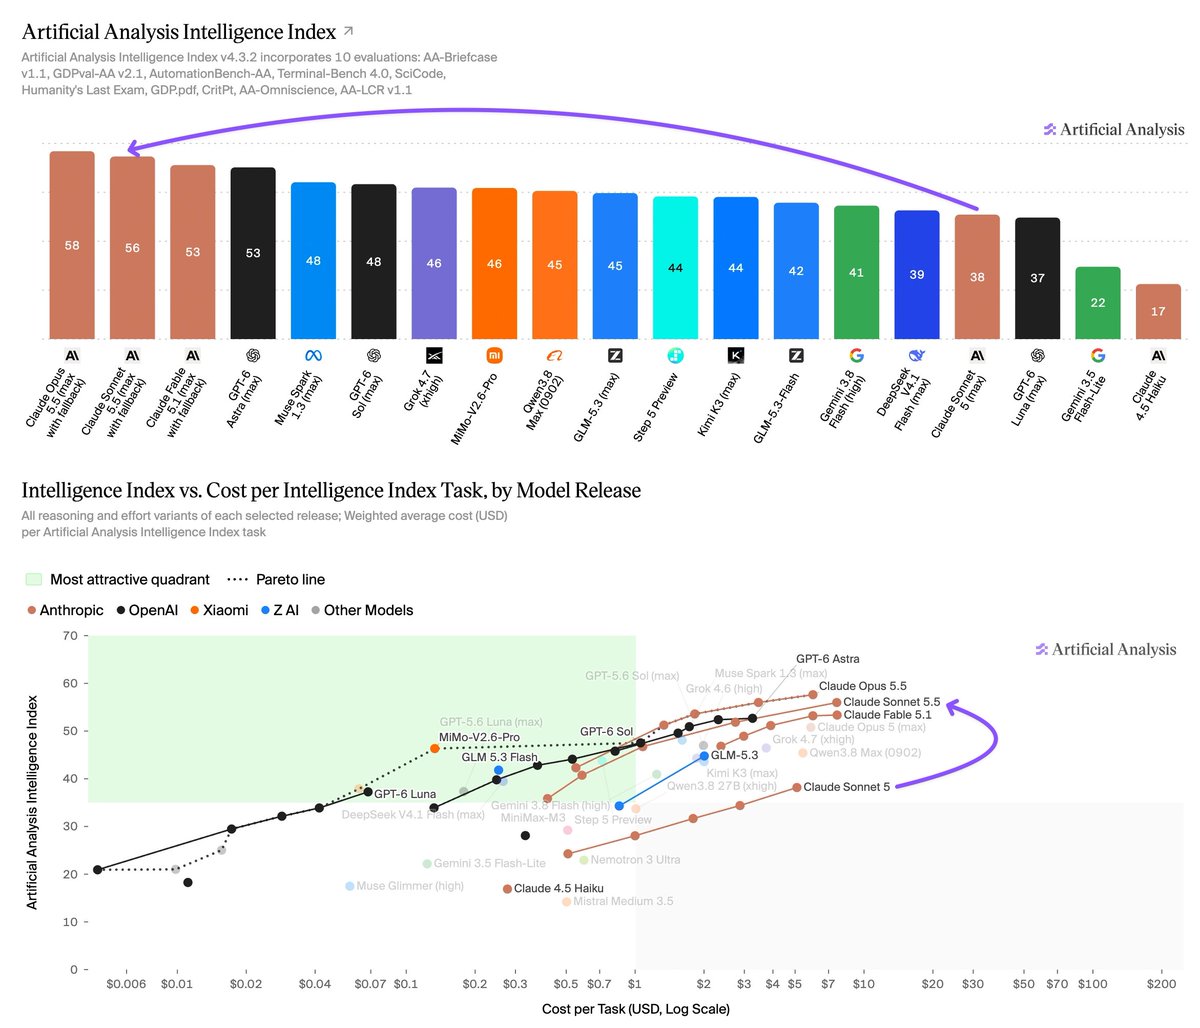
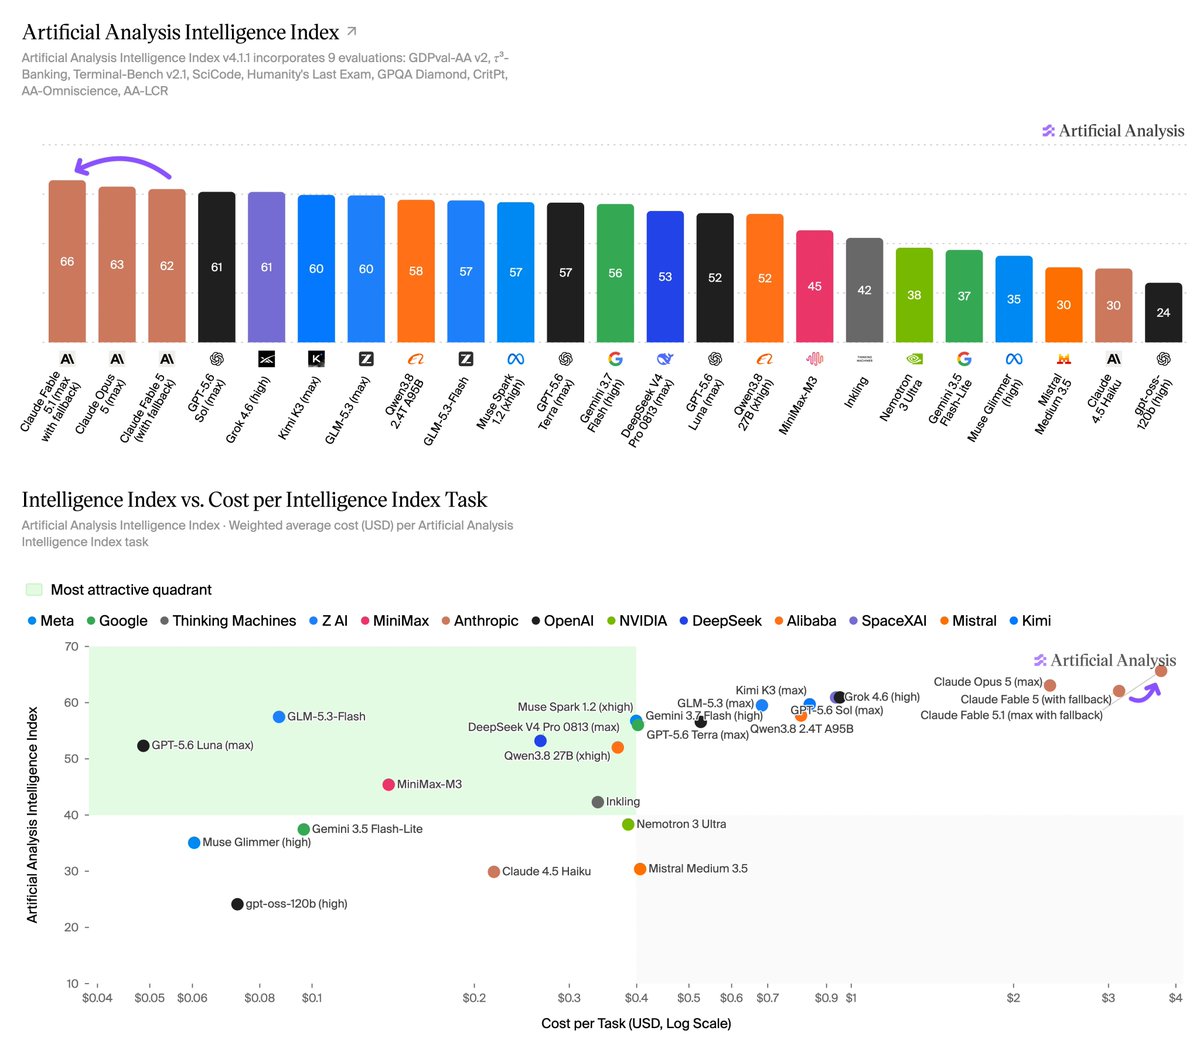
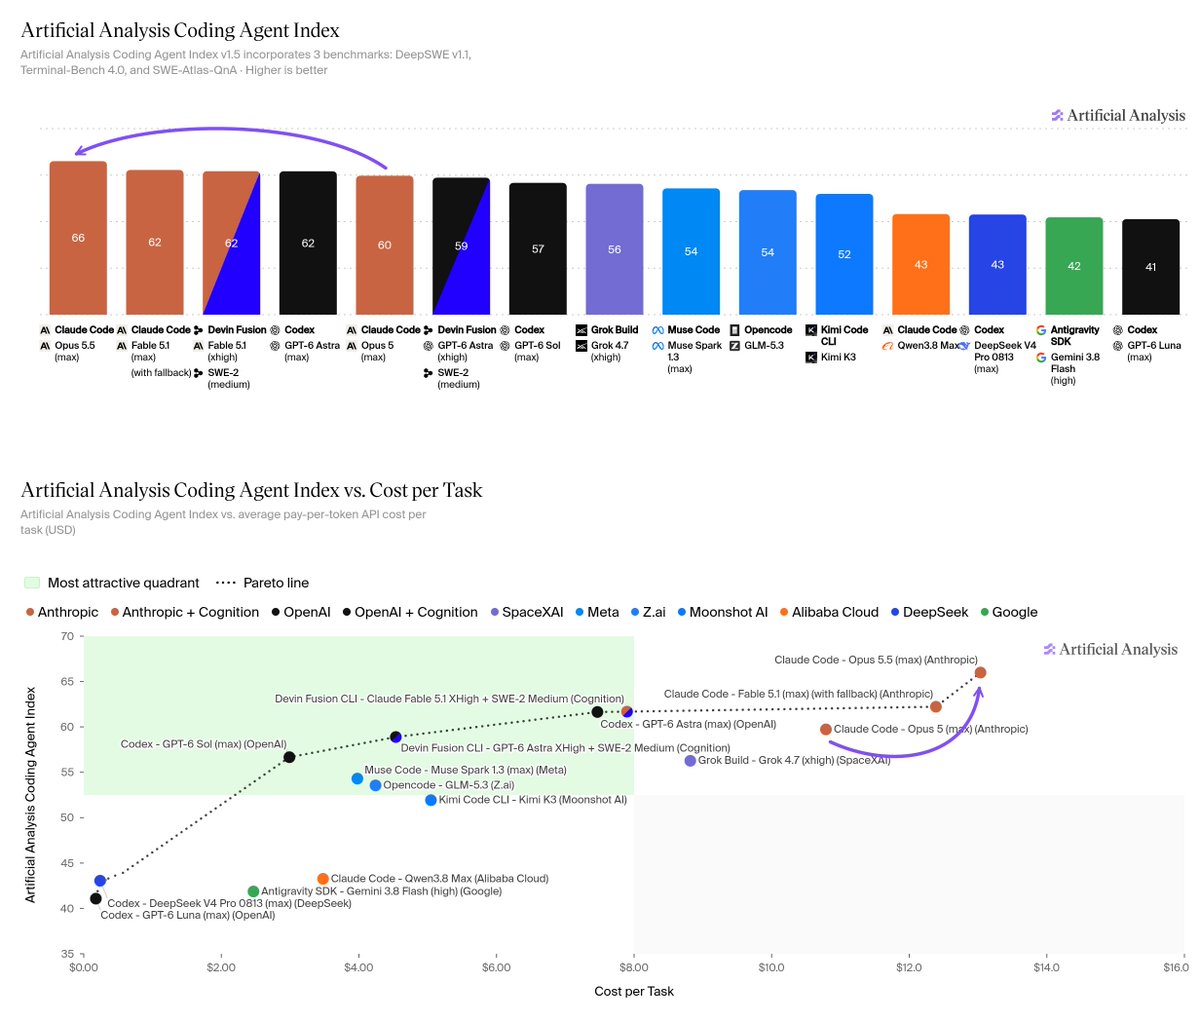
Claude Opus 5.5 takes the top spot on the Artificial Analysis Intelligence Index, along with a 20% price cut and larger cache hit discount Claude Opus 5.5 brings Anthropic to parity with GPT-6 Astra on evaluations like Terminal-Bench 4.0 and AutomationBench-AA, while extending Anthropic’s lead in agentic knowledge work. At max effort it scores 58 on the Artificial Analysis Intelligence Index, the highest score we have measured by several points. Anthropic has cut Opus pricing to $4/$20 per 1M input/output tokens (Opus 5: $5/$25) and cache reads from $0.50 to $0.20. Key takeaways: ➤ Consistent strong performance, with leading scores on six of the ten Intelligence Index evaluations: Humanity's Last Exam 61.4% (previous best 59.1%, Claude Fable 5.1), SciCode 66.9% (63.1%, Fable 5.1), GDPval-AA v2.1, AA-Briefcase v1.1, AA-Omniscience and AutomationBench-AA. On Terminal-Bench 4.0 it scores 59.6%, level with the leader GPT-6 Astra (xhigh) and +11 points over Opus 5. It remains slightly behind on CritPt, AA-LCR, and GDP.pdf ➤ Leads in agentic knowledge work: On AA-Briefcase, our private frontier knowledge work evaluation, it reaches an Elo of 1822. This is +143 over Fable 5.1, ahead…
Context
Artificial Analysis reports that Anthropic's Claude Opus 5.5 scores 58 at max effort on its Intelligence Index, the highest it has measured by several points. Anthropic also cut Opus pricing 20%, to $4/$20 per million input/output from Opus 5's $5/$25, and cache reads are now a 95% discount to uncached input, up from 90%.
Opus 5.5 leads on six of the index's ten evaluations, including Humanity's Last Exam at 61.4% (previous best 59.1%) and SciCode at 66.9% (63.1%). On Terminal-Bench 4.0 it scores 59.6%, level with GPT-6 Astra and 11 points above Opus 5. On AA-Briefcase, a private knowledge-work , it reaches 1822 Elo, 143 above Claude Fable 5.1.
The caveat is token use: at max effort Opus 5.5 uses about 119,000 output tokens per Intelligence Index task against about 73,000 for Opus 5, yet Artificial Analysis says cost per task is level with Opus 5. It remains slightly behind on CritPt, AA-LCR and GDP.pdf.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.




Checking sign-in…
Loading comments…