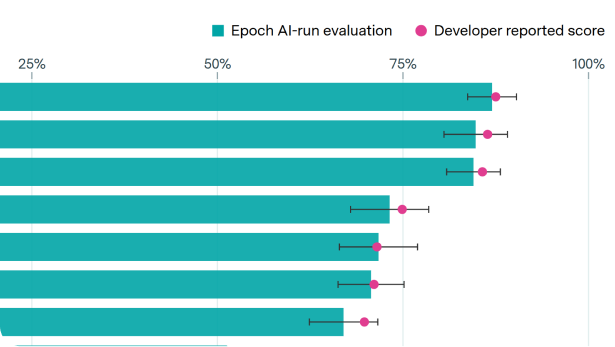
Supports trusting recent lab-reported GPQA Diamond numbers, since they fell within Epoch's confidence intervals for GPT-5, Opus 4.1, Grok 4 and others.
Key takeaways · AI-distilled
The largest gap between a self-report and Epoch's score is Llama 4 Maverick: 69.8% self-reported versus 67.0% in Epoch's runs (z = 1.00, p = 0.32), which is not statistically significant.
DeepSeek R1 showed nearly no gap, reporting 71.5% against Epoch's 71.7%, while GPT-5 reported 85.7% against 84.5% and Grok 4 reported 87.5% against 87.0%.
Epoch tests models multiple times on each question and aggregates results to handle sampling randomness; it says it believes this often estimates true performance to within 4-6 percentage points with 90% confidence.
Mistral reported no GPQA Diamond score for Mistral Large, so Epoch compared against an Artificial Analysis run endorsed on Mistral's benchmarks page; that figure (48.6%) was below Epoch's 51.3% (p = 0.32).
Opus 4.1 was self-reported at 74.9% on GPQA Diamond versus 73.2% in Epoch's runs (z = 0.53, p = 0.60); the table row carries the note 'No extended thinking'.