Glm 5 2 Is The New Leading Open Weights Model On The Artificial Analysis Intelligence Index
Source
artificialanalysis.ai
Author
Artificial Analysis articles
Date
Why it matters
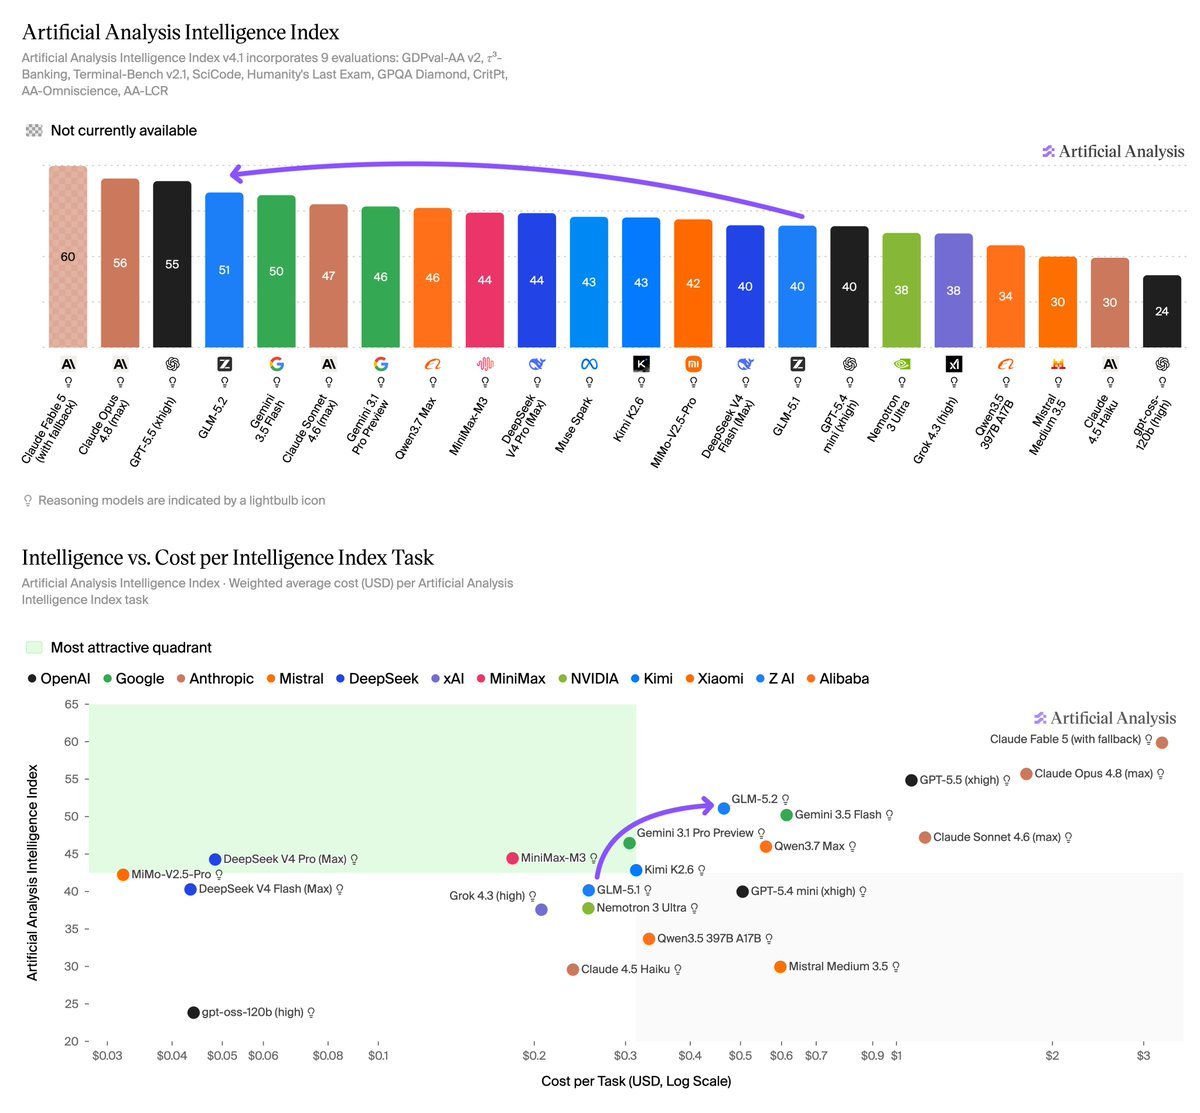
GLM-5.2 scores 51 on the Intelligence Index at unchanged GLM-5.1 pricing, making it the strongest open-weights option on cost per task and a relevant choice for self-hosted agents.
Key takeaways · AI-distilled
GLM-5.2 keeps GLM-5.1's size (744B total, 40B active) but scores 11 points higher at 51 on Intelligence Index v4.1, ahead of MiniMax-M3 and DeepSeek V4 Pro (max) (both 44). It is MIT-licensed with context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → raised from 200K to 1M tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition →.
On GDPval-AA v2 it scored 1524, effectively level with GPT-5.5 xhigh (1514). The v2 benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → baselines Elo to human performance at 1000, uses a rotating panel of frontier-model judges and raises the turn limit from 100 to 250.
GLM-5.2 improved over GLM-5.1 on most evaluations; reported gains include CritPt (+16 to 21%), TerminalBench v2.1 (+16 to 78%), tau3 banking (+15 to 27%) and HLE (+12 to 40%).
It is less token-efficient, using 43k output tokens per task (37k of it reasoning) vs 26k for GLM-5.1; cost per task is about $0.46, versus $0.25 for GLM-5.1 and $0.05 for DeepSeek V4 Pro (max), though first-party API pricing is in line with GLM-5.1.
Terms in this piece · Glossary
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.