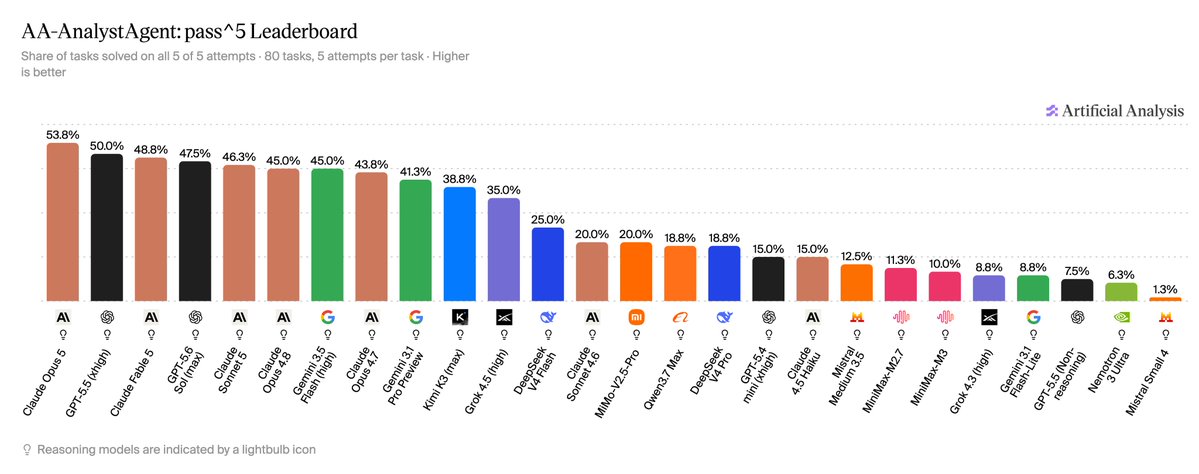
Reliability measured as correct on all five attempts shows even the best model solves only 54% of real spreadsheet analysis tasks, a useful bar before trusting analyst agents unreviewed.
Key takeaways · AI-distilled
AA-AnalystAgent counts a task as reliable only if the model answers correctly on all five attempts. A high rate of solving a task at least once can therefore coexist with a much lower headline score.
Artificial Analysis found early commitment to a wrong interpretation in 57% of 1,567 classified failed AA-AnalystAgent attempts. Attempts could have multiple failure labels, so the category percentages do not sum to 100%.
AA-AnalystAgent runs 80 private questions in a shared tool-using agent harnessThe scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.Full definition →. Its launch cost comparisons use representative provider prices and cache-hit rates, so those costs are conditional on the evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition →'s pricing assumptions.
Terms in this piece · Glossary
agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.