Grok 4.7 is now available in Devin.
- Source
- Cognition
- Date

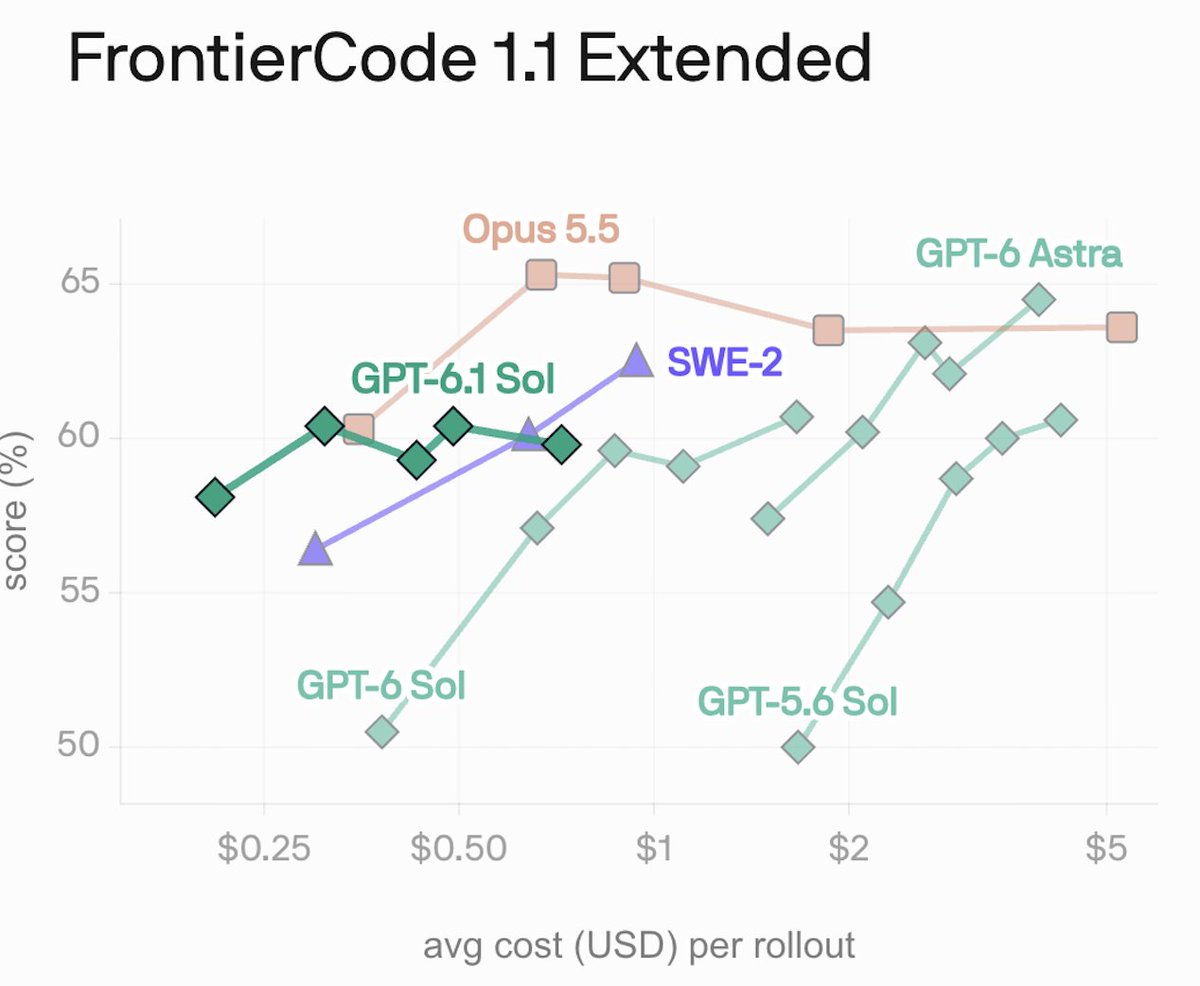
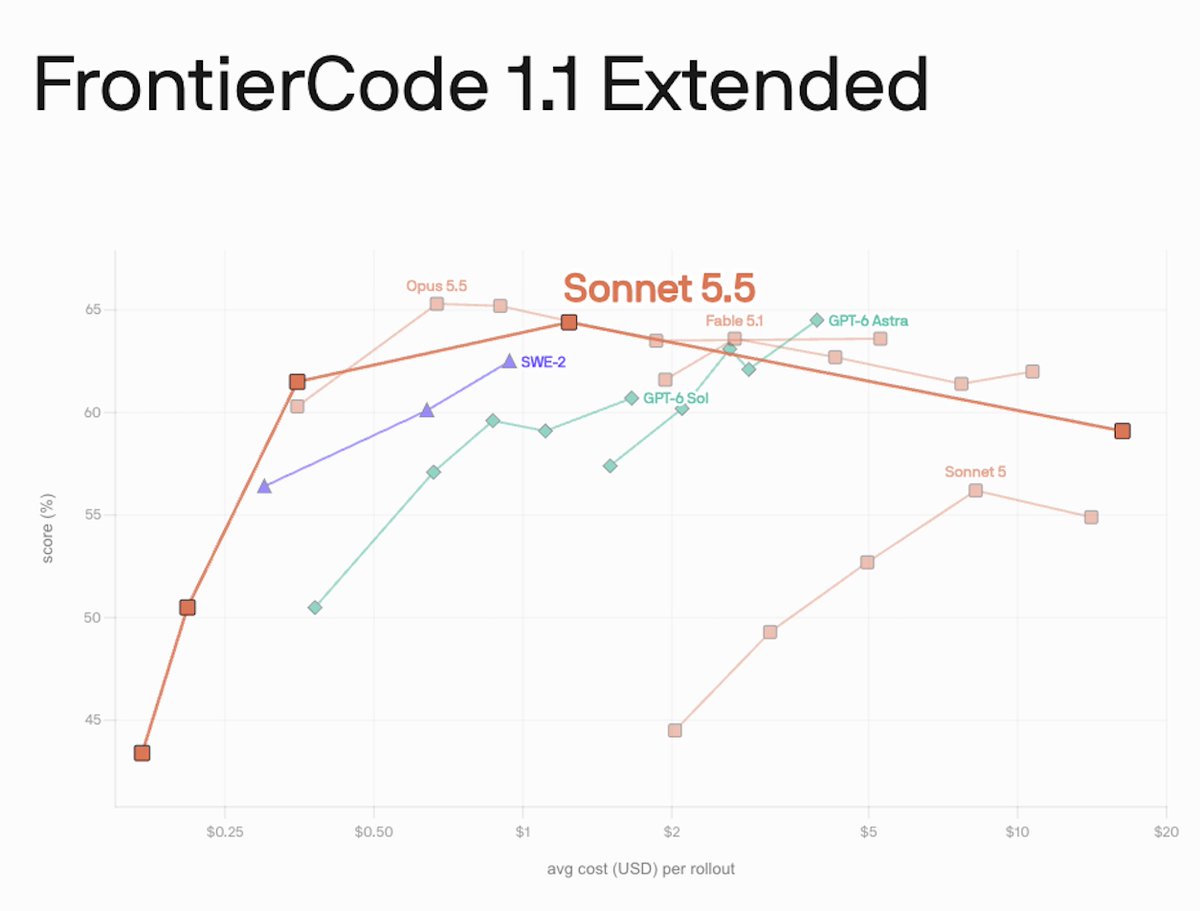
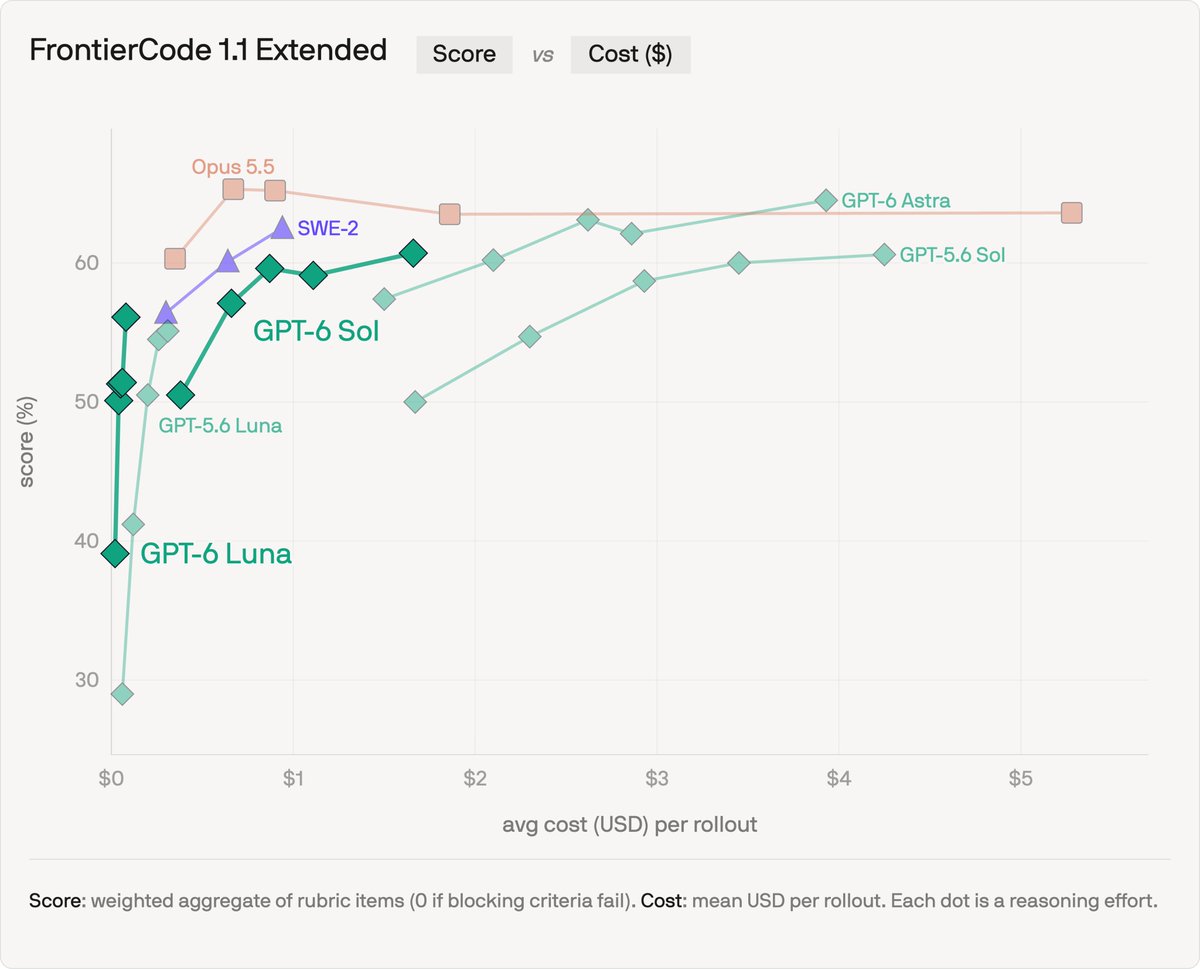
Grok 4.7 is now available in Devin. On FrontierCode 1.1, Grok 4.7 scores 59.4% on Extended. In our evaluation, we see the model performs very well on hard backend engineering tasks.

Context
Cognition, maker of the Devin coding , added Grok 4.7 as a model option and reports it scoring 59.4% on FrontierCode 1.1 Extended, Cognition's own for mergeable, real-world engineering tasks. Cognition's notes the model performs especially well on hard backend engineering work specifically, without detailing performance on other task types in this post.
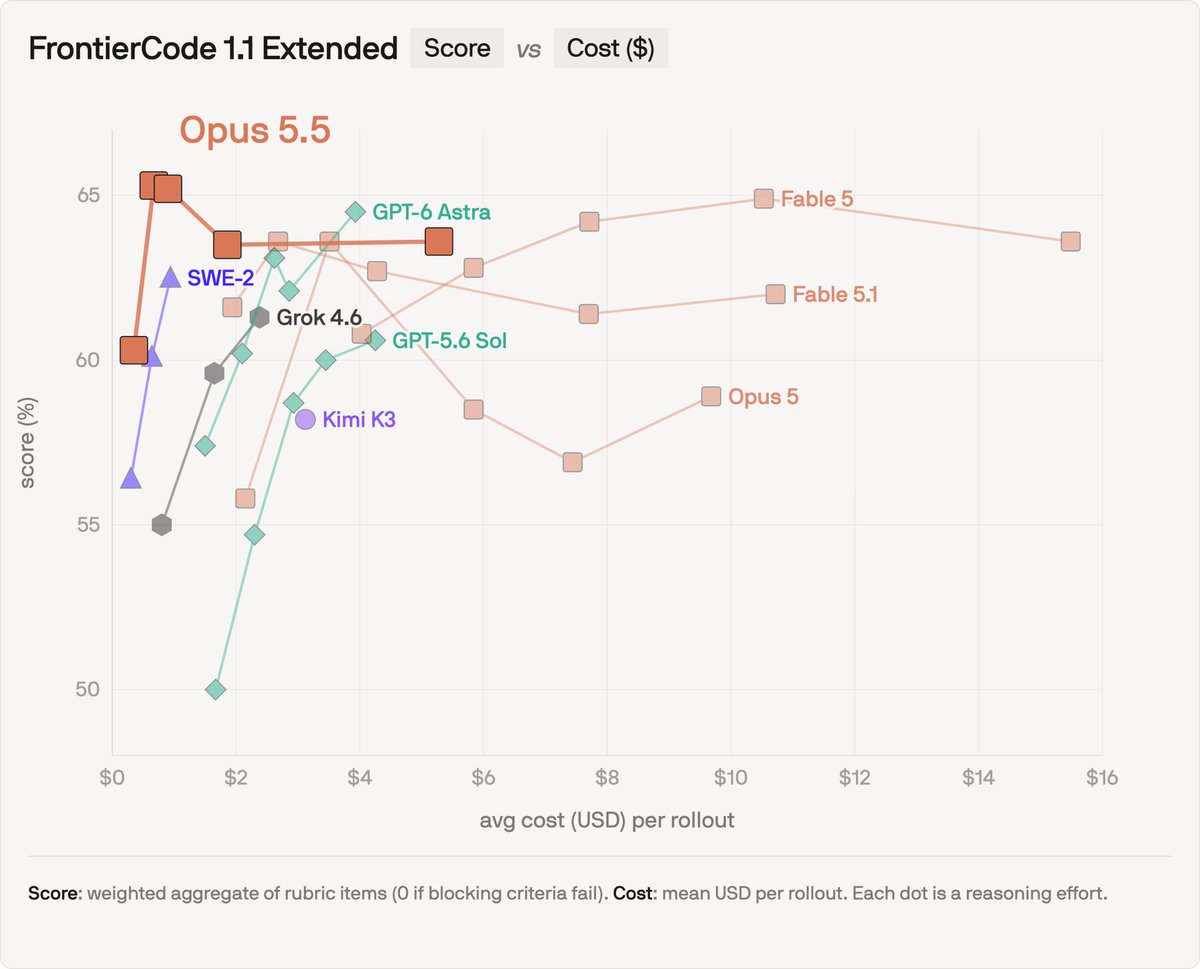
That score did not stay the ceiling for long: the next day, Cognition added Claude Opus 5.5 to Devin and reported it topping the same FrontierCode 1.1 Extended benchmark at 65.3%, at a lower cost than the prior leader. Both figures are Cognition's own internal benchmark results, not independently verified scores, so they describe relative model performance inside Cognition's own rather than a neutral ranking.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.

Checking sign-in…
Loading comments…