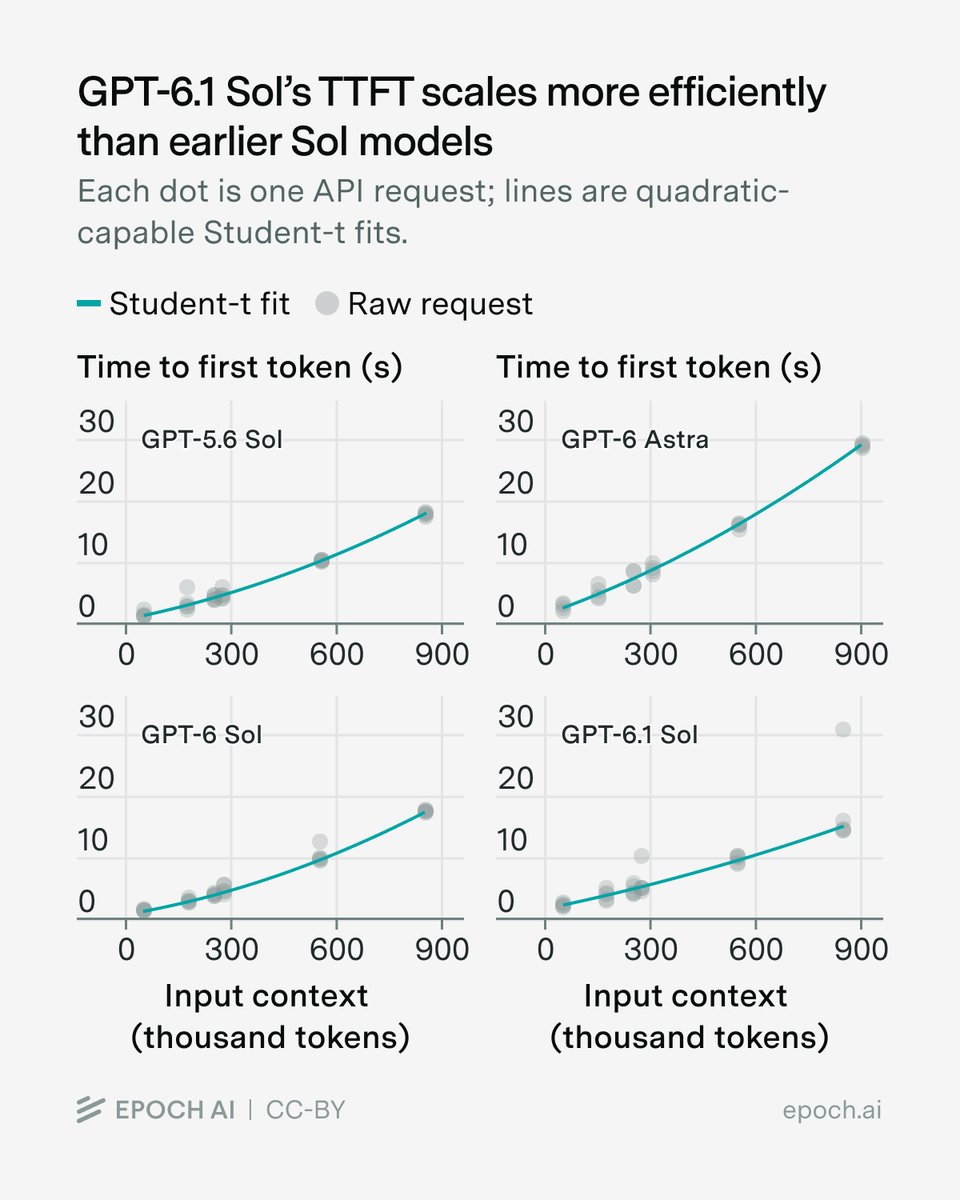
If you run long-context agents, latency at large prompts grows far faster on GPT-5.6 than on Claude 5 per this data, which should shape model choice and context budgeting.
Key takeaways · AI-distilled
Measuring time to first tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → with reasoning off up to about 1M tokens, Epoch found GPT-5.6 Terra and Sol curve upward, consistent with a large quadratic term, while Claude Sonnet 5 stayed near-linear and Opus 5 was noisier but similar.
The gap held across three estimators with different assumptions about API latency noise, all recovering similar curvature for GPT-5.6 and near-linear fits for Claude.
Epoch reads this as different architectures: full attentionThe mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.Full definition →, whose compute scales quadratically with context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition →, appears to contribute much less to long-context processing in Claude than in GPT.
Pricing diverges the same way: OpenAI charges double input and 1.5x output prices above 272,000 input tokens, while Claude keeps a fixed price at any length, though Epoch notes price need not reflect cost.
Terms in this piece · Glossary
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.