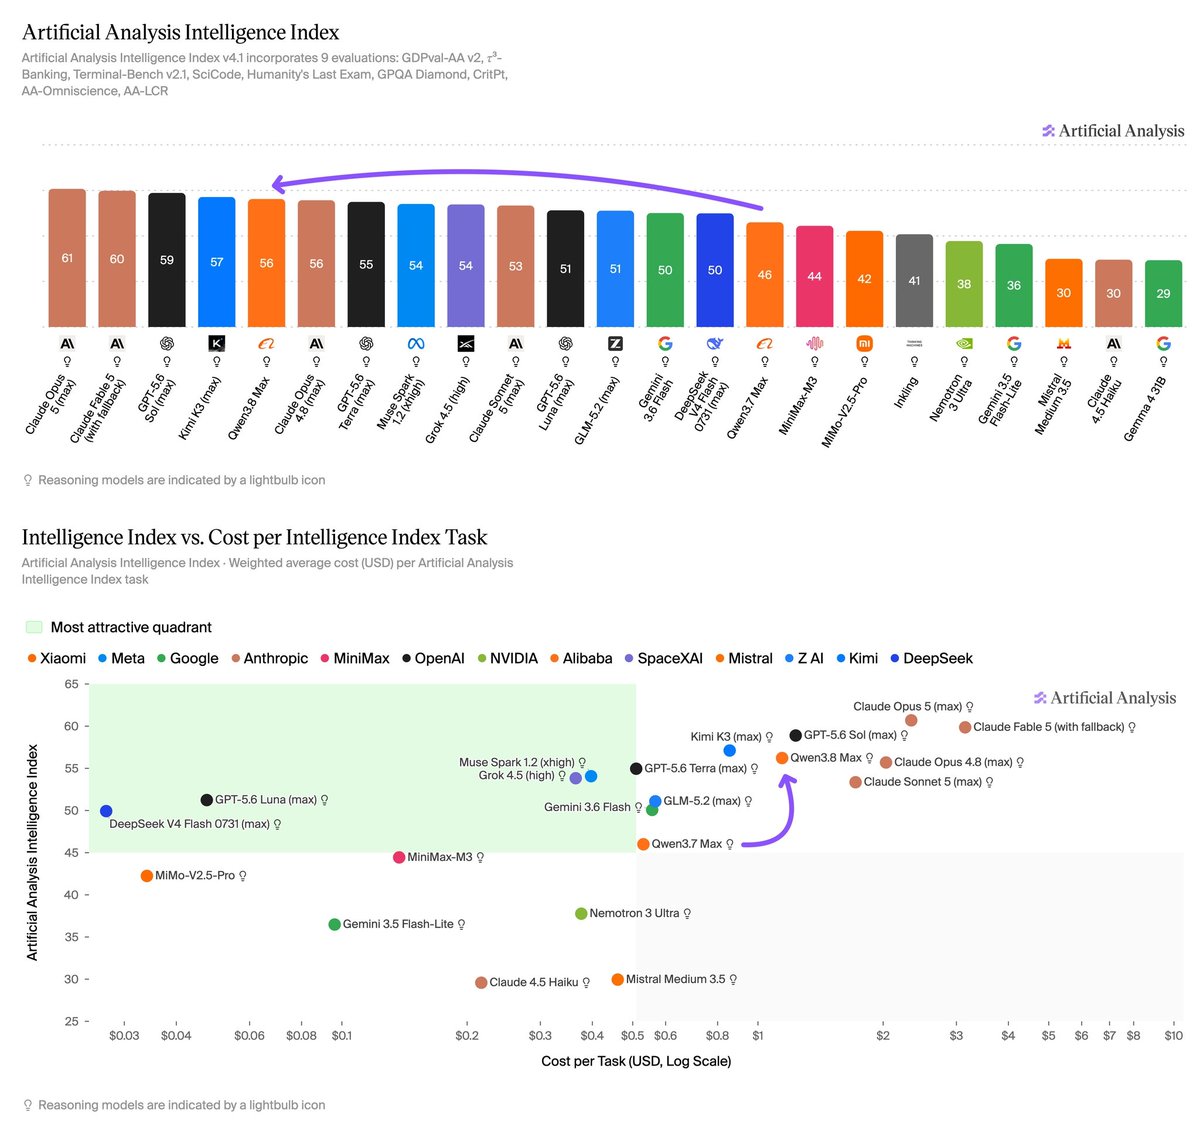
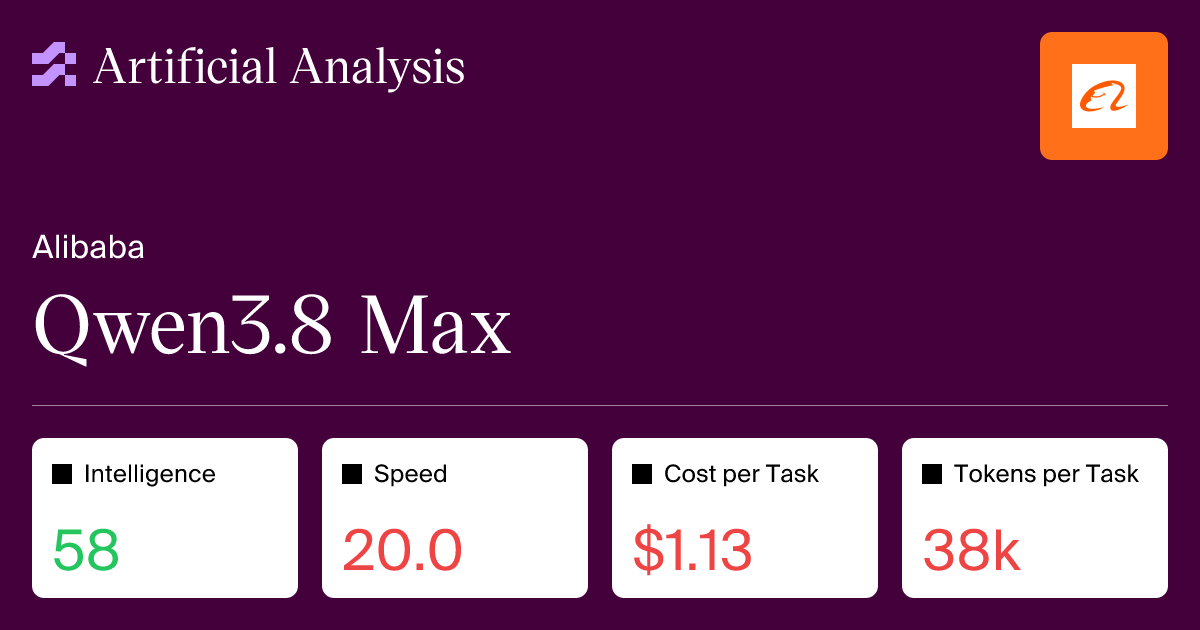
Qwen3.8 Max scores 1739 Elo on GDPval-AA, ahead of Kimi K3 (1685), effectively tied with Claude Fable 5 (1743) and GPT-5.6 Sol (max, 1730), and behind only Claude Opus 5 (max, 1852). The 468 Elo gain is in part driven by the new model taking more turns per task (64 vs. 14 for Qwen3.7 Max)
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
Why it matters
A gain driven by taking 4x more turns per task is a different purchase than a gain in per-turn capability: it lands as latency and tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → spend in production. This is the kind of read a benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → headline alone would hide.