We're introducing GLM-5.2, our latest flagship model for long-horizon tasks. It marks a substantial leap in long-horizon task capability over its predecessor GLM-5.1 and, for the first time, delivers that capability on a solid 1M-token context. GLM-5.2's new capabilities include:
Solid 1M Context: A solid 1M-token context that stably sustains long-horizon work
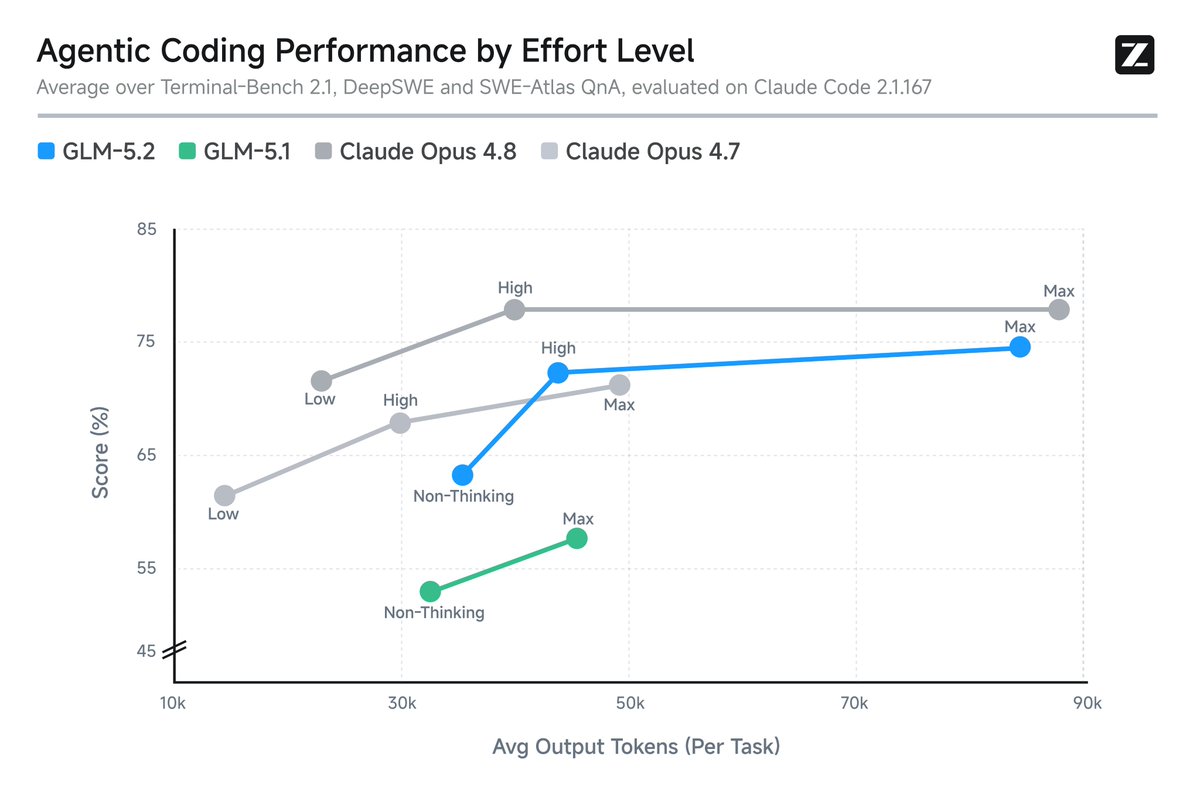
Advanced Coding with Flexible Effort: Stronger coding capabilities with multiple thinking effort levels to balance performance and latency
Improved Architecture: We propose IndexShare, which reuses the same indexer across every four sparse attention layers, reducing per-token FLOPs by 2.9× at a 1M context length. We also improve GLM-5.2’s MTP layer for speculative decoding, increasing the acceptance length by up to 20%
Pure Open: An MIT open-source license — no regional limits, technical access without borders
Supporting long-horizon tasks starts with making long context engineering-usable: the model must maintain quality across long, messy coding-agent trajectories, not just accept more tokens. A 1M context is easy to claim, but much harder to keep reliable under real engineering pressure. To this end, we substantially…
IndexShare works by reusing the same indexer across every four sparse attentionThe mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.Full definition → layers rather than running one per layer — the specific technique behind GLM-5.2's 2.9x FLOPs reduction at 1M-token context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition →.
The improved multi-token-prediction layer for speculative decodingA speed trick where a small model drafts several tokens ahead and the big model verifies them in one pass, often doubling generation speed.Full definition → raises GLM-5.2's token acceptance length by up to 20%.
On the FrontierSWE long-horizon benchmark, GLM-5.2 trails Opus 4.8 by just 1%, edges out GPT-5.5 by 1%, and beats Opus 4.7 by 11%.
On PostTrainBench, where each AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → gets one H100 GPU to improve a small model via post-training, GLM-5.2 beats both Opus 4.7 and GPT-5.5, ranking second only to Opus 4.8.
On SWE-Marathon, an ultra-long-horizon benchmark covering tasks like building compilers and optimizing kernels, GLM-5.2 trails Opus 4.8 by 13% — its widest benchmark gap, suggesting more room to grow at extreme task lengths.
Terms in this piece · Glossary
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
speculative decoding — A speed trick where a small model drafts several tokens ahead and the big model verifies them in one pass, often doubling generation speed.
Why it matters
GLM-5.2 ships with a genuinely usable 1M-token context for long coding-agent trajectories, an IndexShare attention scheme cutting per-token FLOPs 2.9x at that length, faster speculative decoding, and an unrestricted MIT license.


 Read the full post on X ↗