Mercury Coder adds apply-edit at a claimed 46x GPT-5 speed
- Source
- x.com
- Date

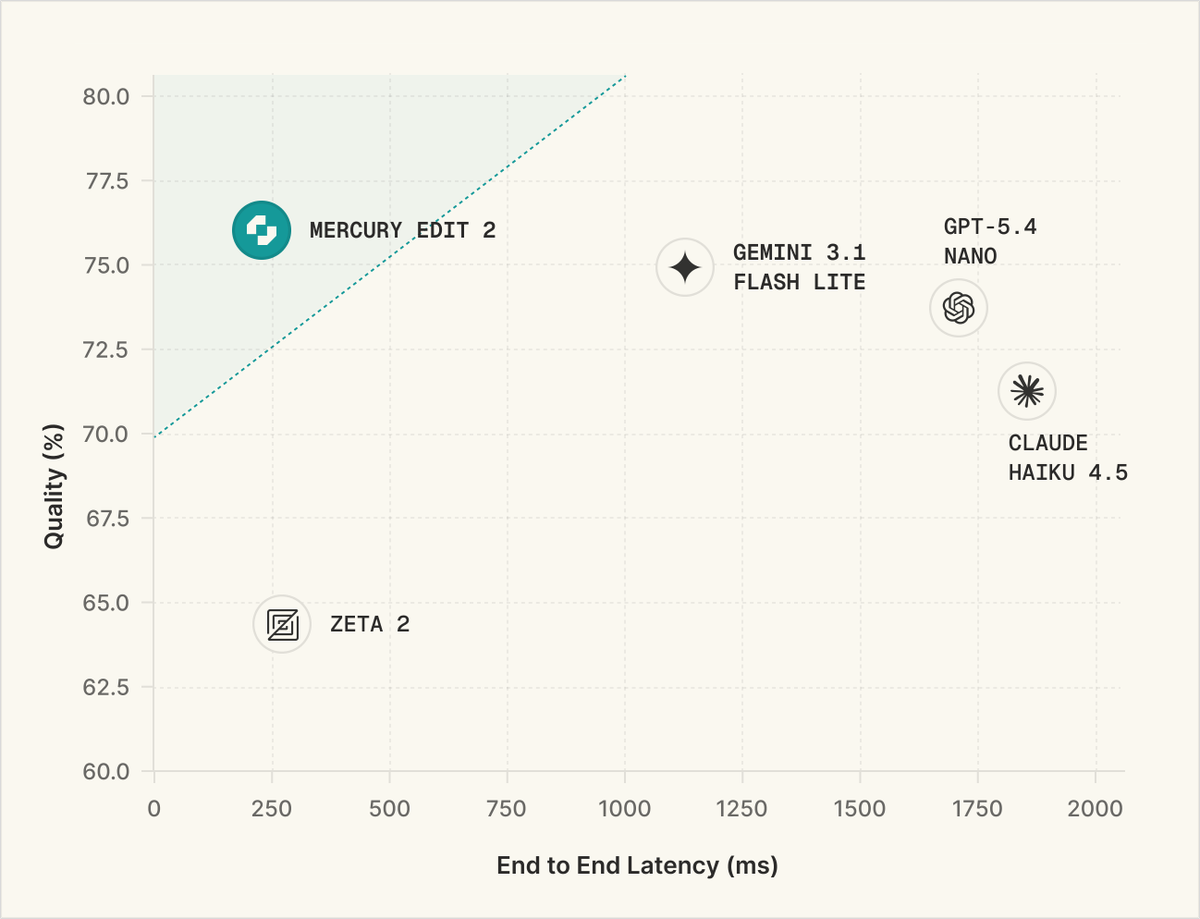
Mercury Coder now supports Apply-Edit capabilities, providing quality on par with GPT-5 at speeds 46x faster!

Apply-Edit entails integrating suggested code changes into existing code. With its diffusion-based, parallel generation process, Mercury Coder strictly dominates both frontier LLMs and specialized Apply-Edit models in speed, quality, and cost.

You can use Mercury Coder’s Apply-Edit functionality immediately through the @continuedev extension on VS Code. Apply-Edit is also available through the Inception Platform: https://t.co/8163kehKqi #dLLM #InceptionAI #ApplyEdit
@continuedev For more info, check out our blog: https://t.co/ZhmE5jThMR
Context
Mercury Coder's Apply-Edit capability handles a specific step in AI-assisted programming: merging a proposed change into an existing file. Inception describes sending the original code and an update snippet, then receiving the integrated file. It reports that the model applied edits correctly 92% of the time on a standardized dataset from Kortix AI, in line with frontier models such as OpenAI's GPT-5, and its post puts Mercury Coder's speed at 46 times GPT-5's, with a throughput chart measured in per second. These are the company's own figures, and they concern applying already-proposed edits, so they do not establish a 46-fold improvement in designing software or completing an entire coding task. Apply-Edit explanation and results
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
 postInception ships Mercury Decide update with ZDR and 66k context
 postInception launches Mercury Voice, a diffusion LLM for low-latency voice agents
 postToday, we’re introducing Mercury 2.5, the most capable diffusion LLM on the…
 postInception ships Mercury 2.5 Preview at roughly 1,100 tokens per second
Checking sign-in…
Loading comments…