Mercury Edit 2 claims the next-edit quality lead at 221ms
- Source
- x.com
- Date

Introducing Mercury Edit 2: highest quality next-edit model at the lowest latency. 75.6% quality at 221ms. Beats Zeta 2 (64.4%), Claude 4.5 Haiku (71.4%), GPT-5.4 Nano (73.5%). +48% accept rate. -27% shown rate.
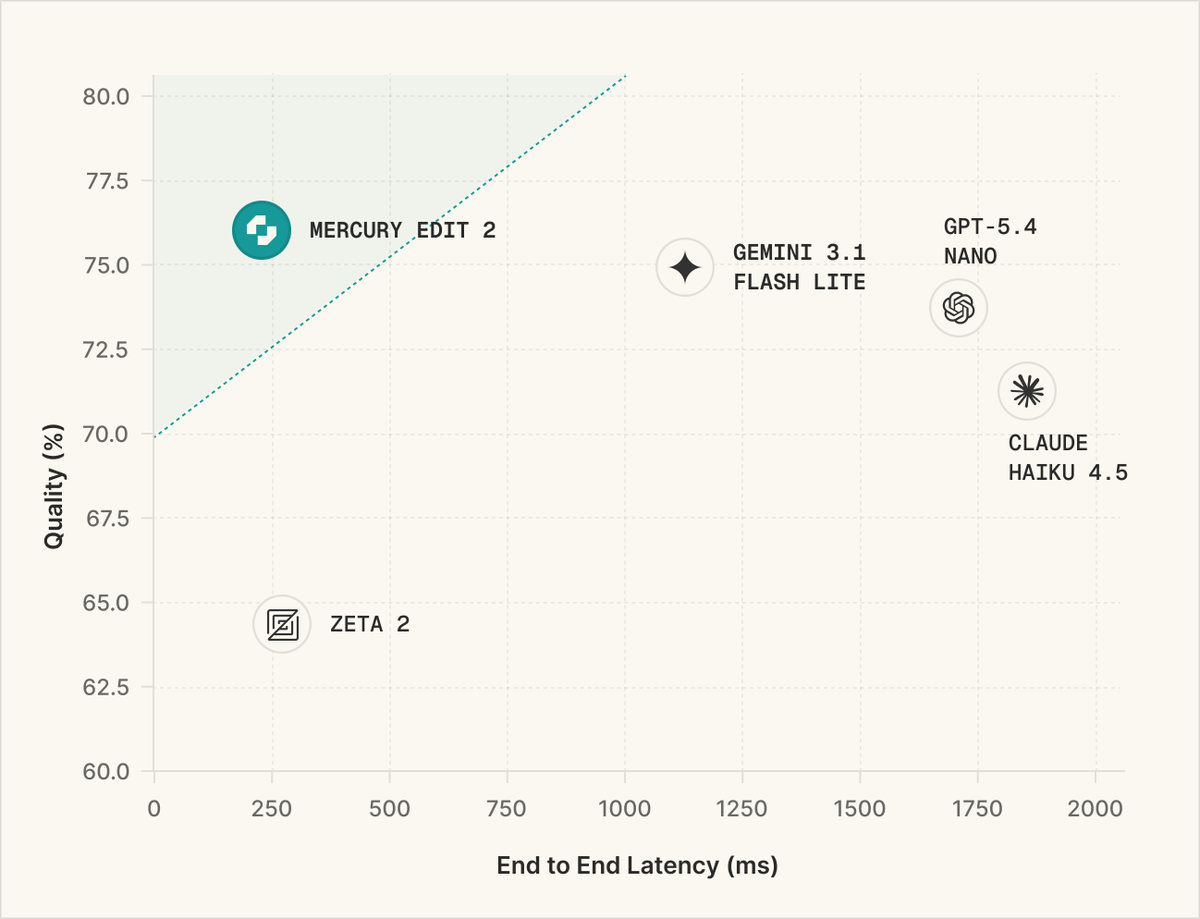
@zeddotdev Fewer suggestions, higher signal. Zed users: try Mercury Edit 2 free for 1 month with this API key: sk_ae471146ea60fc117c131b574b00ba96

Context
Inception's Mercury Edit 2 predicts a programmer's next change from recent edits and code . Its announcement reports 75.6% quality at 221 milliseconds of response latency. The methodology gives that percentage a specific meaning: it averages four editing benchmarks. One checks modified code by running tests; three use another to judge similarity to human-written reference edits. The score therefore measures performance across that test suite, rather than the percentage of suggestions developers accept or the proportion of real projects edited correctly.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
 postInception ships Mercury Decide update with ZDR and 66k context
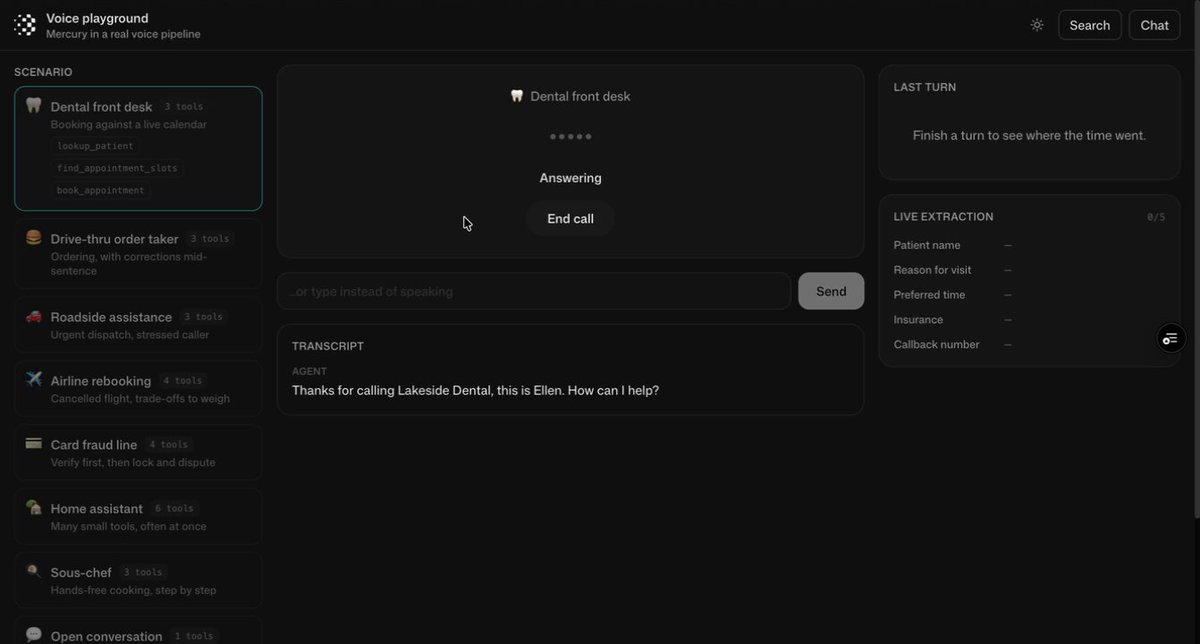 postInception launches Mercury Voice, a diffusion LLM for low-latency voice agents
 postToday, we’re introducing Mercury 2.5, the most capable diffusion LLM on the…
 postInception ships Mercury 2.5 Preview at roughly 1,100 tokens per second
Checking sign-in…
Loading comments…