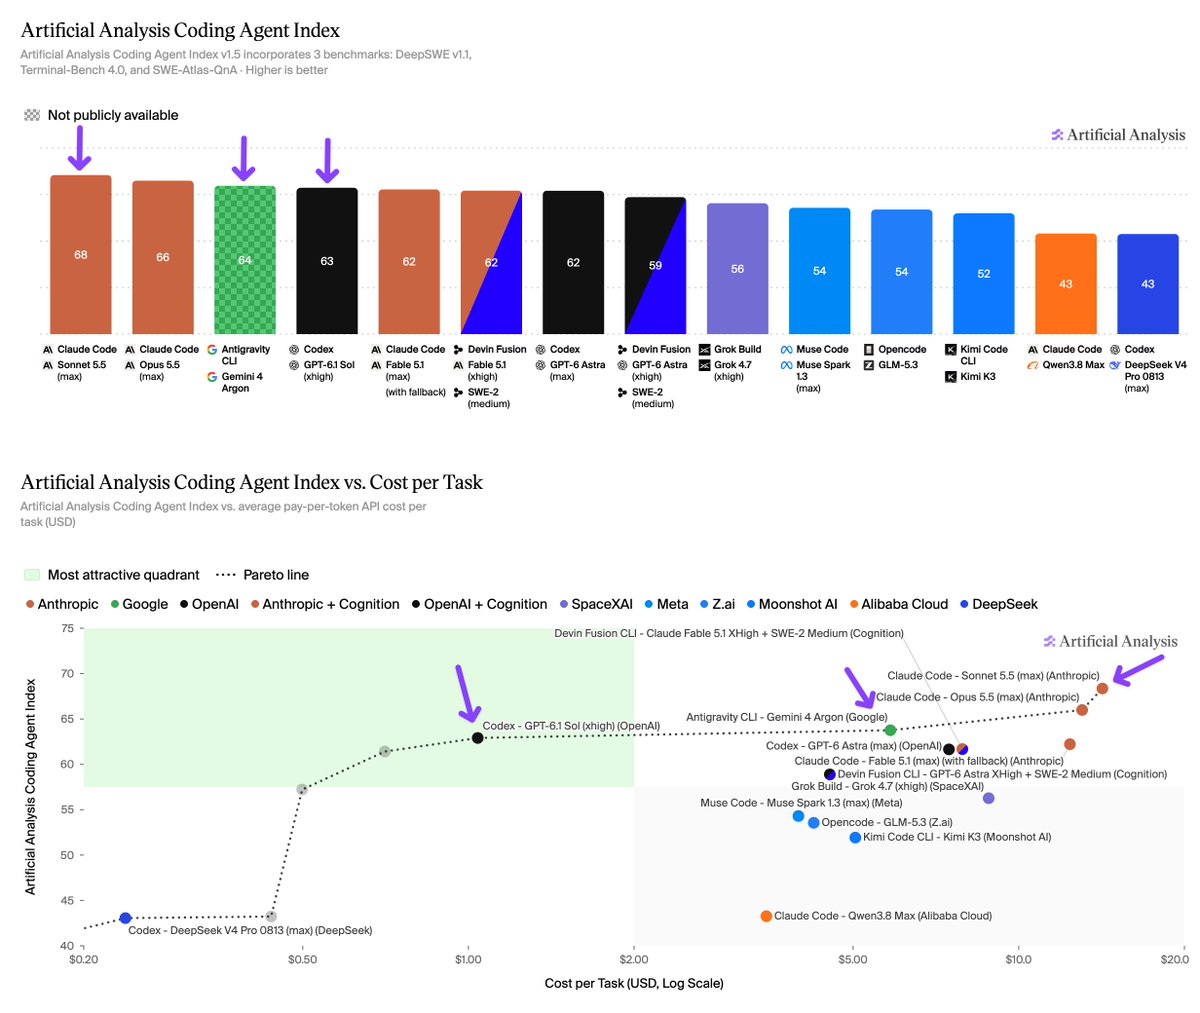
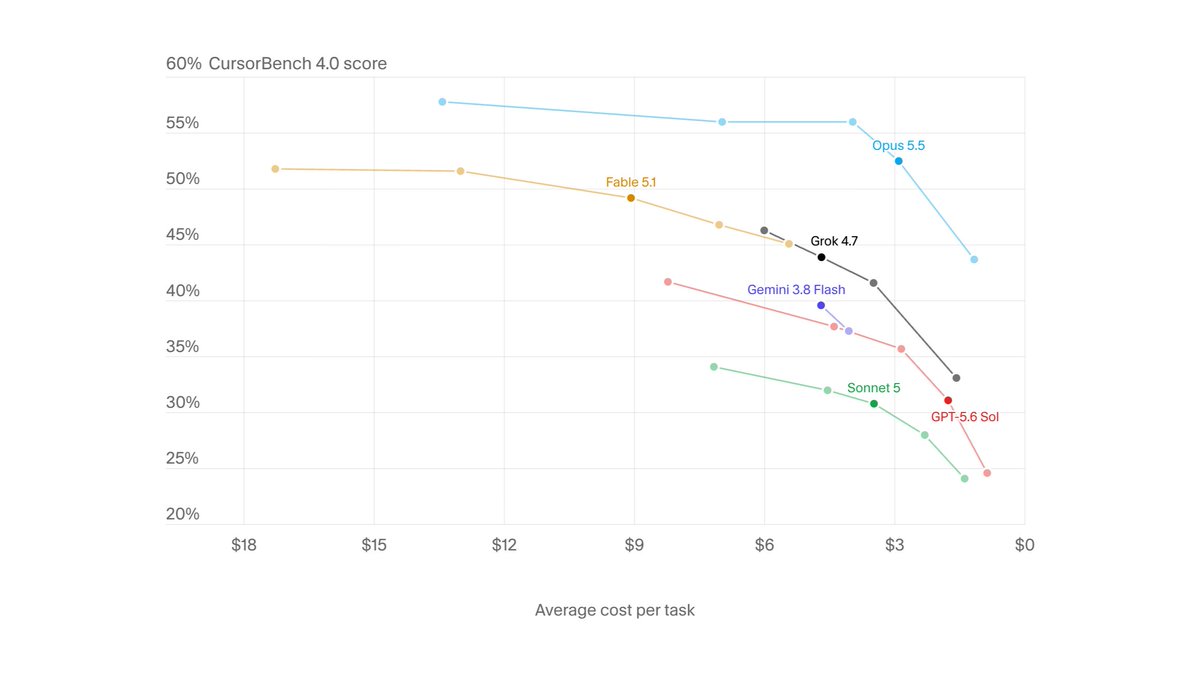
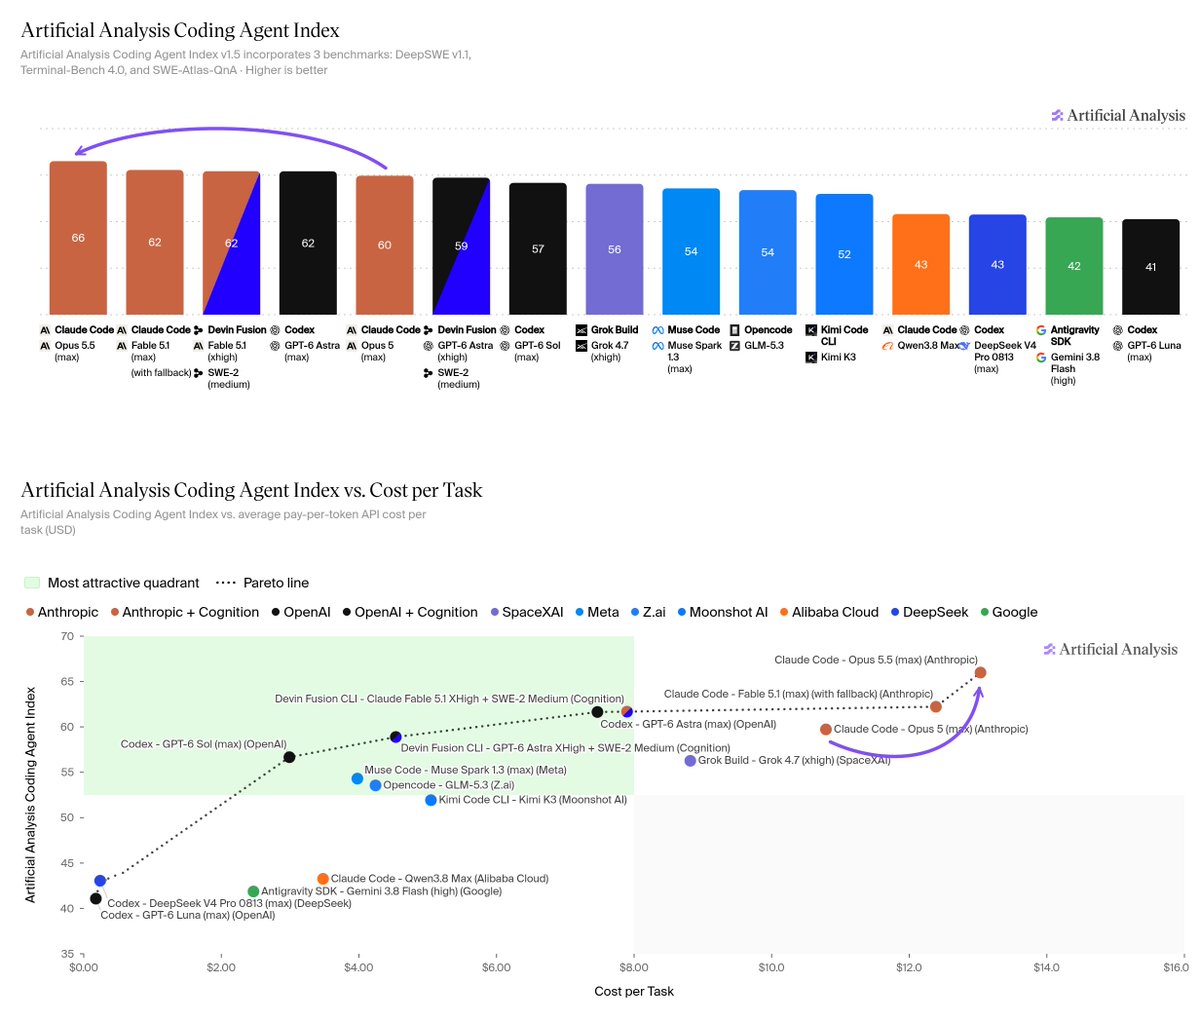
Composer 2.5 scores 62 at $0.07 to $0.44 per task, close to Claude Code and Codex at roughly 10 to 60 times the cost.
Key takeaways · AI-distilled
Composer 2.5 scores 62 on the Coding AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → Index, 14 points above Composer 2, behind only Claude Opus 4.7 (max) in Claude Code at 66 and GPT-5.5 (xhigh) in Codex at 65, which cost $4.10 and $4.82 per task.
The largest gain is on SWE-benchThe standard benchmark for AI coding agents: real GitHub issues from real repositories, scored by whether the agent's patch passes the project's own tests.Full definition →-Pro-Hard-AA, from 12% to 47%, comparable to Claude Opus 4.7 (max) in Claude Code; Terminal-Bench v2 rose 2 points to 66% and SWE-Atlas-QnA 3 points to 72%.
Composer 2.5 Fast runs about 30% faster than standard (6.7 vs 9.3 minutes per task) at about 6x the per-task cost, matching Cursor's 6x tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → pricing of $3.00/$15.00 versus $0.50/$2.50 per million tokens.
Composer 2.5 continues training on Moonshot AI's open-weights Kimi K2.5, with Cursor reporting about 85% of total compute from its own training and RL. It is available only in Cursor's IDE and CLI, with no external API.
Terms in this piece · Glossary
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
SWE-bench — The standard benchmark for AI coding agents: real GitHub issues from real repositories, scored by whether the agent's patch passes the project's own tests.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.