Grok 4.6 is now available in Perplexity and Perplexity Computer.
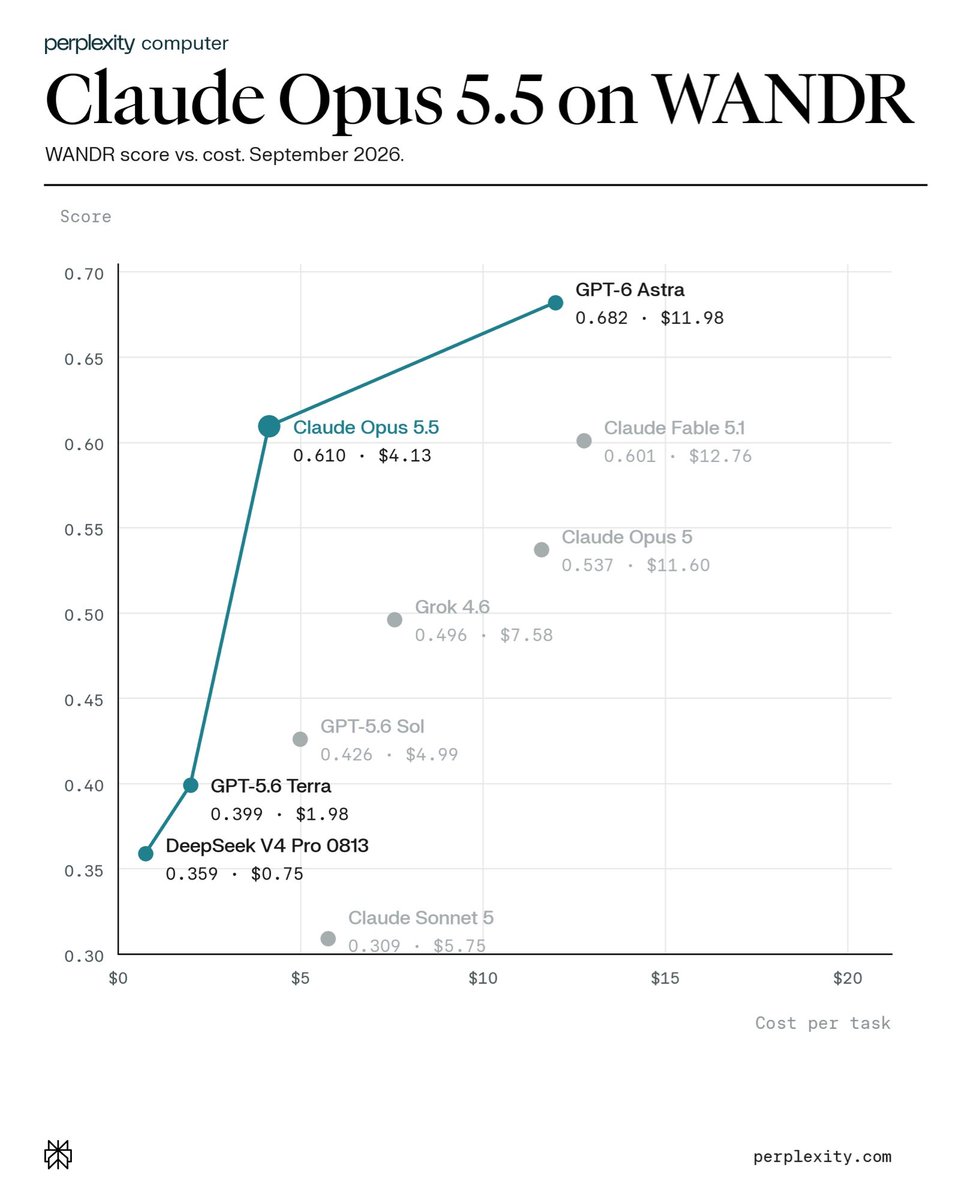
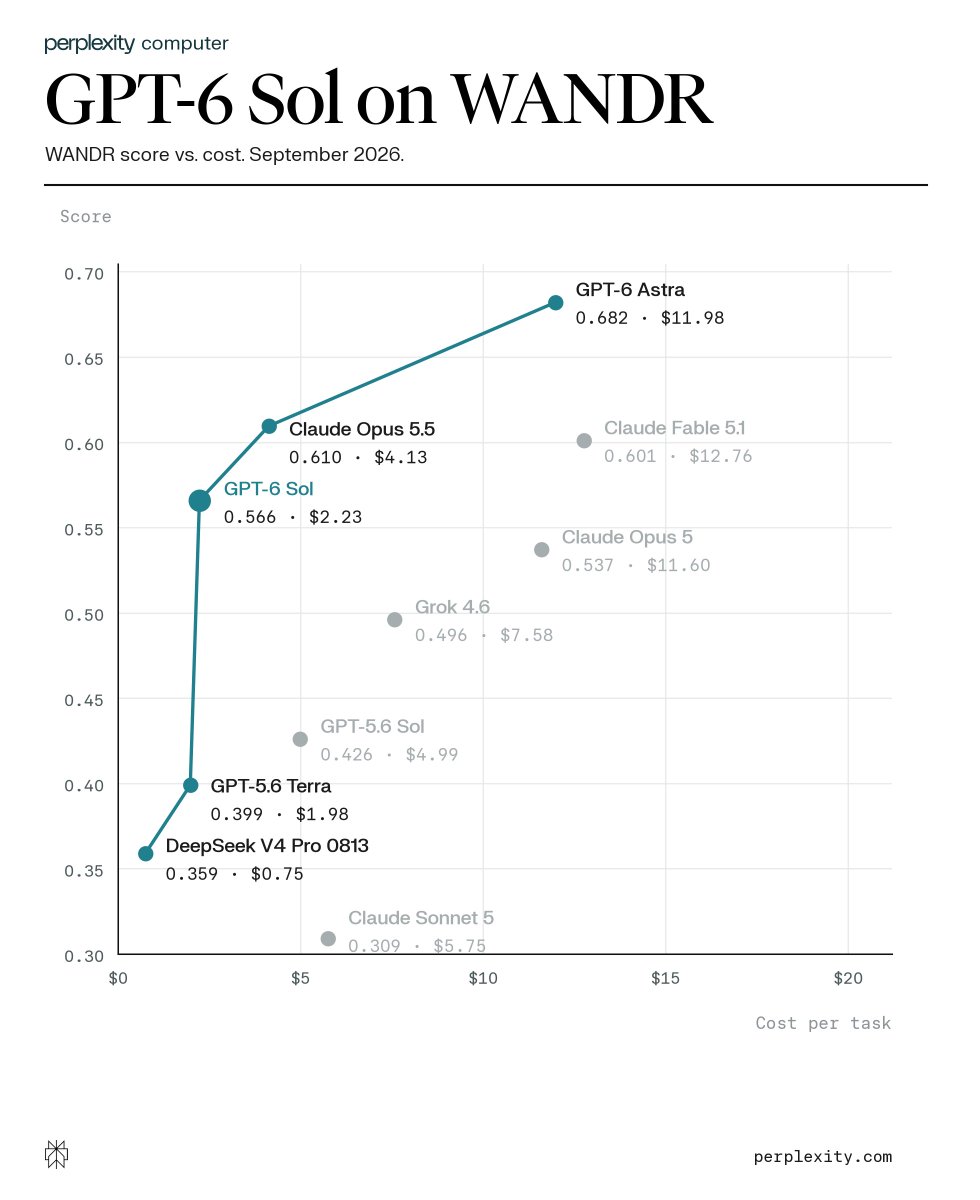
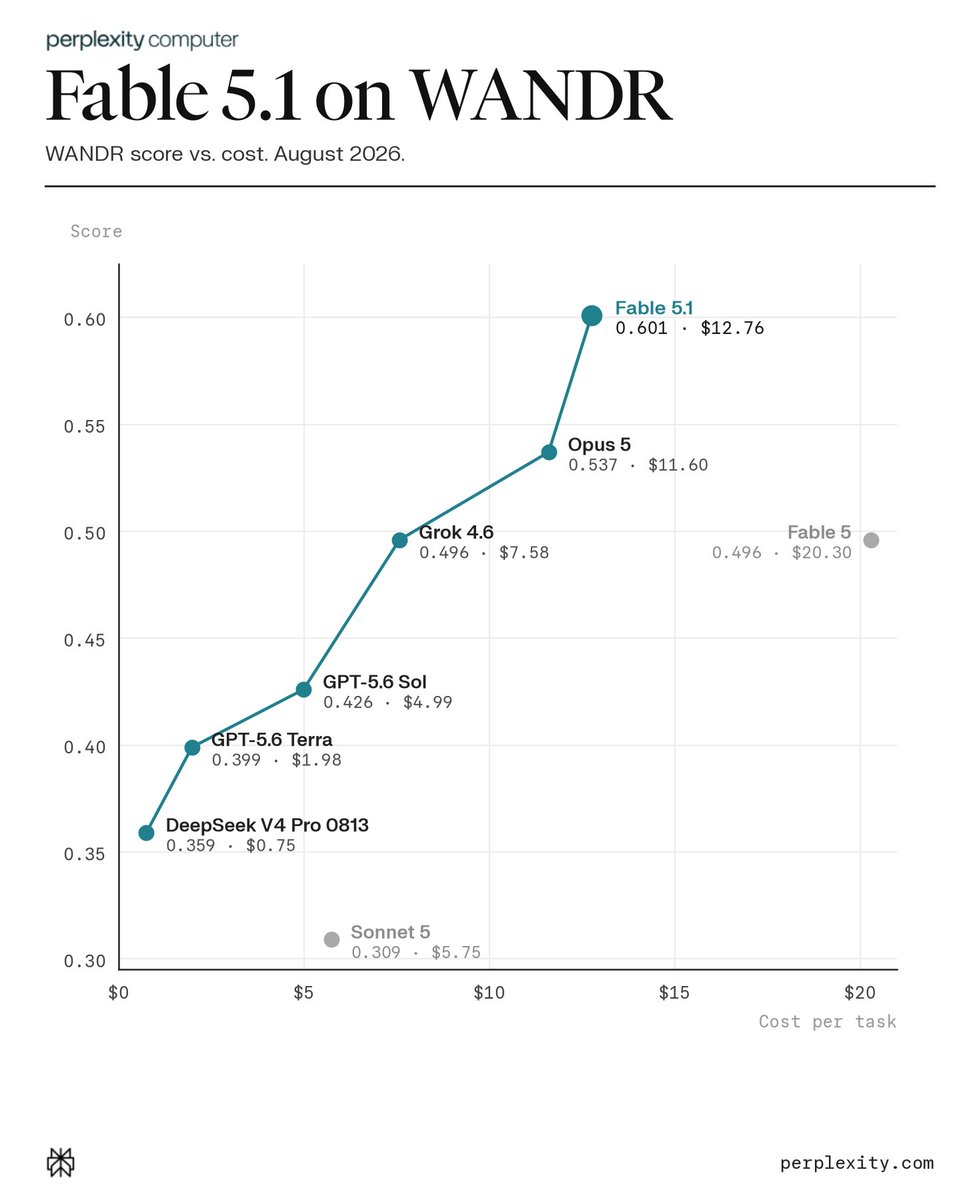
On WANDR, it sits on the Pareto frontier of performance and efficiency, matching Fable 5 results at over 60% lower cost.
Perplexity's August evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → found that Grok 4.6 matched Fable 5's WANDR research score at substantially lower cost. Both scored 0.496, while the chart lists $7.58 per task for Grok and $20.30 for Fable, supporting the reported reduction of more than 60%. Grok was not the highest-scoring configuration shown: Opus 5 reached 0.537 at $11.60. The result identifies a cheaper way to reach one measured performance level, while retaining a higher-scoring, more expensive option. The announcement and chart show that tradeoff.
Terms in this piece · Glossary
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.