Mercury refresh claims 5x Haiku speed at a quarter the price
- Source
- x.com
- Date

Mercury is refreshed – with across-the-board improvements in coding, instruction following, math, and knowledge recall. Start building responsive, in-the-flow AI solutions! Read more: https://t.co/QyTVaHAIue

Mercury runs five times faster than Claude 4.5 Haiku at less than one-fourth the price, while maintaining higher quality.

Context
Inception's November 2025 Mercury refresh combined a diffusion-based with changes to training and serving. The model generates blocks of text through repeated refinement, providing a mechanism for parallel generation. In its release account, the company claimed roughly one-fifth the response latency and less than one-quarter the price of Anthropic's Claude Haiku 4.5.
The comparison needs its settings: the supplied chart plots end-to-end latency against an average of five benchmarks. Mercury scores above Haiku without reasoning in that chart, while Haiku's reasoning setting scores higher and takes longer. The claim therefore concerns a particular quality–latency comparison from that release.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
 postInception ships Mercury Decide update with ZDR and 66k context
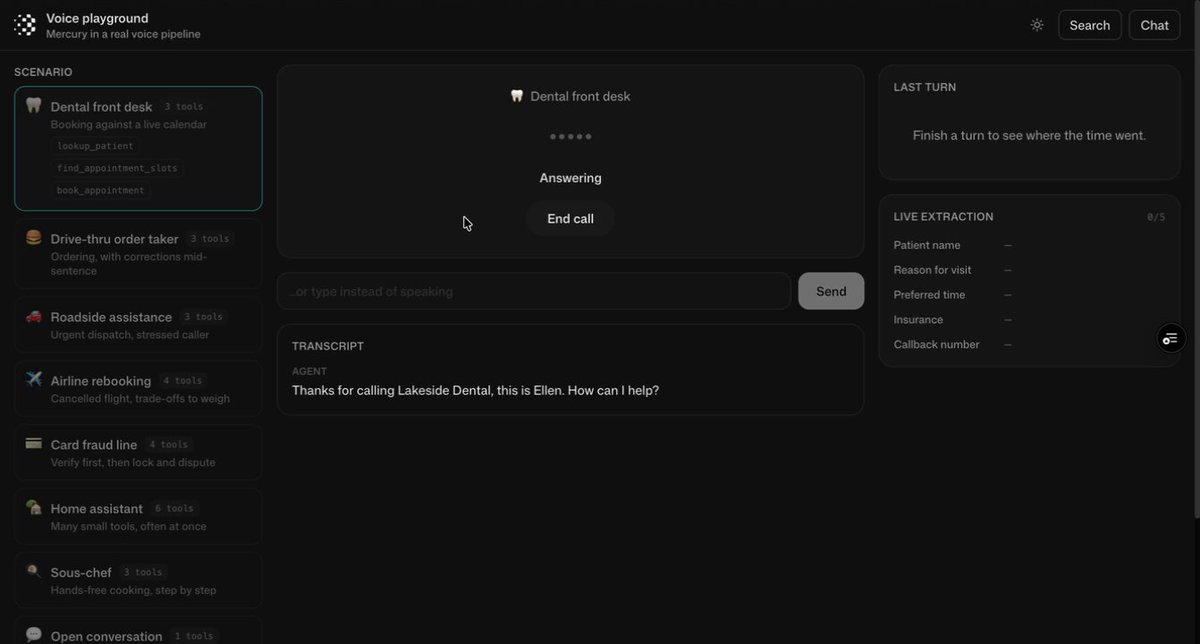 postInception launches Mercury Voice, a diffusion LLM for low-latency voice agents
 postToday, we’re introducing Mercury 2.5, the most capable diffusion LLM on the…
 postInception ships Mercury 2.5 Preview at roughly 1,100 tokens per second
Checking sign-in…
Loading comments…