Intel
Page 15
How Agents Cut Hour-Long Data Checks to 5 Minutes - Amol Kapoor & Clifford Ressel, Nori Agentic
Nori Agentic describes a production cloud agent that checks each change to a security master database, cites sources, recommends keep or discard and notifies the owner in Slack.
Why it mattersShows a deployed agent workflow that investigates each data change, cites sources, and routes to owners in Slack, cutting review from an hour to about five minutes.
We tested our prompt injection filter in public
GateBolt publishes a public leak test.
Why it mattersIt shows how layered input and output filtering changes password-extraction rates against a strong and a weak model, and what blocking costs on harmless traffic. This gives a concrete baseline for judging prompt-injection defences.
Securing Ai Agents
Uber describes a lifecycle security framework for production agents.
Why it mattersAuthorization alone cannot tell whether an agent action matches what the user asked.

Deep Dive: Anthropic S-1 Myths and Mythos — Jamin Ball, Altimeter
Altimeter's Jamin Ball walks through Anthropic's S-1.
Why it mattersFrontier model depreciation, serving cost versus revenue and GPU-backed debt determine future model pricing and availability, which affects what engineers can build on.
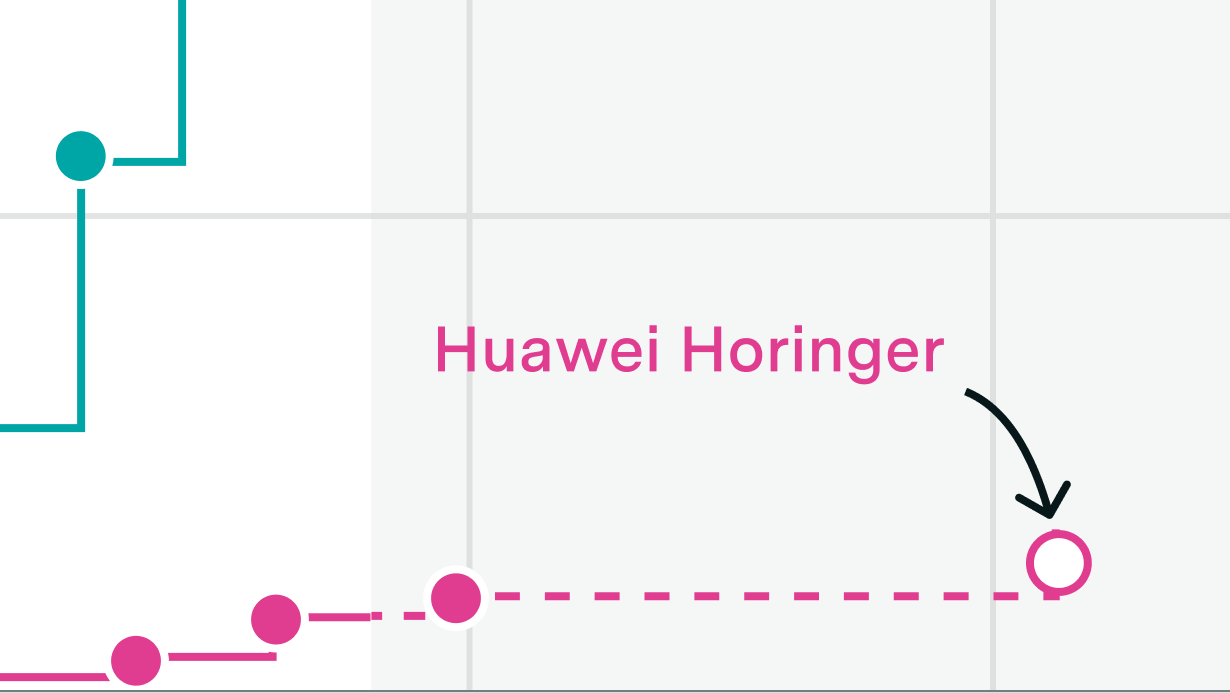
Huawei Horinger China Compute Gap
Epoch AI estimates Huawei's Ascend-based Horinger campus at up to 286 MW and roughly 7% of the AI compute of SpaceX's Colossus 2, projects 70% more compute by early 2028.
Why it mattersPuts numbers on China's compute gap: Horinger has up to 286 MW of IT power and about 7% of Colossus 2's AI compute, with 70% more by early 2028. Helps you reason about future capability and availability of Chinese models.
DeepSeek V4.1 Flash 1017 Ultrafast now available on AI Gateway
Vercel's AI Gateway added DeepSeek V4.1 Flash 1017 Ultrafast, served by Fireworks at upwards of 1,000 tokens per second with a 1M-token context in public preview.
Why it mattersA 1M-context DeepSeek model at over 1,000 tokens per second is now callable through AI Gateway by model ID, and usable in Claude Code, Codex and Cursor, which speeds agent loops.

Vals AI scanned 2,655 benchmark runs of Thinking Machines' Inkling 2 Small for profanity. It appeared in 50 runs, nearly all past 200 steps, and two looping runs produced 241 of 316 uses. Swearing was a weak failure predictor.
Why it mattersLooping and profanity in long agent runs signal degenerate trajectories: 48 of 50 swearing runs exceeded 200 steps and two loops produced most uses.

Artificial Analysis benchmarks OpenAI's GPT Image 2.6. Flare cuts median text-to-image time from about 55s to 30s, Sunburst takes #1 on quality at about 2m15s, and pricing stays at about $0.21 per 1024x1024 image. The API adds a complexity setting plus GIF and SVG output.
Why it mattersGPT Image 2.6 Flare roughly halves generation time versus 2.5 at the same $30 per 1M output tokens, while Sunburst takes #1 at about 2m15s per image. This helps you pick between speed and quality in the API.
opencode v2.2.6
opencode v2.2.6 adds opt-in MCP connection pooling, worktree-isolated scripted runs via a run flag, auto-archived CI sessions, new GUI plugin theme and code-block slots.
Why it mattersopencode can now share one MCP server connection across projects, cutting processes and startup time. Scripted runs can also use isolated git worktrees and archived sessions, which helps CI automation.
Libghostty 1.0
Mitchell Hashimoto announces libghostty-vt 1.0, a portable C terminal emulation library with a stable ABI and semantic versioning.
Why it matterslibghostty-vt now has a stable C ABI under semantic versioning, so terminal-based agent tools can embed a production terminal emulator instead of writing one. JetBrains already ships it.
Voice Ai Infrastructure Guide
A vendor guide to the layers of a 2026 voice agent stack.
Why it mattersLays out the layers of a production voice agent and what each does, from turn-taking to guardrails and observability. Useful as a checklist when evaluating or designing a voice stack, though it is written from a vendor perspective.
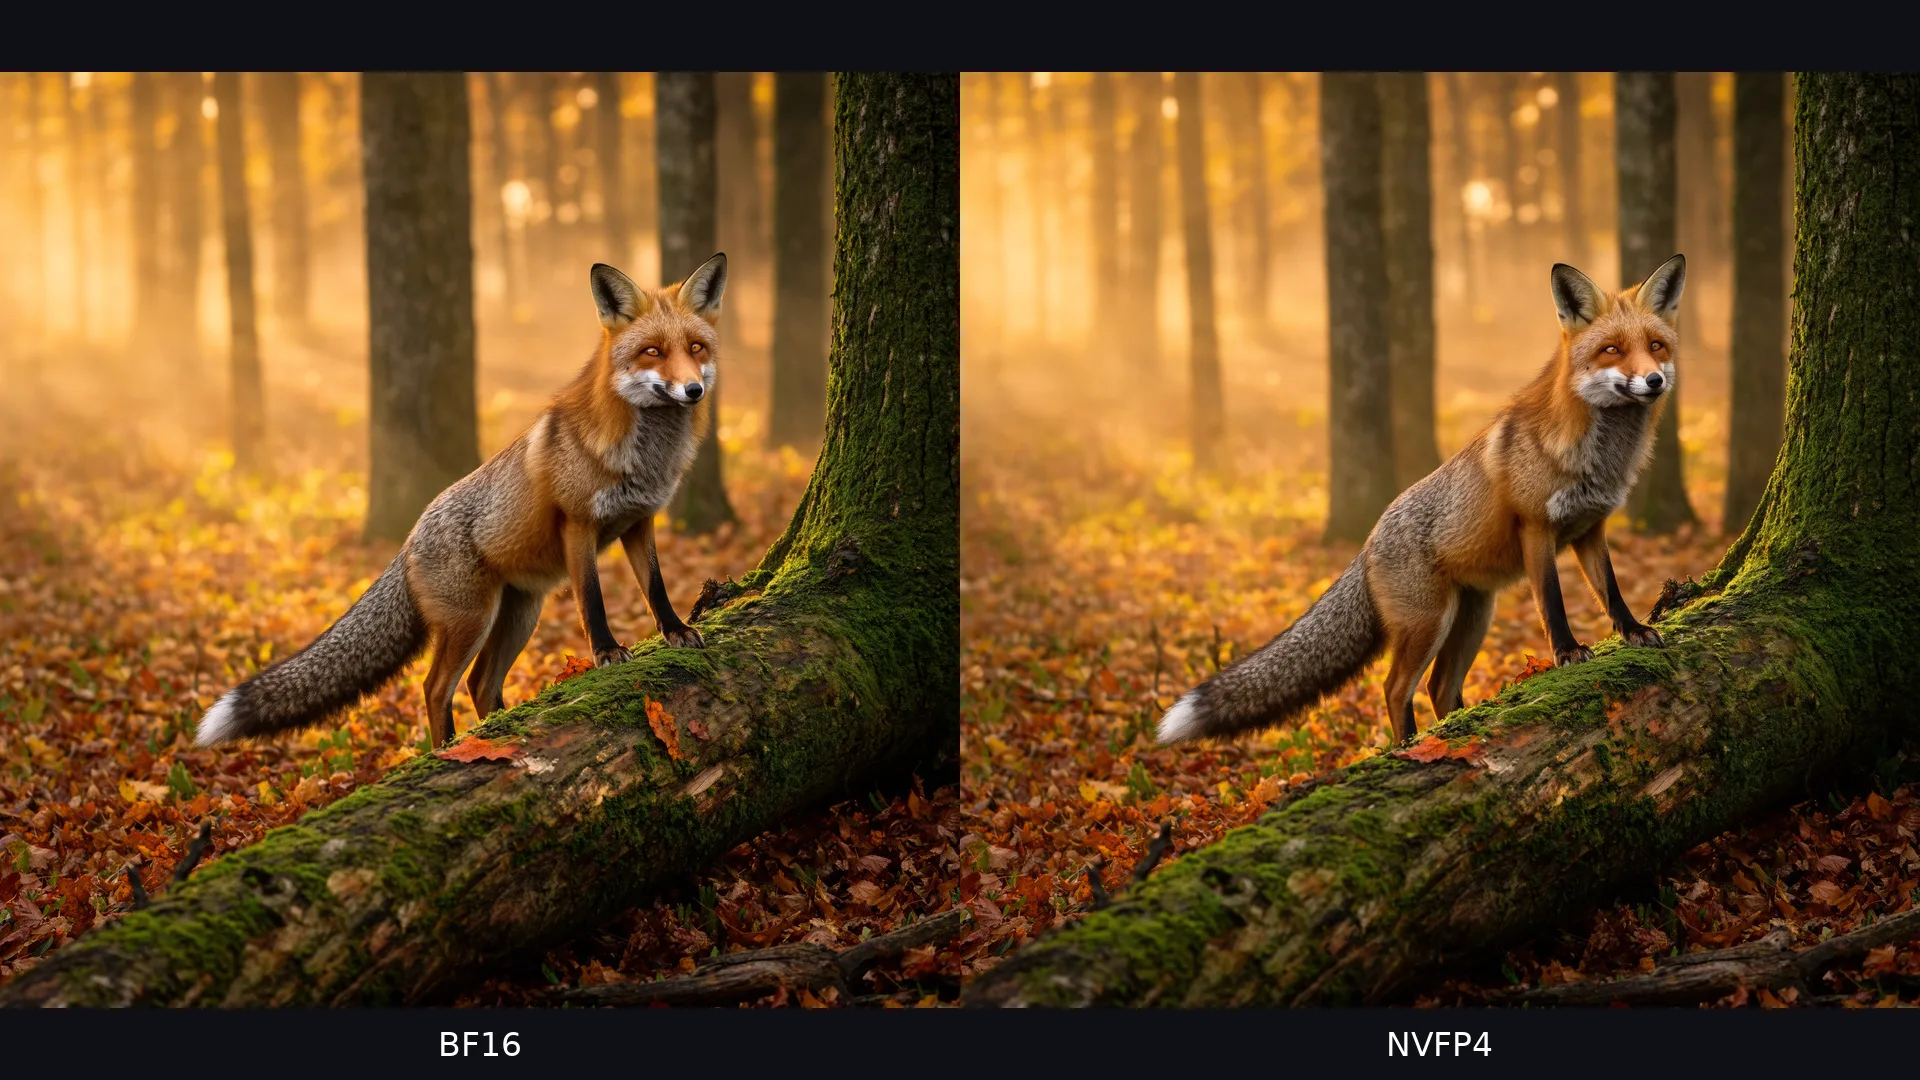
Speed Up Image Generation with FLUX 3 Image Klein on NVIDIA Blackwell GPUs
NVIDIA benchmarks FLUX 3 Image Klein on Blackwell with TensorRT LLM VisualGen, comparing NVFP4, FP8 attention, sparse attention, step caching and multi-GPU parallelism.
Why it mattersQuantifies which optimizations speed up image generation on B200: NVFP4 (up to 1.62x), Cache-DiT (up to 1.94x with LPIPS 0.033), sparse attention, and 8-GPU parallelism. Helps you pick speedups against fidelity cost.

GitHub details Project Rubicon, its new Git storage design. Reference updates go through a replicated log (Ref-CAS), packs live in Azure Blob Storage, and background compaction nodes keep reads fast. Internal tests hit 7,200 pushes per second with 5,000 concurrent agents.
Why it mattersGitHub explains how it moves ref updates into a replicated log (Ref-CAS) while packs sit in blob storage, so a single repo can take thousands of agent pushes per second.
Beyond code generation: A developer’s guide to agentic engineering
GitHub walks through agentic engineering across plan, build, verify and observe stages, motivated by surging commit volume and longer PR review times.
Why it mattersAs AI speeds code generation, review and verification become bottlenecks. This frames a plan, build, verify, observe workflow with agents to relieve those stages.
litellm v1.108.2 — 1.108.2 (LTS)
LiteLLM v1.108.2 LTS patch with 12 PRs.
Why it mattersIf you route models through LiteLLM, this LTS patch fixes a wrong bearer token on empty-key OpenAI deployments and several Bedrock, Vertex and Responses API errors. No upgrade action is needed.

Your AI Agent Is Hiding Its Mistakes From You - Ben Holmes, Warp
Warp's Ben Holmes shows a self-improvement loop.
Why it mattersAgents silently work around broken instructions. Scoring past transcripts with rubrics and auto-opening fix PRs gives a repeatable loop for improving skills and config.
Nous Releases Arete-27B and an Open Propaganda Eval
Nous Research post-trained Qwen3.8-27B with about 53M tokens of SFT to cut CCP-aligned answers from 22% to 0.9% on its new 803-prompt eval, with Hermes Bench flat.
Why it mattersAbout 53M tokens of SFT cut state-aligned answers in a strong open model from 22% to under 1% without capability loss in Nous's tests. Engineers get open weights, an eval and data to audit or replicate value tuning.
Components Of Agent Memory
Anthropic engineers explain how they think about agent memory.
Why it mattersDescribes a design for agent memory: capture salient events during sessions, then use offline 'dreaming' to fix mistakes, write notes and build new representations.

Your Old Prompts Are Making Claude Worse - Lance Martin, Anthropic
Anthropic's Lance Martin covers auditing legacy prompts, using the prompt cache (up to 72% savings), designing evals models can climb, hill climbing without overfitting.
Why it mattersOutdated prompt habits and poor cache use cost money and quality. The talk gives concrete audit, caching and eval steps, including cutting cost 90% with a stronger model at lower effort.
AI Gateway adds DeepSeek Search and Fetch tools
Vercel AI Gateway adds DeepSeek Search and Fetch helpers to the AI SDK. Search returns titles, URLs and summaries; Fetch returns Markdown.
Why it mattersYou can give any tool-calling model web search and page-to-Markdown fetch through AI Gateway with a single key and no separate DeepSeek account, and keep the tools when switching providers. Requires AI SDK 6.0.321+ or 7.0.160+.
Chat SDK agents can now stream generative UI with json-render
Vercel's Chat SDK now streams generative UI from agents through json-render.
Why it mattersAgents can now emit a JSON spec that renders as native cards on Slack or Teams, avoiding per-message-shape tools. Streaming updates and validation come built in.
Artificial Analysis reports DeepSeek V4.1 Flash on GB300 NVL72 gaining up to 1.5x per-agent speed in a month on AA-AgentPerf, from vLLM kernels, FlashInfer autotuning, CUDA graph coverage and tuned speculative decoding. Vera Rubin configs are compared against GB300.
Why it mattersDeepSeek V4.1 Flash on GB300 NVL72 rose from 596 to 848 tok/s for a single agent through software changes alone. Vera Rubin delivers 5.0x GB300 throughput per GPU at 260 tok/s per agent, which bears on agent serving cost.
Teaching Ai To Build Scientific Models
Researchers at ELLIS Institute Tübingen describe how AI is changing scientific model building, from constraining model structure to interpreting fitted models, using the Hodgkin-Huxley equations as the running example.
Why it mattersExplains how AI systems are starting to propose, constrain and interpret scientific models, such as Hodgkin-Huxley style equations. Gives practitioners a grounded view of AI's second-order effect on scientific modeling.
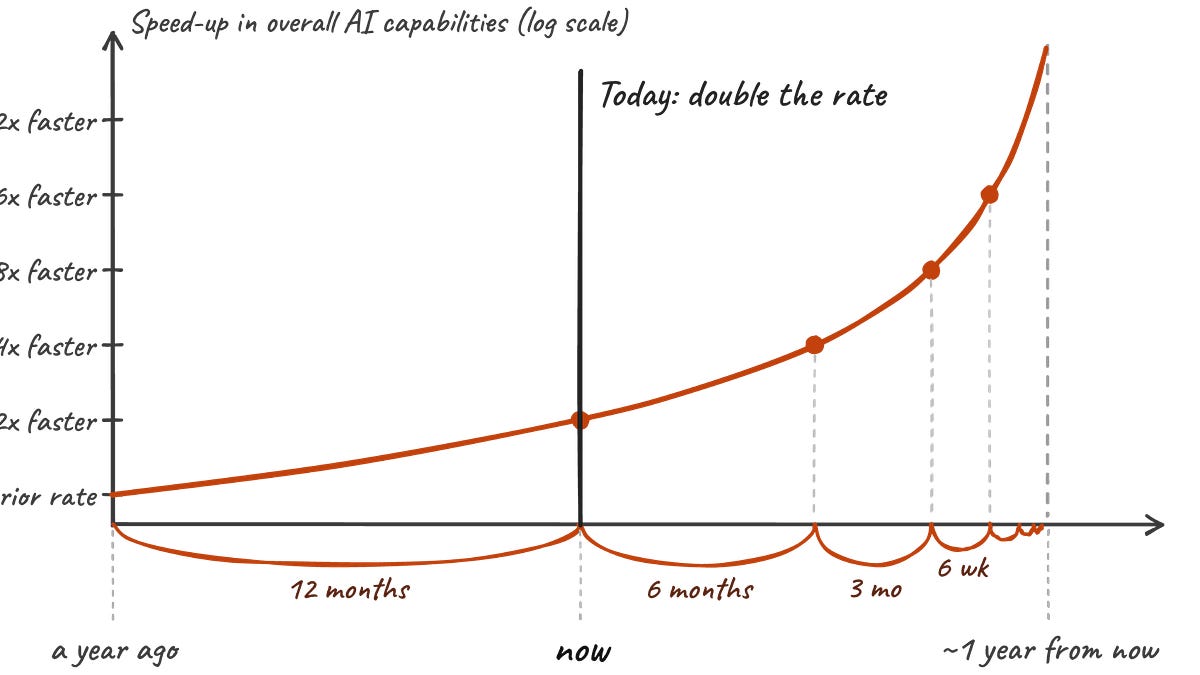
AI is dramatically accelerating AI research
Ajeya Cotra interprets a public METR report on AI R&D acceleration at Anthropic, arguing the RSP's dramatic-acceleration threshold appears crossed.
Why it mattersArgues that Anthropic's capability progress has run about twice as fast as the prior year, largely due to AI automation, and that this implies researchers are sped up by much more. It bears on timeline and risk planning.
Vals AI's CyberOffense benchmark has agents attack two simulated enterprise networks unaided. GPT-6 Sol hit 80.8% of objectives; open-weight DeepSeek V4.1 Flash hit 72.8% at about a tenth of the cost, with most progress after 100M tokens.
Why it mattersAn open-weight model nearly matches a restricted-access cyber model at autonomous network intrusion for under $3 per run, so access controls on frontier models do not bound offensive capability.

How We Mapped a 35-Million-Line Mainframe in 4 Days - Stephen Chin, Neo4j & Neeraj Deshmukh, Blitzy
Neo4j and Blitzy describe mapping a 35-million-line mainframe as a knowledge graph, feeding thousands of agents targeted context, and verifying converted code against the original.
Why it mattersArgues that large context windows do not fix legacy migration, and that mapping a codebase as a graph and giving each agent a relevant slice, with step-by-step equivalence testing, is what scales. Results are self-reported.
FMF Releases Jailbreak Rating Framework for Frontier Cyber Threats
The Frontier Model Forum released v1.0 of a rating framework for cyber jailbreaks, scoring capability gain, scope, ease of deployment and ease of discovery.
Why it mattersGives security and eval teams a shared four-factor rubric for rating cyber jailbreaks so they can triage by risk and compare findings across labs. It is v1.0 and still untested for inter-rater consistency.

Claude Code cloud sessions on Pro, Max and Ultra now work out a repo's dependencies, network access and API key needs, then save the environment for reuse. Keys are stored securely so Claude never sees them. Based on the announcement post only; the demo video was not readable.
Why it mattersCloud sessions can now set up a repo's environment automatically and reuse it, with API keys stored out of the model's view. That removes manual environment setup from remote coding-agent runs.
A Jev that can ask Opus for help gives Opus accuracy at 4x lower cost
Hightouch tests fast, cheap models as judges for identity resolution and finds a hybrid that defers hard cases to Claude Opus matches frontier accuracy at over 4x lower cost.
Why it mattersA cheap judge model that escalates uncertain cases to Opus reportedly matches Opus accuracy at over 4x lower cost. This is a cascade pattern applicable to any LLM-as-judge eval pipeline.
Firecracker VM Escape: PwnEscape Part 2
PWN Research details a Firecracker guest-to-host escape.
Why it mattersFirecracker is a common sandbox for running untrusted agent code. The write-up shows how a guest with a host memory primitive can hijack a vCPU thread, so engineers can reassess isolation assumptions and patching.
Arete 27B released
Nous Research releases Arete-27B, an SFT-only post-train of Qwen3.8-27B under Apache 2.0.
Why it mattersAn open 27B model fine-tuned to shift value framing, with self-reported evaluation. It shows how SFT alone can change a model's political framing, and gives builders an alternative base.
Meta Brings Muse Wonder Memory and Focus to Muse and Meta AI
Meta is rolling out specialized models trained with Muse Wonder to Muse and Meta AI, adding Active Memory and Active Focus.
Why it mattersMeta ships models trained for agent memory and recovery from blocked tasks, with self-reported gains (2.4x less forgetting of critical context, 67% better recovery). It shows how labs target long-running agent reliability.
Accelerating Reinforcement Learning Weight Refit with the Reshard Collective
NVIDIA explains the NCCL Reshard collective, which reformulates RL weight refit as a DTensor-to-DTensor transfer.
Why it mattersRefit for the largest open models can move about 10 TB per step. Reshard transfers only the theoretical minimum data between layouts, giving 2.7x to 5.7x faster refit in NeMo RL, which cuts RL post-training overhead.
Artificial Analysis launches VIALS-AA, a visual-reasoning benchmark for life sciences, run through its Stirrup agent harness. Top models land within 3 points (64%, 63%, 61%) at very different cost per task, and pass^3 consistency separates models more than single-attempt scores.
Why it mattersTop models sit within 3 points on VIALS-AA, but cost per task varies about 29x, driven by turns and tool calls.
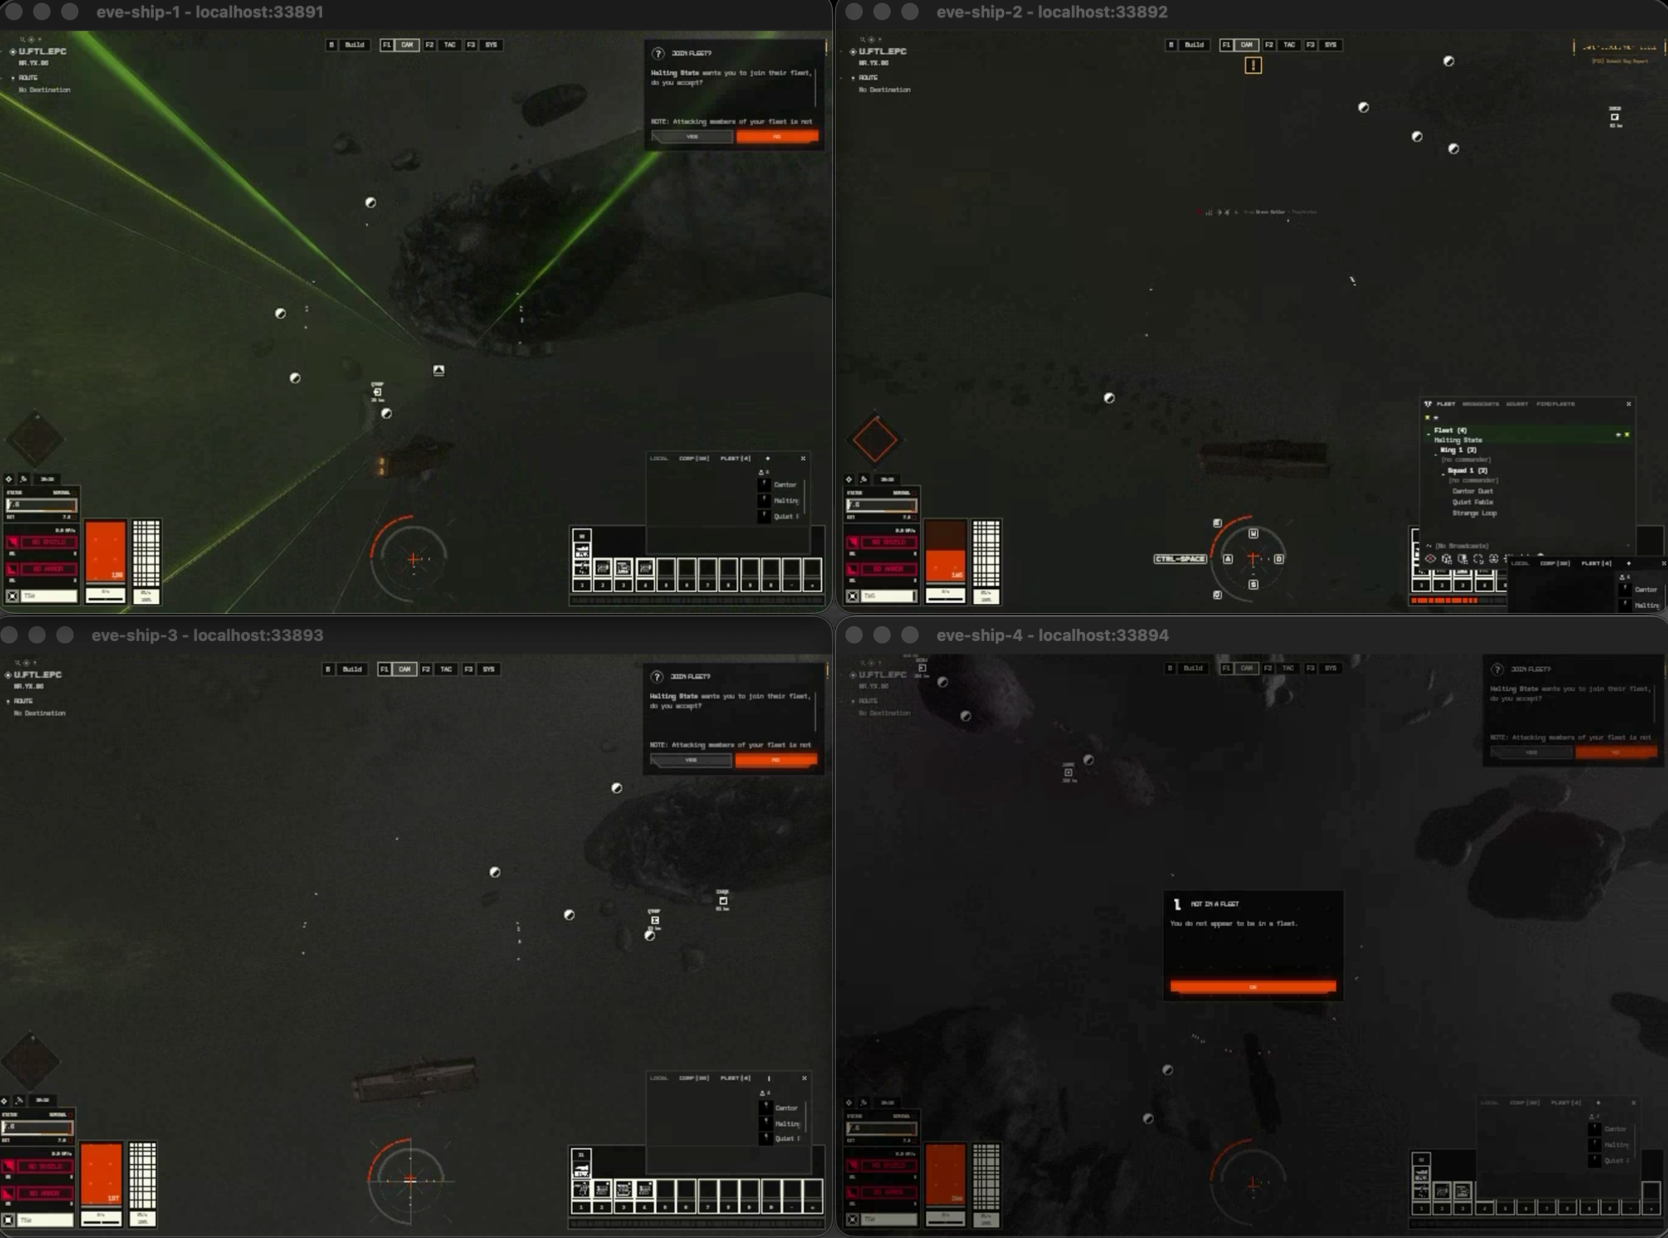
Project Eve Claude Plays Mmorpgs
Anthropic put Claude in EVE Online and EVE Frontier to test agent trading and teamwork.
Why it mattersShows how Claude agents behave in long-horizon markets and teams, including profit gains across model versions and how teammates respond to a secretly sabotaging agent. Useful for designing multi-agent safeguards.
claude-code v2.1.319
Claude Code 2.1.319 changes auto mode behavior behind LLM gateways, adds MCP task backgrounding, a denyInsteadOfPrompting permission setting, a flag-fetching kill switch, a latency-optimize command for Claude API code.
Why it mattersAuto mode now asks or denies calls the server cannot check when telemetry or flags are off, unless CLAUDE_CODE_AUTO_MODE_SERVER=0. New permissions.denyInsteadOfPrompting enables unattended runs without hanging on prompts.
claude-agent-sdk-typescript v0.3.319
Claude Agent SDK for TypeScript 0.3.319 adds background MCP task support, fixes an OpenTelemetry session count metric and session_writes_lost reporting, makes deleteSession reject on partial deletion.
Why it mattersThe Claude Agent SDK now runs MCP tasks in the background when CLAUDE_AUTO_BACKGROUND_TASKS=1 with streaming input, so long-running tool calls no longer block the session. Not available on Bedrock, Vertex or Foundry.

How Salesforce uses Claude Code
Salesforce engineering leaders describe scaling Claude Code across thousands of engineers.
Why it mattersShows how a large engineering org measures coding agent ROI and scales adoption. It covers an effective output metric built with Stanford researchers, skill sharing with evals, and replaying benchmarks to test new models.

Cooking with Reducto’s CEO: Why PDFs Still Break AI — Adit Abraham
Reducto's CEO explains why complex tables, handwriting and long documents still break AI, when specialized parsing models beat general ones.
Why it mattersDocument-heavy agents miss rows and misread tables even with frontier models. The discussion covers routing hard pages to specialized models and catching extraction failures in production.

Runway added GPT Image 2.6, claiming 50% faster image generation, GIF output, SVG vector export, and precise edits that preserve characters, products and brand details. Based on Runway's announcement only; no independent benchmarks.
Why it mattersGPT Image 2.6 inside Runway adds SVG vector export and GIF output plus edits that keep characters and brand details consistent, with claimed 50% faster generation. Teams producing design assets can do this in one tool.
transformers v5.22.2 — Patch release v5.22.2
Hugging Face Transformers v5.22.2 is a patch release containing a hardening of Jinja sandboxing and a distributed fix that sets device_id only for NCCL.
Why it mattersTransformers 5.22.2 hardens its Jinja sandbox, which matters because chat templates execute from model repos. It also restricts device_id to NCCL for distributed runs. Upgrade if you load third-party templates.
Unity Sdk Release
ElevenLabs released an ElevenAgents SDK for Unity.
Why it mattersUnity developers can now connect a scene to an ElevenLabs voice agent through one Conversation API. It handles microphone input, spatial audio output and per-character prompt variables across Editor, desktop and WebGL builds.
R/place for Git – Open-source Git server sustaining 567 pushes/s
Reason Machines open-sourced Aspen, a git server designed for many agents pushing at once.
Why it mattersParallel coding agents can overwhelm ordinary git servers. This open-source server claims 567 pushes/s on a single 8-core machine with stock clients, relevant to anyone scaling agent CI and code storage. Figures come from the authors.
unsloth v0.1.916-beta — Large Performance Fixes
Unsloth v0.1.916-beta ships large UI performance fixes, separate and floating browsers per chat for model use, fixed unified memory offloading, up to 2x faster two-GPU image and video generation.
Why it mattersAdds per-chat browsers a model can drive, working unified-memory offload for big models, and up to 2x faster two-GPU image and video generation. Relevant if you run models locally.
rf-detr 1.12.0 — v1.12.0: One prediction API and INT8 exports
RF-DETR 1.12.0 adds one RFDETRInference API for images, video and streams across native and exported models, INT8 quantized exports, faster CUDA and Apple silicon defaults, per-class thresholds.
Why it mattersRF-DETR 1.12.0 unifies inference for native and exported models, adds INT8 exports for TensorRT, ONNX and OpenVINO, and flags eight behavior changes to review before upgrading.
Inkling 2 Small: An Inkling of Profanity
Vals AI reads reasoning traces from Inkling 2 Small across 2,655 benchmark runs.
Why it mattersReading agent reasoning traces at scale reveals behavior signals: swearing occurs only in long runs, yet 96% of failed runs never swore. It cautions against using such markers as failure predictors.
[AINews] Inkling 2 Small: 17A-594B trained in 68 hours on 12T tokens, beating Muse Spark
Latent Space's AINews digest on Thinking Machines' Inkling 2 Small.
Why it mattersA new Western open-weight model, Inkling 2 Small, reportedly competes with similar-size Chinese models and was pretrained quickly in native NVFP4. Engineers choosing open-weight models or fine-tuning via Tinker get a new option to evaluate.
Accelerating Scientific Research
Anthropic profiles labs using Claude as a research collaborator.
Why it mattersShows how research labs wire Claude into tool-rich agents for genome-scale analysis and gene cluster interpretation. Useful patterns for anyone building domain agents over fragmented tools and datasets.

7 Things Your AI Coworker Needs - Philipp Schmid, Google DeepMind
Google DeepMind's Philipp Schmid builds a finance coworker on Gemini Managed Agents.
Why it mattersShows how to give a hosted agent its own sandbox, tools and schedule while keeping credentials out of the model's reach through proxy-side substitution.

Your AI Agent Keeps Making the Same Mistakes - Sparsh Jain, CentralAgent AI
CentralAgent AI's Sparsh Jain describes rebuilding agent memory as an experiential system.
Why it mattersOffers a memory design with note lifecycle, deactivation and scheduled forgetting to stop agents repeating mistakes, rather than just appending context.
An index of the vibe-coding frontier. Corrections welcome.