Intel
Page 18
How I use AI (Oct 2026)
A research engineer describes moving from autocomplete to running five or six parallel coding agents in separate worktrees, what that costs in tokens.

Anthropic's ClaudeDevs account says Claude plugins can now auto-connect when users log in, provided the MCP server accepts Claude as a trusted issuer. Plugin builders can add support to speed onboarding and avoid repeated authorization. The linked docs and video were not available to read.
Why it mattersMCP servers that accept Claude as a trusted issuer let plugins connect automatically at Claude login, so users skip re-authorizing. Plugin builders need to add this support to get the faster onboarding.
openai-python v3.43.0
openai-python 3.43.0 expands Live Responses delegation tools and adds rich WebSocket progress accumulation plus lane overflow isolation for Responses streaming.
Why it mattersThe Responses API's WebSocket and Live Responses features gain delegation tools, progress accumulation and overflow isolation in the Python SDK, which matters if you stream agent output over WebSockets.

Mistral announces Large 4, an open-weight model with 1.05T parameters and a 1M-token context window, now live for approved teams on Open Math OS, a research workspace where mathematicians and AI agents share projects using only open models.
Why it mattersMistral Large 4 ships with 1.05T open weights and a 1M-token context window, available on Open Math OS to approved teams. Engineers can inspect and run an open frontier model, though access is gated and no benchmarks were provided.
Postman silently auto-installs AI plugins and attempts to share all API data
A user-filed issue reports Postman's desktop app auto-installing Codex and Claude Code plugins, a startup instruction hook and a remote MCP connection.
Why it mattersA desktop app reportedly modified users' coding agent configs without consent, so check your Codex and Claude Code plugin and hook directories for unexpected entries after installing API tooling.
Introducing Physical Engineering S Last Exam Ple With Google Cloud Ai Research
Mercor and Google Cloud AI Research release Physical-Engineering's Last Exam: 85 long-horizon engineering tasks run in the open-source Archipelago environment.
Why it mattersShows agents still fail about half of licensed-engineer tasks in mechanical, electrical, civil and structural work, at roughly 27M tokens and 63 minutes per task for the best configuration.

Agentic cheminformatics with Google Antigravity
DeepMind demonstrates Google Antigravity with new Cheminformatics Skills searching thousands of compounds, running matched molecular pair analysis and proposing macrocycles with synthetic routes in an hour.
Why it mattersShows how domain skills let a coding agent handle a multi-day cheminformatics loop (data curation, matched molecular pair analysis, candidate proposal) in about an hour. A useful template for packaging expert workflows as agent skills.
F3 Lightning: How Meta Accelerates Ads ML Features to Production at Scale
Meta details F3 Lightning.
Why it mattersShows how to decouple release units in a shared-execution feature graph without losing efficiency, a pattern applicable to large ML feature serving systems.
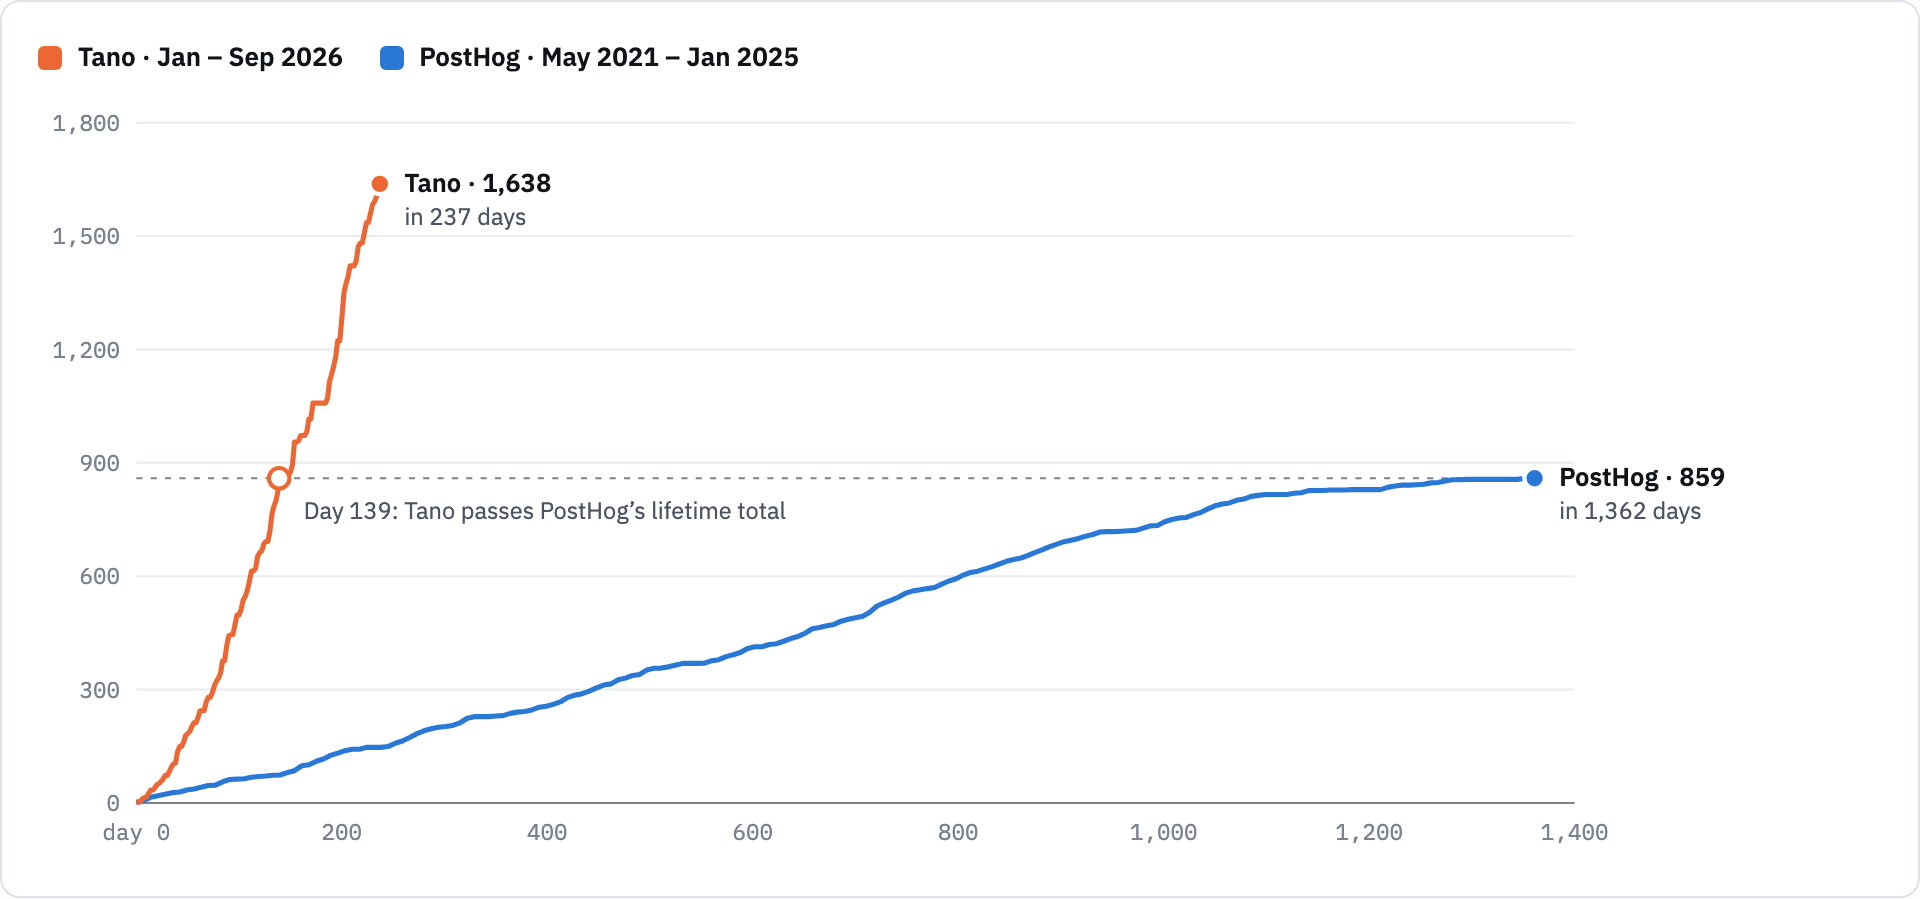
How software engineering is changing: a tale of two eras
The Pragmatic Engineer publishes its essay contest winner, in which engineer Neil Kakkar uses years of his own output data to contrast shipping before and after AI coding tools.
Why it mattersA data-driven personal account of how AI coding changed one engineer's shipping rate across two eras. It gives concrete numbers rather than generic opinion on AI's effect on software work.
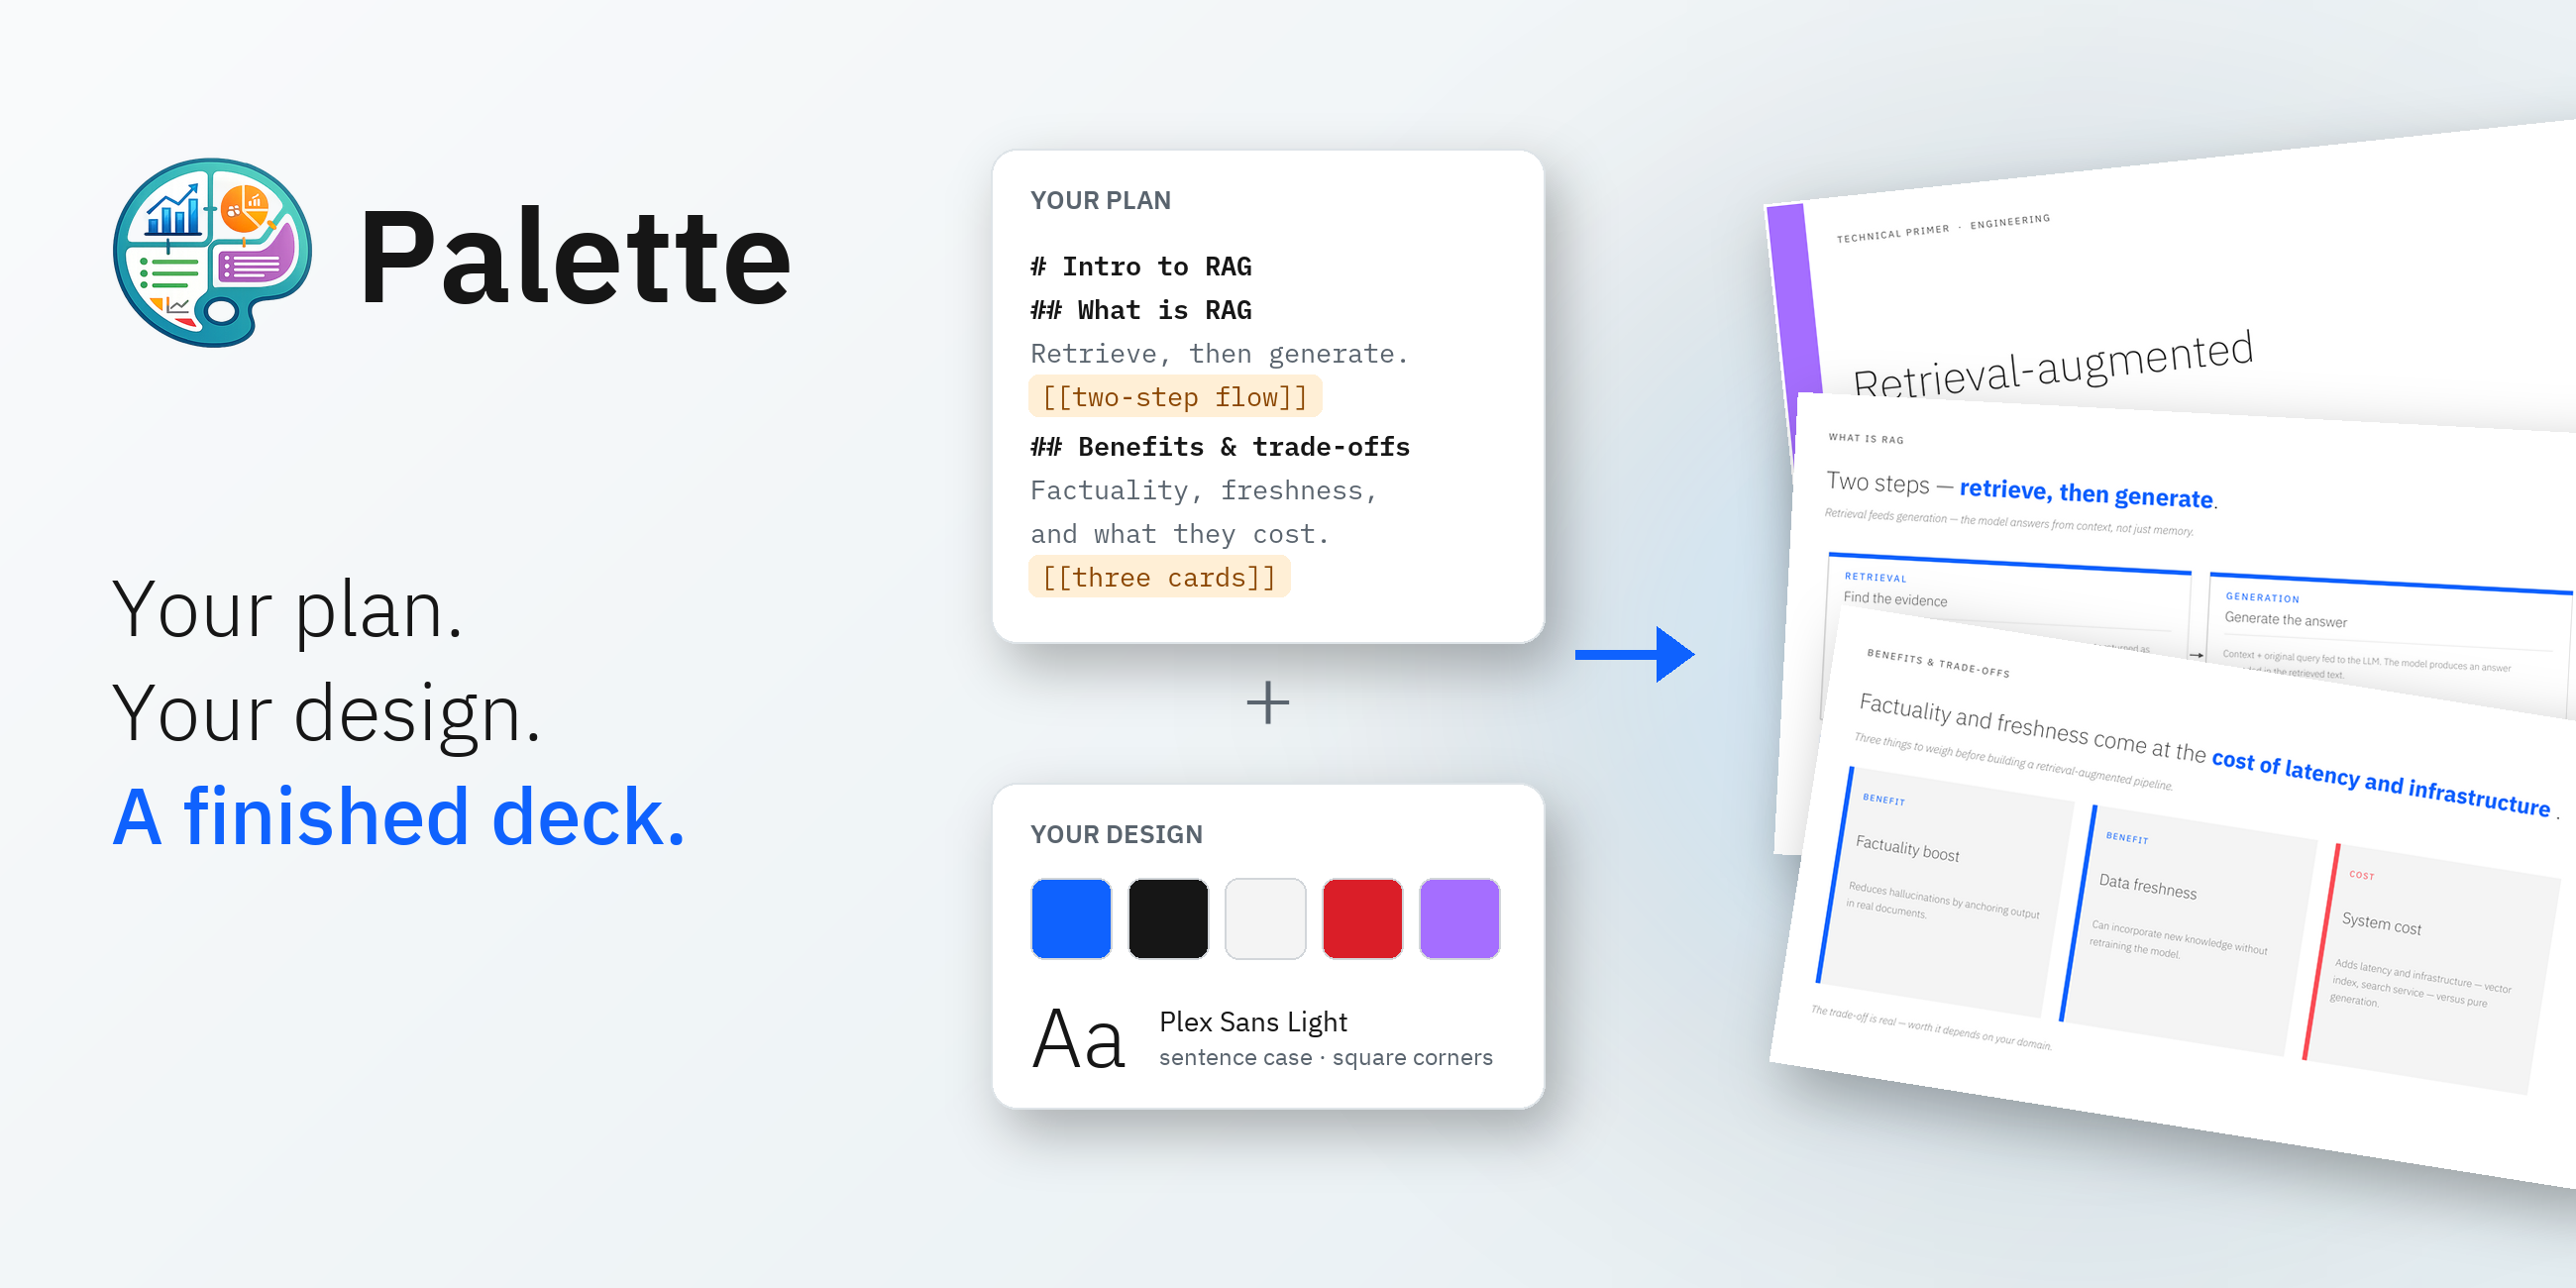
Palette: teaching a small model to build decks in your design language
IBM Research fine-tunes a 20B open-weight model with synthetic data and a checking harness to plan and draw decks in the IBM Design Language, reporting a top PresentBench ranking.
Why it mattersDemonstrates training a self-hostable small model on synthetic data in a specific design language, with a verifying harness, to compete with frontier systems. Useful pattern for brand-constrained generation with private content.
Qwen 3.8 27B on my laptop can interpret model weights, too
Simon Willison tests the weight-space programming idea from a new paper and finds a locally run Qwen 27B model can also read and interpret neural network weights.
Why it mattersShows that interpreting raw model weights as text, claimed for a frontier model in a new paper, also works with a 27B model on a laptop. Gives you a runnable way to test the claim yourself.
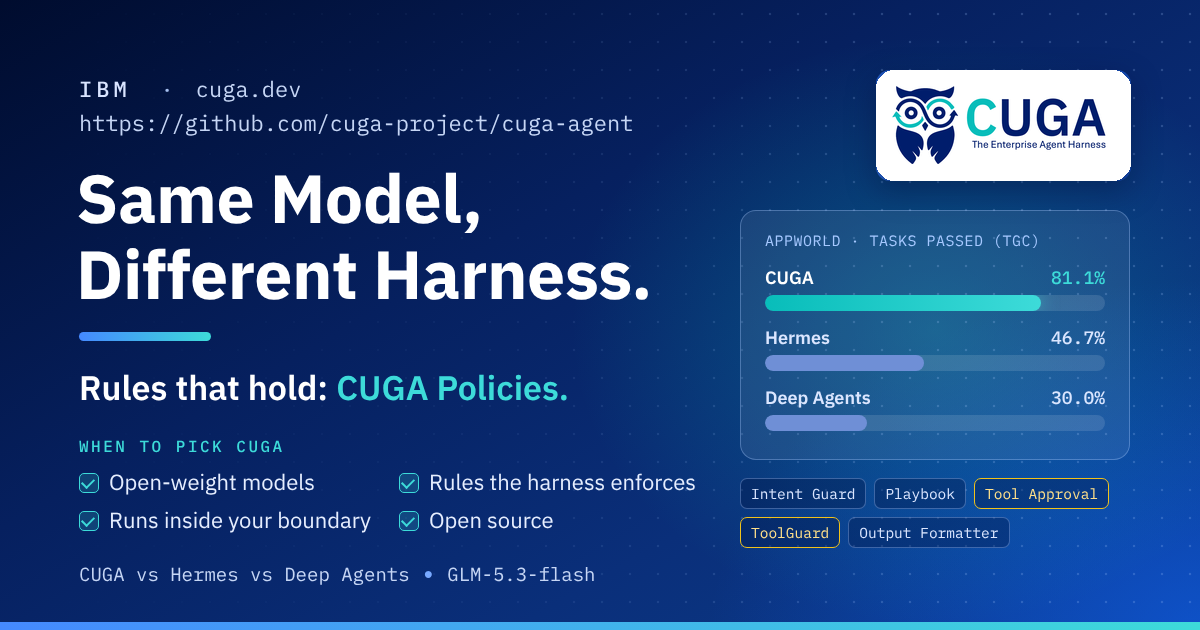
Same Model, Different Harness: CUGA, Hermes, and Deep Agents — When to Pick CUGA?
IBM Research compares three agent harnesses on the same open-weight model across 90 AppWorld tasks, reporting task completion from 30% to 81%.
Why it mattersQuantifies how much the agent harness alone changes outcomes with the same open-weight model. Useful evidence when choosing or building a harness, though the authors build one of the three.
unsloth v0.1.914-beta — Glass Theme, Personalize & Faster Generation
Unsloth v0.1.914-beta brings CPU text training, faster generation, more multi-GPU training options, chat navigation and Glass themes.
Why it mattersUnsloth adds CPU text training from the Train page, faster generation and more multi-GPU options, and links benchmarks of its DeepSeek-V4.1 GGUFs. Relevant if you fine-tune or run models locally.
open-webui v0.13.0
Open WebUI 0.13.0 adds a tabbed chat workspace for files, terminals and previews.
Why it mattersOpen WebUI now supports computer-use workflows in a desktop tab and keeps terminals, files and artifacts alongside the chat. Self-hosters can try agentic desktop control with compatible models.
The 'Astra can read and write weights to improve Qwen' post is misleading
A breakdown of a viral claim that a frontier model can read and write weights to improve Qwen.
Why it mattersIt separates what a model can infer from raw weights alone from what it does by writing Python and running the network, so you can read similar capability claims without overestimating the headline.
How Much Does Reasoning Effort Affect Score and Cost?
Vals AI runs seven frontier models at low, medium and leaderboard reasoning settings across the Vals Index.
Why it mattersLowering reasoning effort cut cost far more than score: at the lowest setting, four of seven models kept at least 80% of their Vals Index score for half the cost or less. Opus 5.5 kept 80% at 16% of cost.
github-mcp-server v2.1.0 — GitHub MCP Server 2.1.0
GitHub MCP Server 2.1.0 adds experimental artifact management tools, fixes merged state in pull request list output, rejects out-of-range integer parameters.
Why it mattersThe GitHub MCP server is a core integration for coding agents. This release adds experimental tools to create, read, update and delete artifacts and tightens integer parameter validation.
Mistral Large 4: When KV-Cache Savings Cost Agent Performance
Mistral's Large 4 report covers a 1T-parameter MoE built for agentic work.
Why it mattersMistral reports that KV-cache compression that looked fine on language-modeling loss degraded long-horizon agent performance, and describes how it recovered full context with sparse attention.

Make Your AI Agents Predictable With Graph Engineering - Zachary Blumenfeld, Neo4j
Neo4j's Zachary Blumenfeld presents graph engineering: compiling skills and memory traces into graph-shaped skills, with a loan-approval agent demo and per-branch observability.
Why it mattersShows how to turn skills and past runs into graph structures that constrain agent behavior and make branches observable. Useful if you need agents to follow auditable logic rather than free-form text.

Your AI Agents Shouldn't Care Where They Run - Nikhil Harithas, Factory
Factory's Nikhil Harithas details how Droid was rebuilt to run on any compute, covering the gateway and relay design, bring-your-own-key model calls, snapshots and forking.
Why it mattersExplains a design for running coding agents inside a customer's own cloud without borrowing user identity or leaving the VPC. Relevant for anyone deploying agents in regulated environments.
The Lisp curse, now coming to your ecosystem
Tim Zöller applies the Lisp curse to LLM-assisted coding.
Why it mattersArgues that if generating code is cheaper than learning a library, usage feedback and new open-source projects both decline. Worth weighing before defaulting to generated code over dependencies.
Better Search Took This AI Agent From 36% to 98% Accuracy - Aamir Shakir, Mixedbread
Mixedbread's Aamir Shakir critiques the OCR, chunking and vector database stack and demos multimodal late-interaction retrieval on earnings reports, citing a customer accuracy rise from 36% to 98%.
Why it mattersMakes the case that the OCR, chunk and embed pipeline loses information that agents need. Multimodal late-interaction retrieval is presented as the fix, with a reported accuracy gain from 36% to 98%.
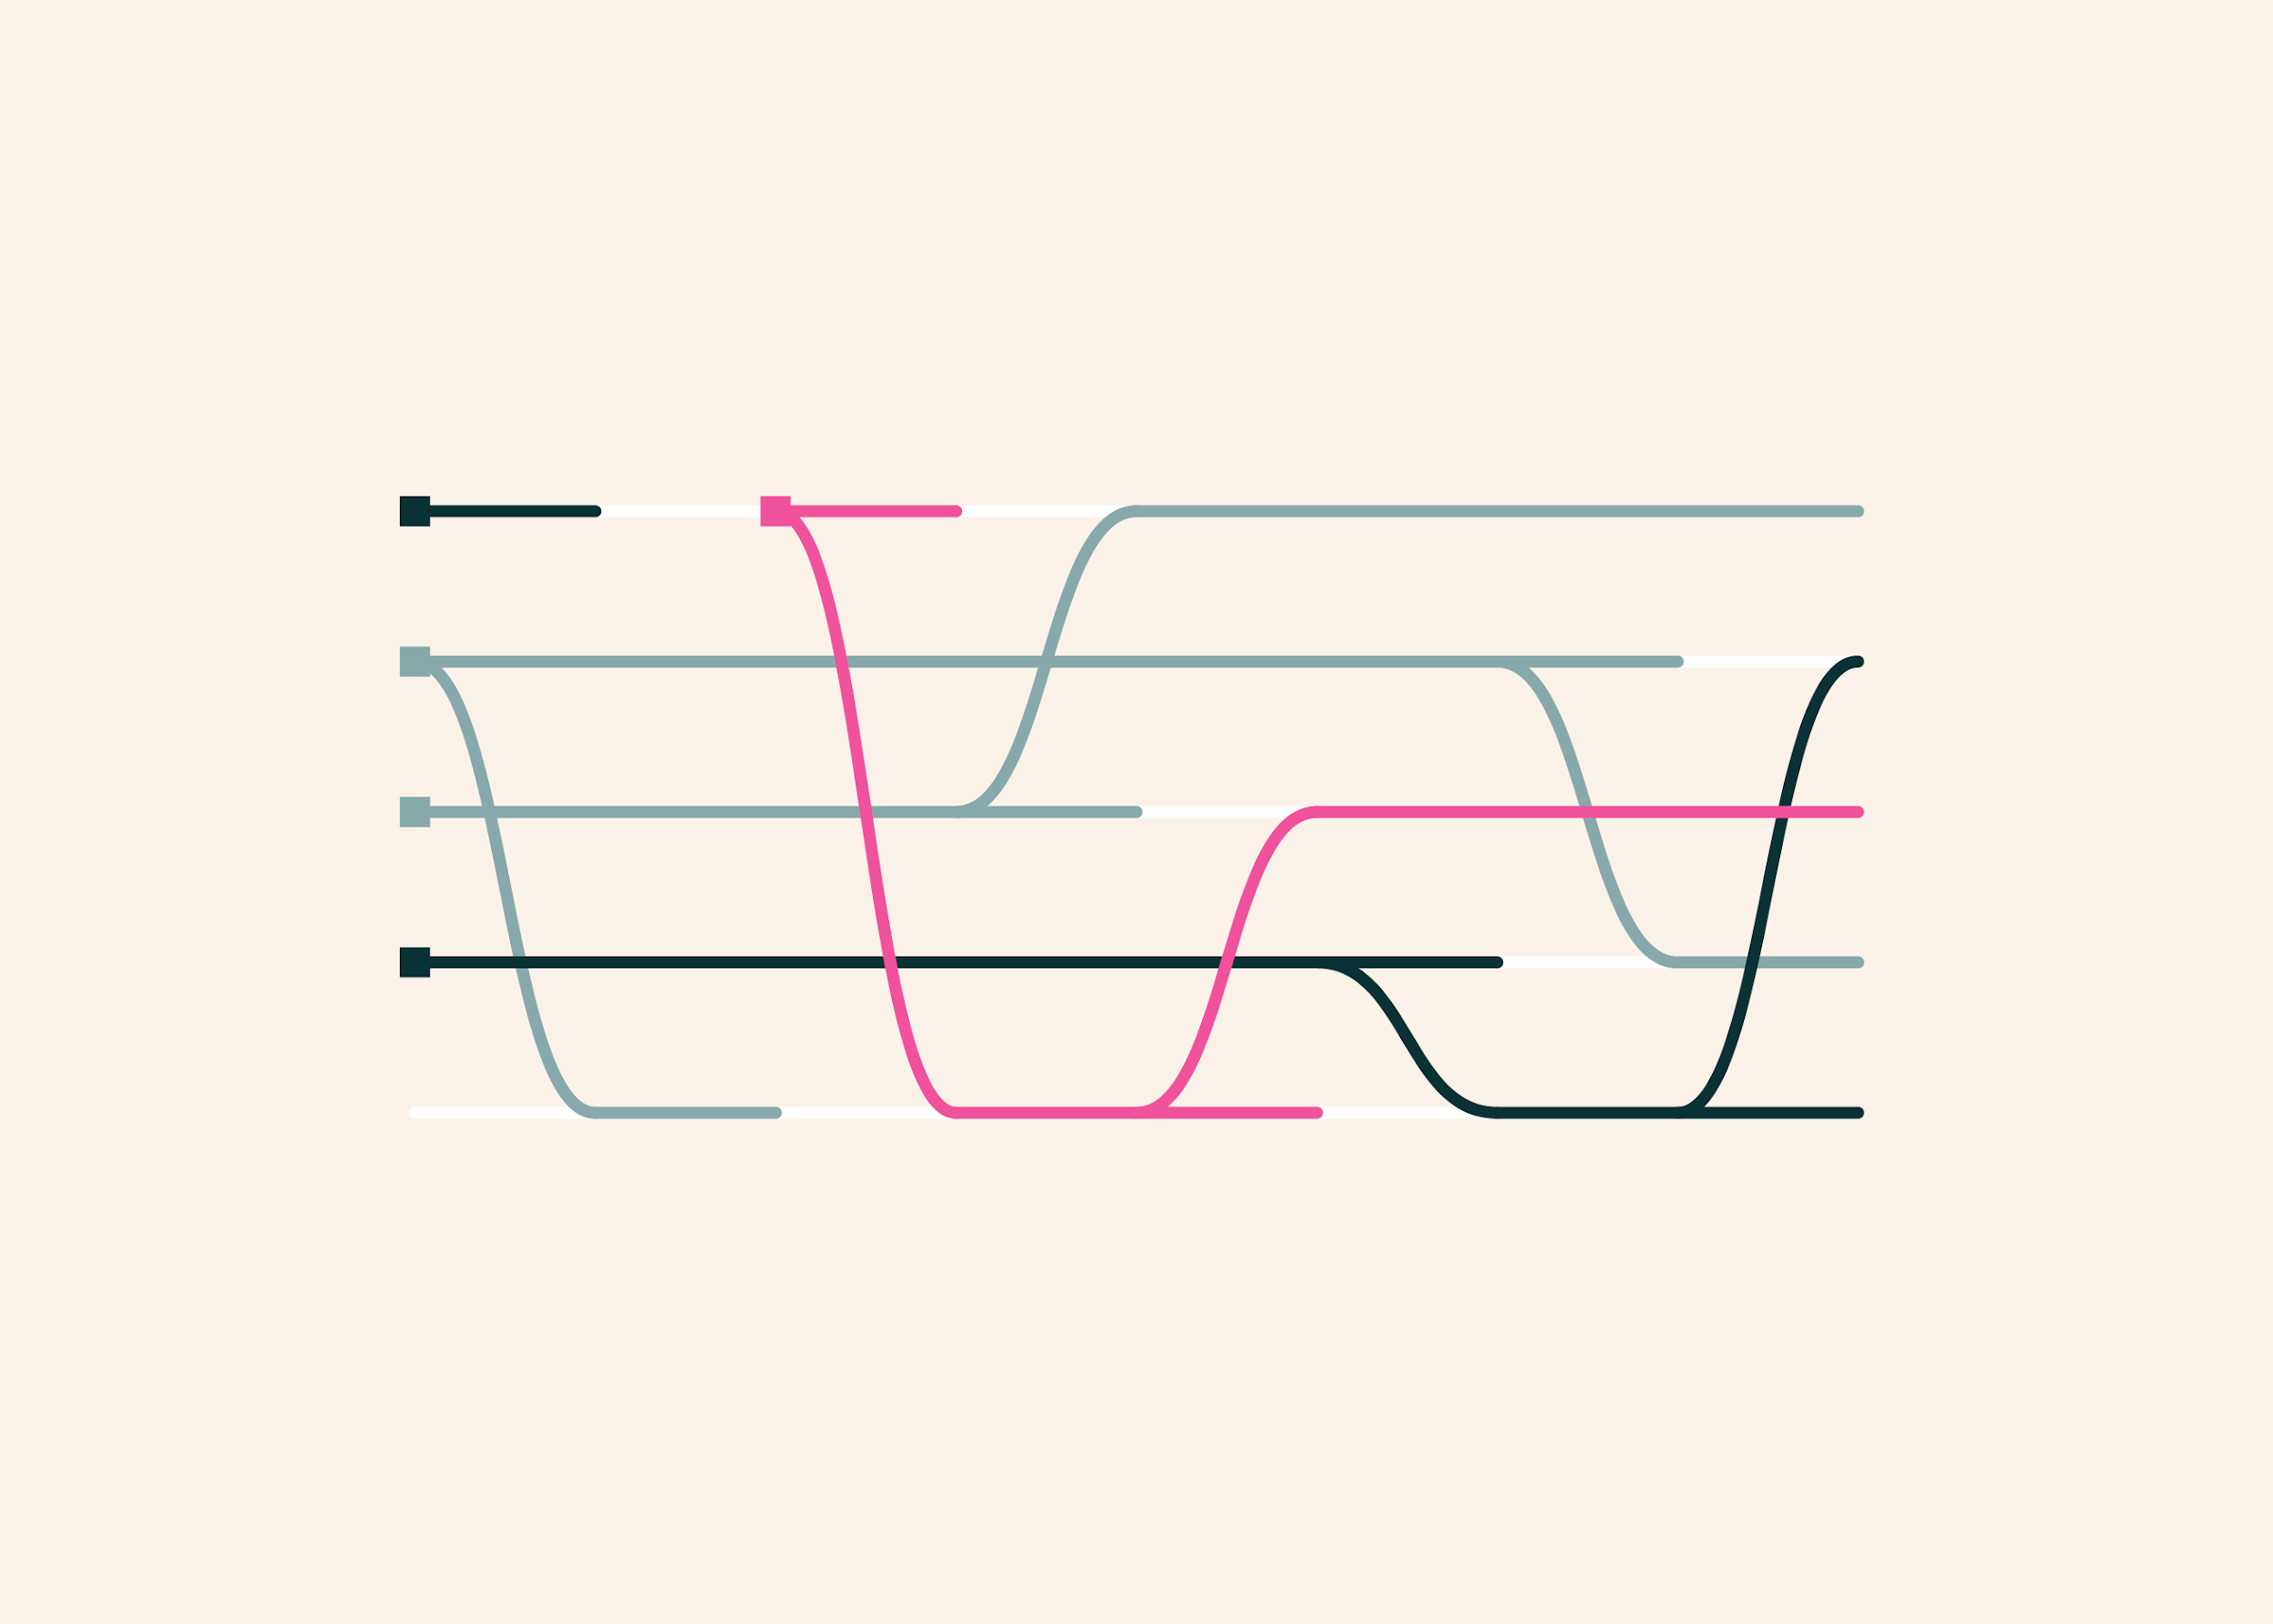
StateBench: Testing how language models track state changes over long documents
Ai2 introduces StateBench, a benchmark that grades how well language models follow entity state changes across long documents, from simple latest-value lookups to multi-step chains.
Why it mattersLong-context state tracking underlies code reading and agent memory. StateBench separates easy latest-update lookups from hard chained updates, so you can see which architectures, including hybrids, actually hold up.
MiniMax H3 Image released
MiniMax releases MiniMax-H3-Image, an open-weights model for text-to-image and image editing in one checkpoint.
Why it mattersAn open checkpoint generates and edits images up to about 16 megapixels in 6 sampling steps without CFG or an upscaler, so you can run fast high-resolution image generation locally or via API.
Arcee Ai Intel Gaudi2 Training A Financial Insights Model
Arcee AI details training Llama 3 8B and Qwen2 7B on 10B tokens of SEC and financial data using Intel Gaudi2, optimum-habana and DeepSpeed ZeRO-3, including Docker setup and Gaudi-specific configuration flags.
Why it mattersGives a working recipe for fine-tuning Llama 3 8B and Qwen2 7B on Intel Gaudi2, including the HPU flags and ZeRO-3 settings needed, for teams looking beyond Nvidia hardware.
[AINews] LLMs can read & write neural network weights: "Weight Space Programming" cuts Autoresearch out of the RSI loop
Latent Space's AINews covers a paper on 'weight space programming', where a capable LLM inspects and edits a smaller model's weights to diagnose, patch.
Why it mattersReports a method where an LLM reads and writes another network's weights directly, bypassing the usual train-and-eval loop. If it holds, it changes how automated research and self-improvement loops are built. Claims are unverified here.
MemU-Bench: Benchmarking GUI Agents on Long-Horizon User Interactions
MemU-Bench evaluates mobile GUI agents on 118 vague tasks built from 29 long user trajectories.
Why it mattersGUI agents are usually tested on precise, stateless instructions. This benchmark tests whether they can recover missing context from long interaction histories, and it penalizes agents that just search every app.
Early Stopping in Large Reasoning Models: A Survey and Empirical Audit of Efficiency and Reliability
An audit of early-stopping methods for large reasoning models across five models and math, science, code and factuality tasks.
Why it mattersCutting reasoning tokens early saves cost, but this audit finds correctness can fall beyond what decoding noise predicts and that stopped traces continue reasoning. Check these reliability failures before deploying early exit.
Fidelity Collapses with Table Size, Not Turn Count: Delivery Architecture in a Deployed Tool-Using Agent
A production award-travel agent comparison shows in-context synthesis of tool records corrupts data as tables grow, while a state-plus-deterministic-filter design stays accurate.
Why it mattersIf your agent re-emits tool output through the model, accuracy collapses once tables exceed roughly 10 to 200 rows depending on model. Keep records in session state and filter deterministically.
Agent Stack for ML Training Lifecycle: Generation, Validation, and Optimization
LinkedIn describes two agent loops in production: AutoTorch for generating and migrating PyTorch models, and AutoResearch for model optimization.
Why it mattersShows how a large engineering org gates agent-generated model code with executable checks (API compliance, trainability, conversion fidelity) before human review, a pattern reusable in other agent pipelines.
MEMENTO: Learning Context Management for Long Context Processing Agents
MEMENTO trains Qwen3-8B to manage its own context via compaction, using hindsight-annotated notes then RL with correctness, note-quality and calibration rewards.
Why it mattersCompaction notes written by off-the-shelf models are often ineffective for long-context agents. Training context management explicitly lifted an 8B model from 36.9% to 67.8% on book-length QA.
Provable Inference
Anthropic's Frontier Red Team presents FlashProve, a zkSNARK system proving which model produced a response without revealing weights.
Why it mattersShows that proving which model produced a response is now feasible at ~70-95x GPU cost, without revealing weights. This bears on detecting silent model substitution by routers or providers.

OpenAI plans an internal security sprint with Cathedral Systems researchers using its models to probe its defenses, raises bug bounty rewards more than fourfold for critical findings (up to $172,000 with bonuses), and says it will widen model access for trusted defenders.
Why it mattersOpenAI is paying up to $172,000 for critical findings and extending model access to trusted defenders. Security engineers get a larger bounty incentive and a signal that frontier models are being used for defensive vulnerability discovery.
ollama v0.40.14
Ollama v0.40.14 fixes the Claude Code output token cap for cloud models, stops OpenAI-compatible endpoints overriding packaged sampler defaults, preserves /v1/responses input content, adds Codex routing checks.
Why it mattersOllama's OpenAI-compatible endpoints now use a model's packaged temperature and top_p instead of forcing 1.0, and ollama launch claude respects cloud models' output limits past the 128k default, which changes behavior for existing clients.
claude-code v2.1.317
Claude Code 2.1.317 adds fail-closed hook callbacks in the Agent SDK, a prompt before account email is sent over the network, extra OTel attributes, a gateway cost report API, scheduled-task connector warnings.
Why it mattersAgent SDK hook callbacks can now fail closed with onFailure: "block", so a broken safety hook no longer lets an action through. The release also adds a cost report API and new OTel attributes for tracking spend.
claude-agent-sdk-typescript v0.3.317
Claude Agent SDK for TypeScript 0.3.317 adds fail-closed hook matchers, a session_writes_lost message for disk-full conditions, new startup failure reasons.
Why it mattersHooks can now fail closed with onFailure: "block", so a crashing security or policy hook no longer lets an action through silently.
ai @ai-sdk/workflow@2.0.94
AI SDK workflow 2.0.94 reports a durable WorkflowAgent run as one telemetry operation covering the prompt, steps, tools and output.
Why it mattersDurable agent runs that span suspension and resumption can now be traced as one operation, with model spans nested under the invoke_agent tree.
ai ai@7.0.162
AI SDK 7.0.162 restores server-defined tool metadata, dynamic status, and title when validating tool approval continuations.
Why it mattersIf you run durable agents with tool approvals, approval policies now see the same tool definition fields as fresh calls. WorkflowAgent runs can also report as one traced operation via an OpenTelemetry ID generator bridge.

You Can't Tell What's Real Anymore. Here's What Comes Next - Cristóbal Valenzuela, Runway
Runway's CEO traces video generation from 2019 to today, explains physics learned via next-frame prediction.
Why it mattersOutlines where real-time, interactive video and world models are heading and how Runway thinks visual output could serve coding agents. Gives builders a view of upcoming capability.
Diagnose Vercel CLI setup problems with vercel doctor
Vercel CLI adds vercel doctor, which checks CLI install, login, team, project link, vercel.json and platform incidents, reporting per-check status and fix commands.
Why it mattersAgents deploying to Vercel can run a non-interactive, read-only diagnostic and get structured fix commands with --json, instead of guessing at CLI, login or project-link problems.
Tencent Hy4 now available on AI Gateway
Vercel added Tencent's Hy4 to AI Gateway at 50% off through December 31, 2026.
Why it mattersHy4, Tencent's first vision-capable Hy model with 1M-token context and computer use, can now be called as tencent/hy4 through AI Gateway at half price until December 31, 2026, including from coding agents via the Vercel CLI.
Transformers Model Integration Contracts
Hugging Face's Transformers team proposes Model Integration Contracts: small pinned fixtures, runnable usage paths and baselines that run on CPU per PR.
Why it mattersShrunken CPU fixtures built from real checkpoint configs can catch silent regressions like UMT5's decoder seeing future tokens, which a forward-pass test misses. Useful pattern for anyone testing model code in CI.
CWE-bench v2: More coverage, quality, and transparency
Collinear AI releases CWE-bench v2.
Why it mattersGives a reproducible, programmatically graded benchmark for agents that find and fix real vulnerabilities, with checks designed to reject memorized upstream patches. Useful for evaluating security capability of coding agents.
llm 0.37
Simon Willison's llm 0.37 adds OpenAI-compatible endpoint registration, new GPT models, a cheaper default model, and per-item content types for multimodal embeddings.
Why it mattersThe llm CLI now registers any OpenAI-compatible endpoint with one command and embeds mixed media such as audio, images and video. It also shows maintainers handling AI-assisted PR volume with model-assisted triage.
llm 0.37
Release 0.37 of the llm CLI adds new OpenAI model IDs, switches the default model to GPT-6 Luna, adds commands to manage OpenAI-compatible endpoints.
Why it mattersThe default model changes to GPT-6 Luna for users without their own default, which can alter behavior and cost; llm models default gpt-5.6-luna reverts it. Embedding plugins can now accept typed attachments such as images.
Diagnose Distributed AI Workload Failures with NVIDIA Attribution
NVIDIA explains its open-source Attribution tool.
Why it mattersOffers an open-source way to turn scattered logs, metrics and scheduler state into a reproducible root-cause diagnosis for failed distributed AI jobs. It has been used on fabric failures at large GPU scale.

Building Legal Agents When You Can't See the Data - Jacob Lauritzen, CTO of Legora
Legora's CTO explains how the team evaluates a legal agent without seeing customer data: engineer and lawyer pairs build test worlds from customer work.
Why it mattersShows a working approach to evaluating production agents without access to customer data: small teams of engineers and domain experts building simulated task worlds.
Why Nextcloud bundled Olmo 3 for local, auditable AI
Nextcloud bundles Olmo 3 7B in its llm2 local LLM backend, chosen for its highest Ethical AI rating (open training data and software, self-hostable) and because it runs without 16 to 32 GB of VRAM.
Why it mattersNextcloud admins can deploy Olmo 3 7B once through llm2 and expose it across Assistant and Mail on modest hardware. It shows openness criteria (open training data, self-hosting) deciding model choice for public-sector deployments.
Keep Distributed Training Running with Automated Workload Recovery
NVIDIA describes a workload recovery service for training clusters that detects anomalies from logs, GPU metrics and scheduler signals, attributes failures, isolates nodes.
Why it mattersShows a concrete design for auto-recovering failed distributed training jobs: monitor mode first, then autonomous actions, with an audit trail. Reported production latencies give a baseline for what automated recovery achieves at scale.
sglang v0.5.23
SGLang v0.5.23 ships 1007 PRs adding cookbook support for new LLMs, VLMs and diffusion models, plus DeepSeek-V4.1 prefill and first-token latency gains on GB300 hardware.
Why it mattersSGLang v0.5.23 adds serving support for several new LLM and diffusion models and reports up to 1.5x prefill throughput for DeepSeek-V4.1 on GB300, which affects self-hosted inference cost and latency.
An index of the vibe-coding frontier. Corrections welcome.