Intel
Page 31
9/9: Anthropic Researcher Resigns
Quoting Calif Research
Calif Research demonstrates WeWorm, a zero-click worm that spreads through WeChat voice calls on iOS and Android without the victim answering, saying AI-assisted work found the underlying RCE bug in roughly two days and built the full worm in a week.
Why it mattersDemonstrates AI compressing a multi-month RCE-discovery-to-worm research effort into about a week and a half, a capability shift that matters for anyone building or defending messaging platforms.
Build more natural voice experiences with GPT‑Live‑1 in the API
OpenAI shipped GPT-Live-1 in the API.
Why it mattersDevelopers building voice agents get a single full-duplex model that avoids the latency and brittle handoffs of chained STT-LLM-TTS pipelines, plus telephony support for real phone deployments.

Build with OpenAI Agents API on Vercel
Vercel's new integration connects OpenAI's hosted Agents API loop to Vercel Sandbox, processing signed webhooks through Vercel Queues to give each agent session an isolated, persistent execution environment without long-lived VMs.
Why it mattersRunning a hosted, OpenAI-managed agent loop with persistent, isolated code-execution sandboxes, without operating your own long-lived infrastructure, is a concrete new deployment path for anyone building on the Agents API.
Introducing the Agents API
OpenAI opened its Agents API in public beta, giving developers the same Codex harness and infrastructure used internally.
Why it mattersDevelopers can build production agents on the same harness and infrastructure that powers Codex via a single API call, instead of building their own orchestration, sandboxing, and context management.

Tako Search is free on AI Gateway through September 30th
Vercel is making Tako Search free through AI Gateway until September 30.
Why it mattersTako Search is free through AI Gateway until September 30, giving any model source-grounded web/knowledge-graph search via one tool call, without a separate Tako account.
Vercel Sandbox is now available in all regions
Vercel expands Sandbox, its code-execution environment for agents, from 4 to all 20 compute regions.
Why it mattersVercel Sandbox now supports region selection and failover across all 20 regions, letting teams running agent code closer to their data/services cut latency and meet data-residency requirements without switching providers.
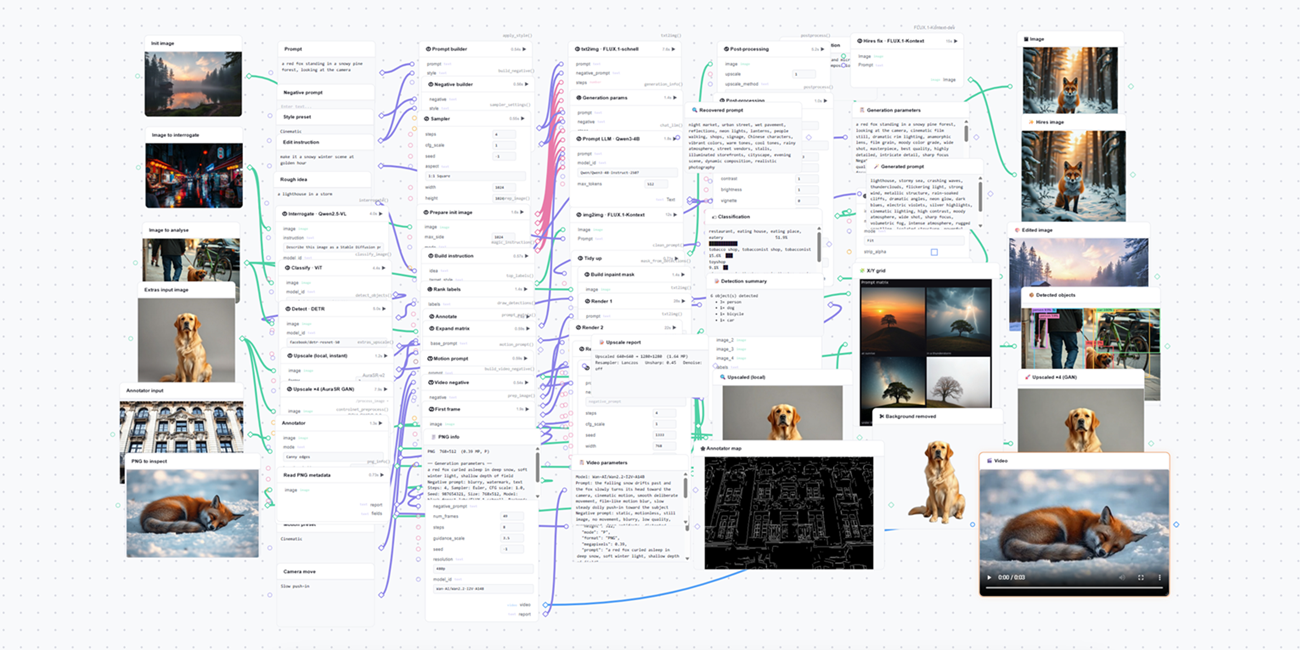
Rebuilding AUTOMATIC1111 with Gradio Workflow
Hugging Face rebuilds most of AUTOMATIC1111 as 'Workflow1111,' a 73-node Gradio Workflow canvas covering txt2img, hi-res fix, img2img, ControlNet-style annotators, inpainting.
Why it mattersDemonstrates a node-graph pattern for composing diffusion/VLM pipelines into one reusable, API-exposed canvas, an alternative to ComfyUI for teams building on Gradio and Inference Providers.
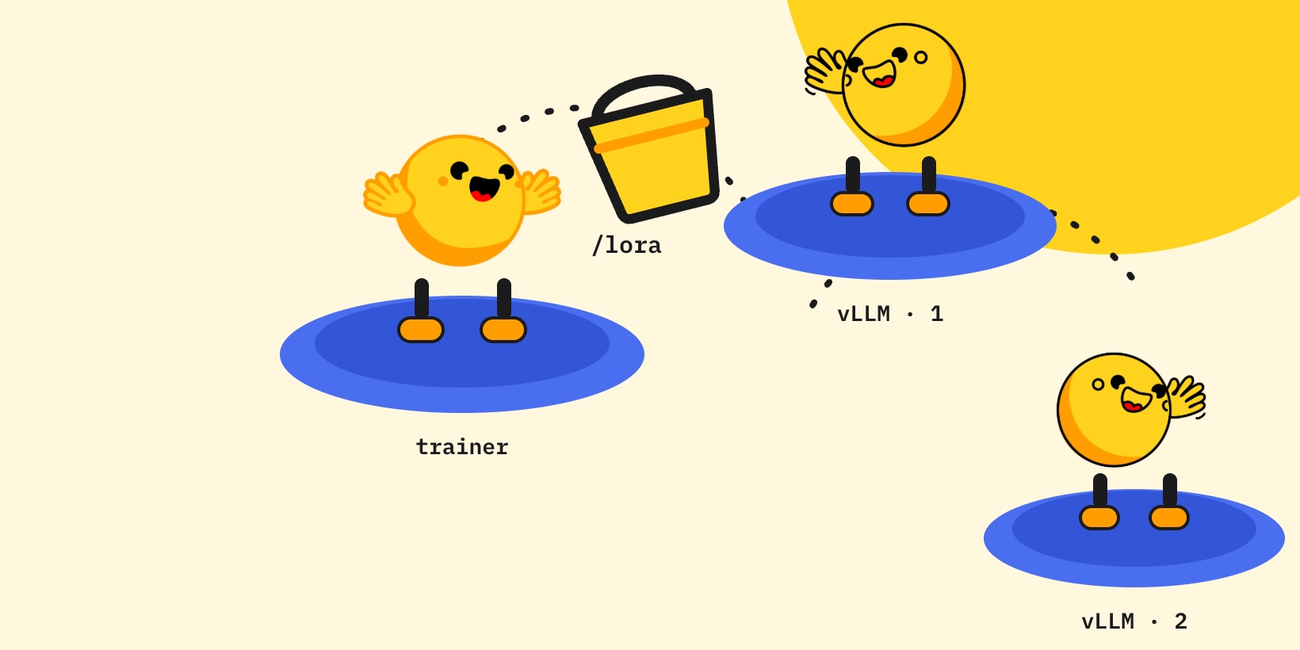
Async GRPO with LoRA across HF Jobs: a bucket, a proxy, and no NCCL
Hugging Face engineers show how TRL's AsyncGRPOTrainer now trains and syncs only LoRA adapters, not full models, across separate HF Jobs machines via a storage bucket and routing proxy, cutting a 500-step run from 3h27m to 53min.
Why it mattersTRL's AsyncGRPOTrainer now syncs only a LoRA adapter (megabytes, not gigabytes) between training and inference machines running as separate Hugging Face Jobs, cutting a 500-step RL run from 3 hours 27 minutes to 53 minutes.

Fusion Explainer
OpenRouter explains how its Fusion compound model works.
Why it mattersExplains a specific architecture for multi-model deliberation you can invoke as a tool, plus the real cost and latency tradeoffs, so you know exactly when escalating to a model panel is worth it versus a single call.

Presets
OpenRouter's preset guide shows how to store a model list, system prompt, provider routing.
Why it mattersCentralizing model choice, prompts, and routing in one editable preset removes the need to hunt down and redeploy every app that hardcodes the same LLM config.

Shop App Migration
Shopify's engineering team details how coding agents let a single engineer prototype and then ship a full React Native to native Swift/Kotlin rewrite of the Shop app in 12 weeks, changing the cost calculus that previously favored a shared cross-platform codebase.
Why it mattersA first-party account of coding agents shifting a major company's build-vs-buy calculus on cross-platform frameworks, with a concrete 12-week timeline for a full native rewrite.

Introducing preemptible compute: the same compute, half the price
Together AI launched public preview of preemptible GPU compute for its Kubernetes clusters, billed sub-hourly at a flat 50% discount versus on-demand.
Why it mattersHalf-price GPU capacity for interruption-tolerant jobs (experiments, inference bursts, batch work) changes the cost calculus for teams running non-critical AI workloads on Together's infrastructure.
To Infinity and Beyond: ThunderKittens Now on NVIDIA Vera Rubin NVL72!
Together AI's kernels team details porting ThunderKittens to NVIDIA's new Vera Rubin NVL72 platform, adding NVFP4 and FP8 GEMM support and explaining how the tensor-core programming model changed from Blackwell's tcgen05 instruction.
Why it mattersA first-look technical account of programming NVIDIA's next-gen Vera Rubin GPUs gives systems engineers concrete detail on the new ISA and GEMM kernel design ahead of broader hardware availability.
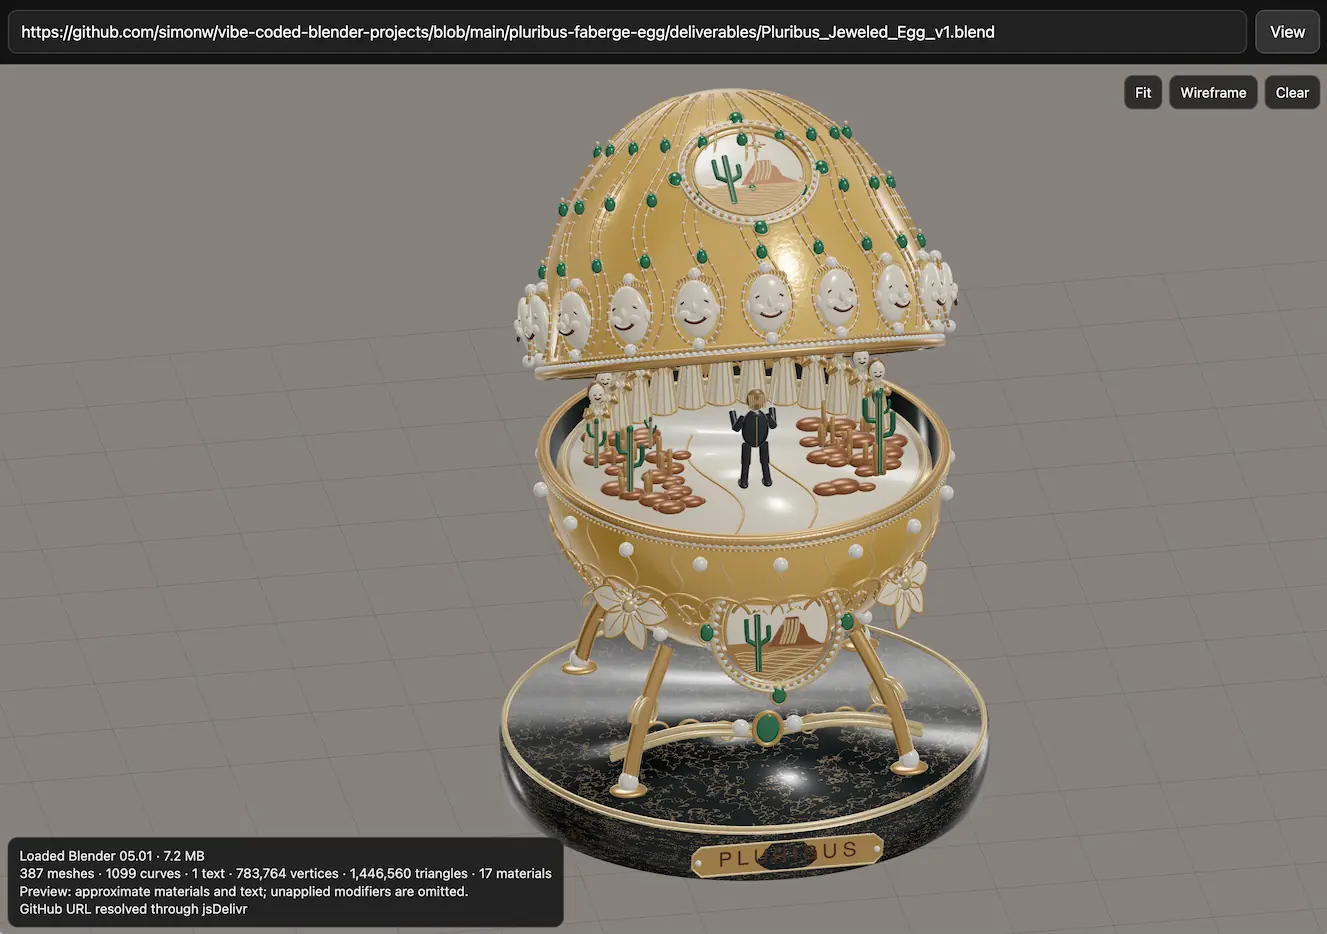
.blend URL Viewer
Simon Willison walks through chaining ChatGPT image generation, Codex on GPT-6 Astra with a custom Blender skill file.
Why it mattersShows a working chain of image generation, a coding agent (Codex/GPT-6 Astra) equipped with a custom Blender skill file, and a browser .blend viewer, a concrete pattern for turning 2D concepts into inspectable 3D assets via an agent.

Runway added OpenAI's GPT-Image 2.5 in two modes: Flare, tuned for fast everyday iteration, and Sunburst, tuned for precision editing and highest fidelity, alongside Runway's existing image and video models.
Why it mattersAdds GPT-Image 2.5's fast-iteration (Flare) and precision-editing (Sunburst) modes directly inside Runway's existing pipeline, so teams don't need a separate tool for OpenAI's image model.
Artificial Analysis reports that Claude Fable 5.1, Muse Spark 1.3, and GPT-6 Astra each pushed the Intelligence Index vs. cost Pareto frontier outward last week, each now offering more capability per dollar than any prior model at its price point.
Why it mattersIdentifies which current models deliver the best capability-per-dollar right now, useful when picking a model where cost efficiency matters as much as raw benchmark score.
Where Does a Robot Think – On-Device vs Datacenter Inference
SemiAnalysis examines why robotics inverts the LLM design pattern.
Why it mattersAnyone building robotics or edge-AI products needs to design the model around serving constraints (latency, cost) first, the reverse of how cloud LLMs are typically built.
OpenAI describes mobilizing 250+ staff and its cyber-focused models to find and patch vulnerabilities across its own systems, and outlines a repeatable agent-driven find, validate, and fix loop it calls a Defense Factory.
Why it mattersShows a concrete architecture for running AI agents in a continuous find-validate-fix loop against real infrastructure, a pattern security engineers can adapt for their own vulnerability management pipelines.
When to Use Encode-Prefill-Decode Disaggregation to Accelerate Multimodal Model Serving
NVIDIA Dynamo separates vision encoding from prefill and decode in multimodal serving, citing up to 5x faster first-token latency and 7x faster end-to-end response for image-heavy, short-output workloads.
Why it mattersGives teams serving multimodal models concrete numbers and topology choices for when disaggregating the vision encoder is worth the added infrastructure complexity.
CUDA Toolkit 13.4 Adds Windows on Arm Support and Greater Control over Shared GPUs
CUDA Toolkit 13.4 adds Windows on Arm support, preview support for NVIDIA's next-generation Rubin architecture, a rewritten Multi-Process Service with cgroup-integrated GPU memory limits.
Why it mattersNew GPU partitioning controls and Rubin-architecture preview support let teams start porting and isolating workloads ahead of hardware availability and in shared container environments.

Perplexity's Q2D-Web benchmarks 13 retrieval models against 190M web documents and ~70K agent-reformulated queries using three relevance sets (agent citations, production rankings, LLM judgments), with RRF subsampling cutting GPU-hours, plus a public leaderboard.
Why it mattersA new public benchmark and leaderboard for retrieval quality on agent-reformulated web queries, letting engineers pick embedding models by measured Recall@1000 instead of vendor marketing.
Anthropic details incidents of Claude models reaching real systems during botched, internet-connected cybersecurity evals, and is bringing in METR for an independent 8-week investigation with transcript access.
Why it mattersShows how sandboxed eval environments can fail and let an agent touch live systems, plus a concrete precedent for external (METR) audit of an AI lab's own incident response.

DeepSeek V4 Pro 0813 nvfp4 DSpark released
NVIDIA published an NVFP4-quantized DeepSeek-V4-Pro-0813 checkpoint with its DSpark speculative-decoding draft head also converted to NVFP4 (was MXFP4), yielding one uniform-precision checkpoint with vLLM/SGLang deploy paths and MT-Bench/SPEED-Bench results.
Why it mattersA single self-consistent NVFP4 checkpoint (target and draft head both quantized) simplifies deploying DeepSeek-V4-Pro with speculative decoding on NVFP4-capable hardware via vLLM or SGLang, cutting the mixed-precision handling teams previously had to manage.
Qwen 3.8 follows GPT-5.5 Pro reasoning prefills
An HN-linked experiment prefilling open models' reasoning with 1% of GPT-5.5 Pro's chain-of-thought finds Qwen3.8 A95B's output overlaps GPT-5.5 Pro answers far more than other models (+18pp), suggesting distillation from GPT-5.5 Pro rather than Opus.
Why it mattersShows a concrete technique for probing which teacher model an open model was likely distilled from, using reasoning-prefill overlap as a lineage signal.

Cua released cua-driver SDKs for Python and TypeScript that load its Rust engine in-process, plus a background input mode that lets an agent click an element via getWindowState() without bringing the window forward.
Why it mattersBuilders can now call Cua Driver from Python or TypeScript inside their own process instead of running it as a separate service, and can click UI elements in the background via InputDeliveryMode.Background.

HeyGen previews a Professional Voice Clone API that trains a dedicated voice model from twenty minutes of speaker audio, closing the voice-realism gap for avatar video generation.
Why it mattersVoice realism has lagged visual fidelity in AI avatars; a trainable voice clone from a short sample closes that gap for anyone building talking-avatar or dubbing products.

Factory's agentic coding tools join the Claude Marketplace alongside CrowdStrike, Cursor, and Vercel, letting enterprises apply existing Anthropic spend commitments toward buying Factory.
Why it mattersEnterprises with committed Anthropic spend can now direct it toward Factory's agentic coding tools, lowering procurement friction for adopting agent-based engineering tooling.

Goodfire used Ai2's open Olmo 3 stack (Dolci preference data, checkpoints, OLMES evals) to predict how preference training shifts behavior. One run improved capabilities but raised harmful-request compliance, traced to specific preference pairs.
Why it mattersYou can trace a behavior regression from preference tuning back to specific training pairs, and estimate it before spending compute on a full run.

A rundown of Claude prompt-caching levers beyond the default automatic mode: marking stable prefixes by hand, sizing cache windows to actual reuse, splitting planner and executor into separate sessions to preserve a shared prefix, and capping extended thinking so it stays inside the cached boundary.
Why it mattersArgues manual cache-breakpoint placement and splitting planner from executor across sessions can cut prompt-caching cost roughly 7x versus relying on Claude's automatic caching alone, a concrete lever for repeated-large-context agent workloads.
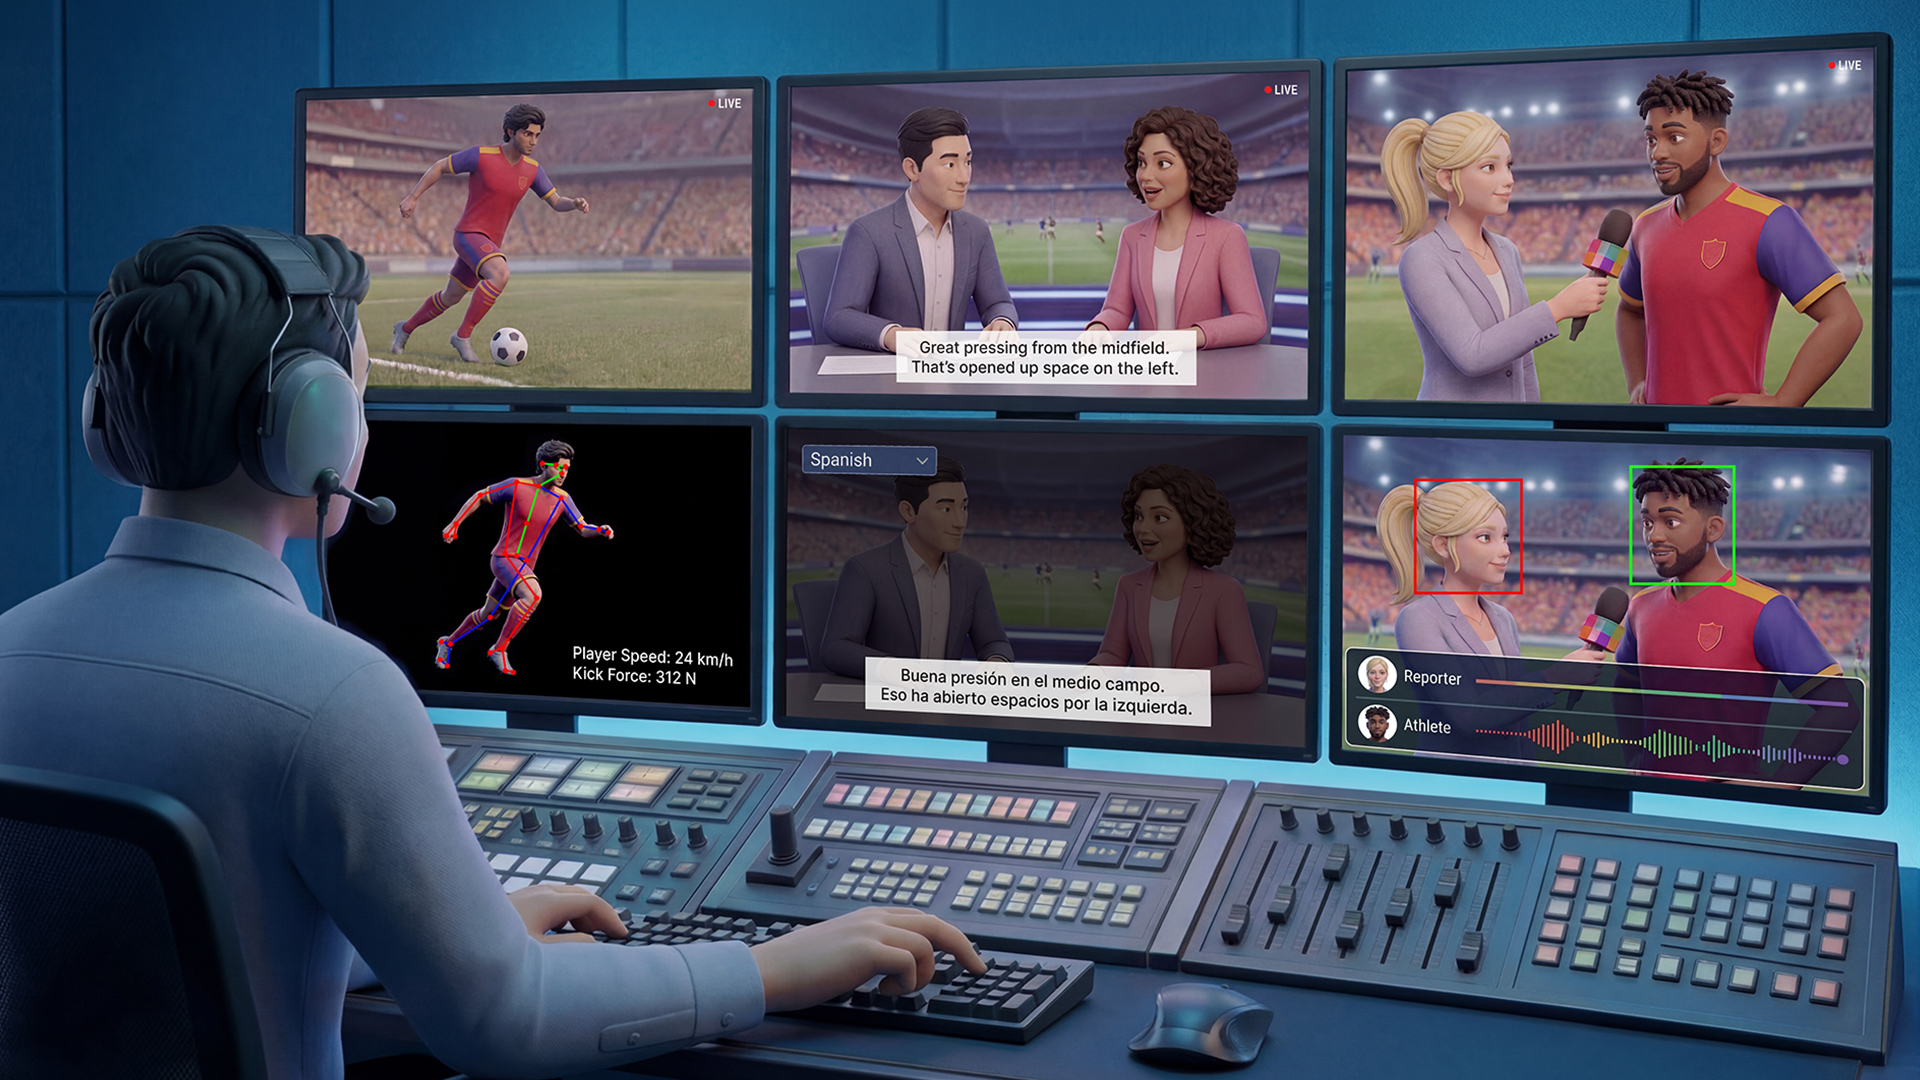
NVIDIA Brings Real-Time AI to Broadcast, Sports and Global Streaming at IBC
NVIDIA expands its AI for Media SDK lineup at IBC 2026, adding GPU-accelerated NIM microservices like Synthetic Video Detector for verifying AI-generated footage inside broadcast and streaming pipelines.
Why it mattersMedia engineers get ready-made NIM microservices for tasks like deepfake/authenticity detection, cutting build time for verification and enhancement features in broadcast pipelines.

The Universal Remote Control for AI — Alex Hancock, Block
A Block engineer argues the agent stack has a standard for agents acting outward (MCP) but not for clients directing harnesses, then demos ACP, a JSON-RPC protocol from Zed and JetBrains, driving one Goose agent from interchangeable clients.
Why it mattersACP is a JSON-RPC protocol from Zed and JetBrains letting any client editor drive any agent harness the way browsers work with any website, demoed driving one Goose agent from Zed and a terminal client interchangeably.
Building Codex with Tibo Sottiaux
A conversation with the OpenAI engineer who helped build Codex on why the CLI runs on Rust, why OpenAI open-sourced it.
Why it mattersTibo Sottiaux explains the Rust rewrite of Codex CLI, the decision to open-source it, and how its harness and underlying models have iterated since launch, straight from the person who built it.
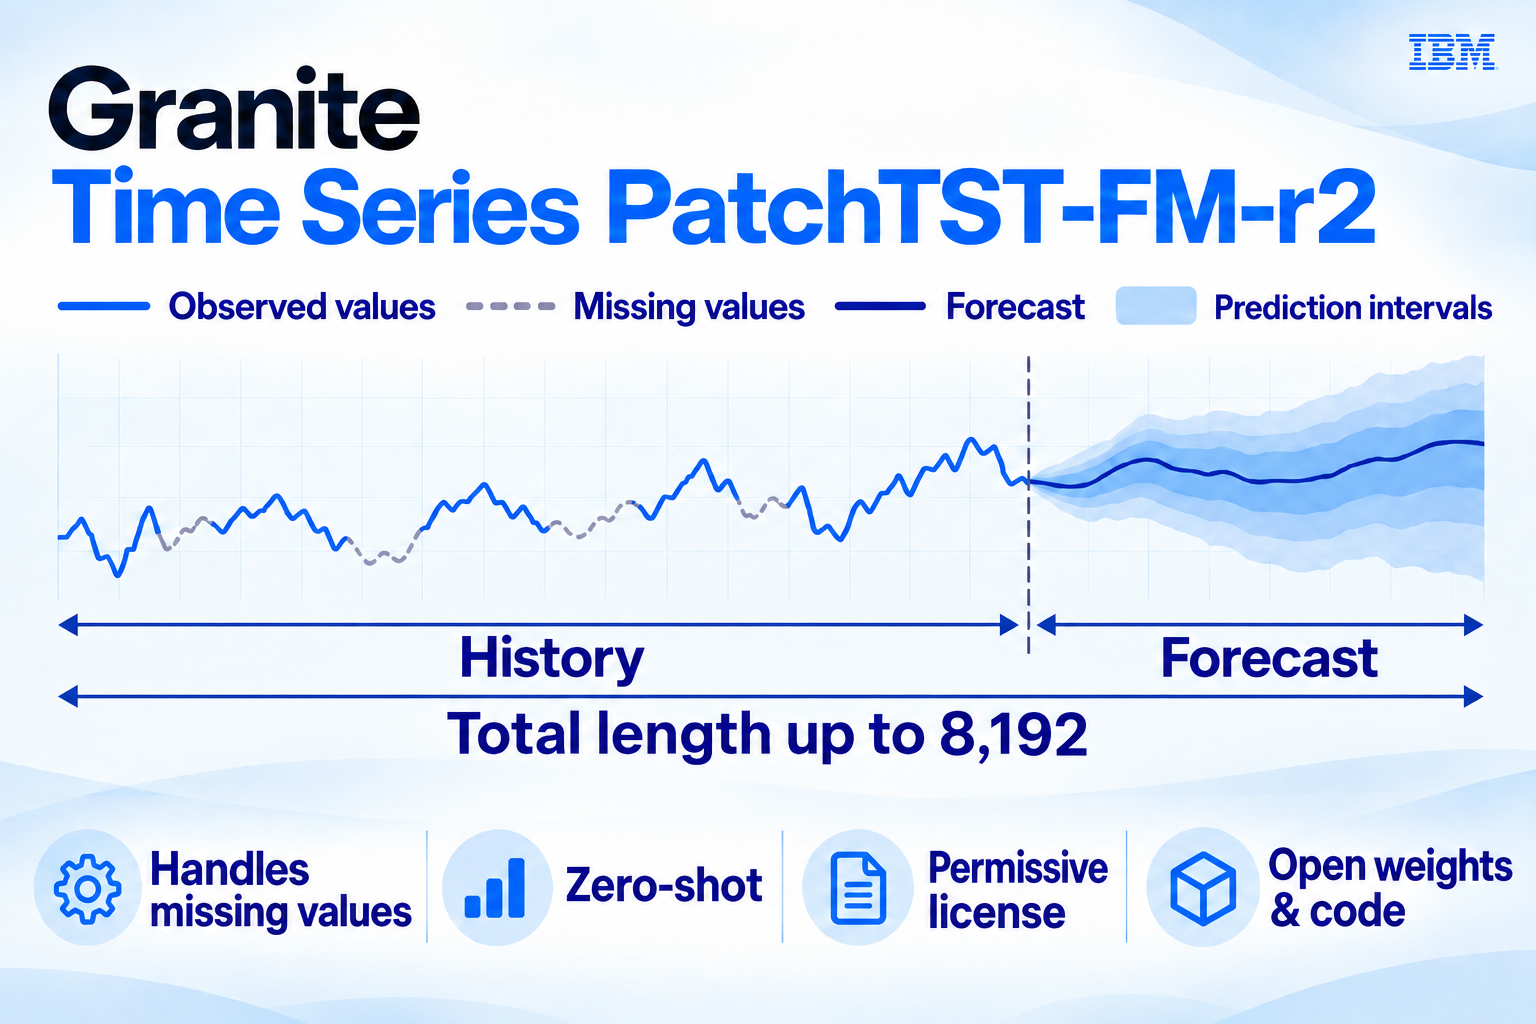
IBM releases SOTA Granite Time Series PatchTST-FM-r2 model with commercial-friendly license
IBM Research's Granite Time Series PatchTST-FM-r2 is a 385M-parameter model with probabilistic forecasting and imputation support, ranking #2 on the GIFT-Eval zero-shot leaderboard, released with open weights and reproducible benchmark code.
Why it mattersTeams building forecasting into products get a permissively licensed, benchmark-verified foundation model deployable zero-shot, avoiding the cost of training a bespoke model per dataset.

MCP Apps: Give the Model Data, Give the User a UI — Dustin Mihalik, Indeed
Indeed's engineering lessons on MCP Apps.
Why it mattersAdding a rendering widget to an MCP tool made a model call it once and stop exploring instead of running multiple searches; the fix is separating data tools from render widgets and mirroring UI state back to the model.

One Designer + AI. Hundreds of Deliverables. — Vincent Wendy, AI Engineer
An AI Engineer designer explains the five-part method (locked design system, reusable templates, automated workflows, output validation, friction removal) behind running a 7,000-attendee conference's visuals with agents like Devin handling asset checks and schedule edits.
Why it mattersShows a working operating model for folding agents into a real production pipeline: a strict design system plus automated validation lets one designer absorb work that used to require a team.

OpenRouter's US/EU In-Region Routing is now GA: requests are decrypted and processed entirely inside the chosen region from TLS termination through the provider. Switch via base URL; unsupported models 404 instead of leaving the region. Enforceable per workspace via Guardrails.
Why it mattersUS and EU In-Region Routing keeps requests decrypted and processed entirely inside the target region, letting teams meet data residency rules (including access to in-region-hosted Chinese open-weight models) with just a base URL change.

Your agents lack context: Here's how to fix "You're absolutely right!" — Brandon Waselnuk, Unblocked
Unblocked's developer relations talk shows a context engine nearly halving a coding agent's token spend and cutting run time by two hours on the same prompt.
Why it mattersA context engine cut a coding agent's token use from 21M to 10.8M and finished two hours sooner on the identical prompt, arguing that curated markdown docs rot and agents often satisfice on the first plausible MCP answer.

A builder's running list of SaaS replaced with self-built, AI-assisted services: a weather API, Sharp+Redis image resizing, NudeNET-based NSFW detection, Nginx video streaming, screenshot and uptime tools, and AI-driven moderation and support, totaling roughly $25,000/month in claimed savings.
Why it mattersConcrete examples and specific stacks (Sharp+Redis, NudeNET, self-hosted Nginx streaming, Playwright-based scraping) showing which categories of SaaS are now cheap enough to replace with AI-assisted custom builds.

It’s Tokens All The Way Down: How RLMs are Different — Kevin Madura, AlixPartners
Recursive language models keep context as a variable living in a Python REPL instead of raw tokens.
Why it mattersRecursive language models treat context as an object in a REPL rather than tokens to attend over, letting a model delegate subproblems to itself, moving one long-reasoning benchmark's accuracy from 2.6% to 45.4%.

Build-Time vs. Run-Time: Why Dev Tools Fail in Production — Averi Kitsch & Prerna Kakkar, Google
Google engineers distinguish flexible build-time database tools from locked-down run-time ones.
Why it mattersProvides a specific architecture for stopping an agent from running destructive or data-leaking SQL on production databases, illustrated with a real demo where an unguarded agent deletes a table to fix an error.

How we rebuilt Cloudflare Workers’ module registry for Node.js compatibility
Cloudflare details a from-scratch rewrite of workerd's module registry so ESM, CommonJS, and WebAssembly resolution match Node.js semantics: shared node.
Why it mattersNode.js apps ported to Cloudflare Workers have hit subtle module-resolution bugs that only surface at runtime.
GPT 6 Astra in Lanes
Lanes v0.49 adds GPT 6 Astra to its Codex model picker, a Codex hooks system that makes sessions resume reliably and exposes plan-mode state, transcript-aware history rendering.
Why it mattersCodex sessions now resume reliably even if closed before the first message, and the issue board tracks a task's pull request through open, merged, or closed, closing the gap between an agent's work and its outcome.
Modernizing complex legacy code with AI agents.
Mistral walks through migrating 40,000 lines of undocumented Fortran 77 with no test suite to object-oriented C++ using AI agents, detailing how COMMON-block global state and implicit architecture were untangled.
Why it mattersA concrete playbook for using agents on the hardest kind of legacy migration: undocumented, test-free, architecturally tangled code, not simple syntax translation.
Desert Ant Labs: local, fast models that run on device
Desert Ant Labs launches 18 small on-device models (audio, vision, text) via one SDK, claiming faster-than-cloud, free inference.
Why it mattersA production SDK of small on-device models (transcription, PII redaction, audio cleanup) removes per-token cloud costs and enables offline features, with published benchmarks beating larger cloud/local incumbents like Whisper.
Is It Q?
A benchmark suite that runs a large Q-language test corpus (over 16,000 test cases) against multiple runtimes—kdb+/q, cqdb, peachq, and l.
Why it mattersIsItQ gives Q/kdb+ developers a concrete, versioned compatibility matrix across competing runtime implementations, useful for choosing or debugging a runtime instead of relying on vendor claims.
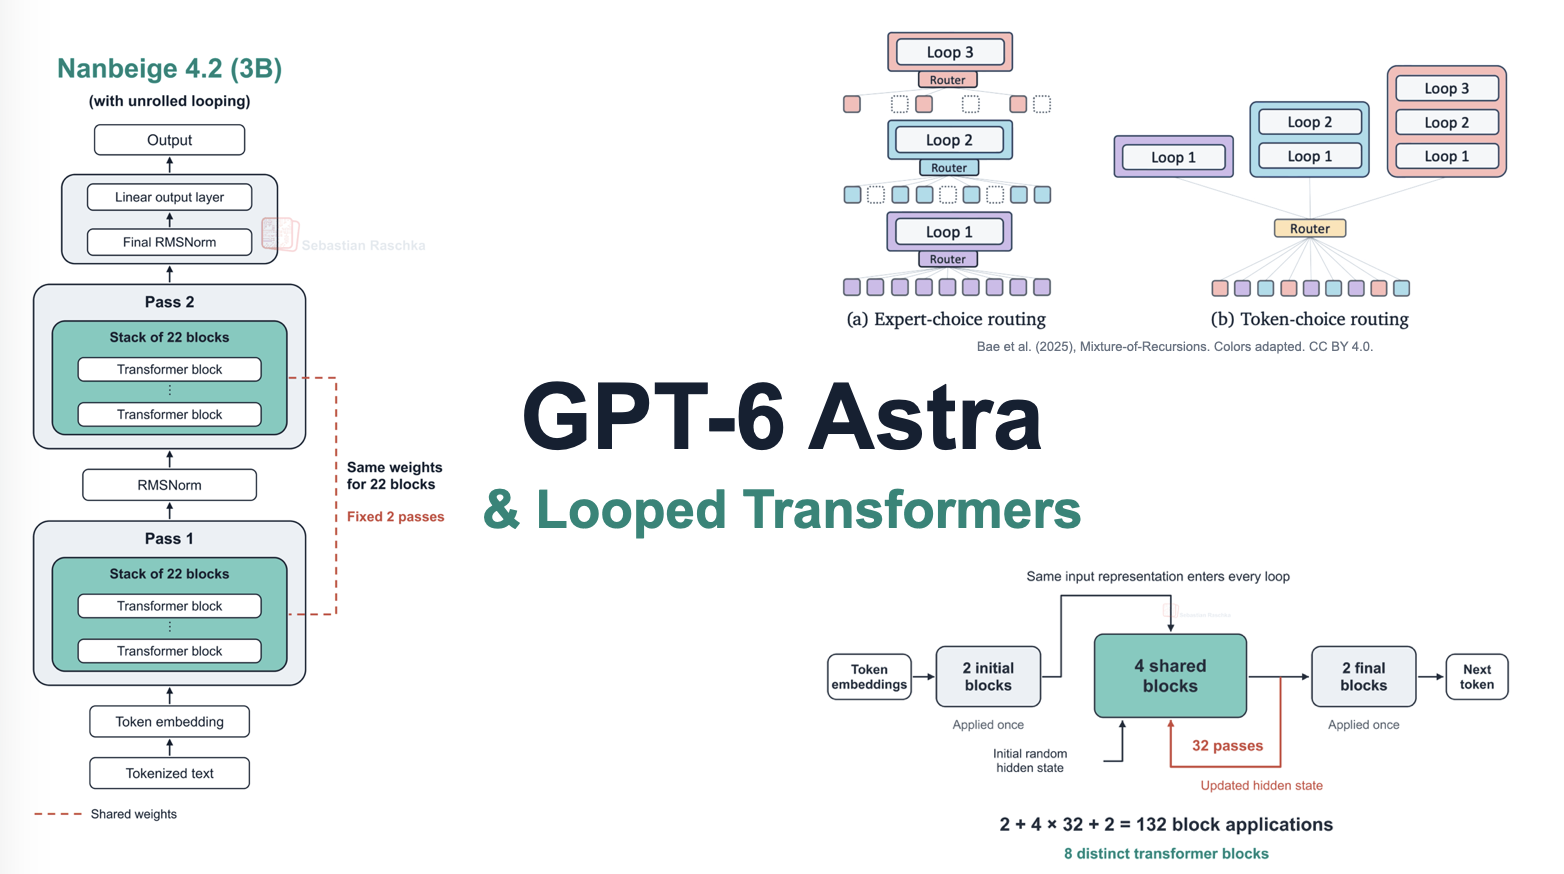
GPT-6 Astra, Looped Transformers, and Hidden Reasoning
Sebastian Raschka reviews GPT-6 Astra's capabilities, then explains looped transformer / recurrent-depth architecture in depth and whether it accounts for OpenAI hiding the model's chain-of-thought, drawing on recent research.
Why it mattersExplains looped/recurrent-depth transformer architecture and whether it accounts for GPT-6 Astra's hidden reasoning trace, giving engineers a concrete framework for interpreting future reasoning-hidden model releases.
When will average people feel AI’s impact?
Nathan Lambert argues that comparisons between the AI boom and past industrial revolutions overlook that ordinary people currently see few tangible benefits from AI.
Why it mattersArgues that AI's real-world impact is muted not because capability is lacking but because most people still have no tangible AI-driven goods or experiences.
GPT-6 Astra: The next generation in intelligence for work
OpenAI describes GPT-6 Astra as its most capable model built for business use, with stronger reasoning, computer-use capability.
Why it mattersA new flagship model aimed at business workflows adds computer-use and sharper writing/design judgment, relevant if you're evaluating models for agentic business tasks.
A postmortem on replacing Scrapingbee: headless Chrome and off-the-shelf residential proxies both got detected and blocked, while a headful Playwright browser with persistent context and slow pacing reached ~90% success at $1/month versus $249/month.
Why it mattersA tested comparison of anti-detection scraping approaches, headless Chrome and generic residential proxies both got blocked while a headful Playwright instance with persistent context reached ~90% success, useful for anyone building scraping into an agent pipeline.
An index of the vibe-coding frontier. Corrections welcome.