Artificial Analysis Benchmarks GPT-6 Sol and Luna's Cost Cuts
- Source
- ArtificialAnlys
- Date
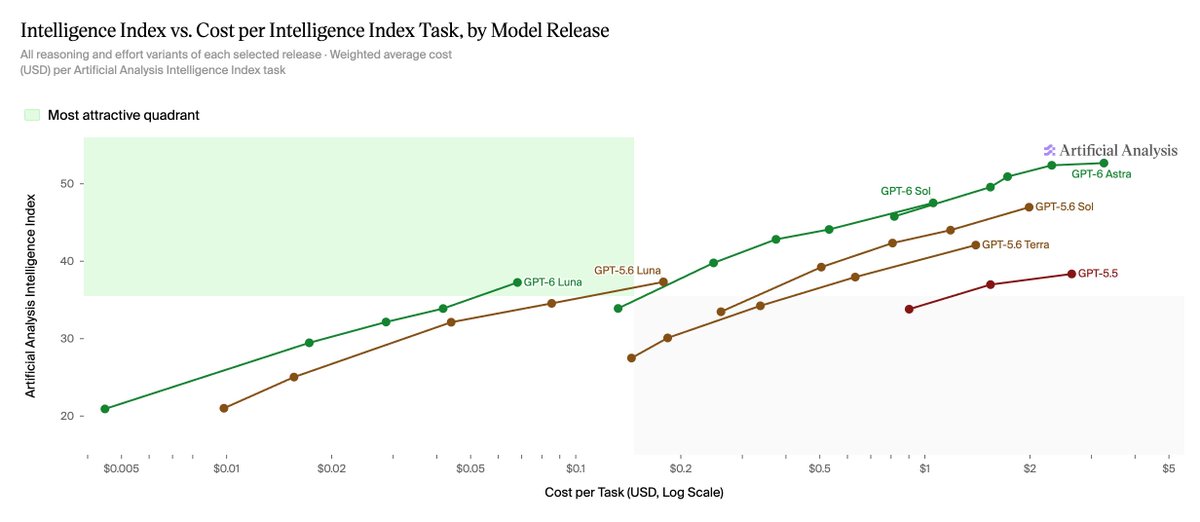
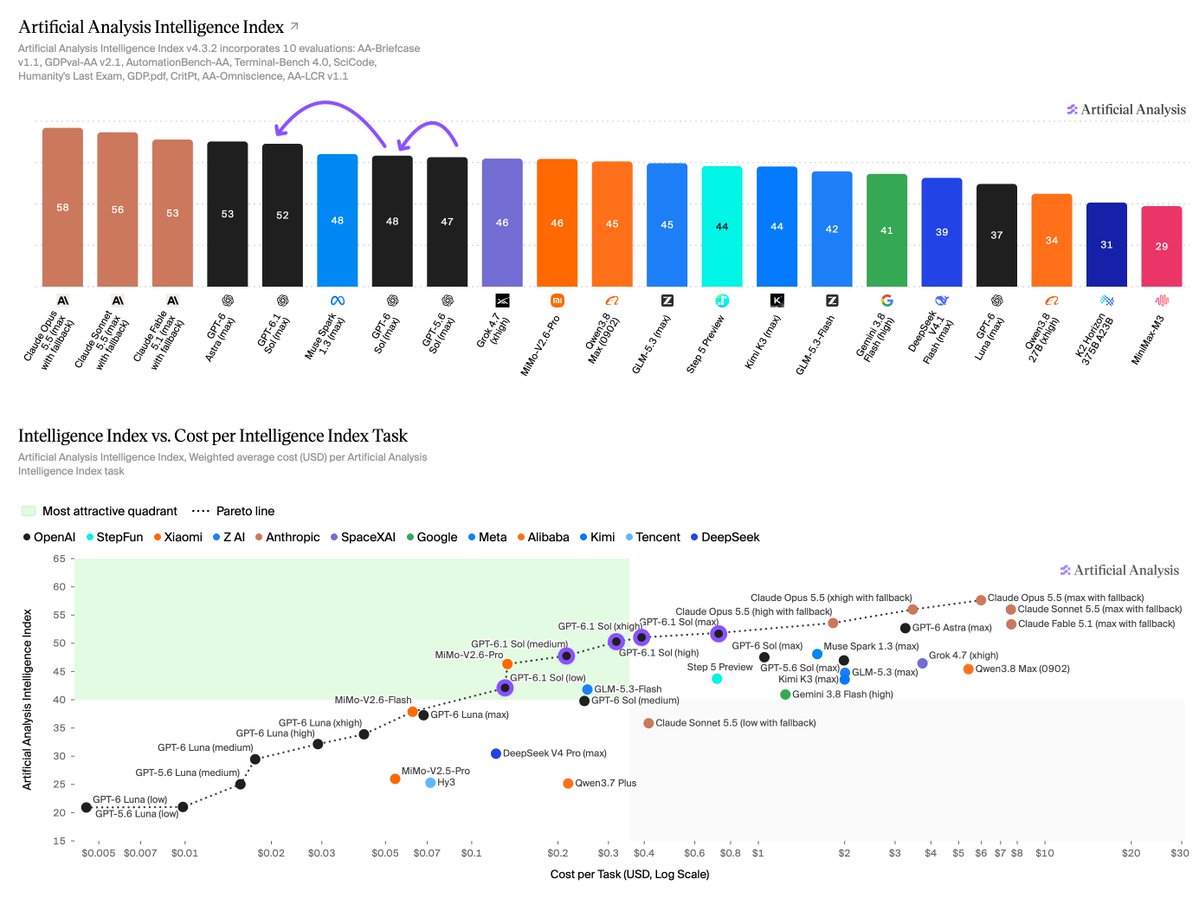
GPT-6 Sol and Luna push the cost efficiency frontier by halving cost relative to GPT-5.6 Sol and Luna. Intelligence Index and Coding Agent Index scores remain level with GPT-5.6, with progress in some evaluations and regressions in others Pricing is approximately half that of GPT-5.6: Sol drops from $4/$20 to $2/$10 per million input/output tokens, and Luna from $0.20/$1.20 to $0.10/$0.50, with the same 90% discount for cache reads and 25% premium for cache writes. Key takeaways: ➤ Halves Cost per Task: GPT-6 Sol (max) costs $1.06 per task to run the Artificial Analysis Intelligence Index, ~50% less than GPT-5.6 Sol (max) at $1.99. GPT-6 Luna (max) costs $0.07 per task, ~60% less than GPT-5.6 Luna (max) at $0.18. This is driven by the price cut, as both models use slightly more output tokens per task (31k vs 29k for Sol, and 51k vs 41k for Luna). These two releases allow OpenAI to capture a significant portion of the cost efficiency Pareto frontier. ➤ In the Coding Agent Index, Sol improves but Luna regresses: In OpenAI's Codex harness, GPT-6 Sol (max) scores 57 in the Artificial Analysis Coding Agent Index, up 2 points from GPT-5.6 Sol (max), with gains in Terminal-Bench 4.0…

Context
Artificial Analysis benchmarked OpenAI's GPT-6 Sol and Luna and reports that they roughly halve cost relative to GPT-5.6 Sol and Luna while Intelligence Index and Coding Index scores stay level, with gains on some evaluations and losses on others.
On the Intelligence Index, Sol (max) costs $1.06 per task against $1.99 for GPT-5.6 Sol, and Luna (max) $0.07 against $0.18. Artificial Analysis attributes this to the price cut, since both new models use slightly more output tokens per task. In its Coding Agent Index, run in OpenAI's Codex , Sol rose 2 points to 57 while Luna fell 2 points to 41.
rates on its AA-Omniscience fell from 92% to 60% for Sol and from 93% to 77% for Luna. For Sol that came partly from declining to answer more often, attempting 83% of questions instead of 99%, and accuracy dropped from 59% to 54%. It also reports regressions on GDPval-AA, where Sol fell about 100 Elo points and Luna about 75.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- agent harness — The scaffolding around a model that turns it into a working agent — the loop, the tools it can call, and the rules for when to stop.
- hallucination — When a model states something false with full confidence — inventing facts, citations, or APIs that don't exist.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.




Checking sign-in…
Loading comments…