Grok Voice Transcribe 2.0 Tops Streaming ASR Accuracy Benchmark
- Source
- ArtificialAnlys
- Date

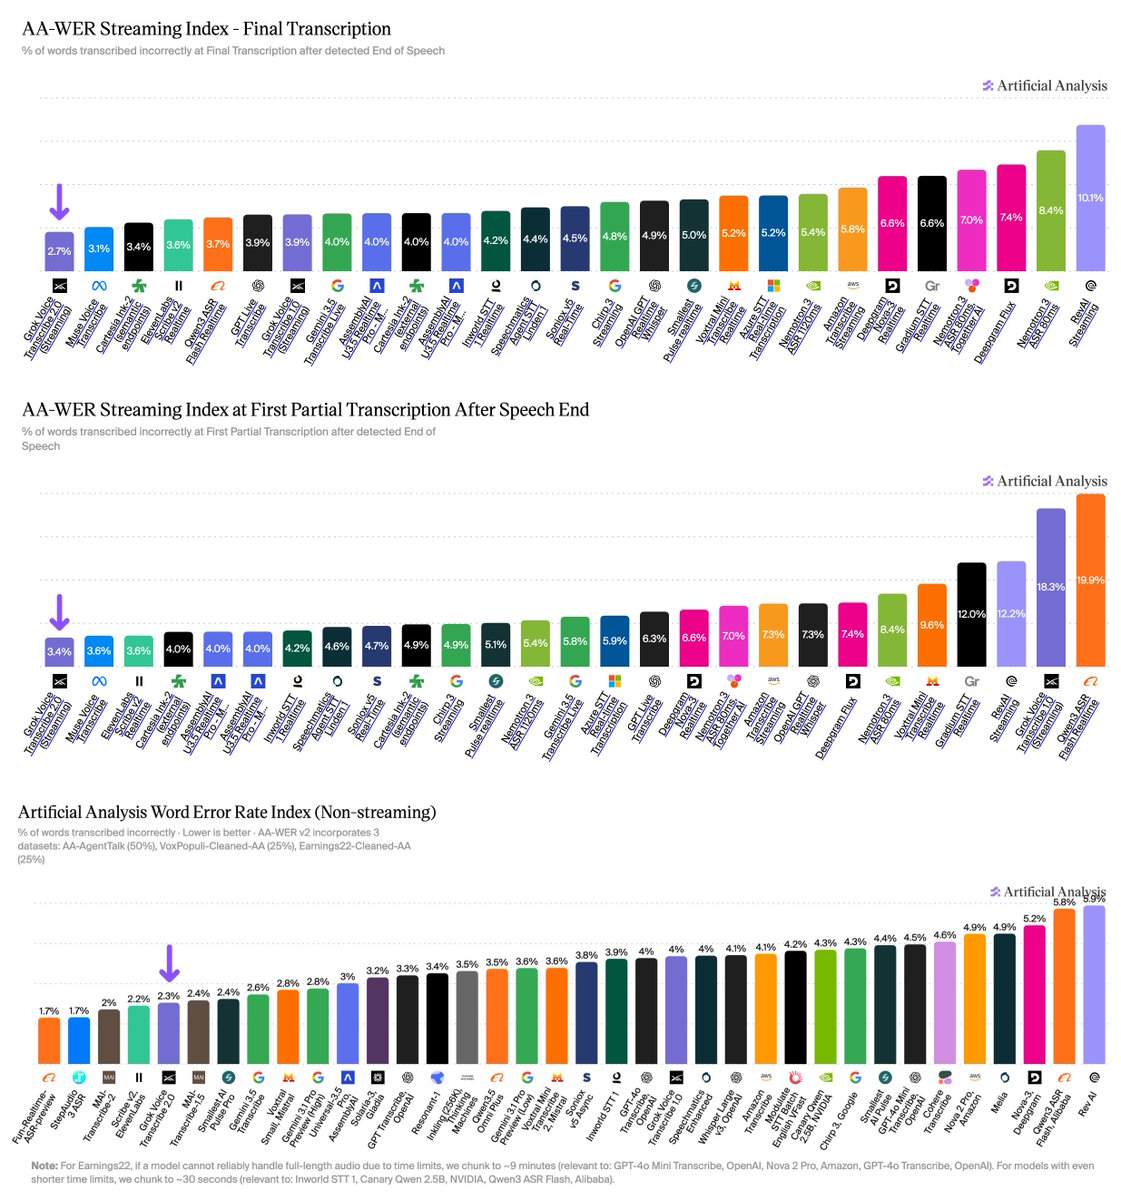
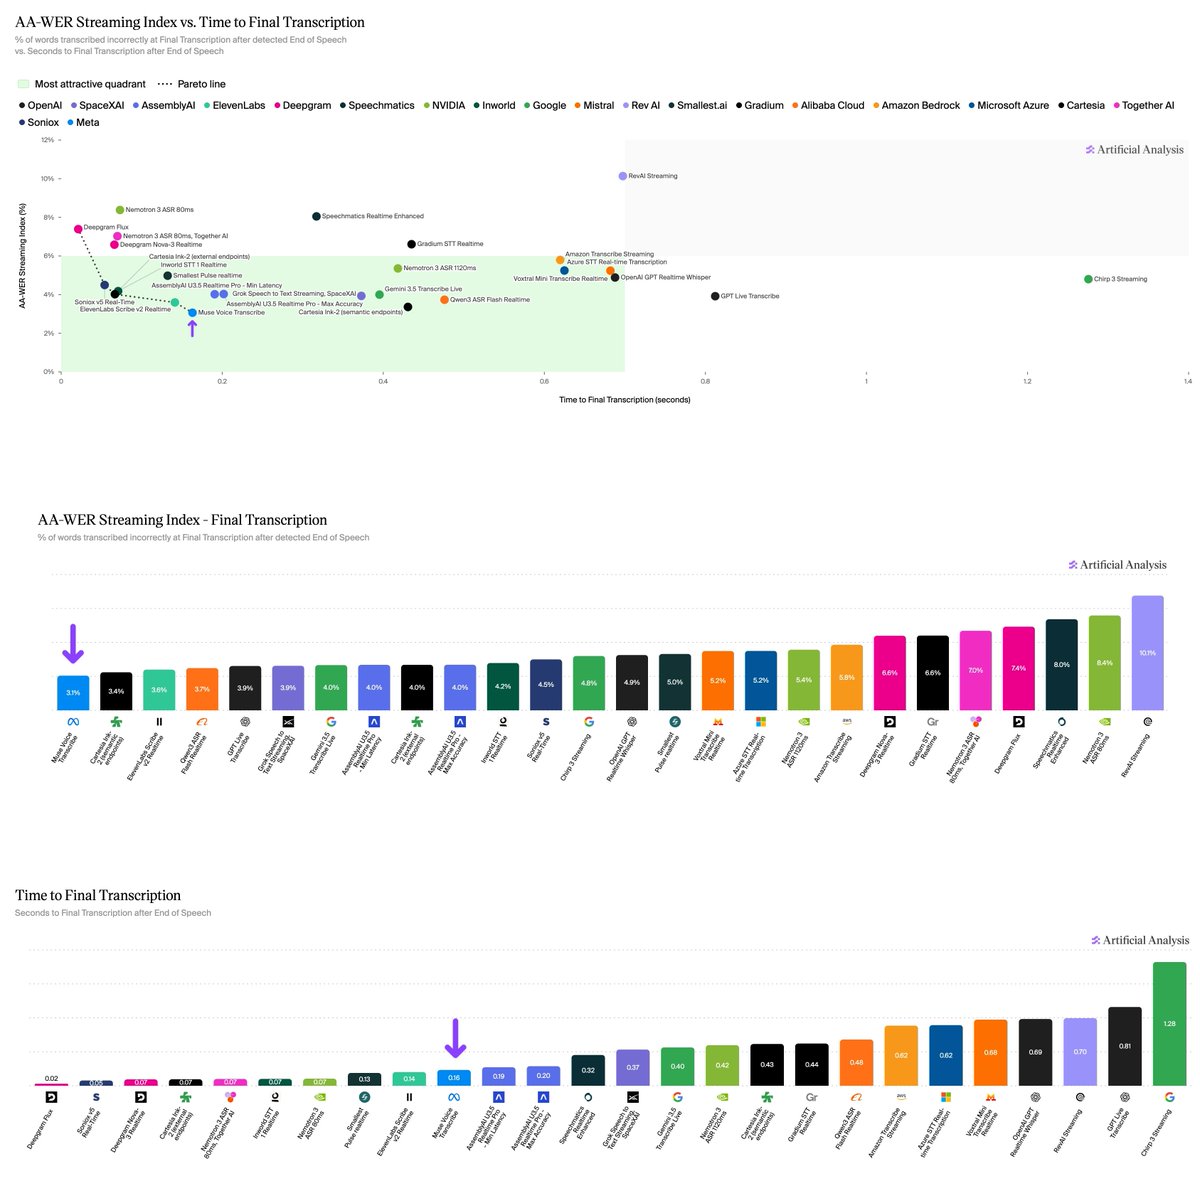
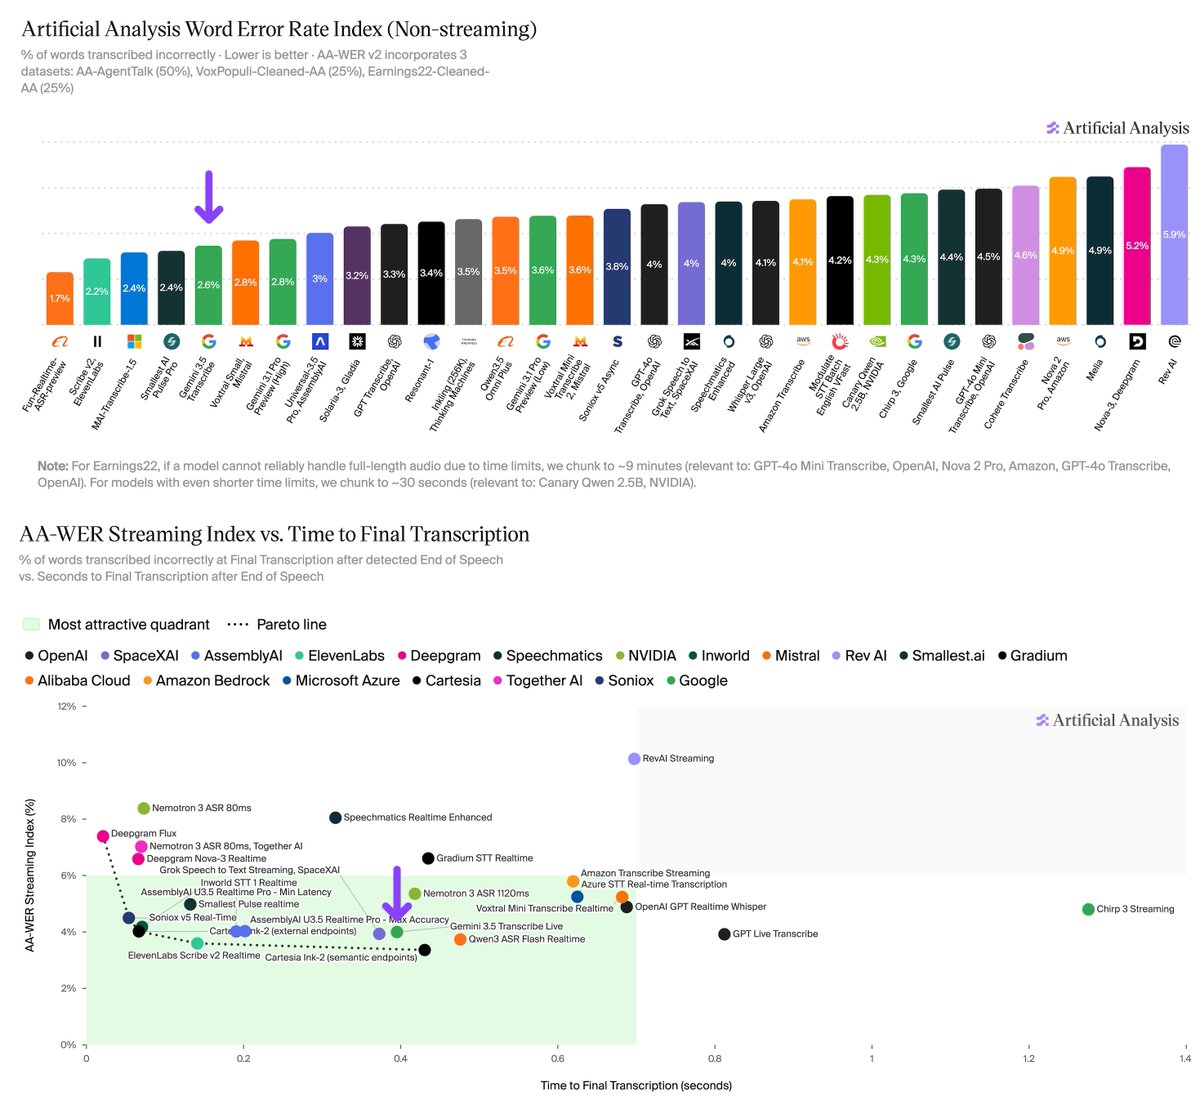
SpaceXAI has released Grok Voice Transcribe 2.0, taking the #1 spot for Final Transcript accuracy and First Partial Transcript accuracy on AA-WER Streaming with 2.7% WER at 0.49s after end of speech Grok Voice Transcribe 2.0 is @SpaceXAI's new Speech to Text model, succeeding Grok Voice Transcribe 1.0 (previously Grok Speech to Text). It improves streaming Final Transcript WER from 3.9% to 2.7% and non-streaming AA-WER from 4.0% to 2.3%. It is available through the SpaceXAI API for both streaming and non-streaming transcription, at the same price as its predecessor. Key takeaways ➤ Final Transcript: Grok Voice Transcribe 2.0 achieves 2.7% WER at 0.49s after end of speech. It is more accurate but slower than Muse Voice Transcribe at 3.1% and 0.16s, and ElevenLabs Scribe v2 Realtime at 3.6% and 0.14s. It is also more accurate, though slightly slower, than Cartesia Ink-2 (semantic endpoints) at 3.4% and 0.43s ➤ First Partial Transcript: The model achieves 3.4% WER at 0.49s, just ahead of Muse Voice Transcribe and ElevenLabs Scribe v2 Realtime on accuracy, both at 3.6%, though slower than both at 0.13s. It is more accurate but slower than Cartesia Ink-2 (semantic endpoints) at 4.9%…
Context
Artificial Analysis reports that SpaceXAI's new Grok Voice Transcribe 2.0 now ranks first for accuracy on its speech-to-text leaderboard, reaching 2.7% word error rate about half a second after a speaker stops talking, down from 3.9% for the prior version, at the same price as before. On Artificial Analysis's broader non-streaming accuracy measure, the model ranks fifth of 59 models tested, behind models from Alibaba, StepFun, Microsoft, and ElevenLabs. The tradeoff Artificial Analysis highlights: Grok Voice Transcribe 2.0 is more accurate than several faster competitors, such as Meta's Muse Voice Transcribe and ElevenLabs' Scribe v2 Realtime, but it also takes longer to return that more accurate transcript, so a product prioritizing the fastest possible response may still prefer a less accurate but quicker model.
- streaming — Sending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.




Checking sign-in…
Loading comments…