MathArena tests agents on open-ended research blog writing
- Source
- x.com
- Date

Can LLMs write interesting and novel blog posts for MathArena? We give four agents 48 hours and a $500 API key to create an interesting MathArena blog post. GPT-6 Astra, GPT-6.1 Sol, and GLM-5.3 produced slop. Opus-5.5 created a good blog post with interesting conclusions.

Context
Jasper Dekoninck, first-listed author of an October 8, 2026 write-up on MathArena, which evaluates AI models on math, describes giving four AI agents 48 hours and a $500 API budget to write a novel, interesting blog post for the site. Each worked in its own repository copy with internet access and deliberately vague instructions.
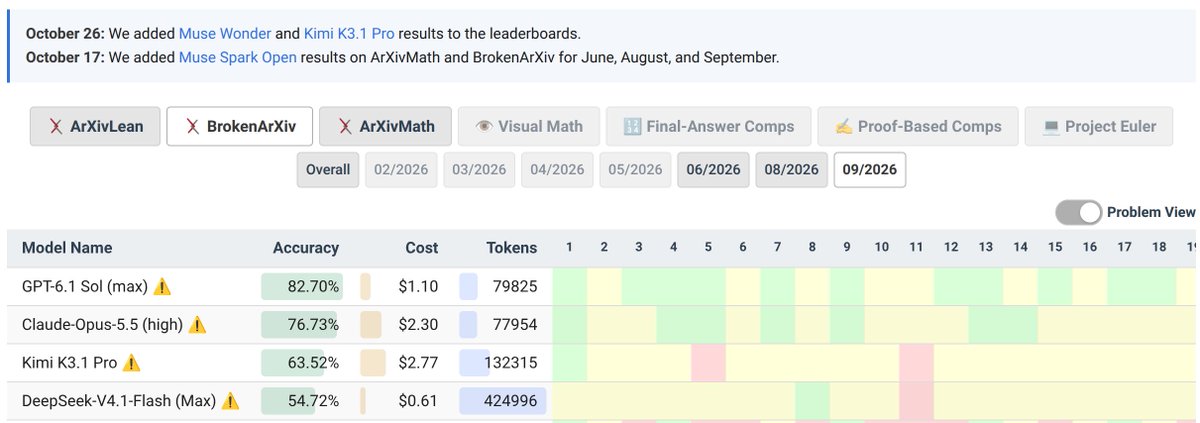
Three authors reviewed every post, two seeing name-hidden versions, and wrote short reviews rather than scores. GPT-6 Astra's and GPT-6.1 Sol's posts were judged off-topic and uninteresting. GLM-5.3's was too long and poorly written. Opus-5.5 built UnBrokenArXiv, a testing whether models wrongly call true statements false. It found Opus-5.5 itself did this most often, and that seven ground-truth statements in the June BrokenArXiv release were false as written or ambiguous. The authors judged it the only post worth reading.
The write-up attributes the OpenAI models' failures to tunnel vision after one interesting output; Opus-5.5 weighed several topics first. With one per model and no numeric scores, this describes four attempts, not a ranking.
Checking sign-in…
Loading comments…