Quantifies fast progress in visual error-spotting and the open weightsA model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.Full definition → lag, informing whether vision agents can guide physical repair and assembly tasks.
Key takeaways · AI-distilled
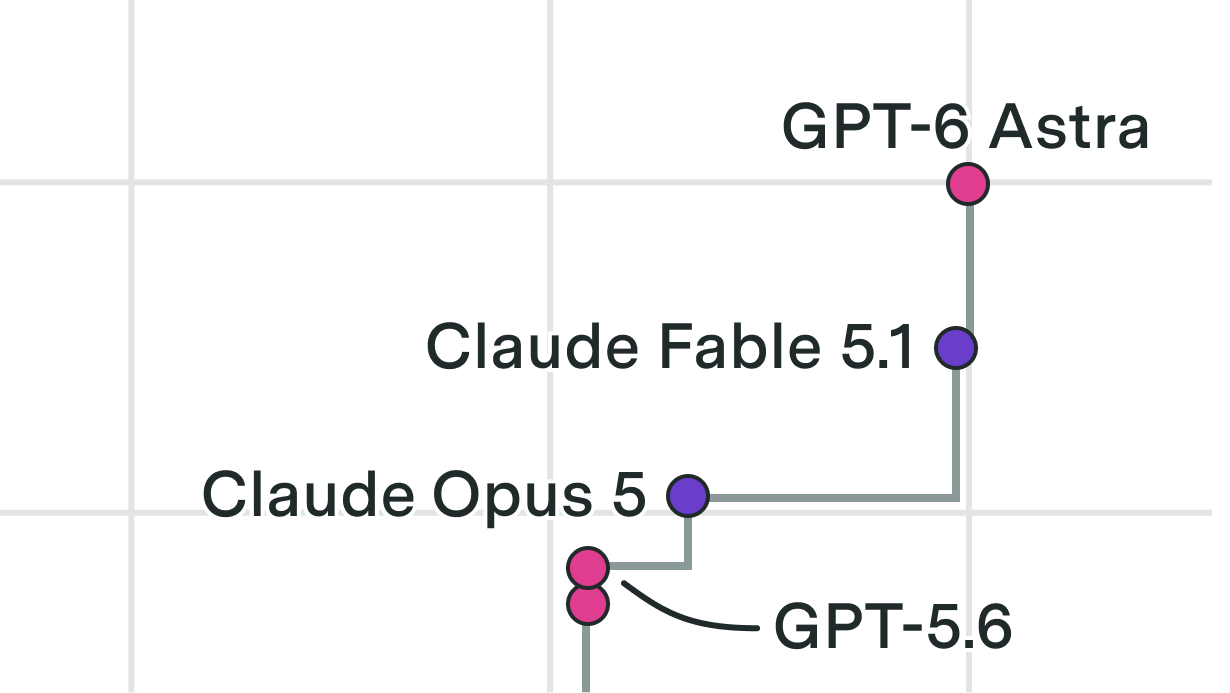
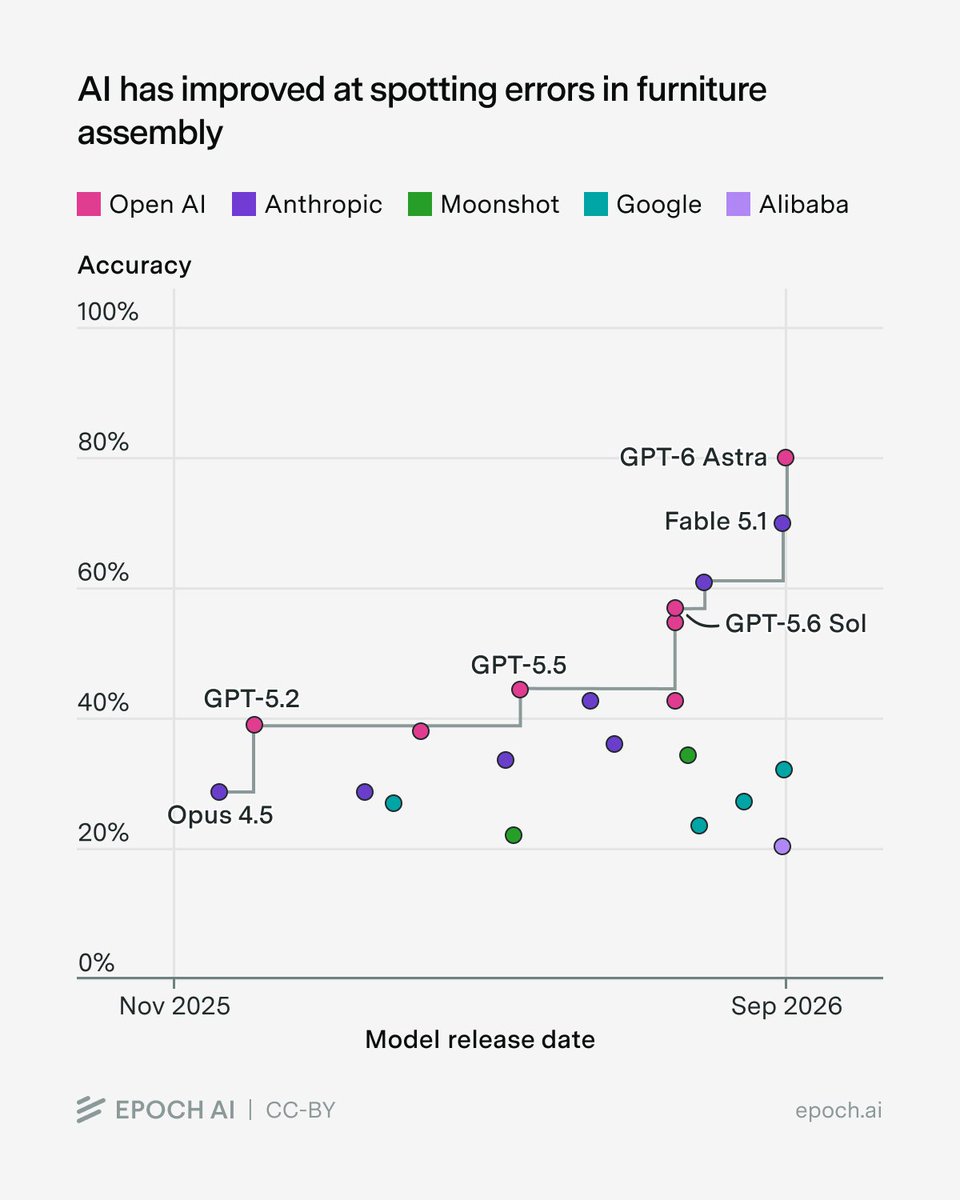
Among models Epoch tested, Claude Opus 4.5 set the November 2025 frontier at 28% (Epoch says it may have been somewhat higher); OpenAI's GPT-6 Astra now leads at 80% and was the fastest evaluated, at a median 3 minutes per photo.
The benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → has 60 photos from three IKEA builds of rising IKEA Complexity Index scores: a shoe rack, bed frame and dresser with estimated human assembly times of 1.5, 3.5 and 5 hours. Models get the assembly manual and image-inspection tools.
To score well, a model must identify every step with a mistake and describe it, or correctly say an image has none. Epoch says it tried to err realistically, often building past mistakes to make them harder to spot. Human performance is not yet measured.
Epoch frames the task as a proxy for tasks like fixing cars or appliances and says very few visual reasoning benchmarks test it, but notes that with only 60 photos from three builds, it is unclear how well results extend to other physical tasks.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.