Sonnet 5.5 nears Opus 5.5 on agentic evals but burns record output tokens
- Source
- Artificial Analysis
- Date
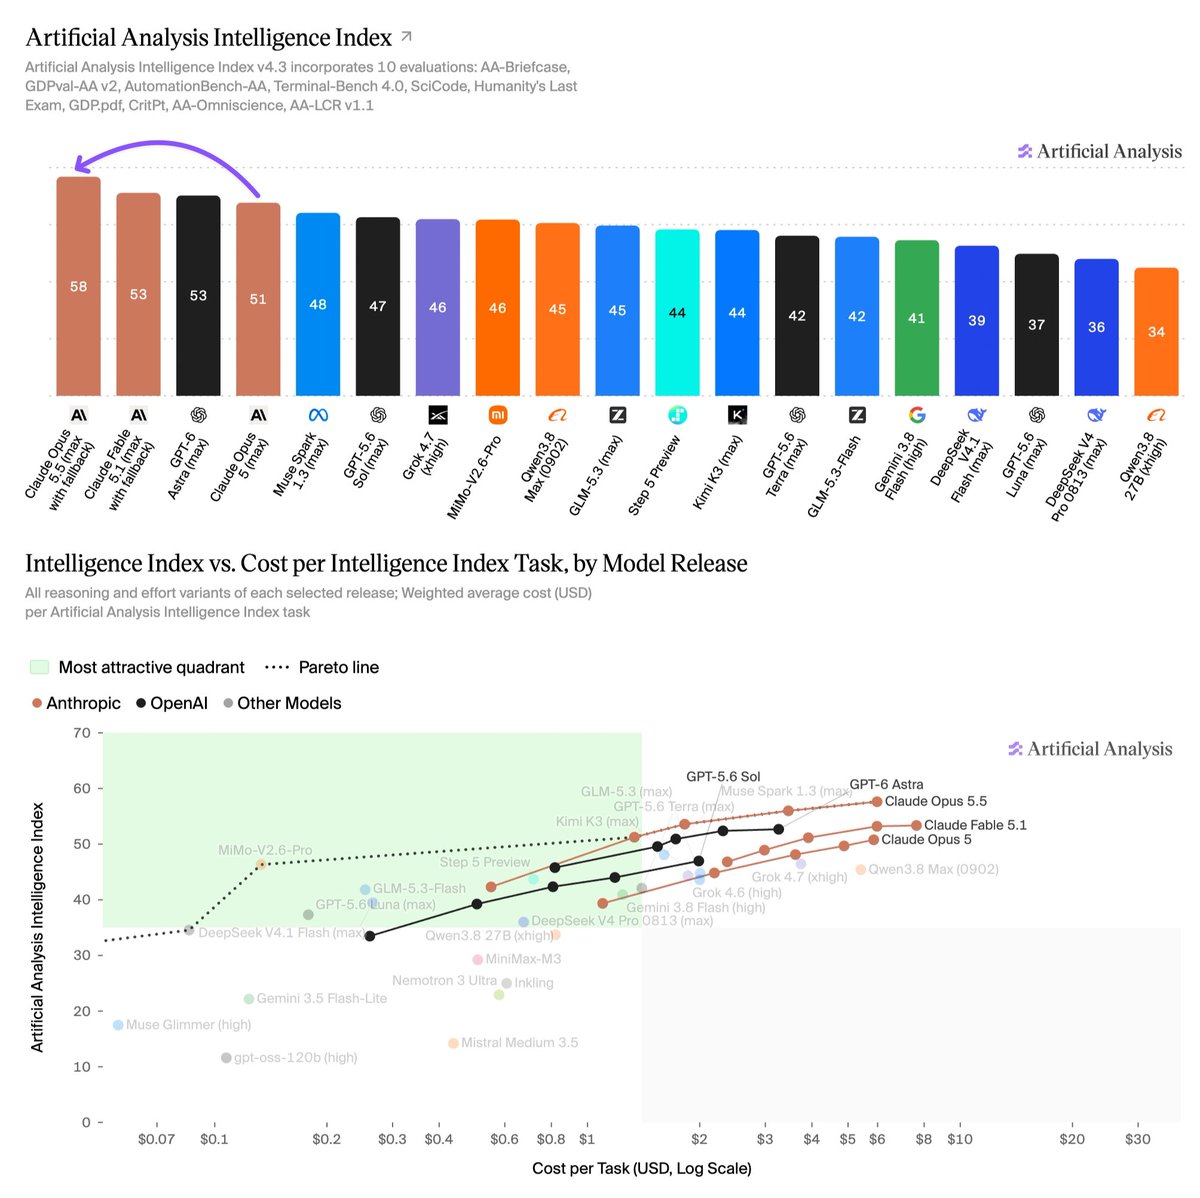
This is a follow-up to yesterday's launch coverage, which reported Anthropic's claim that Sonnet 5.5 finishes tasks with fewer tokens. Artificial Analysis's independent run found the opposite pattern on its suite. Sonnet 5.5 scored 56 on the Intelligence Index and reached parity with Opus 5.5 on several agentic evaluations, but used roughly 60% more output tokens than Sonnet 5, the most the firm says it has measured. That puts cost per task at $7.60, about 50% higher than Sonnet 5 at the same list price.
It repeats the pattern Artificial Analysis found for Opus 5.5 earlier this week, where extra token use offset a price cut. The two measurements can both hold, since token use varies by task and by reasoning setting. Anthropic has published migration and tuning guidance for Sonnet 5.5, and the practical advice is the same either way: compare cost per completed task on your own workload, not the per-token price.

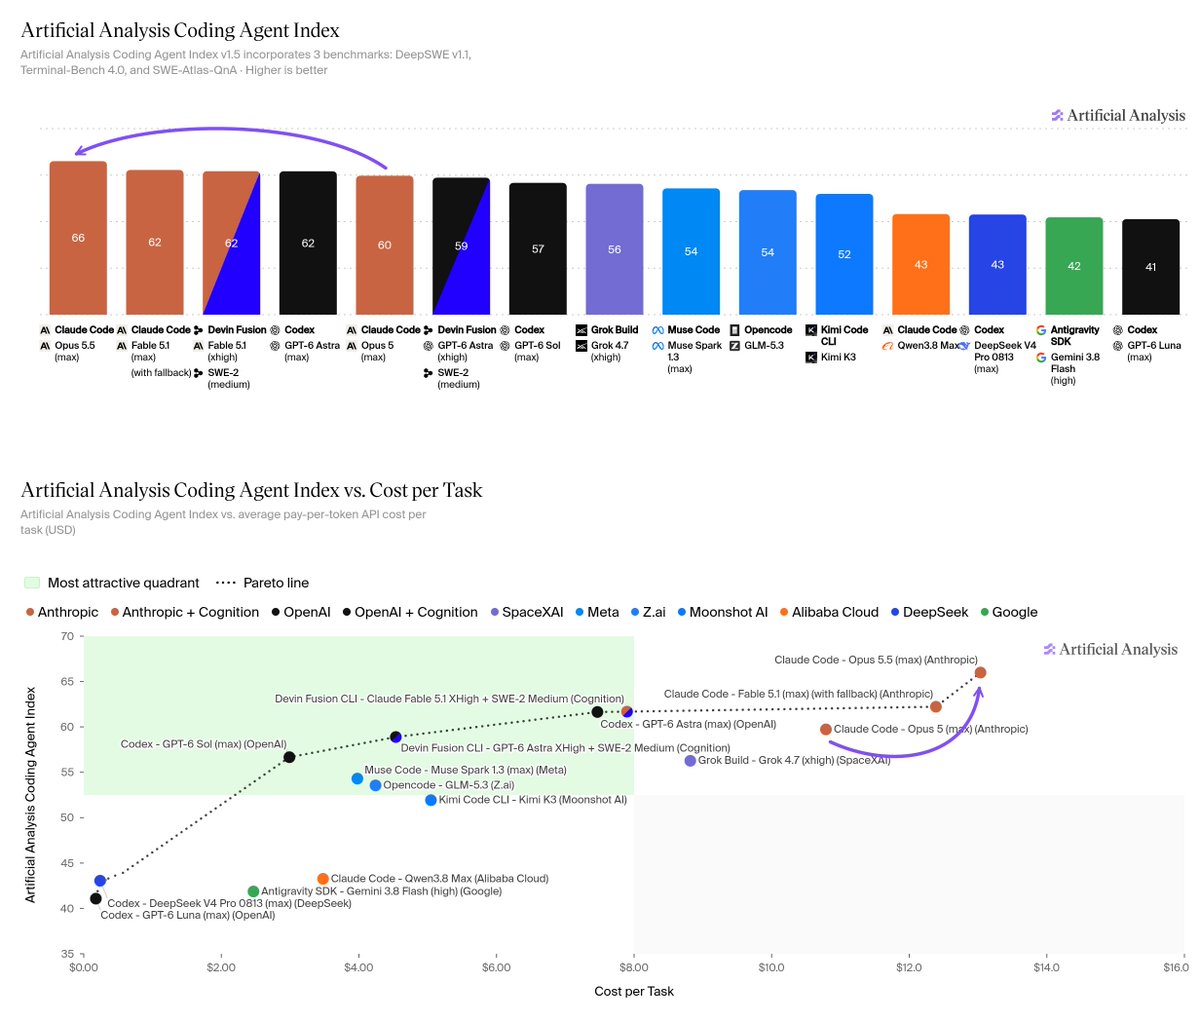
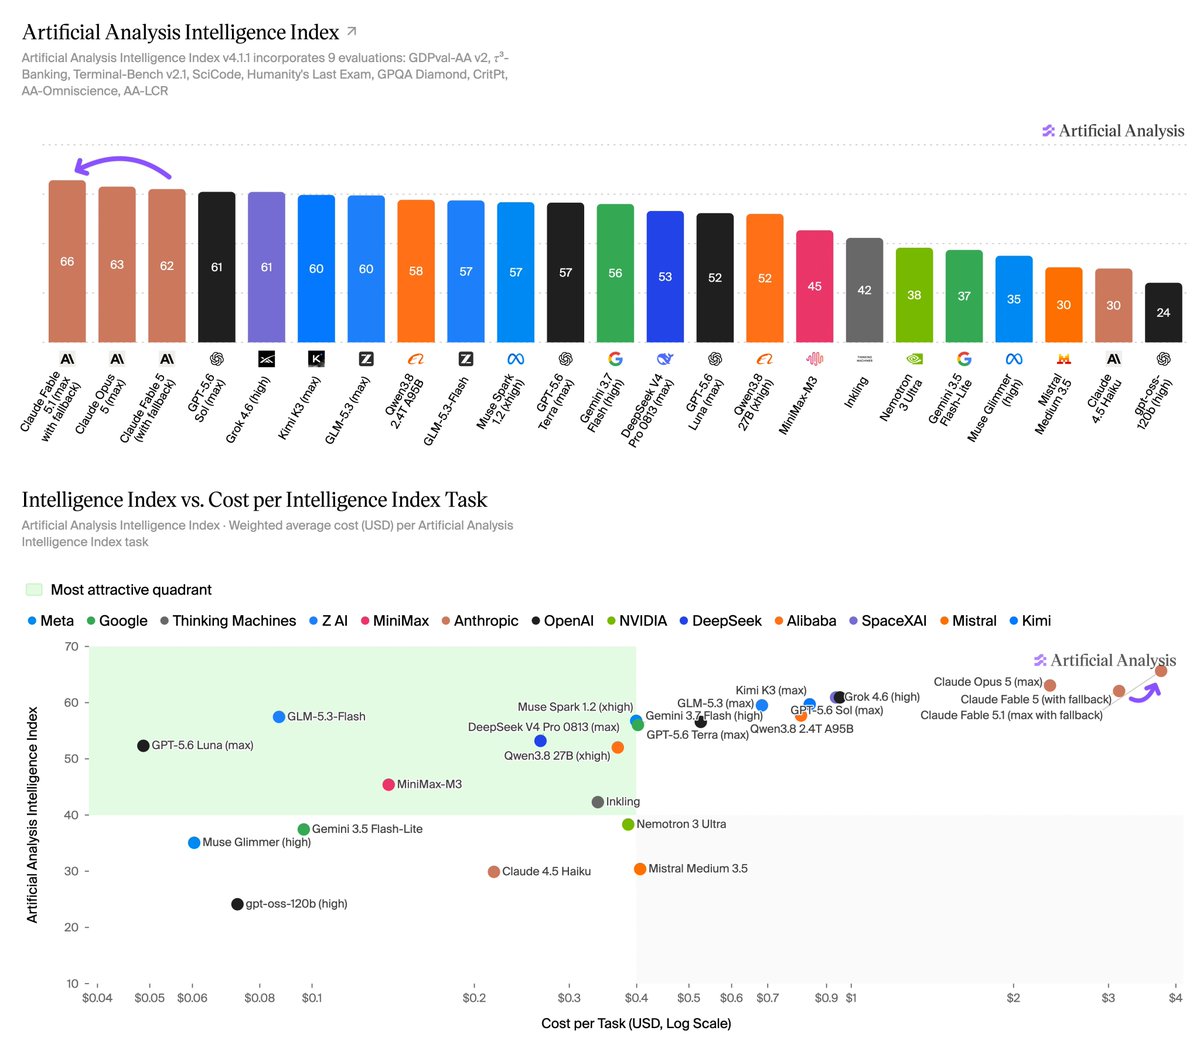
Anthropic has launched Claude Sonnet 5.5: it scores 56 on the Artificial Analysis Intelligence Index, just 2 points behind Opus 5.5 (max), but at the highest Output Tokens per Task we’ve seen With max effort, Sonnet 5.5 gains 18 points over Sonnet 5 and to #2 on the Intelligence Index behind only Opus 5.5 (max). Anthropic has priced Sonnet 5.5 identically to Sonnet 5 at $0.2/$2/$10 per 1M cache input/input/output tokens, however it outputs a higher number of Output Tokens per Task and costs $7.60 per task (~50% higher than Sonnet 5’s Cost per Task) Key takeaways: ➤ Meets leading models on agentic terminal use and knowledge work: in Terminal-Bench 4.0, Claude Sonnet 5.5 reaches 64% against 60% for Opus 5.5 and GPT-6 Astra. On AA-Briefcase (1811 vs 1822 Elo), GDPval-AA (1844 vs 1846 Elo), and AutomationBench-AA (71% vs 70% headline score), Sonnet 5.5 reaches parity with Opus 5.5, albeit with significantly higher token usage to achieve it ➤ Heaviest token use we have measured: at max effort, where it reaches performance nearing that of Opus 5.5, Claude Sonnet 5.5 used ~193k Output Tokens per Intelligence Index Task. This is the highest token use we have measured on around 60%…

- On Terminal-Bench 4.0, Artificial Analysis measured Sonnet 5.5 at 64% versus 60% for Opus 5.5 and GPT-6 Astra, and near parity with Opus 5.5 on AA-Briefcase (1811 vs 1822 Elo), GDPval-AA (1844 vs 1846) and AutomationBench-AA (71% vs 70%).
- At max effort Sonnet 5.5 used about 193k output per Intelligence Index task, the highest Artificial Analysis has measured: about 60% above Opus 5.5 (max) and Sonnet 5 (max), and about 7x GPT-6 Astra (max).
- By Artificial Analysis's cost analysis, Sonnet 5.5 sits off the intelligence-versus-cost Pareto frontier. High effort is its most competitive setting, narrowly behind GPT-6 Sol on intelligence at about the same cost per task.
- Sonnet 5.5 trails Opus 5.5 on factual knowledge (54% vs 66% accuracy on AA-Omniscience) but hallucinates less (47% vs 59%), and sits about 6 points lower on Humanity's Last Exam and SciCode.
- Caveat: the runs used a pre-release deployment with a structured-outputs bug that Anthropic says is fixed for the public release. Anthropic expects minimal change or slightly understated scores, and Artificial Analysis plans to rerun relevant .
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.




Checking sign-in…
Loading comments…