Claude Opus 5.5 tops the Coding Agent Index, at a higher cost per task
- Source
- Artificial Analysis
- Date

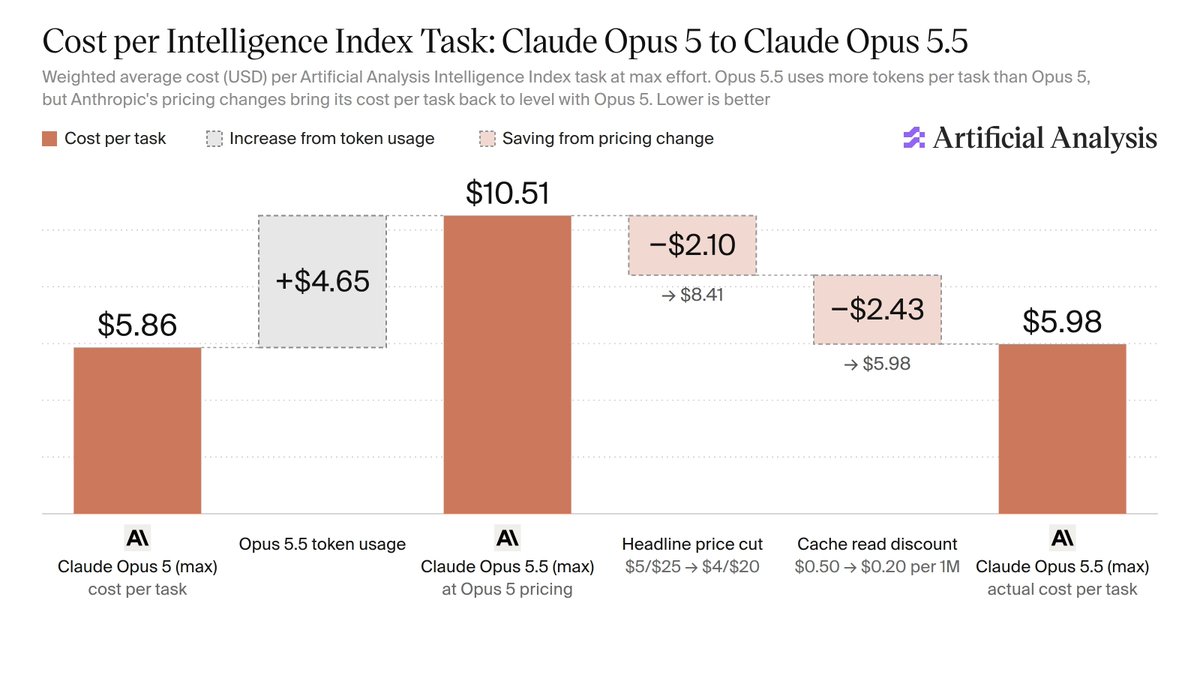
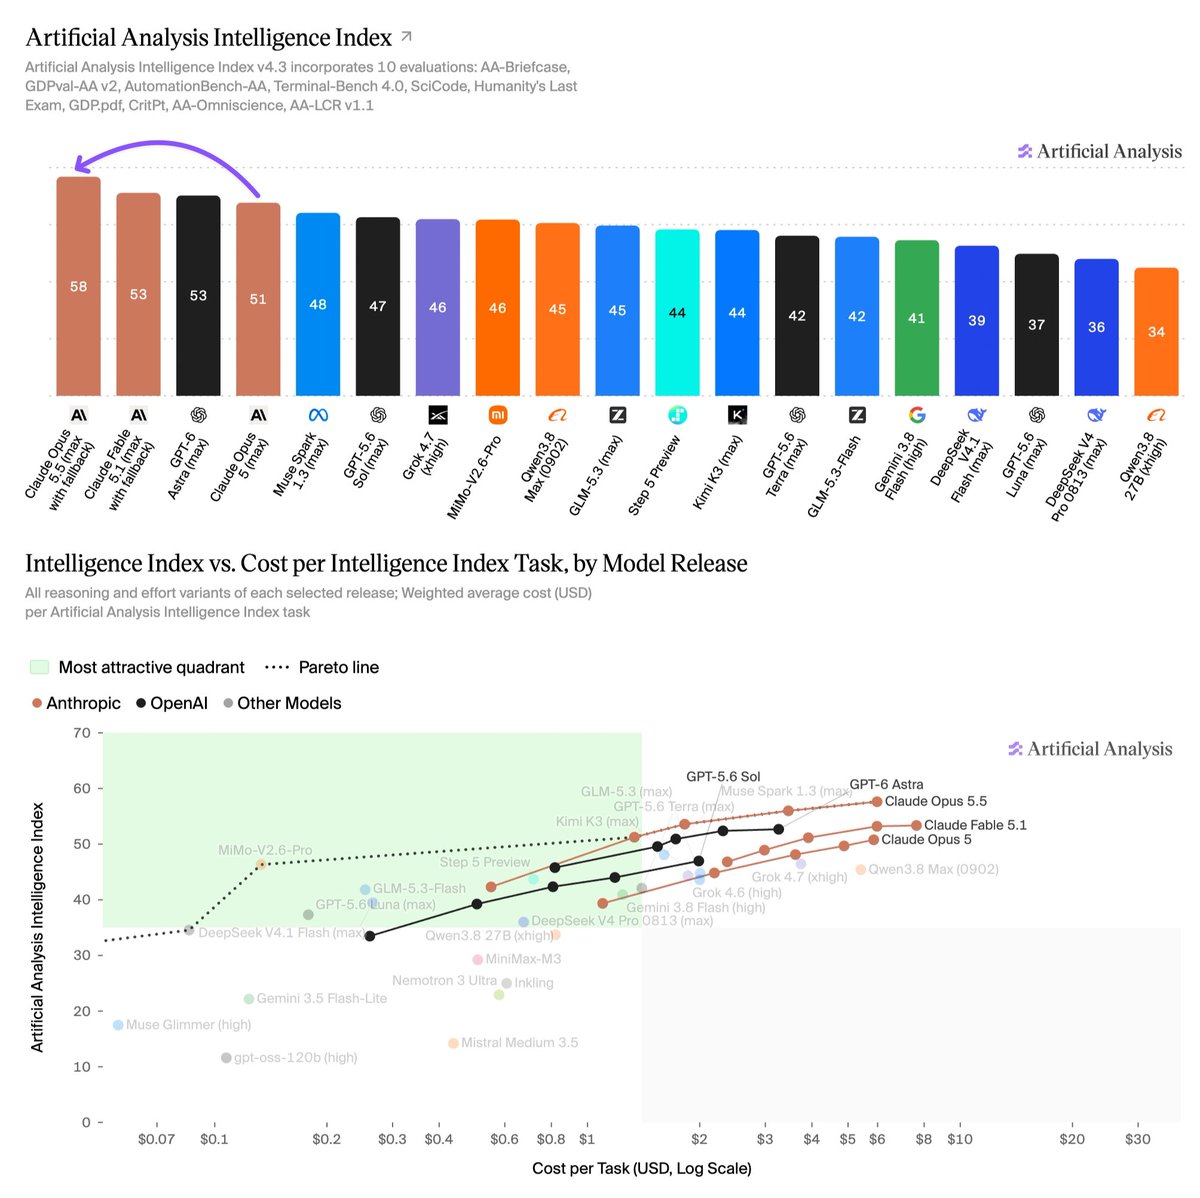
Claude Opus 5.5 is the new #1 in the Artificial Analysis Coding Agent Index, with gains across all three evaluations, though at a higher Cost per Task At max effort in Claude Code, Opus 5.5 scores 66 on the Coding Agent Index, the highest score we have measured. It is up 6 points against Opus 5 (60) and 4 points against Claude Fable 5.1 (62). Anthropic has cut Opus pricing to $4/$20 per million input/output tokens, from $5/$25 for Opus 5, and cache reads to $0.20 from $0.50. Even with those reductions, Opus 5.5’s Cost per Task is $13.04, above Opus 5’s $10.79, because it uses substantially more tokens. Key takeaways: ➤ Improves across all three Coding Agent Index evaluations: Terminal-Bench 4.0 rises to 63.1% from 54.5% for Opus 5, DeepSWE v1.1 to 68.4% from 62.5%, and SWE-Atlas-QnA to 66.4% from 62.1%. The largest gain is on Terminal-Bench, at +8.6 percentage points. ➤ The top score comes at the highest Cost per Task: Opus 5.5’s Cost per Task is $13.04, up 21% from Opus 5 at $10.79. It uses about 15.6 million tokens per task against 11.4 million for Opus 5, including about 2.4× as many output tokens. ➤ Extends the Coding Agent Index vs Cost per Task Pareto frontier: No lower-cost model in our comparison matches Opus 5.5's score. It moves the frontier upward at its high-cost end. Other model details: ➤ Pricing: $4/$20 per million input/output tokens, down 20% from Opus 5. Cache reads cost $0.20 per million, down 60% from $0.50. ➤ Evaluation setup: Claude Code at max effort, measured on DeepSWE v1.1, Terminal-Bench 4.0 and SWE-Atlas-QnA. The Coding Agent Index gives each evaluation equal weight.

Opus 5.5 costs $13.04 per Coding Agent Index task, 21% more than Opus 5 despite lower token prices. It uses 15.6 million tokens per task against 11.4 million for Opus 5, with output rising from about 137k to 333k tokens per task.

Opus 5.5 uses 15.6M tokens per task vs 11.4M for Opus 5 (+37%). Cached input rises from 10.9M to 14.6M, while output more than doubles, from 137k to 333k.

Compare Claude Opus 5.5 with other leading coding agents at: https://t.co/huXZWndXsZ
Context
Artificial Analysis reports that Claude Opus 5.5 is the new number one on its Coding Index, which gives equal weight to Terminal-Bench 4.0, DeepSWE v1.1, and SWE-Atlas-QnA, run in Claude Code at max effort. Opus 5.5 scores 66, up 6 points from Opus 5's 60, with its largest gain on Terminal-Bench 4.0, up 8.6 points to 63.1%. Anthropic cut Opus pricing to $4/$20 per million input/output from $5/$25, and cache reads to $0.20 from $0.50. Even so, Artificial Analysis measured cost per task at $13.04, 21% above Opus 5's $10.79, because Opus 5.5 uses about 15.6 million tokens per task against 11.4 million, including about 2.4 times as many output tokens. It says no lower-cost model in its comparison matches Opus 5.5's score, so the top score comes at the highest cost per task.




Checking sign-in…
Loading comments…