StepFun's StepAudio 3 ASR Tops Speech-to-Text Accuracy Leaderboard
- Source
- ArtificialAnlys
- Date
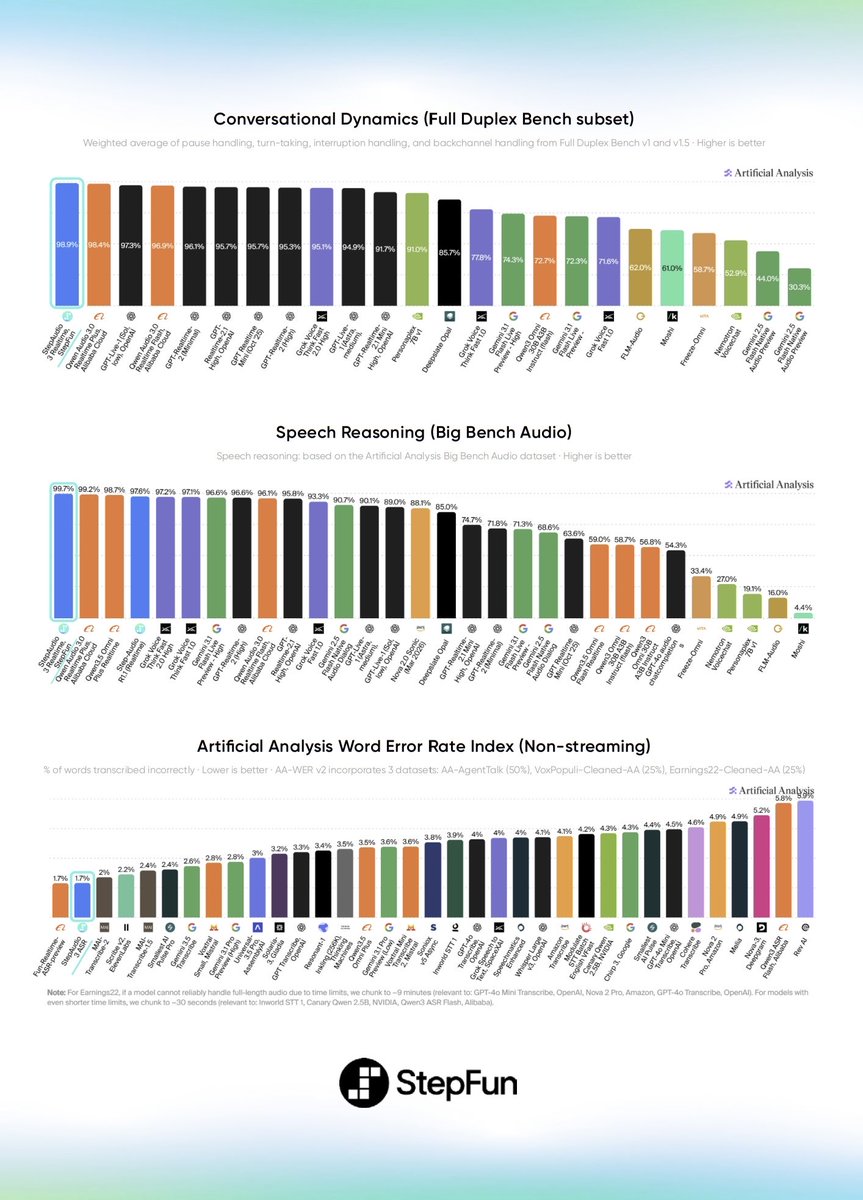
StepFun has released StepAudio 3 ASR, ranking #1 on the AA-WER Index for non-streaming Speech to Text with 1.7% WER, a notable improvement on StepAudio 2.5 ASR (4.7%) StepAudio 3 ASR is StepFun's new Speech to Text model, available through the StepFun API for non-streaming transcription, and the first StepFun model to reach the top of our non-streaming Speech to Text leaderboard. Key takeaways ➤ Accuracy: StepAudio 3 ASR scores 1.7% on the AA-WER Index, effectively tied with Alibaba's Fun-Realtime-ASR-preview at 1.7%. It leads on AA-AgentTalk, our held-out voice-agent dataset, at 1.4%, but trails on long-form Earnings22 calls at 2.8%, where Fun-Realtime-ASR-preview scores 1.8% ➤ Speed: The model transcribes at a speed factor of 88x real time, behind MAI-Transcribe-2 at 374x, Smallest AI Pulse Pro at 285x and Grok Voice Transcribe 2.0 at 154x, roughly level with ElevenLabs Scribe v2 at 84x and Gemini 3.5 Transcribe at 91x, and ahead of Fun-Realtime-ASR-preview at 20x ➤ Price: StepAudio 3 ASR costs $0.40 per hour, or $6.67 per 1,000 minutes, the most expensive of the five most accurate models. MAI-Transcribe-2 and Grok Voice Transcribe 2.0 cost $1.67 per 1,000 minutes and…

Context
Speech-to-text accuracy is usually measured by word error rate (WER), the share of words a transcription model gets wrong compared with a human transcript. Artificial Analysis reports that StepFun's new StepAudio 3 ASR model now tops its non-streaming Speech-to-Text leaderboard with a 1.7% WER, a sharp improvement over StepFun's own prior model, StepAudio 2.5 ASR, which scored 4.7%, and the first time a StepFun model has led that leaderboard.
That top score is effectively tied with Alibaba's Fun-Realtime-ASR-preview, also at 1.7%. Looking at specific conditions, StepAudio 3 ASR leads on Artificial Analysis's held-out voice- dataset at 1.4% WER, but trails on long-form earnings-call audio at 2.8%, where Fun-Realtime-ASR-preview scores 1.8%, meaning its accuracy advantage is not uniform across audio types.
The tradeoff is speed and price: StepAudio 3 ASR transcribes at about 88x real time, slower than several rivals like MAI-Transcribe-2 at 374x, and costs $0.40 per hour of audio, the most expensive of the five most accurate models Artificial Analysis tracks. The reported takeaway is that it buys top-tier accuracy on conversational audio specifically, at a higher per-minute cost than faster competitors.
- streaming — Sending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.




Checking sign-in…
Loading comments…