StepFun's Step 5 Preview matches Kimi K3 at far lower cost per task
- Source
- ArtificialAnlys
- Date
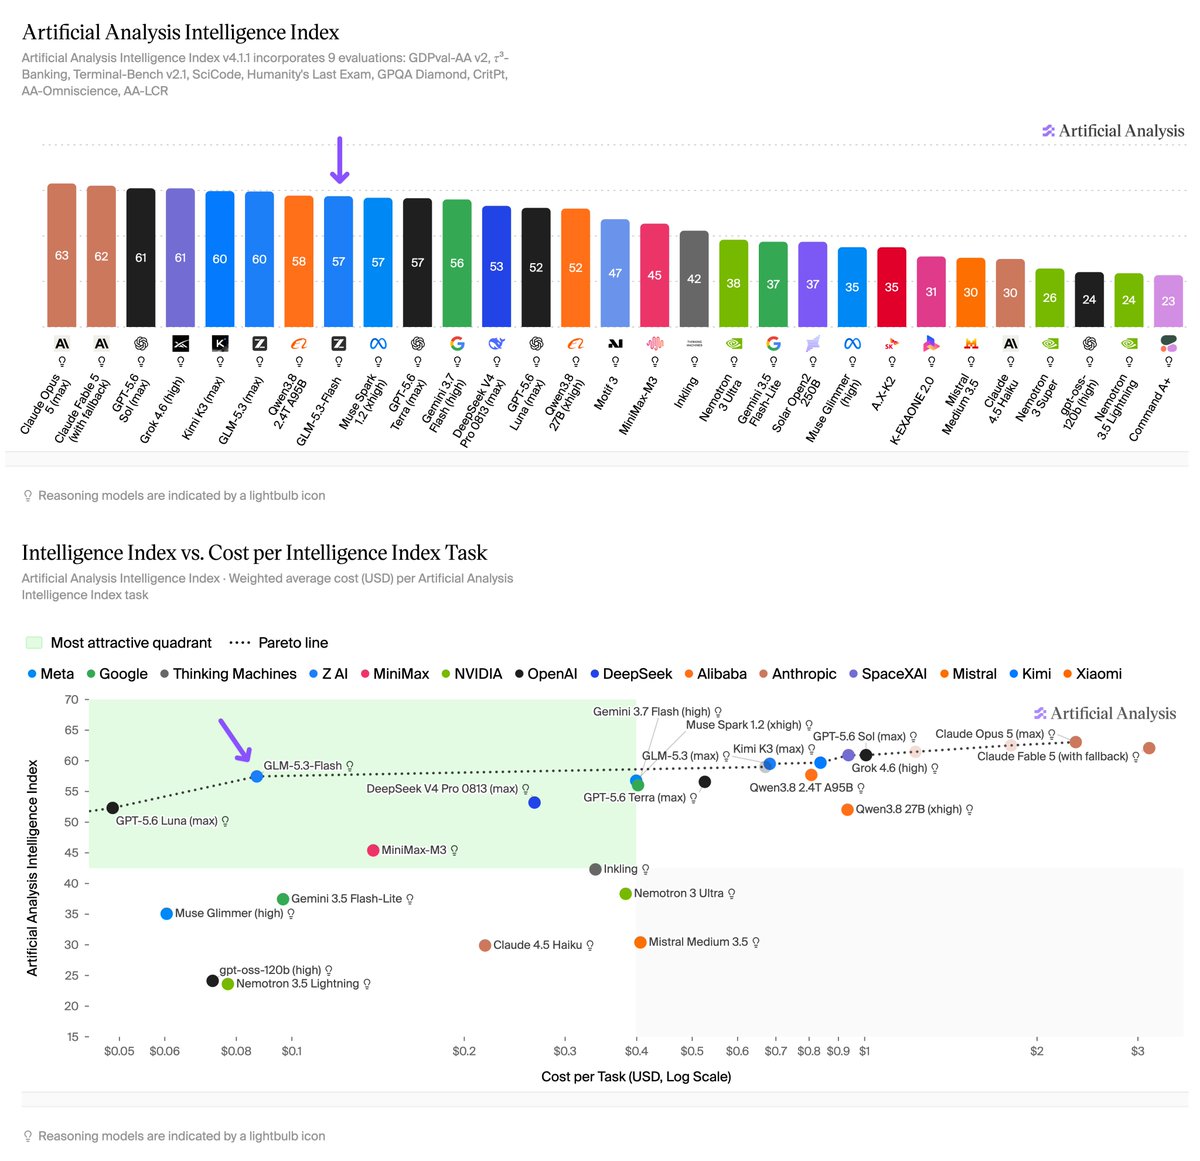
StepFun's Step 5 Preview scores 44 on the Artificial Analysis Intelligence Index, matching Kimi K3 (max) at ~2.8x lower cost per task, but trails peers on agentic evaluations Step 5 Preview is @StepFun_ai's new flagship model, with 600B total and 27B active parameters, succeeding Step 3.7 Flash (released May 2026). It scores 44 on the Intelligence Index, level with Kimi K3 (max) and just behind GLM-5.3 (max, 45) and Qwen3.8 Max (45) Key takeaways: ➤ Step 5 Preview costs ~2.8x less per Intelligence Index task than models at the same score. It costs ~$0.72 per task, against ~$2.00 for Kimi K3 (max) at the same score of 44 and ~$2.01 for GLM-5.3 (max) at 45. This is driven by pricing: at $1/$2.70 per 1M input/output tokens, it is priced below both on input and output. MiMo-V2.6-Pro is the one model that scores higher (46) at a lower cost per task ($0.13) ➤ Frontier reasoning is the standout strength, and where the jump from Step 3.7 Flash is largest. Step 5 Preview scores 46% on Humanity's Last Exam, in line with Kimi K3 (max, 47%), and 21% on CritPt, between Kimi K3 (23%) and GLM-5.3 (max, 19%). Both are up sharply from Step 3.7 Flash: +25 points on HLE and +19 points on CritPt…

Context
StepFun's Step 5 Preview, a 600-billion-parameter model with 27 billion active at any time, succeeding Step 3.7 Flash, scores 44 on Artificial Analysis's Intelligence Index, the same score as Kimi K3 (max) and just behind GLM-5.3 (max) and Qwen3.8 Max. At Artificial Analysis's measured pricing, it costs roughly $0.72 per Intelligence Index task, about 2.8 times less than Kimi K3 (max) at the same score.
Its clearest strength is reasoning: it scores 46% on Humanity's Last Exam and 21% on CritPt, both large jumps over Step 3.7 Flash. Its clearest weakness is agentic work, where it trails peers with a similar overall score, for example scoring 1,566 Elo on Artificial Analysis's GDPval-AA, its primary agentic-performance , against 1,668 for Qwen3.8 Max and 1,646 for GLM-5.3 (max). Weights are not open yet; StepFun says an open-weights release is planned for October 15.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.




Checking sign-in…
Loading comments…