← All IntelIntel / article
Mercury 2 The First Reasoning Model Fast Enough To Pick Up The Phone
- Source
- inceptionlabs.ai
- Author
- Inception
- Date
Context
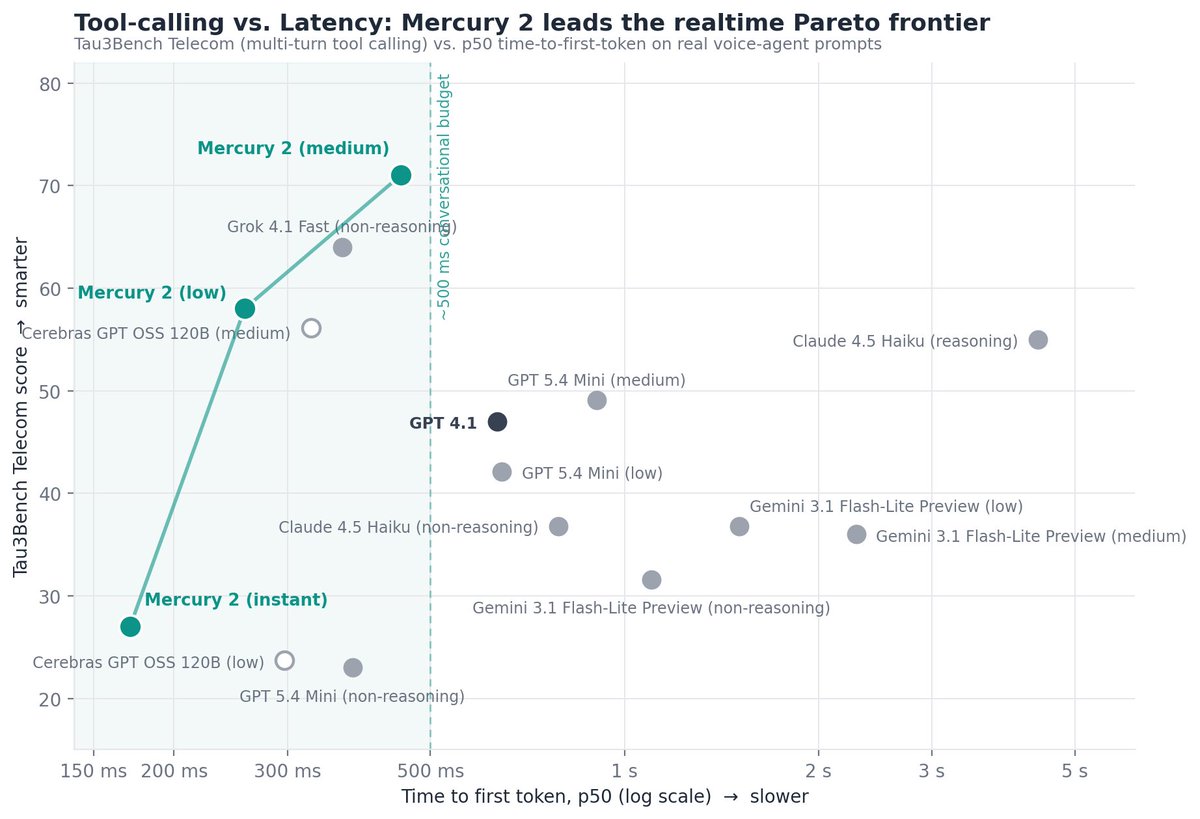
Inception's Mercury 2 account explains how its Mercury 2 , which generates text in parallel, could make reasoning more usable in voice agents. The model repeatedly refines a noisy sequence toward clean text, working on multiple positions in each pass instead of producing every sequentially.
The company reports generation above 1,000 tokens per second and uses a 300-token reasoning trace to illustrate roughly 300 milliseconds of generation time. That calculation concerns the language-model portion of a call. A complete voice system also transcribes incoming speech and synthesizes the response, so this figure alone does not establish the delay a caller experiences.
Terms in this piece · Glossary
Read the source www.inceptionlabs.ai
More from Inception
 postInception ships Mercury Decide update with ZDR and 66k context
 postInception launches Mercury Voice, a diffusion LLM for low-latency voice agents
 postToday, we’re introducing Mercury 2.5, the most capable diffusion LLM on the…
 postInception ships Mercury 2.5 Preview at roughly 1,100 tokens per second
Recommended reads
Comments
Checking sign-in…
Loading comments…