Intel
Page 45
Harness Engineering: Anatomy, Architecture, and Evolution of Coding Agents -- A Source-Code Study of Eleven Systems
A source-code anatomy of eleven production coding harnesses including Claude Code, Codex CLI, Gemini CLI, Aider, OpenHands and OpenCode, mapped onto seven canonical subsystems.
Why it mattersThe closest thing yet to a reference architecture for the runtime around a coding model: loop, tools, context management, safety controls, orchestration and extension surfaces, compared implementation by implementation.
Don't Let the Model Write the YAML: Deterministic, Minimal-Diff GitOps Remediation from LLM-Proposed Field Changes
Measured on real Kubernetes manifests, no text-generation strategy is safe for unattended GitOps remediation.
Why it mattersIf an agent authors your YAML edits, a tolerant patch tool will apply broken changes with no error signal. Emitting a structured field change and letting deterministic code perform the edit removes that failure class.
Can MCP Clients Decide What to Do After Failure? A Result-Only Actionability Audit
An audit of what a client can deterministically infer from a completed MCP failure result alone.
Why it mattersIf you branch on MCP tool failures, isError plus typed fields will not tell you whether to retry, reauthenticate, fix an argument, or switch tools. Recovery logic ends up interpreting prose, which is the fragile path.
GUI-CC: Benchmarking Contextual Consistency of GUI World Models as Agent Environments
GUI world models are usually scored as one-step next-screen predictors, but agents use them as environments.
Why it mattersIf you train or evaluate GUI agents against a generated environment, next-screen accuracy is the wrong metric. Contextual consistency over a rollout is what determines whether the environment is usable at all.
Long-Horizon State Tracking in LLMs: Executing MD5 through a Deep Sequence of Dependent Tool Calls
An evaluation that strips agent tasks down to one variable: can a model carry exact intermediate state across long chains of dependent tool calls?
Why it mattersAgent benchmarks confound instruction understanding with state tracking, so a long run that fails cannot be diagnosed.

Alibaba refreshed its Qwen3.8-Max snapshot: 2.4T parameters, a 1M token context window, and extra post training for coding and long horizon workflows. Live on QwenCloud at $2 per million input tokens and $6 output, with explicit cache hits at $0.17 and implicit at $0.25.
Why it mattersA 1M context model tuned for long horizon agent runs is callable now at $2 per million input tokens, with explicit cache hits at $0.17, which changes the cost math for long running agents.

Arcee's hosted API now serves GLM-5.3 and GLM-5.3-Flash, extending a catalog it opened two weeks earlier beyond its own Trinity line to DeepSeek, Kimi and Inkling. All of them sit behind a single endpoint and are callable from its nac agent for long-running, hands-off work.
Why it mattersOne endpoint now covers several open-weight families, so you can move between GLM, DeepSeek, Kimi and Trinity without changing auth or clients, including from the nac agent for long-running jobs.

SemiAnalysis walks the TCO math behind Nvidia cutting Rubin Ultra from HBM4E 12-Hi (384GB) to HBM4 8-Hi (192GB): memory had climbed to roughly 40% of capital cost, the cut more than halves HBM spend to about 28%, and the savings shift into scale-up optics on the NVL576 SKU.
Why it mattersMemory pricing is now dictating flagship AI hardware specs, so per-accelerator capacity growth can stall even as demand rises. Cost and capacity planning should assume tighter HBM supply and supplier pricing power, not cheaper memory.
GLM-5.3 is 50% off through DigitalOcean on AI Gateway
Vercel is running GLM-5.3 at 50% off on AI Gateway through September 8 in partnership with DigitalOcean.
Why it mattersGLM-5.3 runs at half price on AI Gateway until September 8, and the promo model id stops serving when the window closes. Pinning DigitalOcean in gateway provider order keeps the discount route without hardcoding an id that will disappear.
Gemini 3.8 Flash now available on AI Gateway
Gemini 3.8 Flash is live on Vercel's AI Gateway at half price through December 31.
Why it mattersA 1M context Flash model with thinking on by default, at half price through December 31, reachable from Claude Code, Codex, Cursor and other agents through a single gateway model string.
Muse Spark 1.3 now available on AI Gateway
Meta's Muse Spark 1.3 is live on Vercel's AI Gateway with a 1M-token context and text, image and PDF input.
Why it mattersThe contributor tier serves identical Muse Spark 1.3 weights at roughly a twelfth the input cost and a twentieth the output cost, in exchange for Meta training on your inputs and outputs.
Gemini 3 8 Flash
Artificial Analysis evaluates Gemini 3.8 Flash.
Why it mattersGemini 3.8 Flash gains 3 index points but costs about 40% more per task because it uses more tokens at the same per-token price. Per-task cost, not token price, is what to compare.
River Vulnerability Remediation
Shopify describes River, its Slack-resident AI agent, autonomously reconciling security findings with live code, drafting and updating fixes, pulling in engineers only for judgment calls.
Why it mattersRiver validates fixes against current code, updates patches automatically, and confirms remediation at the repo head after merge, cutting Shopify's vulnerability backlog ~70% in 11 days.

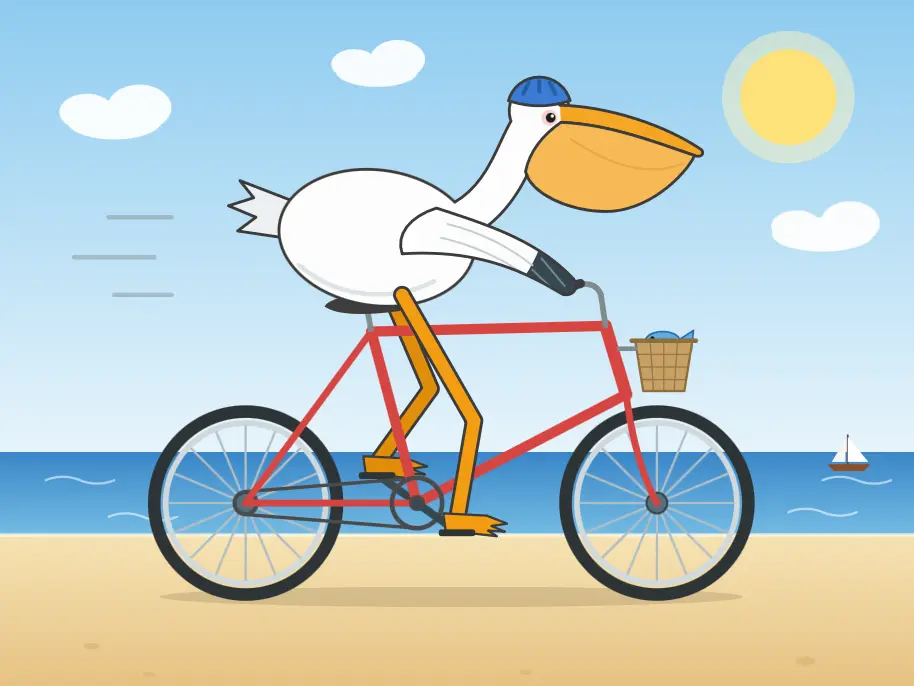
Claude Fable 5.1 made me a really nice animated pelican
A hands-on pass at Fable 5.1's five reasoning levels, including a llm-anthropic fix for missing reasoning traces and a mystery where low and medium return none, set against Anthropic's headline 52.6% on the new Terminal-Bench-Science 0.1 benchmark.
Why it mattersWithin-family comparisons at different reasoning efforts are the useful signal now, and Fable 5.1's low and medium settings appear to record no reasoning traces, which matters when choosing an effort level against cost.

Fable 5.1 is generally available in the GitHub Copilot app, CLI and VS Code, with GitHub citing long running coding tasks and deep codebase research. Unlike other Claude models in Copilot it requires data retention by default so Anthropic's safety classifiers can run.
Why it mattersIf your organization depends on zero data retention in Copilot, Fable 5.1 breaks that assumption by default and the carve-out is temporary and enterprise only.

OpenAI's CEO says Astra has been finished training for a while and launches soon, described as a step forward in both capability and alignment, and that releases after it are being paced deliberately so safeguards keep up with capability.
Why it mattersAstra is imminent, and OpenAI says models after it are being slowed on purpose for alignment work, which changes how you time plans that depend on the next capability step.

Claude Fable 5.1 Is INSANE – Hands-On With the BEST Model Yet!
A long hands-on evaluation of Claude Fable 5.1 run across browser OS control, C++ game development, 3D CAD modeling, frontend builds.
Why it mattersA task by task independent read on where Fable 5.1 holds up on real coding work, from C++ games to CAD to browser control, including what a session actually costs.
LIVE From CrowdStrike's Fal.Con 2026 | George Kurtz, Michael Sentonas, Daniel Bernard & Justin Boitano

Ai2 applied item response theory to results from 100 models across 16 benchmarks and 34K questions. Two latent axes emerged unsupervised, reasoning and safety. BBQ separates models mostly on reasoning, ToxiGen gives weak signal on either, and the strongest 10% of items reproduce full rankings.
Why it mattersSome safety benchmarks are largely scoring reasoning ability, so eval names can misdescribe what a number means. Keeping only the most informative 10% of items reproduced nearly the same model ranking, which cuts eval cost substantially.
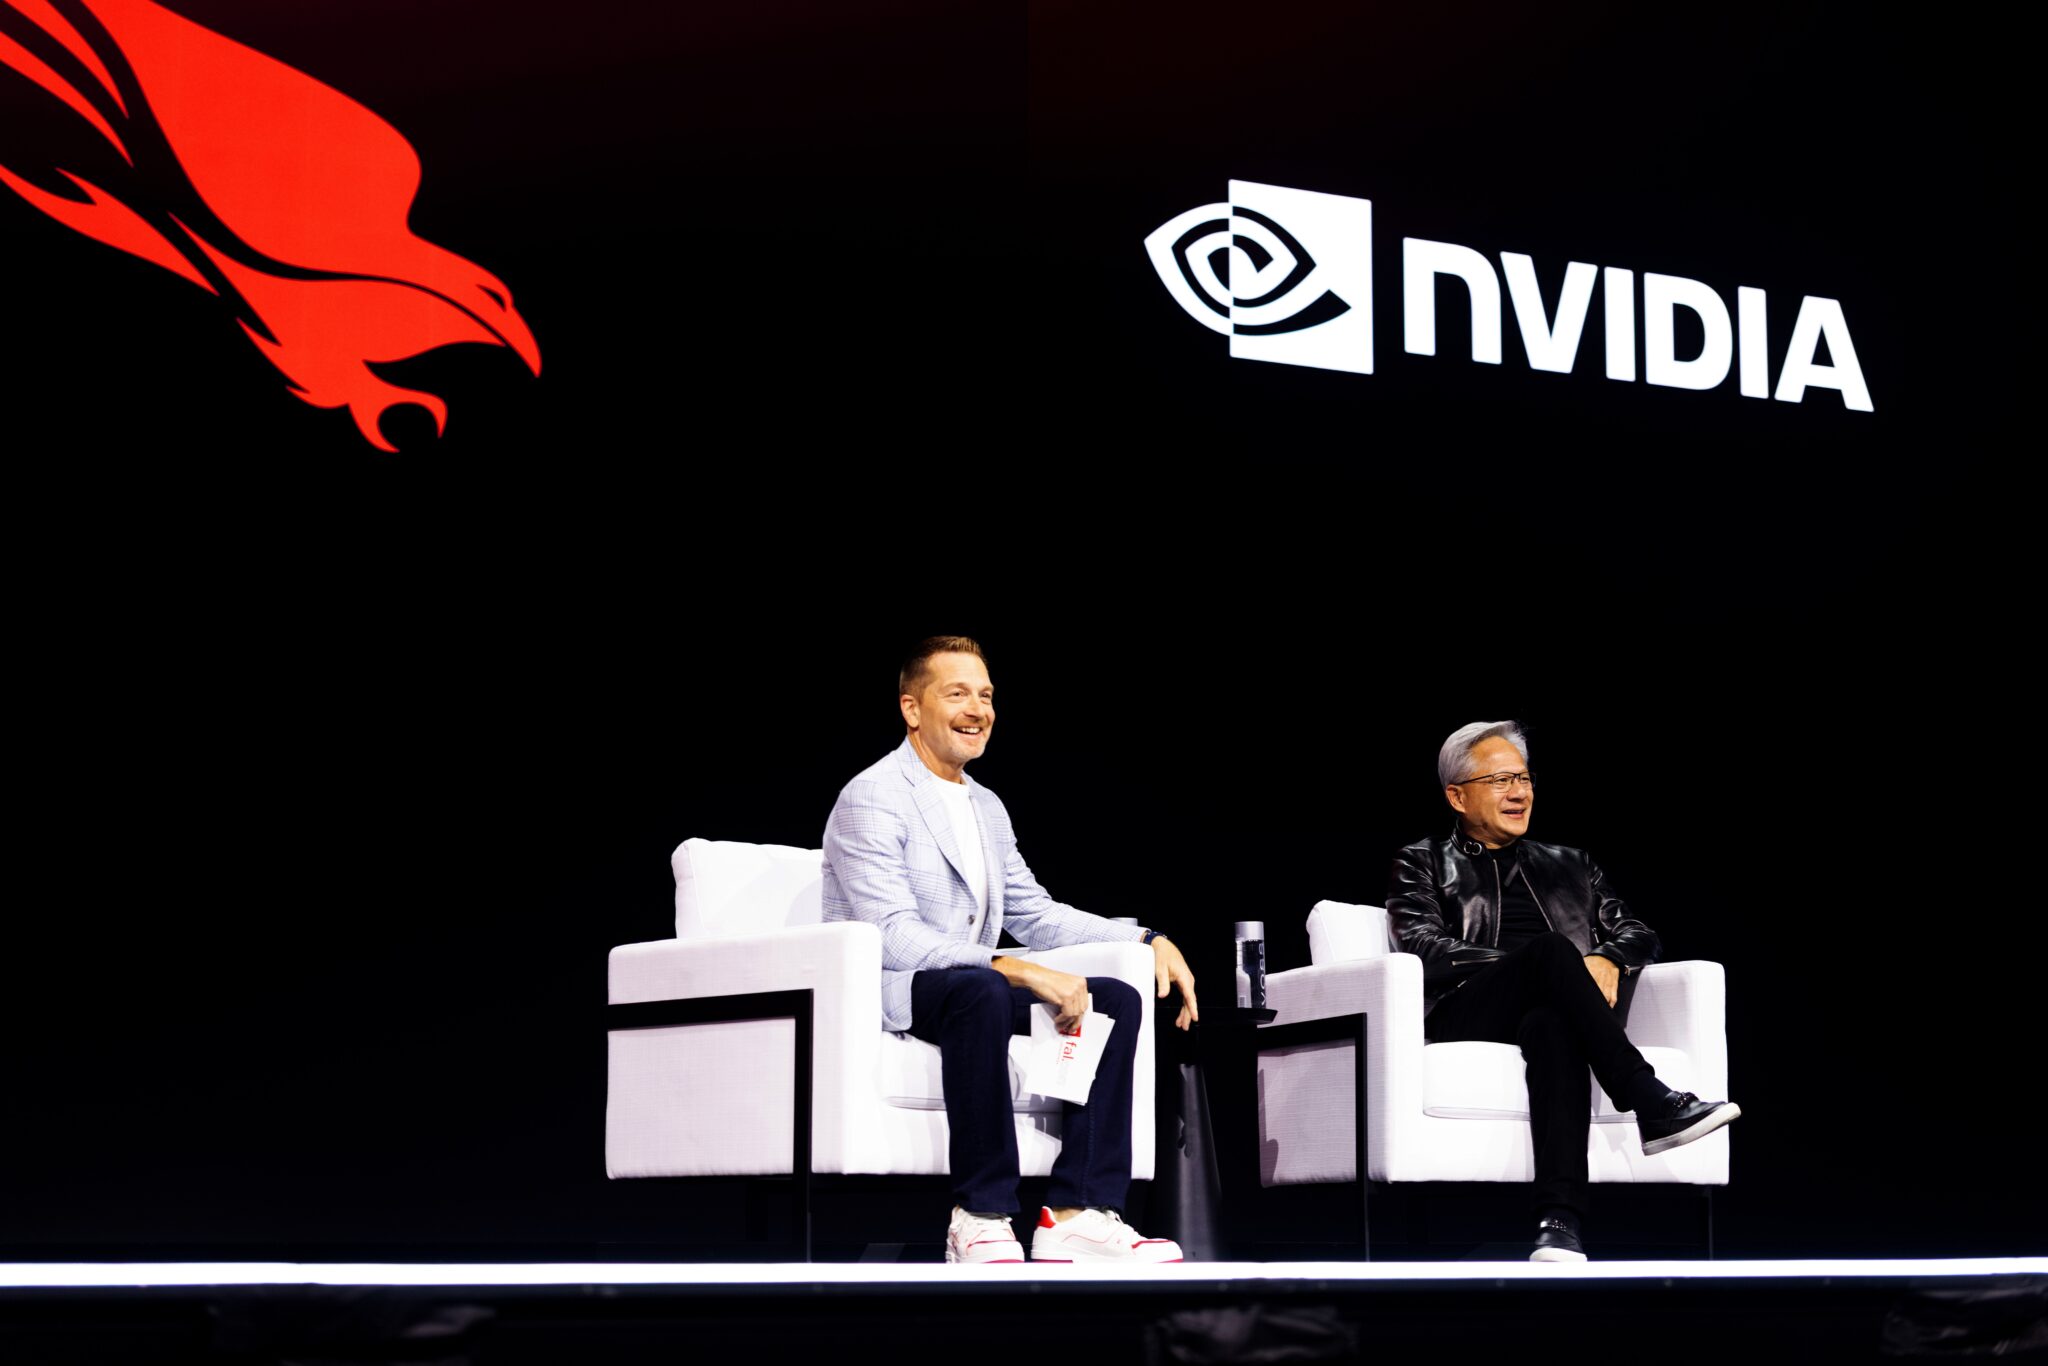
NVIDIA and CrowdStrike Strengthen Agentic Cybersecurity Frontier
CrowdStrike announced SafeMind at Fal.Con 2026, an agentic security system where purpose-built offensive models and NVIDIA Nemotron based defensive models improve against each other in a continuous loop.
Why it mattersDefensive tooling is moving to agent versus agent architectures. SafeMind trains offense and defense models against each other continuously, and Guardian extends runtime protection to the AI agents you deploy.
SemiAnalysis works through Korea's trillion-dollar sovereign AI program: a state-run model tournament that knocked out Motif-3, the strongest non-Chinese open source model, why Nvidia benefits from open weights, and what the buildout means for SK Hynix and Samsung.
Why it mattersKorea's sovereign AI spend shapes who supplies memory and where open weight models come from. Motif-3's elimination narrows the non-Chinese open source field builders can choose from.

Beyond the Lethal Trifecta: Agentic Commerce on the Open Internet — David Levine, Kiduna Club
A DUNA registered in West Virginia under a day-old statute gives an organization of agents legal standing to own property, contract, and bank.
Why it mattersAgents acting outside walled platforms need an accountable identity, and a DUNA supplies a legal entity that can contract, bank, and be sued, with the caveat that distributing profits to members turns memberships into securities.

Ahead of Astra's release, OpenAI says the model reaches the Critical cybersecurity threshold in its Preparedness Framework, and is publishing how it evaluated the model and how safeguards were advanced to match the capability jump.
Why it mattersThe first model OpenAI rates Critical for cyber capability arrives with matching safeguards, which sets expectations for access controls and usage limits on security adjacent work.
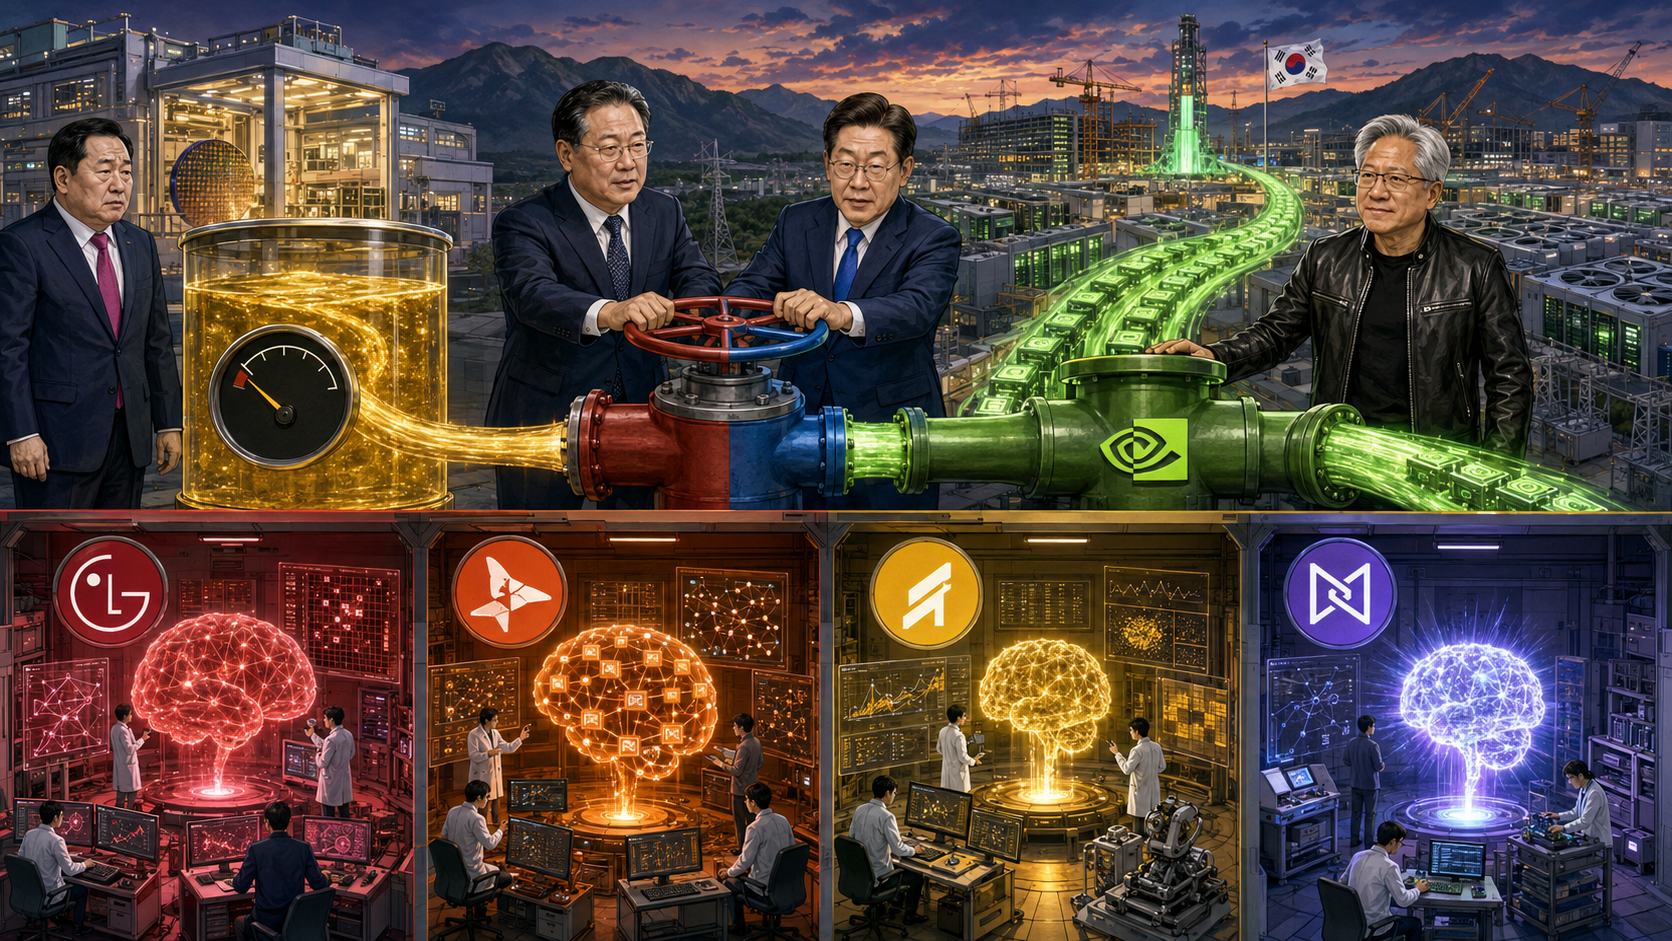
Korea’s Trillion-Dollar Sovereign AI Investment: Nvidia Wins, Hynix Loses
An argument for why governments are funding sovereign AI.
Why it mattersDependency risk on frontier APIs is now a planning input: releases have already been delayed by policy, and open weight licenses are adding revenue thresholds that hit model as a service businesses.

Sutskever argues GPU neoclouds have weak security relative to frontier labs, which makes them the obvious place a rogue self-replicating agent would go for compute. His ask: companies with strong cyber models should help neoclouds harden their infrastructure.
Why it mattersNames a threat model for agent infrastructure where the compute host, not the model, is the weak link. If you run agents on neocloud capacity, its security posture becomes part of yours.

Artificial Analysis puts Fable 5.1 at 66 on its Intelligence Index, the highest it has measured, with 59.1% on HLE and 91.4% on Terminal-Bench v2.1. Output token use of about 1.7x Fable 5 pushes cost per task to $3.76 even after the cache read cut saves roughly $1.40.
Why it mattersThe 75% cache read cut does not make Fable 5.1 cheaper per task; higher output token use puts it 20% above Fable 5 at $3.76. The xhigh setting scores 65 for about a dollar less than max.

The End of the Static Screen: Architecting Intent-Driven UX — Gus Iwanaga, commercetools
A commercetools engineer shows why handing a model a component catalog produced four different sales-report layouts, then walks through the middle path his team built.
Why it mattersLetting a model compose UI from a component catalog produces nondeterministic layouts you cannot ship. Emitting a UI spec against a component schema keeps intent-driven layout while the design system stays enforced.
Claude Fable And Mythos 5 1
Anthropic ships Fable 5.1 alongside the restricted-access Mythos 5.1, both aimed at long-horizon coding and knowledge work.
Why it mattersA new frontier coding model with roughly 25% lower typical token cost, up to 45% on agentic work, 60% fewer false-positive cyber blocks, and vulnerability discovery now allowed though exploit development is not.

Agent Spending Without Controls — Rodrigo Coelho & Pranav Maheshwari, Edge & Node
Two terminals run the same contact-lookup prompt: only the one carrying a payment skill file buys the metered endpoint and returns an answer.
Why it mattersUseful MCP servers are unlikely to stay free, so an agent's ceiling becomes what it can pay for, and counterparties arriving as bare wallet addresses push sanctions screening into the transaction authorization path.
Enterprise Frontier Safeguards
Anthropic's Enterprise Frontier Safeguards store session data in customer-controlled cloud infrastructure while keeping the cross-session misuse detection that 30-day retention was introduced for.
Why it mattersIf retention policy blocked your Claude deployment, EFS keeps session data in your own cloud while preserving cross-session misuse detection, and eligible customers get zero data retention on Fable 5 and 5.1 until it ships.

Perplexity Computer now runs Claude Fable 5.1 for Pro and Max subscribers, and the company reports it first in its August WANDR evaluation at 0.601 and $12.76 per task, a 21% higher score and 37% lower cost than Fable 5.
Why it mattersA third-party agent evaluation with cost attached: Fable 5.1 scores 21% higher than Fable 5 at 37% lower cost per task, which is directly useful when picking a model for long agent runs.
Codex bundles LibreOffice
OpenAI's Codex desktop app quietly carries a 1.7GB private runtime.
Why it mattersOpenAI ships the Codex desktop agent with its own Python, Node, git, Poppler and LibreOffice binaries, so document conversion and office file handling run as local skills invoking bundled tools rather than a hosted tool API.

x402 isn’t good (yet) — Jan Curn, Apify
Apify shipped x402 across 20,000 tools, then catalogued what it still gets wrong.
Why it mattersIf you sell agent-accessible tools over x402, starting work on a verified but unsettled payment exposes you to double spending, and MCP's 401 handshake conflicts with x402's 402, pushing teams onto a second hostname.

Your Agent Just Authorized What?! — Jay Mok & Ben Coumes, Paypal
PayPal is shipping an approval token that inverts checkout: a user approves an amount, expiry and permitted merchant before the agent has chosen an item.
Why it mattersAgent authorization comes down to three questions: did the human consent, is this in scope now, and can you prove it later. Pre-authorization tokens answer them for purchases the agent has not yet found.

OpenRouter now serves Claude Fable 5.1 at Fable 5 pricing, $10 per million input and $50 per million output, with prompt cache reads cut 75% to $0.25 per million. The gains are pitched at agentic coding, long-running workflows, visual code generation and analysis.
Why it mattersHeadline pricing matches Fable 5, but prompt cache reads drop to $0.25 per million tokens, a 75% cut that materially lowers the cost of agent loops replaying large contexts.

Cursor reports Fable 5.1 at 73.4% at max effort on CursorBench 3.2, the highest it has measured for any model on that harness, and credits the model's habit of verifying its own work for carrying harder tasks end to end. Available in Cursor now.
Why it mattersA second harness confirms the coding gain with its own measurement, and the model is selectable in Cursor now, so you can test the claim against your own repository.

Anthropic ships Fable 5.1 to Claude Code and the Claude Platform at Fable 5 pricing, with cache reads cut to $0.25/MTok and 55.8% on Terminal-Bench 4.0. New accounts also lose the ability to edit context before thinking blocks, an anti-distillation measure.
Why it mattersLong agent sessions billed at API rates can run 25-45% cheaper on cache-heavy integrations, and new accounts can no longer edit context preceding thinking blocks, which breaks some multi-turn message rewriting patterns.
Muse Voice Transcribe from Meta Superintelligence Labs reaches 3.1% WER at 0.16s after end of speech, ahead of Cartesia Ink-2 and ElevenLabs Scribe v2 Realtime, for $0.18 per audio hour. It works on 80ms chunks, covers 70 plus languages and handles hour-plus audio without post-processing.
Why it mattersTop of field streaming transcription at $3 per 1,000 minutes, roughly half of ElevenLabs and Deepgram, which resets the cost floor for voice agents and dictation front ends.

Anthropic's Fable 5.1 scores 55.8% on Terminal-Bench 4.0 against Fable 5's 42.0%, and 52.6% on Terminal-Bench-Science 0.1. Cache reads cost 75% less, cutting typical workload cost about 25% and highly agentic ones up to 45%. Enterprise Frontier Safeguards begin rolling out this fall.
Why it mattersA new frontier coding model is available today and cache reads cost 75% less, so agentic loops that re-read large contexts get materially cheaper without changing your prompts.
Introducing Claude Fable 5.1
Anthropic releases Claude Fable 5.1, generally available, for complex long-running work such as proofs and cross-referenced contracts, fixing root causes of software issues.
Why it mattersFable 5.1 can match or beat Fable 5 at lower effort levels at much lower cost, and targets long-running tasks and root-cause bug fixes, changing the cost calculus for agent work.

Cua Cloud Fleets added a creation-age TTL setting for pools and claims, so temporary agent sandboxes used in CI or eval runs delete themselves automatically instead of needing manual cleanup.
Why it mattersRemoves a common source of leaked cloud spend when running many ephemeral agent sandboxes for CI or evaluation.

When AI Agents Pay and Sellers Monetize: Building x402 Apps on AWS — Anil Nadiminti, AWS
AWS on both sides of agent payments.
Why it mattersCard minimums near 25 cents make a tenth-of-a-cent API call nonsensical. The transferable design is keeping the payment path off the agent loop, since skills and inputs can be poisoned.
Instead of holding an HTTP request open for a whole batch, each prompt becomes its own Render Workflow task run, queued, retried and fanned out with compute provisioned on demand. Auto Router records the chosen model per run, and retries can double-bill, so side effects need idempotency.
Why it mattersA concrete pattern for LLM fan-out: per-prompt task runs that outlive the HTTP request, compute provisioned on demand, per-run model attribution via completion.model, and the billing trap where a retry can repeat a paid call.

Runway's Ruby model now exports scene-referred, half-float EXR sequences in ACEScg 1.3 and 2.0. That moves its output out of display-referred formats and into the color space VFX and grading pipelines already run on, with no lossy conversion step in between.
Why it mattersGenerated footage can now go straight into a color-managed compositing pipeline, because ACEScg EXR output keeps scene-referred dynamic range instead of baking in a display transform.

Why Your AI Agent Needs a Wallet: USDC and Nanopayments — Harshal Bhangale, Circle
Circle's case for giving agents wallets, shown with two identical trip-planning agents where the unfunded one stalls at sending mail and placing a call.
Why it mattersMetered per-call API pricing needs sub-cent payments that cards and on-chain gas both price out. Circle reports roughly $24M moved through x402 paid endpoints in 30 days, nearly all in USDC.

Gemini now reasons across a video's transcript, audio, and frames and adjusts frame rate to pull only the moments it needs, reporting better accuracy with up to 88 percent fewer tokens. Available through the API on 3.7 Flash, 3.6 Flash, and 3.5 Flash-Lite.
Why it mattersLong video analysis gets substantially cheaper. Selective frame sampling cuts token use by up to 88 percent on multi-hour recordings, live now via API on 3.7 Flash, 3.6 Flash, and 3.5 Flash-Lite.

World Labs introduces Atlas, a multimodal world model pre-trained to take camera movement as an input, generating video with precise trajectory control and reconstructing explicit 3D from one or many images. It reports beating top open-source reconstruction models and emitting RGB plus depth for rob
Why it mattersAtlas turns a handful of ordinary photos into controllable 3D with depth, removing the specialized scanning hardware step from building simulation environments and multiview capture setups.

Meta Superintelligence Labs released a streaming speech model that processes audio in 80ms chunks and decides at each one whether to keep listening or emit text. RL over combined word error and delay rewards gives it adaptive latency, waiting longer on hard words. Shipping via the Meta Model API.
Why it mattersStreaming transcription with per-word adaptive latency, 20+ speaker diarization, and code switching is available through the Meta Model API, giving voice agent builders a tunable speed versus accuracy trade-off.

A 124-case probe of Mistral's 3B Shieldstral finds it does respond to runtime policy, every unfamiliar-policy match beat its control, but enforcement breaks on specifics: 5 of 12 broad-rule-plus-exception pairs flipped correctly, and a disclosed sponsorship was flagged across four phrasings.
Why it mattersGuard models that take runtime policy behave like semantic scorers rather than rule engines. Exceptions and negations often fail to move the score across the threshold, so test carve-outs before relying on them.
Introducing agentic video understanding with Gemini
Gemini 3.7 Flash, 3.6 Flash and 3.5 Flash-Lite can now scan video agentically, choosing which segments to inspect instead of ingesting everything.
Why it mattersLong-video analysis stops being priced as a full ingest. One API config change cuts token consumption by up to 88% and cost by up to 66%, with reportedly better accuracy.
An index of the vibe-coding frontier. Corrections welcome.